
Downloads · 30 days
1.3K
0% of all-time downloads
deepset/gelectra-base-germanquad
gelectra-base-germanquad is a question answering model from deepset. Use it when the input is a question plus a passage. It is set up for transformers. The card lists the license as mit.
Language model: gelectra-base-germanquad Language: German Training data: GermanQuAD train set (~ 12MB) Eval data: GermanQuAD test set (~ 5MB) Infrastructure: 1x V100 GPU Code: See an example extractive QA pipeline bui…
Downloads · 30 days
1.3K
0% of all-time downloads
All-time downloads
1.3M
Public
Parameters
109M
1.3 GB on disk
Likes
26
Public
Click a slice to open those files.
.h5438 MB · 33%
How the weights are stored.
F32109M · 100%
From the Hugging Face model README
Language model: gelectra-base-germanquad
Language: German
Training data: GermanQuAD train set (~ 12MB)
Eval data: GermanQuAD test set (~ 5MB)
Infrastructure: 1x V100 GPU
Code: See an example extractive QA pipeline built with Haystack
Published: Apr 21st, 2021
See https://deepset.ai/germanquad for more details and dataset download in SQuAD format.
batch_size = 24
n_epochs = 2
max_seq_len = 384
learning_rate = 3e-5
lr_schedule = LinearWarmup
embeds_dropout_prob = 0.1
Haystack is an AI orchestration framework to build customizable, production-ready LLM applications. You can use this model in Haystack to do extractive question answering on documents. To load and run the model with Haystack:
# After running pip install haystack-ai "transformers[torch,sentencepiece]"

from haystack import Document
from haystack.components.readers import ExtractiveReader

docs = [
    Document(content="Python is a popular programming language"),
    Document(content="python ist eine beliebte Programmiersprache"),
]

reader = ExtractiveReader(model="deepset/gelectra-base-germanquad")
reader.warm_up()

question = "What is a popular programming language?"
result = reader.run(query=question, documents=docs)
# {'answers': [ExtractedAnswer(query='What is a popular programming language?', score=0.5740374326705933, data='python', document=Document(id=..., content: '...'), context=None, document_offset=ExtractedAnswer.Span(start=0, end=6),...)]}
For a complete example with an extractive question answering pipeline that scales over many documents, check out the corresponding Haystack tutorial.
from transformers import AutoModelForQuestionAnswering, AutoTokenizer, pipeline

model_name = "deepset/gelectra-base-germanquad"

# a) Get predictions
nlp = pipeline('question-answering', model=model_name, tokenizer=model_name)
QA_input = {
    'question': 'Why is model conversion important?',
    'context': 'The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks.'
}
res = nlp(QA_input)

# b) Load model & tokenizer
model = AutoModelForQuestionAnswering.from_pretrained(model_name)
tokenizer = AutoTokenizer.from_pretrained(model_name)
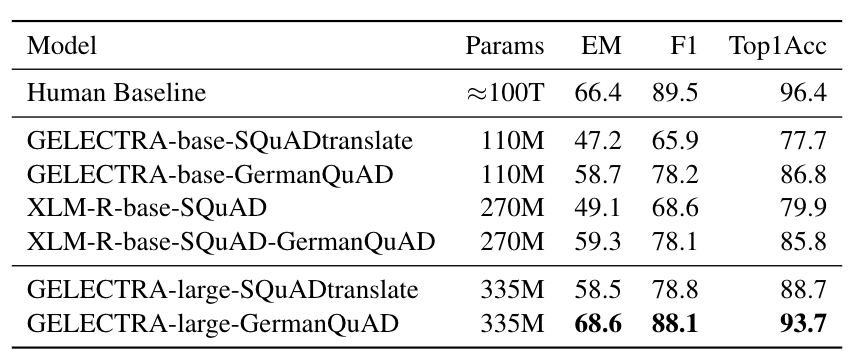
We evaluated the extractive question answering performance on our GermanQuAD test set.
Model types and training data are included in the model name.
For finetuning XLM-Roberta, we use the English SQuAD v2.0 dataset.
The GELECTRA models are warm started on the German translation of SQuAD v1.1 and finetuned on GermanQuAD.
The human baseline was computed for the 3-way test set by taking one answer as prediction and the other two as ground truth.
Timo Möller: timo.moeller@deepset.ai
Julian Risch: julian.risch@deepset.ai
Malte Pietsch: malte.pietsch@deepset.ai
deepset is the company behind the production-ready open-source AI framework Haystack.
Some of our other work:
We also have a <strong><a class="h-7" href="https://haystack.deepset.ai/community">Discord community open to everyone!</a></strong></p>
Twitter | LinkedIn | Discord | GitHub Discussions | Website | YouTube
By the way: we're hiring!