
Downloads · 30 days
108
1% of all-time downloads
dbmdz/bert-base-historic-dutch-cased
bert-base-historic-dutch-cased is a fill-mask model from dbmdz. Use it when you need the model to fill a missing word. It is set up for transformers. The card lists the license as mit.
In this repository we open source a language model for Historic Dutch, trained on the Delpher Corpus, that include digitized texts from Dutch newspapers, ranging from 1618 to 1879.
Downloads · 30 days
108
1% of all-time downloads
All-time downloads
14.8K
Public
Parameters
111M
2.8 GB on disk
Likes
2
Public
Click a slice to open those files.
.data-00000-of-000011.3 GB · 48%
How the weights are stored.
F32111M · 100%
From the Hugging Face model README
In this repository we open source a language model for Historic Dutch, trained on the [Delpher Corpus](https://www.delpher.nl/over-delpher/delpher-open-krantenarchief/download-teksten-kranten-1618-1879\), that include digitized texts from Dutch newspapers, ranging from 1618 to 1879.
The following models for Historic Dutch are available on the Hugging Face Model Hub:
| Model identifier | Model Hub link |
|---|---|
dbmdz/bert-base-historic-dutch-cased | here |
The download urls for all archives can be found here.
We then used the awesome alto-tools from this
repository to extract plain text. The following table shows the size overview per year range:
| Period | Extracted plain text size |
|---|---|
| 1618-1699 | 170MB |
| 1700-1709 | 103MB |
| 1710-1719 | 65MB |
| 1720-1729 | 137MB |
| 1730-1739 | 144MB |
| 1740-1749 | 188MB |
| 1750-1759 | 171MB |
| 1760-1769 | 235MB |
| 1770-1779 | 271MB |
| 1780-1789 | 414MB |
| 1790-1799 | 614MB |
| 1800-1809 | 734MB |
| 1810-1819 | 807MB |
| 1820-1829 | 987MB |
| 1830-1839 | 1.7GB |
| 1840-1849 | 2.2GB |
| 1850-1854 | 1.3GB |
| 1855-1859 | 1.7GB |
| 1860-1864 | 2.0GB |
| 1865-1869 | 2.3GB |
| 1870-1874 | 1.9GB |
| 1875-1876 | 867MB |
| 1877-1879 | 1.9GB |
The total training corpus consists of 427,181,269 sentences and 3,509,581,683 tokens (counted via wc),
resulting in a total corpus size of 21GB.
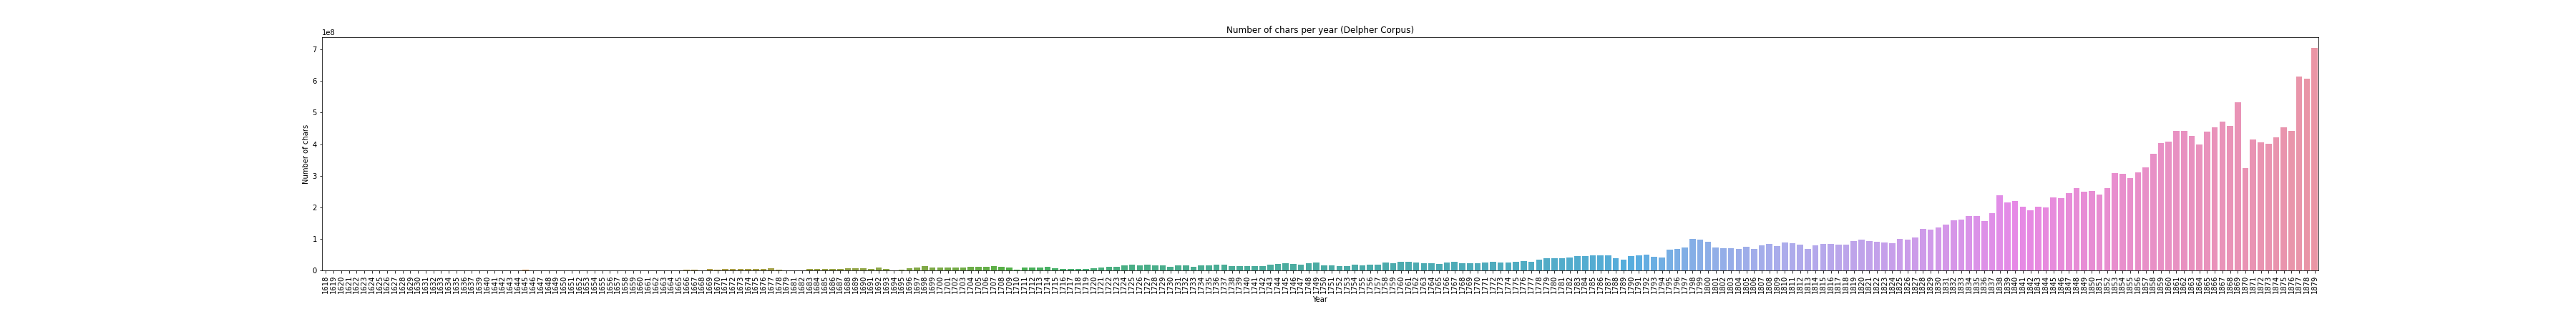
The following figure shows an overview of the number of chars per year distribution:
We use the official BERT implementation using the following command to train the model:
python3 run_pretraining.py --input_file gs://delpher-bert/tfrecords/*.tfrecord \
--output_dir gs://delpher-bert/bert-base-historic-dutch-cased \
--bert_config_file ./config.json \
--max_seq_length=512 \
--max_predictions_per_seq=75 \
--do_train=True \
--train_batch_size=128 \
--num_train_steps=3000000 \
--learning_rate=1e-4 \
--save_checkpoints_steps=100000 \
--keep_checkpoint_max=20 \
--use_tpu=True \
--tpu_name=electra-2 \
--num_tpu_cores=32
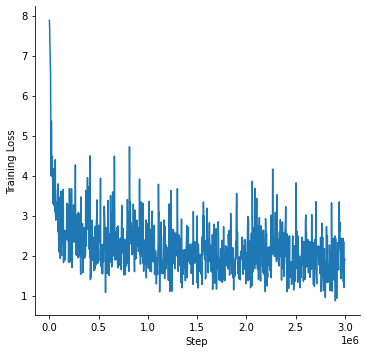
We train the model for 3M steps using a total batch size of 128 on a v3-32 TPU. The pretraining loss curve can be seen in the next figure:
We evaluate our model on the preprocessed Europeana NER dataset for Dutch, that was presented in the "Data Centric Domain Adaptation for Historical Text with OCR Errors" paper.
The data is available in their repository. We perform a hyper-parameter search for:
[4, 8][3e-5, 5e-5][5, 10]and report averaged F1-Score over 5 runs with different seeds. We also include hmBERT as baseline model.
Results:
| Model | F1-Score (Dev / Test) |
|---|---|
| hmBERT | (82.73) / 81.34 |
| Maerz et al. (2021) | - / 84.2 |
| Ours | (89.73) / 87.45 |
All models are licensed under MIT.
Research supported with Cloud TPUs from Google's TPU Research Cloud (TRC) program, previously known as TensorFlow Research Cloud (TFRC). Many thanks for providing access to the TRC ❤️
We thank Clemens Neudecker for maintaining the amazing ALTO tools that were used for parsing the Delpher Corpus XML files.
Thanks to the generous support from the Hugging Face team, it is possible to download both cased and uncased models from their S3 storage 🤗