Downloads · 30 days
0
coreml-community/coreml-westernAnimation_v1_cn
coreml-westernAnimation_v1_cn is a text-to-image model from coreml-community. Use it when you need an image from a text prompt. The card lists the license as creativeml-openrail-m.
- This model was converted to Core ML for use on Apple Silicon devices. Conversion instructions can be found here. - Provide the model to an app such as Mochi Diffusion Github / Discord to generate images.
Downloads · 30 days
0
Access
Public
Updated Jul 2, 2023
Repo size
17.9 GB
Likes
1
Public
Click a slice to open those files.
.zip17.9 GB · 100%
From the Hugging Face model README
split_einsum version is compatible with all compute unit options including Neural Engine.original version is only compatible with CPU & GPU option.vae-ft-mse-840000-ema-pruned.ckpt VAE is embedded into the model.vae-encoder for use with image2image.fp16.CoreML format.safety checker (for NSFW content).Source(s): CivitAI<br>
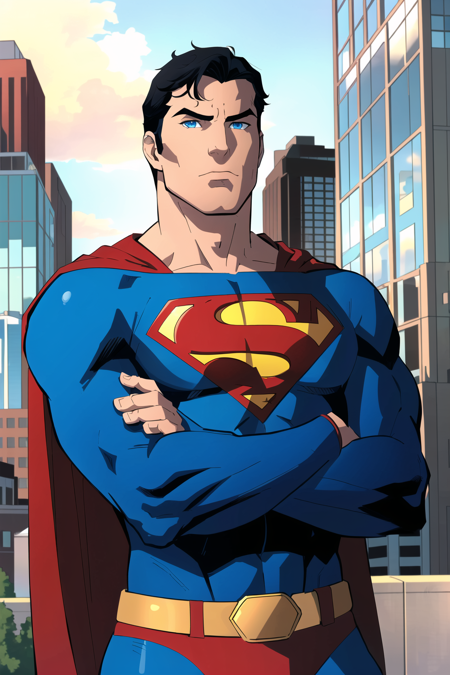
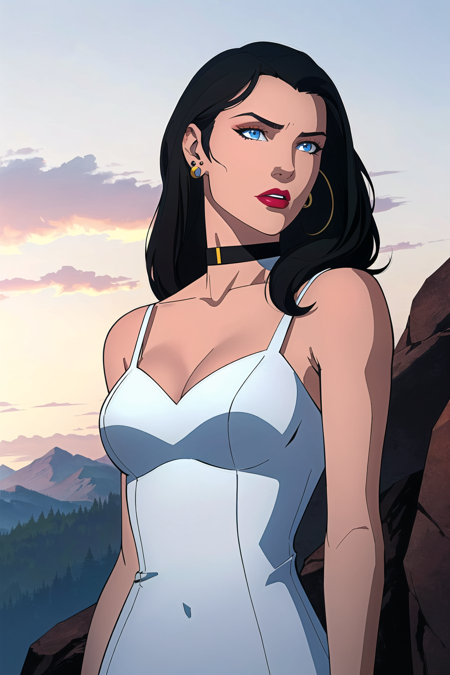
Comicbook and Western Animation Style Model
Do you like what I do? Consider supporting me on Patreon or feel free to buy me a coffee.
A ❤️, a kind comment or a review is greatly appreciated.
Train character loras where the dataset is mostly made of cartoon screencaps or comicbooks, allowing less style transfer and less overfitting.
Add variety to mixes.
Have an alternative to anime models when it comes to western stuff.
NOT to be used with style loras. Also NOT for style lora training.
Set the ETA Noise Seed Delta (ENSD) to 31337
Set CLIP Skip to 2
DISABLE face restore. It's terrible, never use it
Use negative prompts and embeddings that don't ruin the style
Use AnimeVideo or Foolhardy as upscalers in highres fix
Use ADetailer for far away shots or full body images to avoid blurred faces
This was requested by a supporter and I also wanted to see if I was capable of doing it. It was a funny little project.<br><br>