
Downloads · 30 days
0
coreml-community/coreml-inkpunkDiffusion-v2_cn
coreml-inkpunkDiffusion-v2_cn is a text-to-image model from coreml-community. Use it when you need an image from a text prompt. The card lists the license as creativeml-openrail-m.
- This model was converted to Core ML for use on Apple Silicon devices. Conversion instructions can be found here. - Provide the model to an app such as Mochi Diffusion Github / Discord to generate images.
Downloads · 30 days
0
Access
Public
Updated Jul 18, 2023
Repo size
17.9 GB
Likes
2
Public
Click a slice to open those files.
.zip17.9 GB · 100%
From the Hugging Face model README
split_einsum version is compatible with all compute unit options including Neural Engine.original version is only compatible with CPU & GPU option.vae-ft-mse-840000-ema-pruned.ckpt VAE is embedded into the model.vae-encoder for use with image2image.fp16.CoreML format.safety checker (for NSFW content).Source(s): CivitAI / Hugging Face<br>
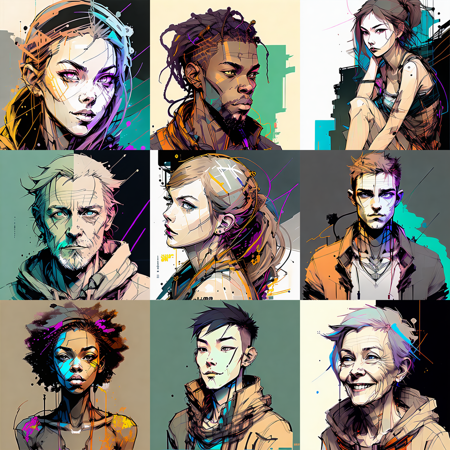
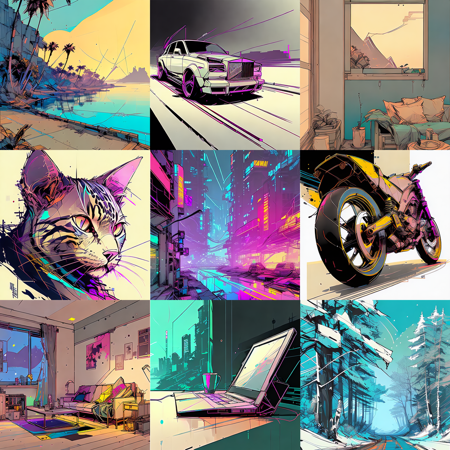
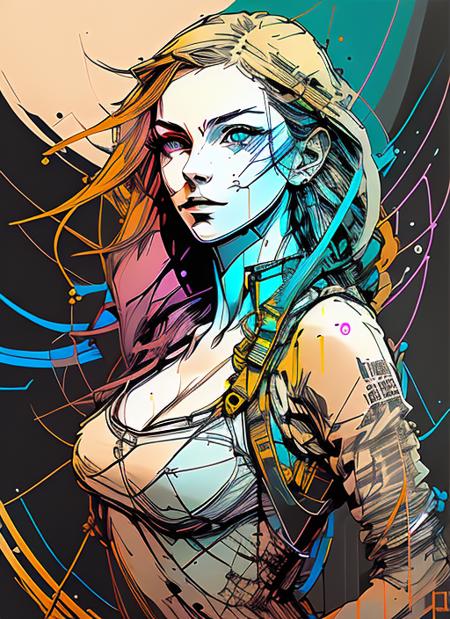
Finetuned Stable Diffusion model trained on Dreambooth.
Vaguely inspired by Gorillaz, FLCL, and Yoji Shinkawa
Use nvinkpunk in your prompts.
Improvements:
Excorsized the woman that seemed to be haunting the model and appearing in basically every prompt. (She still pops in here and there, I honestly don't know where she comes from.)
Faces are better overall, and characters are more responsive to descriptive language in prompts. Try playing around with emotions/nationality/age/poses to get the best results.
Hair anarchy has been toned down slightly and added more diverse hairstyles to the dataset to avoid everyone having tumbleweed hair. Again, descriptive language in prompts helps.
Full body poses are also more diverse, though keep in mind that wide angle shots tend to lead to distorted faces that may need to be touched up with img2img/inpainting.<br><br>
),_((detailed_face)),_((award_winning)),_(High_Detail),_Sharp,_8k,__trending_o.jpeg)
