
Downloads · 30 days
11
2% of all-time downloads
codedrainer/uae-license-detection
uae-license-detection is a image-to-text model from codedrainer. Use it when you need a caption or text from an image. It is set up for transformers. The card lists the license as mit.
Donut model fine-tuned on RVL-CDIP. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Downloads · 30 days
11
2% of all-time downloads
All-time downloads
643
Public
Repo size
1.7 GB
Likes
2
Public
Click a slice to open those files.
.bin858 MB · 100%
From the Hugging Face model README
Donut model fine-tuned on RVL-CDIP. It was introduced in the paper OCR-free Document Understanding Transformer by Geewok et al. and first released in this repository.
Disclaimer: The team releasing Donut did not write a model card for this model so this model card has been written by the Hugging Face team.
Donut consists of a vision encoder (Swin Transformer) and a text decoder (BART). Given an image, the encoder first encodes the image into a tensor of embeddings (of shape batch_size, seq_len, hidden_size), after which the decoder autoregressively generates text, conditioned on the encoding of the encoder.
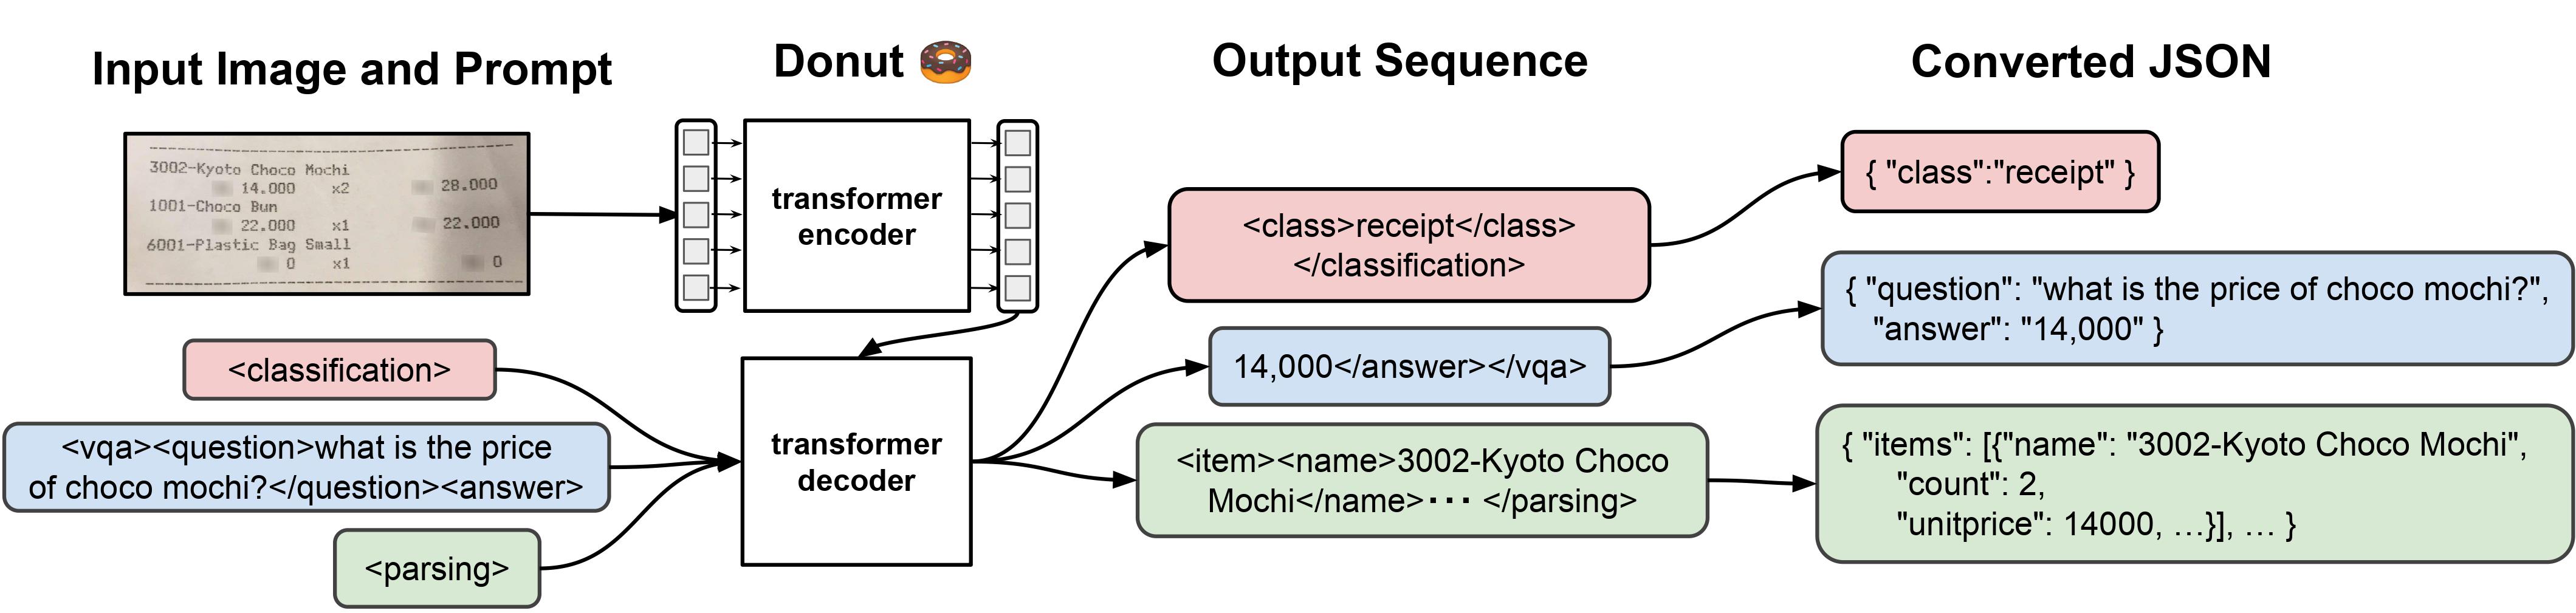
This model is fine-tuned on RVL-CDIP, a document image classification dataset.
We refer to the documentation which includes code examples.
@article{DBLP:journals/corr/abs-2111-15664,
  author    = {Geewook Kim and
               Teakgyu Hong and
               Moonbin Yim and
               Jinyoung Park and
               Jinyeong Yim and
               Wonseok Hwang and
               Sangdoo Yun and
               Dongyoon Han and
               Seunghyun Park},
  title     = {Donut: Document Understanding Transformer without {OCR}},
  journal   = {CoRR},
  volume    = {abs/2111.15664},
  year      = {2021},
  url       = {https://arxiv.org/abs/2111.15664},
  eprinttype = {arXiv},
  eprint    = {2111.15664},
  timestamp = {Thu, 02 Dec 2021 10:50:44 +0100},
  biburl    = {https://dblp.org/rec/journals/corr/abs-2111-15664.bib},
  bibsource = {dblp computer science bibliography, https://dblp.org}
}