
Downloads · 30 days
149
1% of all-time downloads
cmarkea/dit-base-layout-detection
dit-base-layout-detection is a image segmentation model from cmarkea. Use it for the image segmentation task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
We present the model cmarkea/dit-base-layout-detection, which allows extracting different layouts (Text, Picture, Caption, Footnote, etc.) from an image of a document. This is a fine-tuning of the model dit-base on th…
Downloads · 30 days
149
1% of all-time downloads
All-time downloads
13.6K
Public
Parameters
164M
1.3 GB on disk
Likes
7
Trending 1
Click a slice to open those files.
.safetensors655 MB · 100%
From the Hugging Face model README
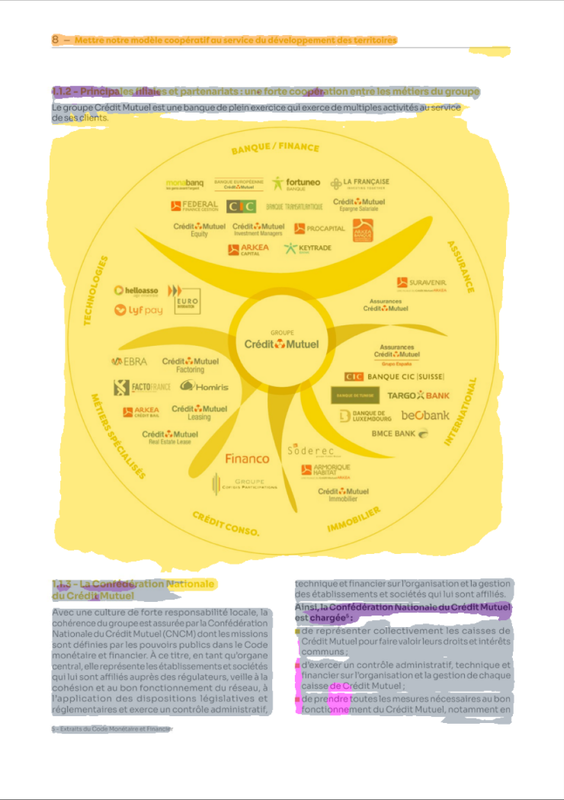
We present the model cmarkea/dit-base-layout-detection, which allows extracting different layouts (Text, Picture, Caption, Footnote, etc.) from an image of a document. This is a fine-tuning of the model dit-base on the DocLayNet dataset. It is ideal for processing documentary corpora to be ingested into an ODQA system.
This model allows extracting 11 entities, which are: Caption, Footnote, Formula, List-item, Page-footer, Page-header, Picture, Section-header, Table, Text, and Title.
In this section, we will assess the model's performance by separately considering semantic segmentation and object detection. We did not perform any post-processing
for the semantic segmentation. As for object detection, we only applied OpenCV's findContours without any further post-processing.
For semantic segmentation, we will use the F1-score to evaluate the classification of each pixel. For object detection, we will assess performance based on the Generalized Intersection over Union (GIoU) and the accuracy of the predicted bounding box class. The evaluation is conducted on 500 pages from the PDF evaluation dataset of DocLayNet.
| Class | f1-score (x100) | GIoU (x100) | accuracy (x100) |
|---|---|---|---|
| Background | 94.98 | NA | NA |
| Caption | 75.54 | 55.61 | 72.62 |
| Footnote | 72.29 | 50.08 | 70.97 |
| Formula | 82.29 | 49.91 | 94.48 |
| List-item | 67.56 | 35.19 | 69 |
| Page-footer | 83.93 | 57.99 | 94.06 |
| Page-header | 62.33 | 65.25 | 79.39 |
| Picture | 78.32 | 58.22 | 92.71 |
| Section-header | 69.55 | 56.64 | 78.29 |
| Table | 83.69 | 63.03 | 90.13 |
| Text | 90.94 | 51.89 | 88.09 |
| Title | 61.19 | 52.64 | 70 |
Now, let's compare the performance of this model with other models.
| Model | f1-score (x100) | GIoU (x100) | accuracy (x100) |
|---|---|---|---|
| cmarkea/dit-base-layout-detection | 90.77 | 56.29 | 85.26 |
| cmarkea/detr-layout-detection | 91.27 | 80.66 | 90.46 |
import torch
from transformers import AutoImageProcessor, BeitForSemanticSegmentation

img_proc = AutoImageProcessor.from_pretrained(
    "cmarkea/dit-base-layout-detection"
)
model = BeitForSemanticSegmentation.from_pretrained(
    "cmarkea/dit-base-layout-detection"
)

img: PIL.Image

with torch.inference_mode():
    input_ids = img_proc(img, return_tensors='pt')
    output = model(**input_ids)

segmentation = img_proc.post_process_semantic_segmentation(
    output,
    target_sizes=[img.size[::-1]]
)
Here is a simple method for detecting bounding boxes from semantic segmentation. This is the method used to calculate the model's performance in object detection, as described in the "Performance" section. The method is provided without any additional post-processing.
import cv2

def detect_bboxes(masks: np.ndarray):
    r"""
    A simple bounding box detection function
    """
    detected_blocks = []
    contours, _ = cv2.findContours(
        masks.astype(np.uint8),
        cv2.RETR_EXTERNAL,
        cv2.CHAIN_APPROX_SIMPLE
    )
    for contour in list(contours):
        if len(list(contour)) >= 4:
            # smallest rectangle containing all points
            x, y, width, height = cv2.boundingRect(contour)
            bounding_box = [x, y, x + width, y + height]
            detected_blocks.append(bounding_box)
    return detected_blocks

bbox_pred = []
for segment in segmentation:
    boxes, labels = [], []
    for ii in range(1, len(model.config.label2id)):
        mm = segment == ii
        if mm.sum() > 0:
            bbx = detect_bboxes(mm.numpy())
            boxes.extend(bbx)
            labels.extend([ii]*len(bbx))
    bbox_pred.append(dict(boxes=boxes, labels=labels))
@online{DeDitLay,
  AUTHOR = {Cyrile Delestre},
  URL = {https://huggingface.co/cmarkea/dit-base-layout-detection},
  YEAR = {2024},
  KEYWORDS = {Image Processing ; Transformers ; Layout},
}