
Downloads · 30 days
154
0% of all-time downloads
cloudyu/Mixtral_7Bx4_MOE_24B
Mixtral_7Bx4_MOE_24B is a text generation model from cloudyu. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as cc-by-nc-4.0.
I don't know why so many downloads about this model. Please share your cases, thanks.
Downloads · 30 days
154
0% of all-time downloads
All-time downloads
55.4K
Public
Parameters
24.2B
48.3 GB on disk
Likes
13
Public
Click a slice to open those files.
.safetensors48.3 GB · 100%
How the weights are stored.
BF1616.9B · 70%
From the Hugging Face model README
I don't know why so many downloads about this model. Please share your cases, thanks.
Now this model is improved by DPO to cloudyu/Pluto_24B_DPO_200
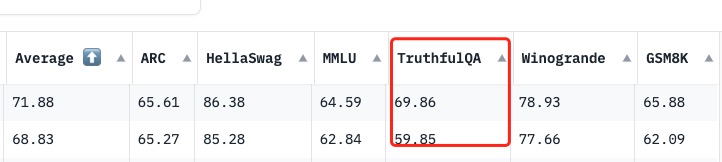
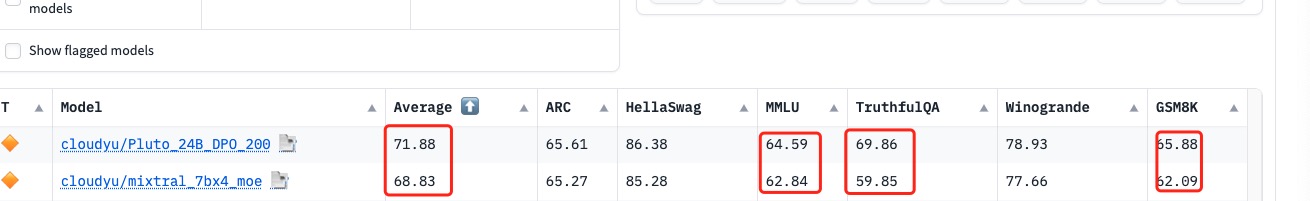
MOE the following models by mergekit:
Metrics
gpu code example
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
import math

## v2 models
model_path = "cloudyu/Mixtral_7Bx4_MOE_24B"

tokenizer = AutoTokenizer.from_pretrained(model_path, use_default_system_prompt=False)
model = AutoModelForCausalLM.from_pretrained(
    model_path, torch_dtype=torch.float32, device_map='auto',local_files_only=False, load_in_4bit=True
)
print(model)
prompt = input("please input prompt:")
while len(prompt) > 0:
  input_ids = tokenizer(prompt, return_tensors="pt").input_ids.to("cuda")

  generation_output = model.generate(
    input_ids=input_ids, max_new_tokens=500,repetition_penalty=1.2
  )
  print(tokenizer.decode(generation_output[0]))
  prompt = input("please input prompt:")
CPU example
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
import math

## v2 models
model_path = "cloudyu/Mixtral_7Bx4_MOE_24B"

tokenizer = AutoTokenizer.from_pretrained(model_path, use_default_system_prompt=False)
model = AutoModelForCausalLM.from_pretrained(
    model_path, torch_dtype=torch.float32, device_map='cpu',local_files_only=False
)
print(model)
prompt = input("please input prompt:")
while len(prompt) > 0:
  input_ids = tokenizer(prompt, return_tensors="pt").input_ids

  generation_output = model.generate(
    input_ids=input_ids, max_new_tokens=500,repetition_penalty=1.2
  )
  print(tokenizer.decode(generation_output[0]))
  prompt = input("please input prompt:")
Detailed results can be found here
| Metric | Value |
|---|---|
| Avg. | 68.83 |
| AI2 Reasoning Challenge (25-Shot) | 65.27 |
| HellaSwag (10-Shot) | 85.28 |
| MMLU (5-Shot) | 62.84 |
| TruthfulQA (0-shot) | 59.85 |
| Winogrande (5-shot) | 77.66 |
| GSM8k (5-shot) | 62.09 |