
Downloads · 30 days
170
1% of all-time downloads
chuxin-llm/Chuxin-Embedding
Chuxin-Embedding is a machine learning model from chuxin-llm. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Chuxin-Embedding 是专为增强中文文本检索能力而设计的嵌入模型。它基于bge-m3-retromae[1],实现了预训练、微调、精调全流程。该模型在来自各个领域的大量语料库上进行训练,语料库的批量非常大。截至 2024 年 9 月 14 日, Chuxin-Embedding 在检索任务中表现出色,在 C-MTEB 中文检索排行榜上排名第一,领先的性能得分为 77.88,在AIR-Bench中文检索+重排序公开排行榜…
Downloads · 30 days
170
1% of all-time downloads
All-time downloads
25K
Public
Parameters
568M
2.3 GB on disk
Likes
12
Public
Click a slice to open those files.
.safetensors2.3 GB · 99%
From the Hugging Face model README
Chuxin-Embedding 是专为增强中文文本检索能力而设计的嵌入模型。它基于bge-m3-retromae[1],实现了预训练、微调、精调全流程。该模型在来自各个领域的大量语料库上进行训练,语料库的批量非常大。截至 2024 年 9 月 14 日, Chuxin-Embedding 在检索任务中表现出色,在 C-MTEB 中文检索排行榜上排名第一,领先的性能得分为 77.88,在AIR-Bench中文检索+重排序公开排行榜上排名第一,领先的性能得分为 64.78。
Chuxin-Embedding is a specially designed embedding model aimed at enhancing the capability of Chinese text retrieval. It is based on bge-m3-retromae[1] and implements the entire process of pre-training, fine-tuning, and refining. This model has been trained on a vast amount of corpora from various fields. As of September 14, 2024, Chuxin-Embedding has shown outstanding performance in retrieval tasks. It ranks first on the C-MTEB Chinese Retrieval Leaderboard with a leading performance score of 77.88 and also ranks first on the AIR-Bench Chinese Retrieval + Re-ranking Public Leaderboard with a leading performance score of 64.78.
2024/10/18: LLM生成及数据清洗 Code 。
2024/9/14: 团队的RAG框架欢迎试用 ragnify 。
2024/9/14: LLM generation and data clean Code .
2024/9/14: The team's RAG framework is available for trial ragnify .
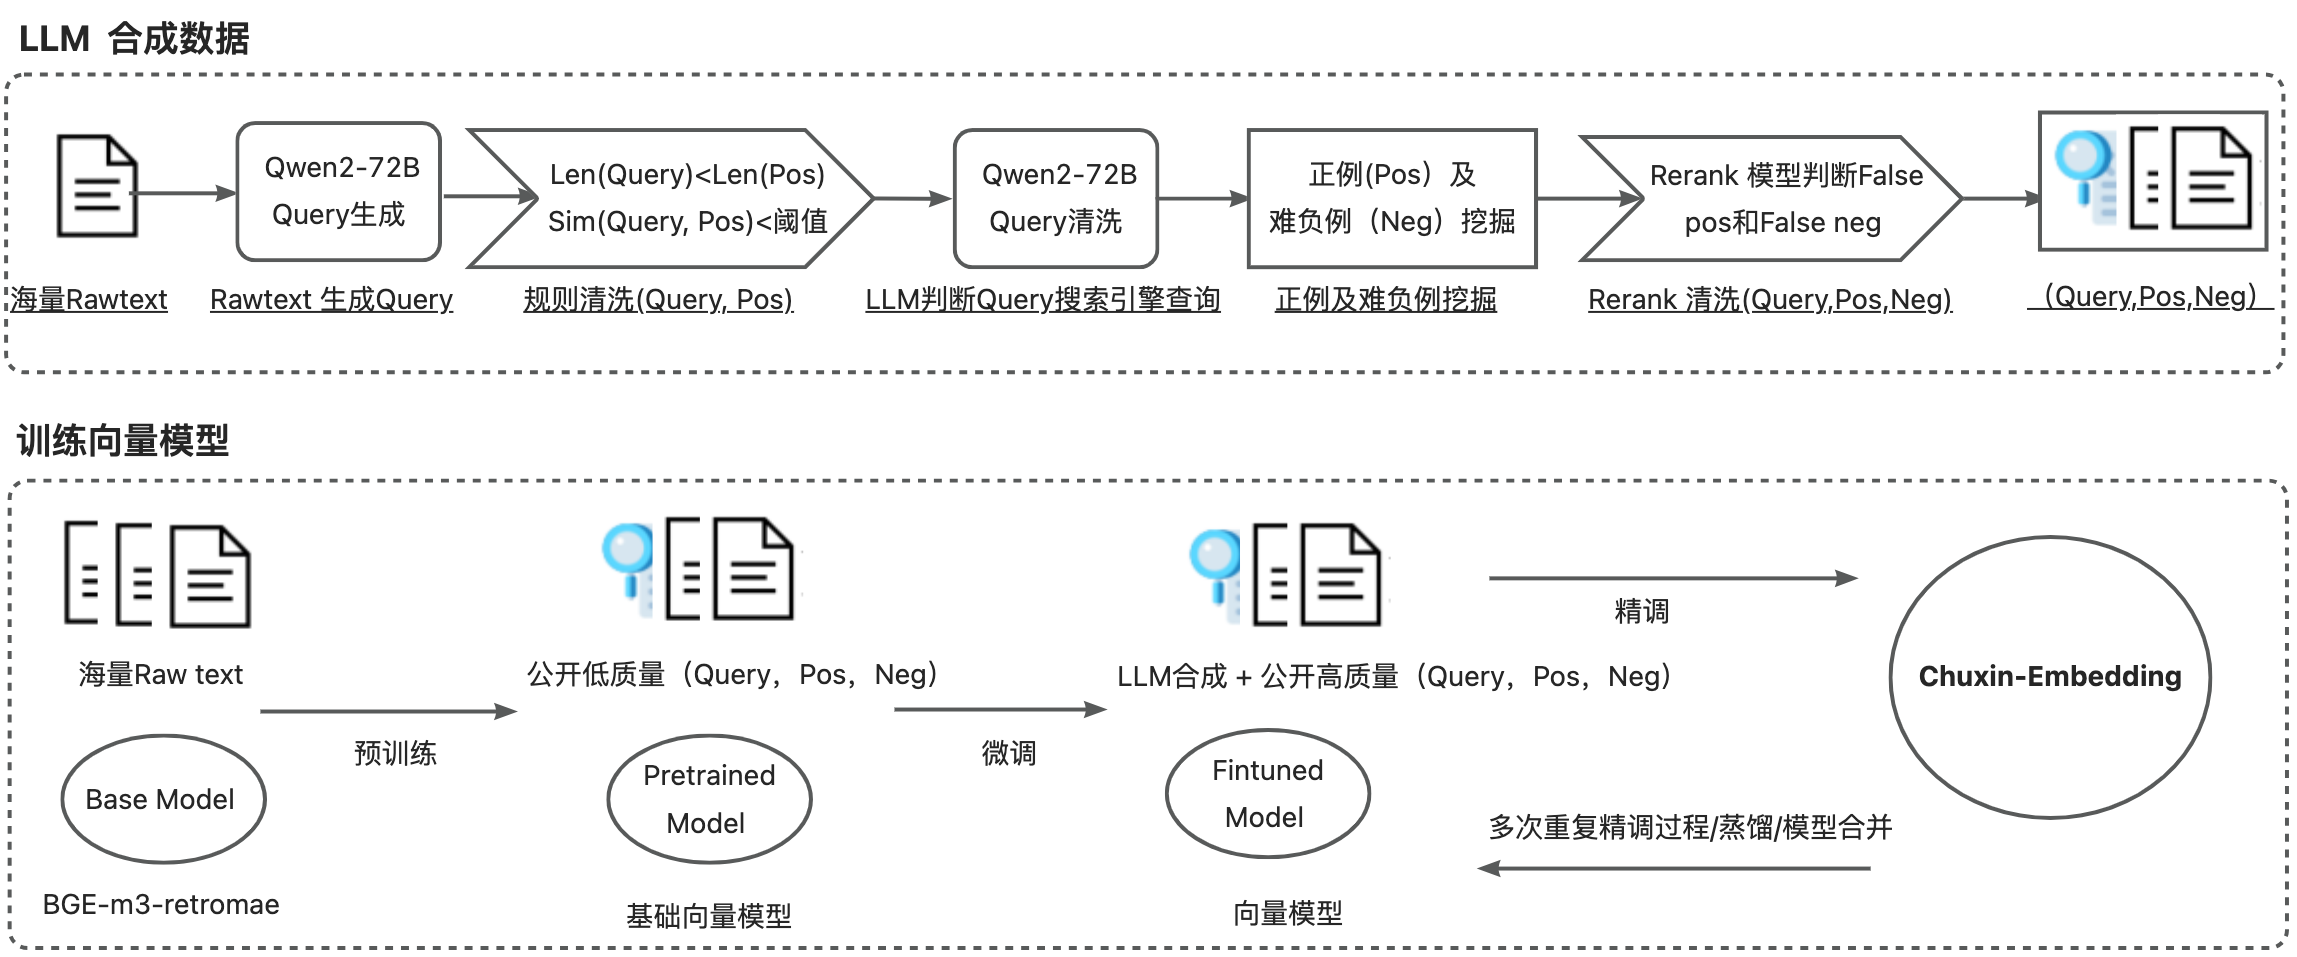 基于bge-m3-retromae[1],主要改动如下:
Based on bge-m3-retromae[1], the main modifications are as follows:
C_MTEB RETRIEVAL
| Model | Average | CmedqaRetrieval | CovidRetrieval | DuRetrieval | EcomRetrieval | MedicalRetrieval | MMarcoRetrieval | T2Retrieval | VideoRetrieval |
|---|---|---|---|---|---|---|---|---|---|
| Zhihui_LLM_Embedding | 76.74 | 48.69 | 84.39 | 91.34 | 71.96 | 65.19 | 84.77 | 88.3 | 79.31 |
| zpoint_large_embedding_zh | 76.36 | 47.16 | 89.14 | 89.23 | 70.74 | 68.14 | 82.38 | 83.81 | 80.26 |
| Chuxin-Embedding | 77.88 | 56.58 | 84.28 | 85.65 | 74.01 | 75.62 | 79.06 | 84.04 | 83.84 |
AIR-Bench
| Retrieval Method | Reranking Model | Average | wiki_zh | web_zh | news_zh | healthcare_zh | finance_zh |
|---|---|---|---|---|---|---|---|
| bge-m3 | bge-reranker-large | 64.53 | 76.11 | 67.8 | 63.25 | 62.9 | 52.61 |
| gte-Qwen2-7B-instruct | bge-reranker-large | 63.39 | 78.09 | 67.56 | 63.14 | 61.12 | 47.02 |
| Chuxin-Embedding | bge-reranker-large | 64.78 | 76.23 | 68.44 | 64.2 | 62.93 | 52.11 |
#pip install -U FlagEmbedding

from FlagEmbedding import FlagModel

model = FlagModel('chuxin-llm/Chuxin-Embedding',
                   query_instruction_for_retrieval="为这个句子生成表示以用于检索相关文章:",
                   use_fp16=True)

sentences_1 = ["样例数据-1", "样例数据-2"]
sentences_2 = ["样例数据-3", "样例数据-1"]

embeddings_1 = model.encode(sentences_1)
embeddings_2 = model.encode(sentences_2)
similarity = embeddings_1 @ embeddings_2.T
print(similarity)