
Downloads · 30 days
163
7% of all-time downloads
cgus/Apollo2-7B-iMat-GGUF
Apollo2-7B-iMat-GGUF is a question answering model from cgus. Use it when the input is a question plus a passage. The card lists the license as apache-2.0.
Original model: Apollo2-7B Made by: FreedomIntelligence
Downloads · 30 days
163
7% of all-time downloads
All-time downloads
2.5K
Public
Repo size
46.7 GB
Likes
2
Public
Click a slice to open those files.
.gguf46.7 GB · 100%
From the Hugging Face model README
Original model: Apollo2-7B
Made by: FreedomIntelligence
Made with llama.cpp-b3938 with imatrix file based on Exllamav2 callibration dataset.
This model is meant to run with llama.cpp-compatible apps such as Text-Generation-WebUI, KoboldCpp, Jan, LM Studio and many many others.
17.12.2024: Readme update. It seems Q4_0_4_4, Q4_0_4_8 and Q4_0_8_8 support was removed in recent llama.cpp. I'll keep them but they might be no longer useful.
03.02.2025: Added Q4_0 and IQ4_NL quants as a substitute for Q4_0_X_Y quants for ARM devices with newer llama.cpp versions.
Covering 12 Major Languages including English, Chinese, French, Hindi, Spanish, Arabic, Russian, Japanese, Korean, German, Italian, Portuguese and 38 Minor Languages So far.
<p align="center"> 📃 <a href="https://arxiv.org/abs/2410.10626" target="_blank">Paper</a> • 🌐 <a href="" target="_blank">Demo</a> • 🤗 <a href="https://huggingface.co/datasets/FreedomIntelligence/ApolloMoEDataset" target="_blank">ApolloMoEDataset</a> • 🤗 <a href="https://huggingface.co/datasets/FreedomIntelligence/ApolloMoEBench" target="_blank">ApolloMoEBench</a> • 🤗 <a href="https://huggingface.co/collections/FreedomIntelligence/apollomoe-and-apollo2-670ddebe3bb1ba1aebabbf2c" target="_blank">Models</a> •🌐 <a href="https://github.com/FreedomIntelligence/Apollo" target="_blank">Apollo</a> • 🌐 <a href="https://github.com/FreedomIntelligence/ApolloMoE" target="_blank">ApolloMoE</a> </p>
12 Major Languages and 38 Minor Languages
<details> <summary>Click to view the Languages Coverage</summary>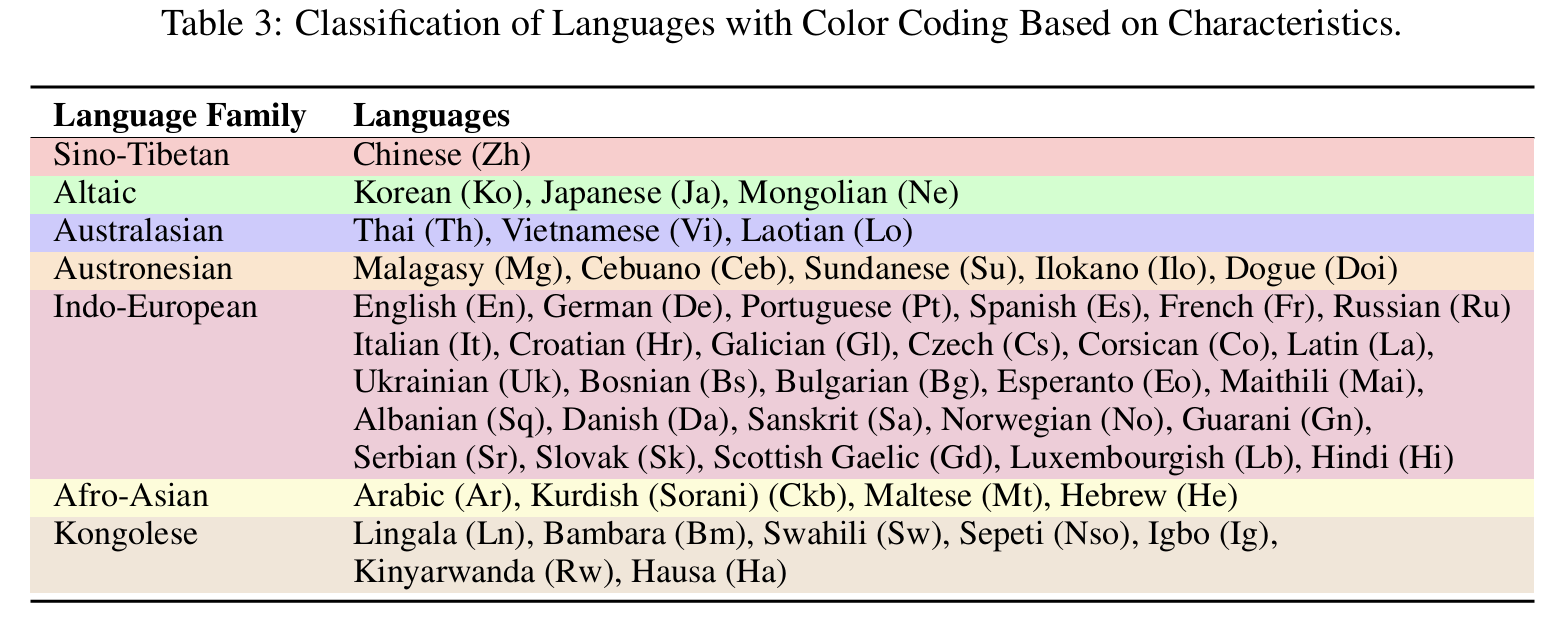
🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-0.5B" target="_blank">Apollo2-0.5B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-1.5B" target="_blank">Apollo2-1.5B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-2B" target="_blank">Apollo2-2B</a>
🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-3.8B" target="_blank">Apollo2-3.8B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-7B" target="_blank">Apollo2-7B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo2-9B" target="_blank">Apollo2-9B</a>
<details> <summary>Click to view the Dense Models Results</summary>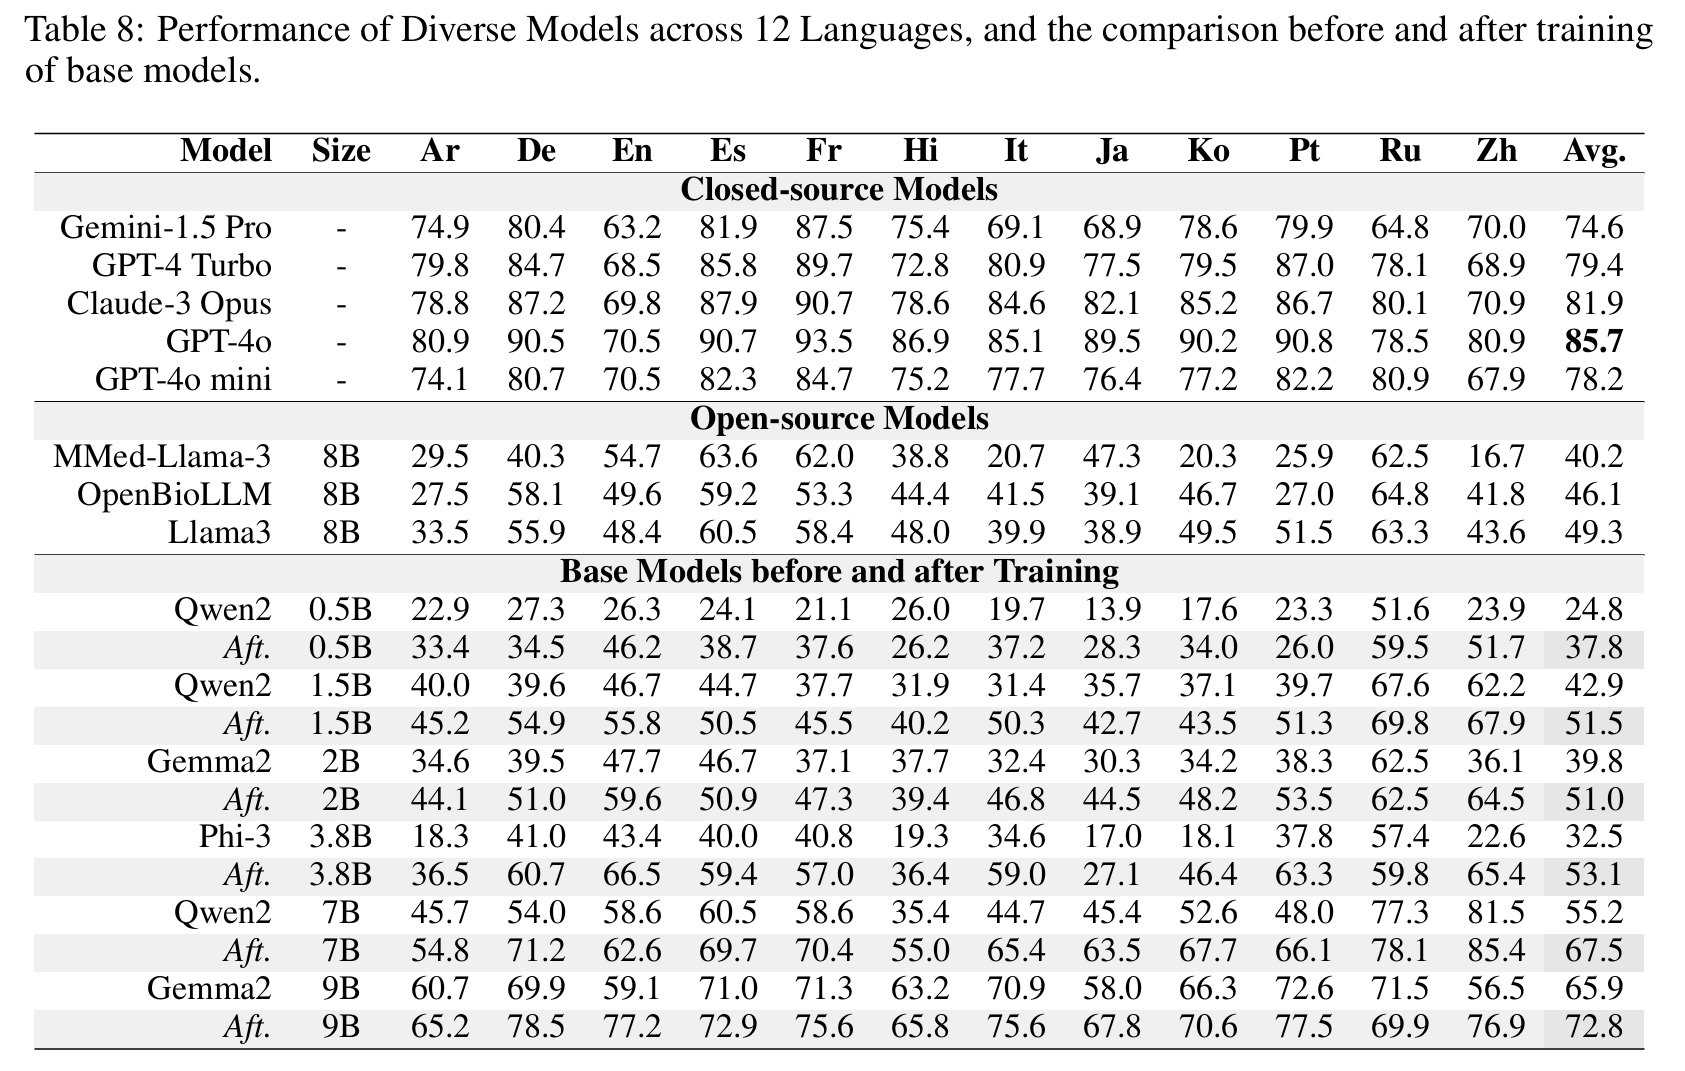
🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo-MoE-0.5B" target="_blank">Apollo-MoE-0.5B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo-MoE-1.5B" target="_blank">Apollo-MoE-1.5B</a> • 🤗 <a href="https://huggingface.co/FreedomIntelligence/Apollo-MoE-7B" target="_blank">Apollo-MoE-7B</a>
<details> <summary>Click to view the Post-MoE Models Results</summary>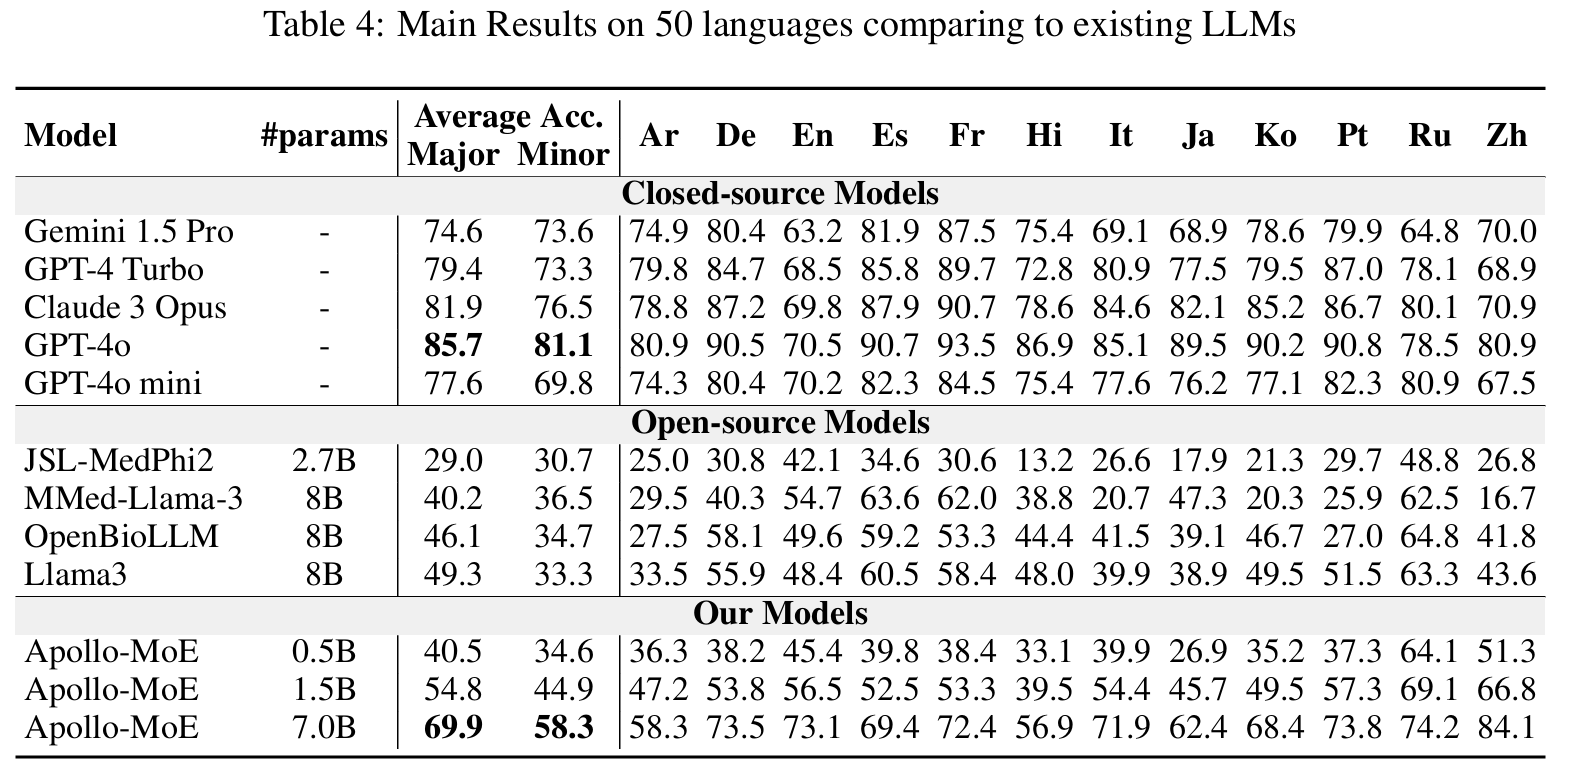
Dataset 🤗 <a href="https://huggingface.co/datasets/FreedomIntelligence/ApolloMoEDataset" target="_blank">ApolloMoEDataset</a>
<details><summary>Click to expand</summary>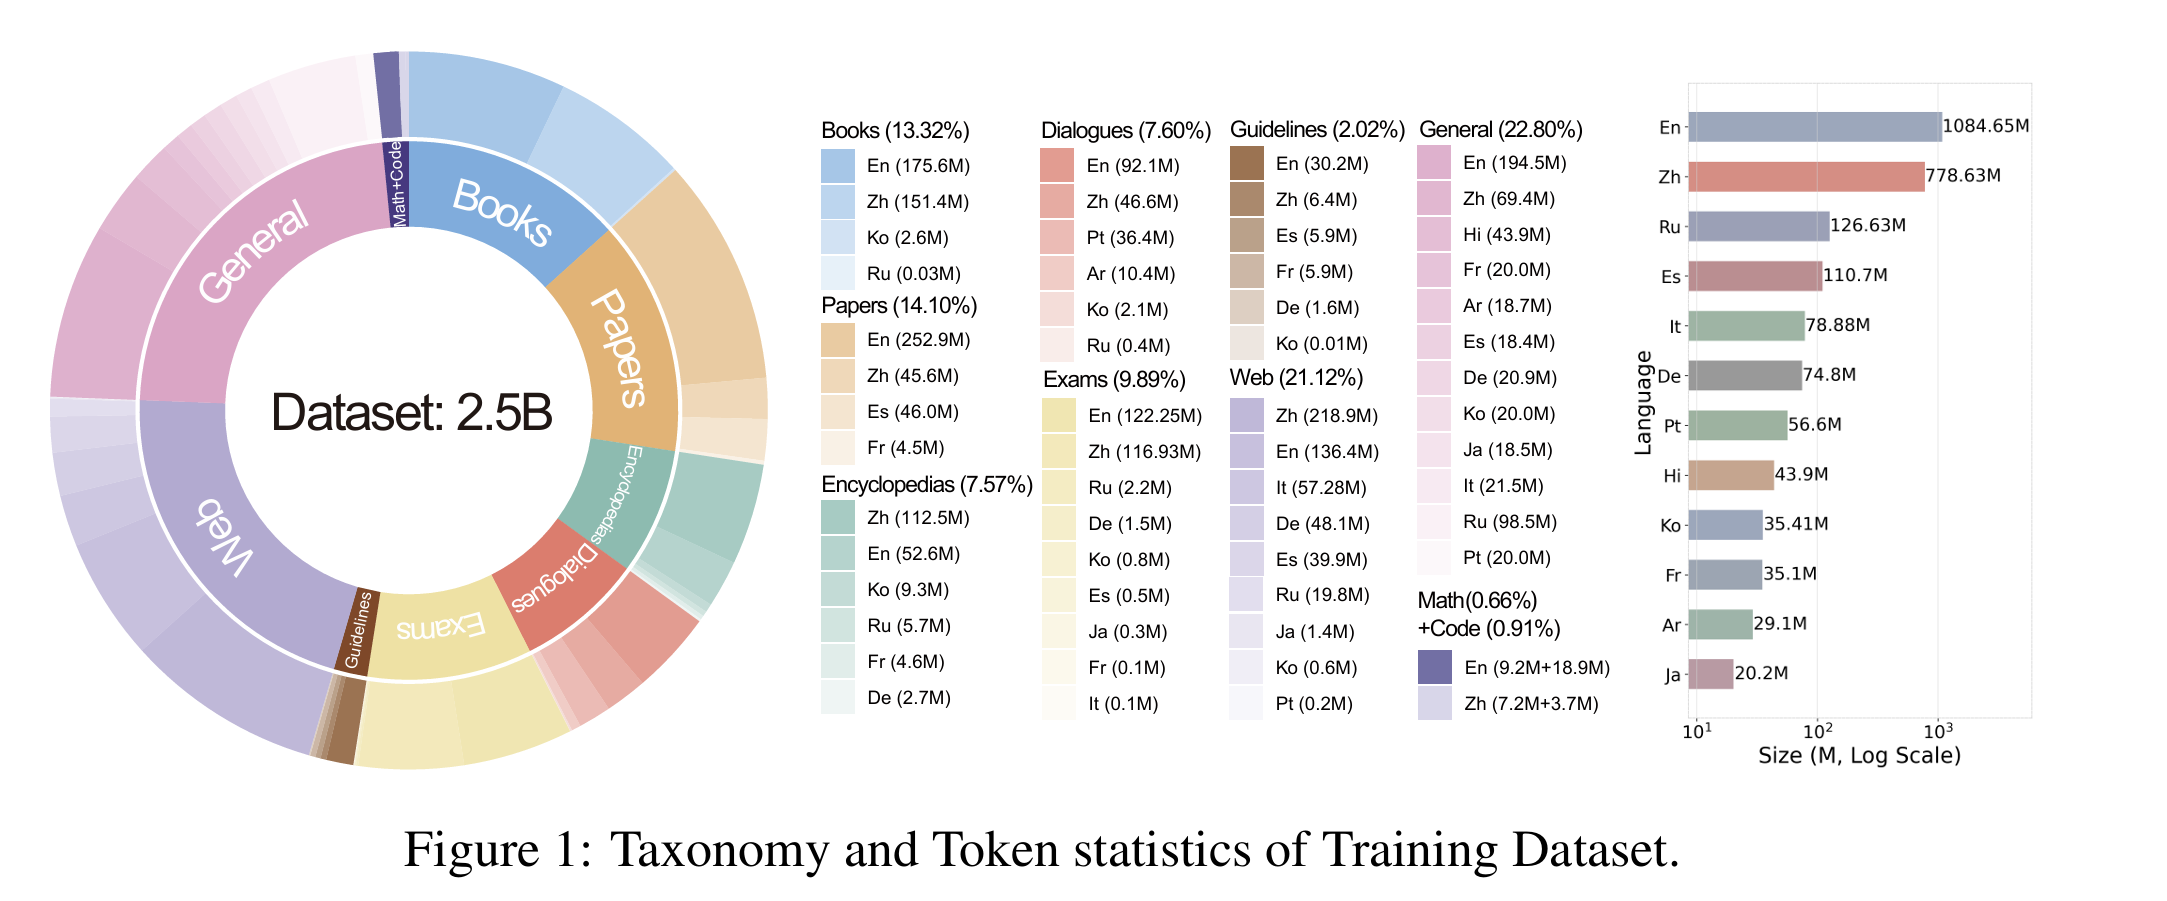
Evaluation 🤗 <a href="https://huggingface.co/datasets/FreedomIntelligence/ApolloMoEBench" target="_blank">ApolloMoEBench</a>
<details><summary>Click to expand</summary>EN:
ZH:
ES: Head_qa
FR:
HI: MMLU_HI
AR: MMLU_AR
JA: IgakuQA
KO: KorMedMCQA
IT:
DE: BioInstructQA: German part
PT: BioInstructQA: Portuguese part
RU: RuMedBench
We take Apollo2-7B or Apollo-MoE-0.5B as example
Download Dataset for project:
bash 0.download_data.sh
Prepare test and dev data for specific model:
bash 1.data_process_test&dev.sh
Prepare train data for specific model (Create tokenized data in advance):
bash 2.data_process_train.sh
Train the model
bash 3.single_node_train.sh
Evaluate your model: Generate score for benchmark
bash 4.eval.sh
Please use the following citation if you intend to use our dataset for training or evaluation:
@misc{zheng2024efficientlydemocratizingmedicalllms,
      title={Efficiently Democratizing Medical LLMs for 50 Languages via a Mixture of Language Family Experts},
      author={Guorui Zheng and Xidong Wang and Juhao Liang and Nuo Chen and Yuping Zheng and Benyou Wang},
      year={2024},
      eprint={2410.10626},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2410.10626},
}