
Downloads · 30 days
49
1% of all-time downloads
ccdv/lsg-bart-base-16384-pubmed
lsg-bart-base-16384-pubmed is a summarization model from ccdv. Use it when you need a shorter version of a longer text. It is set up for transformers.
should probably proofread and complete it, then remove this comment. --
Downloads · 30 days
49
1% of all-time downloads
All-time downloads
6.2K
Public
Repo size
2 GB
Likes
6
Public
Click a slice to open those files.
.bin654 MB · 99%
From the Hugging Face model README
Transformers >= 4.36.1
This model relies on a custom modeling file, you need to add trust_remote_code=True
See #13467
LSG ArXiv paper.
Github/conversion script is available at this link.
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM, pipeline

tokenizer = AutoTokenizer.from_pretrained("ccdv/lsg-bart-base-16384-pubmed", trust_remote_code=True)
model = AutoModelForSeq2SeqLM.from_pretrained("ccdv/lsg-bart-base-16384-pubmed", trust_remote_code=True)

text = "Replace by what you want."
pipe = pipeline("text2text-generation", model=model, tokenizer=tokenizer, device=0)
generated_text = pipe(
  text,
  truncation=True,
  max_length=64,
  no_repeat_ngram_size=7,
  num_beams=2,
  early_stopping=True
  )
This model is a fine-tuned version of ccdv/lsg-bart-base-4096-pubmed on the scientific_papers pubmed dataset.
The model is converted to handle 16384 long sequences and fine-tuned accordingly during 1 epoch.
It achieves the following results on the test set:
| Length | Global tokens | Fine-tuning | Block Size | Sparsity | Connexions | R1 | R2 | RL | RLsum |
|---|---|---|---|---|---|---|---|---|---|
| 16384 | 64 | Full | 256 | 0 | 768 | 48.32 | 22.52 | 29.36 | 44.57 |
| 16384 | 1 | Full | 256 | 0 | 768 | 48.26 | 22.53 | 29.40 | 44.51 |
| 16384 | 64 | Global only | 256 | 0 | 768 | 48.12 | 20.46 | 29.34 | 44.40 |
| 16384 | 1 | None | 256 | 0 | 768 | 48.03 | 22.42 | 29.28 | 44.32 |
Reference model:
| Length | Global tokens | Fine-tuning | Block Size | Sparsity | Connexions | R1 | R2 | RL | RLsum |
|---|---|---|---|---|---|---|---|---|---|
| 4096 | 1 | - | 256 | 0 | 768 | 47.37 | 21.74 | 28.59 | 43.67 |
The model relies on Local-Sparse-Global attention to handle long sequences:
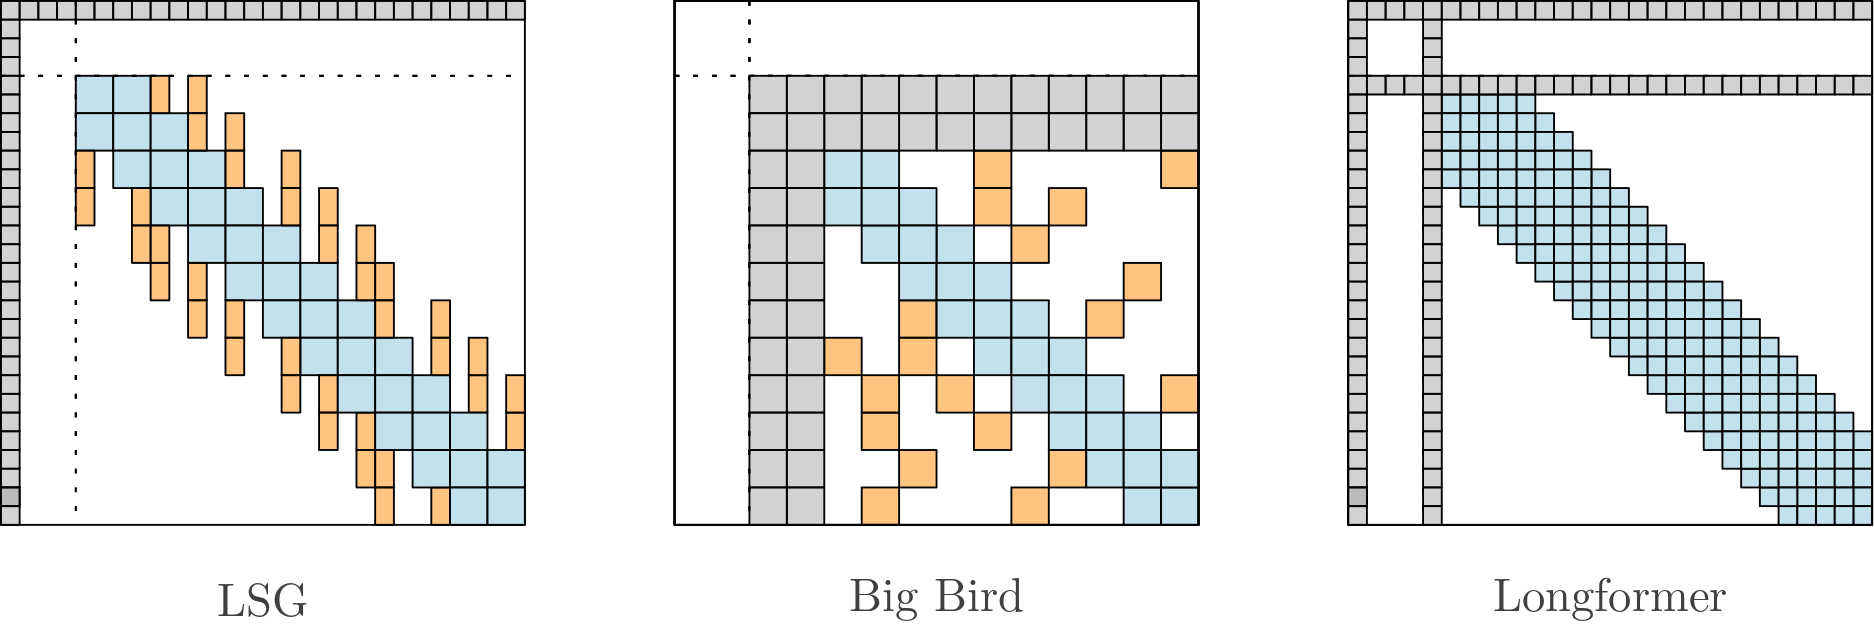
The model has about ~145 millions parameters (6 encoder layers - 6 decoder layers).
The model is warm started from ccdv/lsg-bart-base-4096-pubmed, converted to handle long sequences (encoder only) and fine tuned.
More information needed
More information needed
The following hyperparameters were used during training:
The following hyperparameters were used during generation: