
Downloads · 30 days
10
4% of all-time downloads
catallama/CataLlama-v0.2-Instruct-SFT-DPO-Merged
CataLlama-v0.2-Instruct-SFT-DPO-Merged is a text generation model from catallama. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
Downloads · 30 days
10
4% of all-time downloads
All-time downloads
279
Public
Parameters
8B
16.1 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors16.1 GB · 100%
From the Hugging Face model README
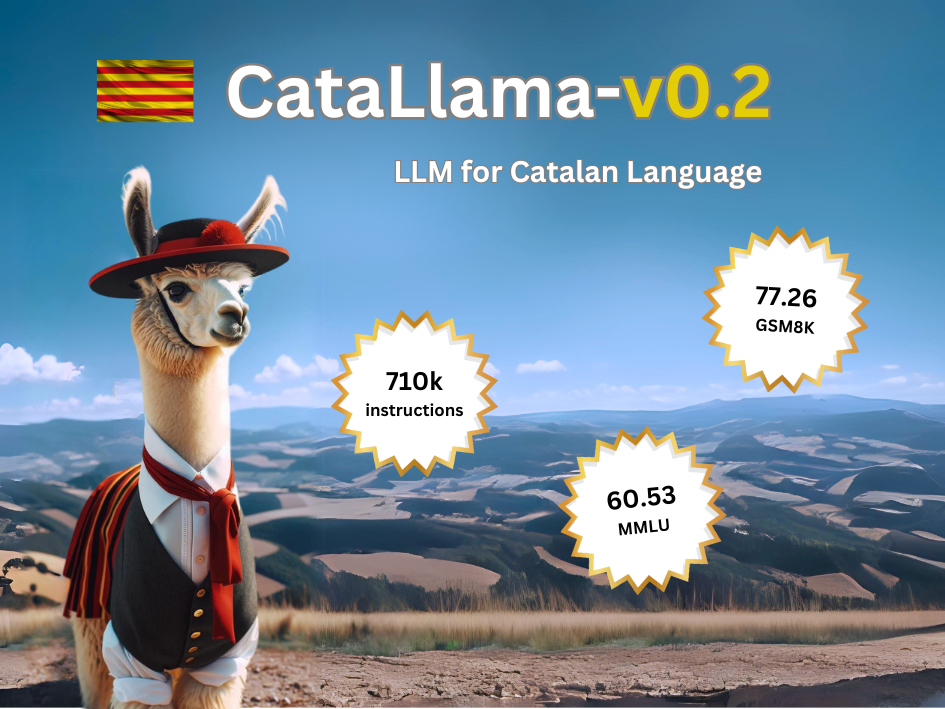
CataLlama-v0.2-Instruct-SFT-DPO-Merged is a merge between catallama/CataLlama-v0.2-Instruct-SFT and catallama/CataLlama-v0.2-Instruct-DPO
The resulting model scores better than it's parents on both MMLU and GSM8K.
This is an instruction fine-tuned model, optimised with DPO, proficient on the following tasks in Catalan
Model developers Laurentiu Petrea based on Llama-3 from Meta.
Model Architecture CataLlama is an auto-regressive language model that uses an optimized transformer architecture. The tuned versions use supervised fine-tuning (SFT) and direct preference optimisation (DPO) to align with human preferences for helpfulness and safety.
License The model uses the llama-3 license available at: https://llama.meta.com/llama3/license
| Model | CataLlama-v0.2-Instruct-DPO | CataLlama-v0.2-Instruct-SFT | CataLlama-v0.2-Instruct-SFT-DPO-Merged |
|---|---|---|---|
| MMLU 5 shot | 58.89 | 59.35 | 60.53 |
| GSM8K CoT 8 shot | 60.05 | 76.04 | 77.26 |
See the snippet below for usage with Transformers:
The model follows the same prompt template as Llama-3 Instruct
import transformers
import torch

model_id = "catallama/CataLlama-v0.2-Instruct-SFT-DPO-Merged"

pipeline = transformers.pipeline(
    "text-generation",
    model=model_id,
    model_kwargs={"torch_dtype": torch.bfloat16},
    device_map="auto",
)

messages = [
    {"role": "user", "content": "Ei com estàs avui?"},
]

prompt = pipeline.tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True
)

outputs = pipeline(
    prompt,
    max_new_tokens=1024,
    do_sample=True,
    temperature=0.6,
    top_p=0.9,
)

print(outputs[0]["generated_text"][len(prompt):])
The merge was performed between the 32 layers of the two models, excluding the embedding, norm and the head layers.
The weights of the 32 layers were merged in equal proportion simply by calculating the average of the corresponding weights from the parent models.
The embedding, norm and head layers are copied from CataLlama-v0.2-Instruct-DPO without modification.
This was done with a custom script, without mergekit.
Note: This model is not intended to beat benchmarks, but to demonstrate techniques for augmenting LLMs on new languages and preserve rare languages as part of our world heritage.
Intended Use Cases Llama 3 is intended for commercial and research use in English. Instruction tuned models are intended for assistant-like chat, whereas pretrained models can be adapted for a variety of natural language generation tasks.
Out-of-scope Use in any manner that violates applicable laws or regulations (including trade compliance laws). Use in any other way that is prohibited by the Acceptable Use Policy and Llama 3 Community License. Use in languages other than English**.
**Note: Developers may fine-tune Llama 3 models for languages beyond English provided they comply with the Llama 3 Community License and the Acceptable Use Policy.