
Downloads · 30 days
0
bird-of-paradise/deepseek-mla
deepseek-mla is a text generation model from bird-of-paradise. Use it when you need the model to write or continue text. It is set up for deepseek-mla. The card lists the license as mit.
This repository provides a PyTorch implementation of the Multi-Head Latent Attention (MLA) mechanism introduced in the DeepSeek-V2 paper. This is not a trained model, but rather a modular attention implementation that…
Downloads · 30 days
0
Access
Public
Updated Feb 27, 2025
Repo size
—
Likes
19
Public
Click a slice to open those files.
.png704 KB · 92%
From the Hugging Face model README
This repository provides a PyTorch implementation of the Multi-Head Latent Attention (MLA) mechanism introduced in the DeepSeek-V2 paper. This is not a trained model, but rather a modular attention implementation that significantly reduces KV cache for efficient inference while maintaining model performance through its innovative architecture. It can be used as a drop-in attention module in transformer architectures.
This repository is part of a series implementing the key architectural innovations from the DeepSeek paper. See the Related Implementations section for the complete series.
Clone this repository:
git clone https://huggingface.co/bird-of-paradise/deepseek-mla
Or download directly from the HuggingFace repository page.
import torch
from src.mla import MultiHeadLatentAttention

# Initialize MLA
mla = MultiHeadLatentAttention(
    d_model=512,      # Model dimension
    num_head=8,       # Number of attention heads
    d_embed=512,      # Embedding dimension
    d_c=64,          # KV compression dimension
    d_c1=64,         # Query compression dimension
    d_rotate=32,     # Rotary embedding dimension
)

# Input sequence
x = torch.randn(2, 10, 512)  # [batch_size, seq_len, d_model]

# Forward pass
output = mla(x)
To run the test suite, execute the following command from the project root directory:
python -m src.tests.test_mla
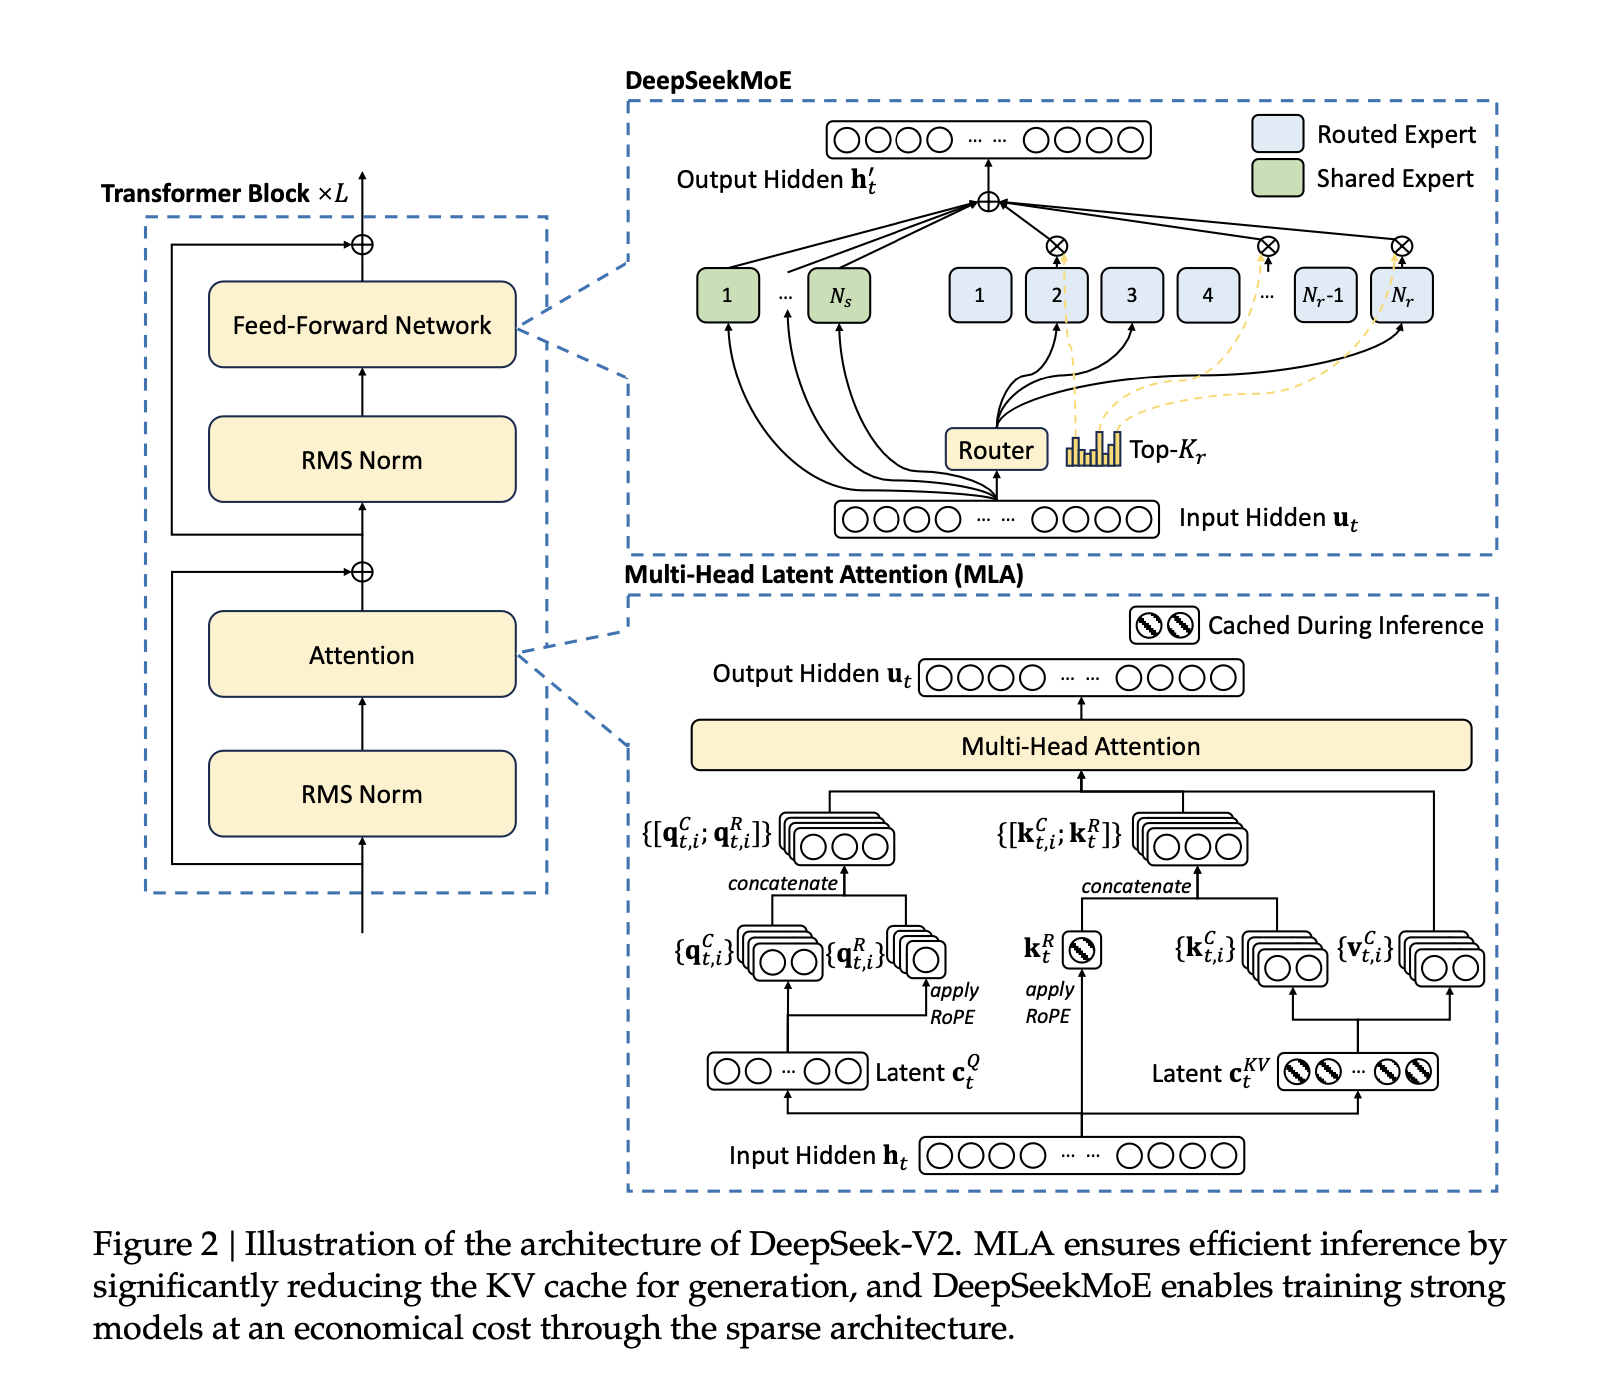
MLA combines two key innovations:
For detailed architectural insights, see insights/architecture.md.
During inference, MLA maintains two caches:
cache_kv: [batch, max_len, d_c]    # Compressed KV states
cache_rk: [batch, max_len, d_r]    # Shared rotary key
For detailed insights on attention masking and caching, see insights/attention_mask.md.
# Standard self-attention
output = mla(sequence)

# Cross-attention
output = mla(query, key_value_states=context)
# Initial forward pass
output = mla(prompt, use_cache=True, start_pos=0)

# Generate tokens using cache
for i in range(max_new_tokens):
    output = mla(next_token, use_cache=True, start_pos=prompt_len + i)
The implementation closely follows the formulation in the DeepSeek-V2 paper:

Key aspects:
This repository is part of a series implementing the key architectural innovations from the DeepSeek paper:
DeepSeek Multi-head Latent Attention(This Repository): Implementation of DeepSeek's MLA mechanism for efficient KV cache usage during inference.
DeepSeek MoE: Implementation of DeepSeek's Mixture of Experts architecture that enables efficient scaling of model parameters.
Transformer Implementation Tutorial: A detailed tutorial on implementing transformer architecture with explanations of key components.
Together, these implementations cover the core innovations that power DeepSeek's state-of-the-art performance. By combining the MoE architecture with Multi-head Latent Attention, you can build a complete DeepSeek-style model with improved training efficiency and inference performance.
Contributions are welcome! Feel free to:
Please ensure all tests pass before submitting pull requests.
@misc{deepseek2024,
    title={DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model},
    author={DeepSeek-AI and et al.},
    year={2024},
    journal={arXiv preprint arXiv:2405.04434}
}