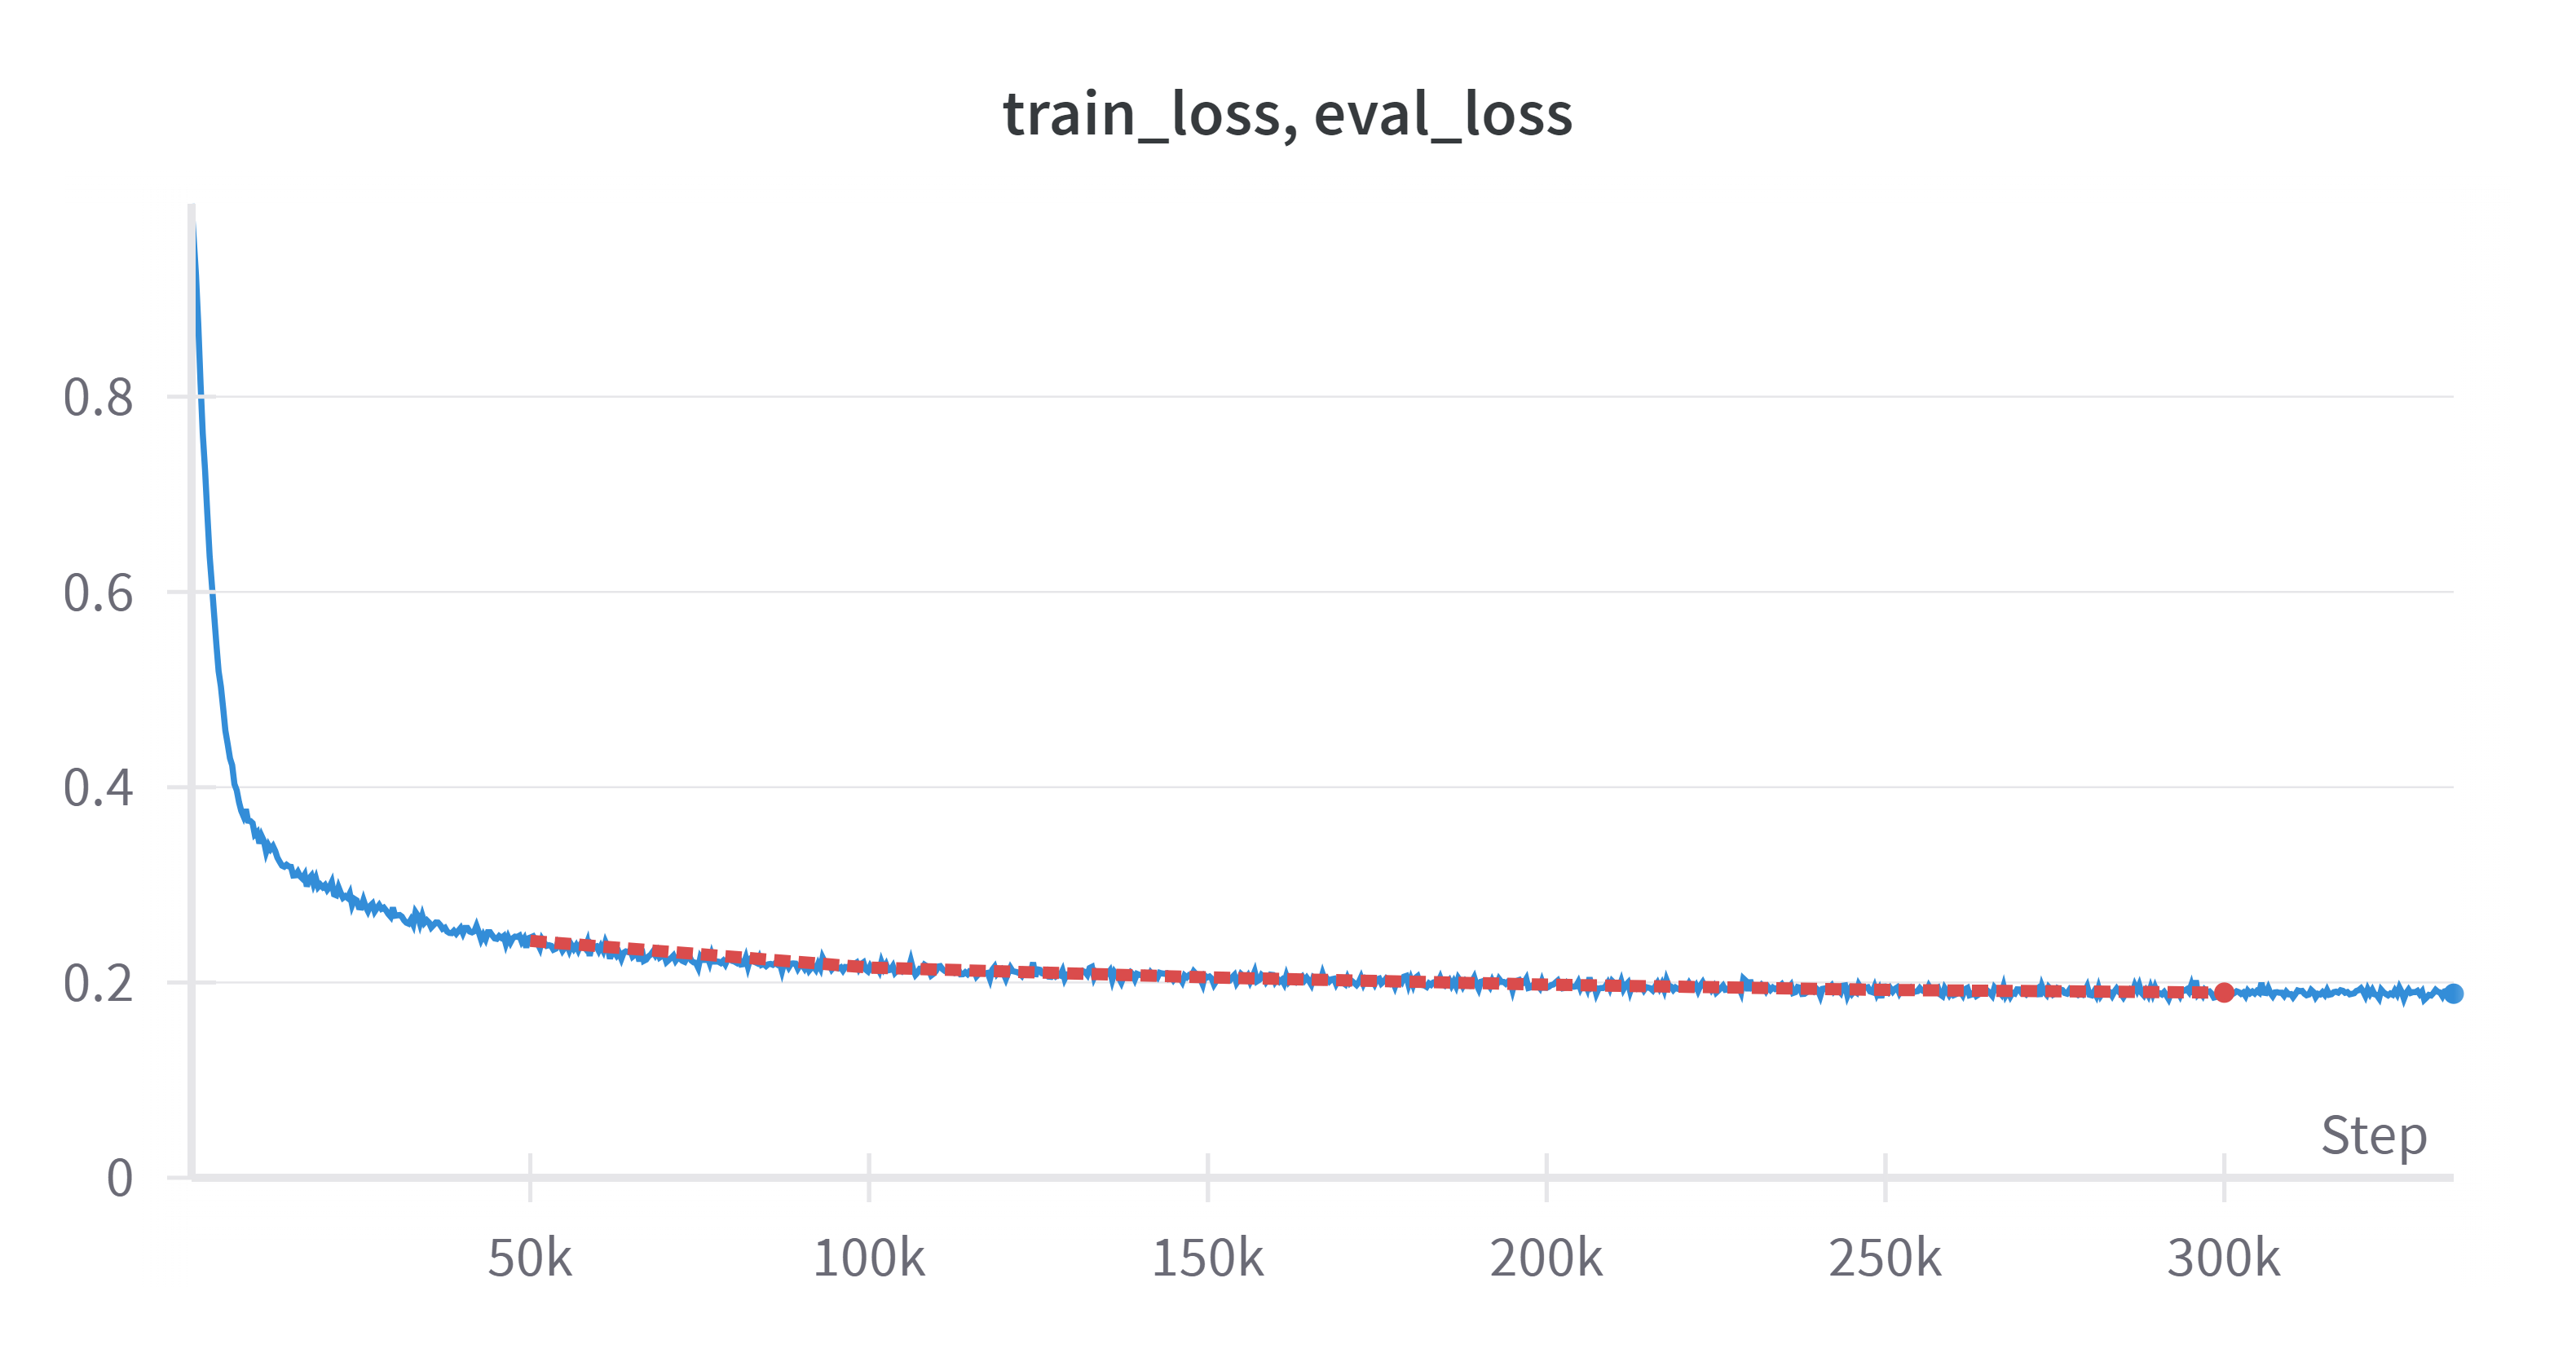
Downloads · 30 days
9
1% of all-time downloads
benchang1110/TaiVisionLM-base-v2
TaiVisionLM-base-v2 is a image-text-to-text model from benchang1110. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers.
Downloads · 30 days
9
1% of all-time downloads
All-time downloads
708
Public
Parameters
1.2B
9.6 GB on disk
Likes
5
Public
Click a slice to open those files.
.safetensors4.8 GB · 100%
From the Hugging Face model README
🌟 This is a small (only 1.2B parameters) visual language model on Hugging Face that responds to Traditional Chinese instructions given an image input! 🌟
✨ Developed compatible with the Transformers library, TaiVisionLM is quick to load, fine-tune, and use for lightning-fast inferences without needing any external libraries! ⚡️
Ready to experience the Traditional Chinese visual language model? Let's go! 🖼️🤖
🌟 TaiVisionLM 是一個小型的視覺語言模型(僅有 12 億參數),可以根據圖像輸入來回覆繁體中文指令!🌟
✨ TaiVisionLM 可以用 transformers 載入、微調和使用!⚡️
準備好體驗"臺視"了嗎?讓我們開始吧!🖼️🤖
This model is a multimodal large language model that combines SigLIP as its vision encoder with Tinyllama as its language model. The vision projector connects the two modalities together. Its architecture closely resembles PaliGemma.
Here's the summary of the development process:
Unimodal pretraining
Feature Alignment
Task Specific Training
這個模型是一個多模態的語言模型,結合了 SigLIP 作為其視覺編碼器,並使用 Tinyllama 作為語言模型。視覺投影器將這兩種模態結合在一起。
其架構與 PaliGemma 非常相似。
以下是開發過程的摘要:
In Transformers, you can load the model and do inference as follows:
IMPORTANT NOTE: TaiVisionLM model is not yet integrated natively into the Transformers library. So you need to set trust_remote_code=True when loading the model. It will download the configuration_taivisionlm.py, modeling_taivisionlm.py and processing_taivisionlm.py files from the repo. You can check out the content of these files under the Files and Versions tab and pin the specific versions if you have any concerns regarding malicious code.
from transformers import AutoProcessor, AutoModelForCausalLM, AutoConfig
from PIL import Image
import requests
import torch
config = AutoConfig.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True)
processor = AutoProcessor.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True,torch_dtype=torch.float16,attn_implementation="sdpa").to('cuda')
model.eval()
url = "https://media.wired.com/photos/598e35fb99d76447c4eb1f28/master/pass/phonepicutres-TA.jpg"
image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
text = "描述圖片"
inputs = processor(text=text,images=image, return_tensors="pt",padding=False).to('cuda')
outputs = processor.tokenizer.decode(model.generate(**inputs,max_length=512)[0])
print(outputs)
利用 transformers,可以用下面程式碼進行推論:
重要通知: 台視 (TaiVisionLM) 還沒被整合進transformers,因此在下載模型時要使用 trust_remote_code=True,下載模型將會使用configuration_taivisionlm.py、 modeling_taivisionlm.py 和 processing_taivisionlm.py 這三個檔案,若擔心有惡意程式碼,請先點選右方 Files and Versions 來查看程式碼內容。
from transformers import AutoProcessor, AutoModelForCausalLM, AutoConfig
from PIL import Image
import requests
import torch
config = AutoConfig.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True)
processor = AutoProcessor.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained("benchang1110/TaiVisionLM-base-v2",trust_remote_code=True,torch_dtype=torch.float16,attn_implementation="sdpa").to('cuda')
model.eval()
url = "https://media.wired.com/photos/598e35fb99d76447c4eb1f28/master/pass/phonepicutres-TA.jpg"
image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
text = "描述圖片"
inputs = processor(text=text,images=image, return_tensors="pt",padding=False).to('cuda')
outputs = processor.tokenizer.decode(model.generate(**inputs,max_length=512)[0])
print(outputs)
| Data size | Global Batch Size | Learning Rate | Epochs | Max Length | Weight Decay |
|---|---|---|---|---|---|
| 1.35M | 4 | 5e-3 | 1 | 1024 | 0 |
We use full-parameter finetuning for the projector and apply LoRA to the language model.
We will update the training procedure once we have more resources to train the model on the whole dataset.