
Downloads · 30 days
15
2% of all-time downloads
aurelio-ai/xclip-base-patch16-zero-shot
xclip-base-patch16-zero-shot is a video classification model from aurelio-ai. Use it for the video classification task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as mit.
X-CLIP model (base-sized, patch resolution of 16) trained on Kinetics-400. It was introduced in the paper Expanding Language-Image Pretrained Models for General Video Recognition by Ni et al. and first released in thi…
Downloads · 30 days
15
2% of all-time downloads
All-time downloads
802
Public
Parameters
195M
1.6 GB on disk
Likes
1
Public
Click a slice to open those files.
.bin780 MB · 50%
How the weights are stored.
F32195M · 100%
From the Hugging Face model README
X-CLIP model (base-sized, patch resolution of 16) trained on Kinetics-400. It was introduced in the paper Expanding Language-Image Pretrained Models for General Video Recognition by Ni et al. and first released in this repository.
This model was trained using 32 frames per video, at a resolution of 224x224.
Disclaimer: The team releasing X-CLIP did not write a model card for this model so this model card has been written by the Hugging Face team.
X-CLIP is a minimal extension of CLIP for general video-language understanding. The model is trained in a contrastive way on (video, text) pairs.
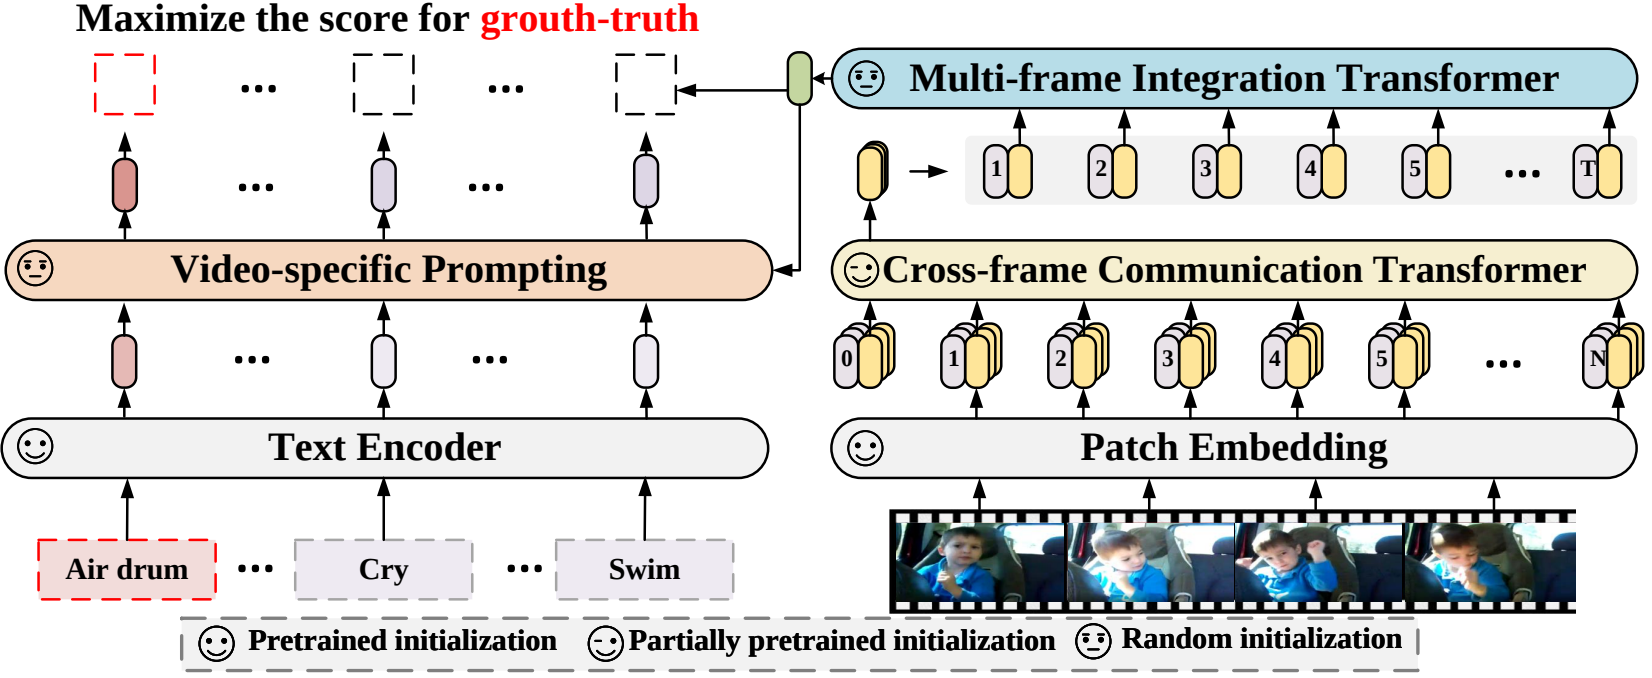
This allows the model to be used for tasks like zero-shot, few-shot or fully supervised video classification and video-text retrieval.
You can use the raw model for determining how well text goes with a given video. See the model hub to look for fine-tuned versions on a task that interests you.
For code examples, we refer to the documentation.
This model was trained on Kinetics 400.
The exact details of preprocessing during training can be found here.
The exact details of preprocessing during validation can be found here.
During validation, one resizes the shorter edge of each frame, after which center cropping is performed to a fixed-size resolution (like 224x224). Next, frames are normalized across the RGB channels with the ImageNet mean and standard deviation.
This model achieves a zero-shot top-1 accuracy of 44.6% on HMDB-51, 72.0% on UCF-101 and 65.2% on Kinetics-600.