
Downloads · 30 days
12
15% of all-time downloads
alphaedge-ai/SmolLM3-3B-eng-16384
SmolLM3-3B-eng-16384 is a text generation model from alphaedge-ai. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
This model is a 7.45% smaller version of HuggingFaceTB/SmolLM3-3B optimized for English language via vocabulary size reduction using the trimming method. This trimmed model should perform similarly to the original mod…
Downloads · 30 days
12
15% of all-time downloads
All-time downloads
81
Public
Parameters
2.8B
5.7 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors5.7 GB · 100%
From the Hugging Face model README
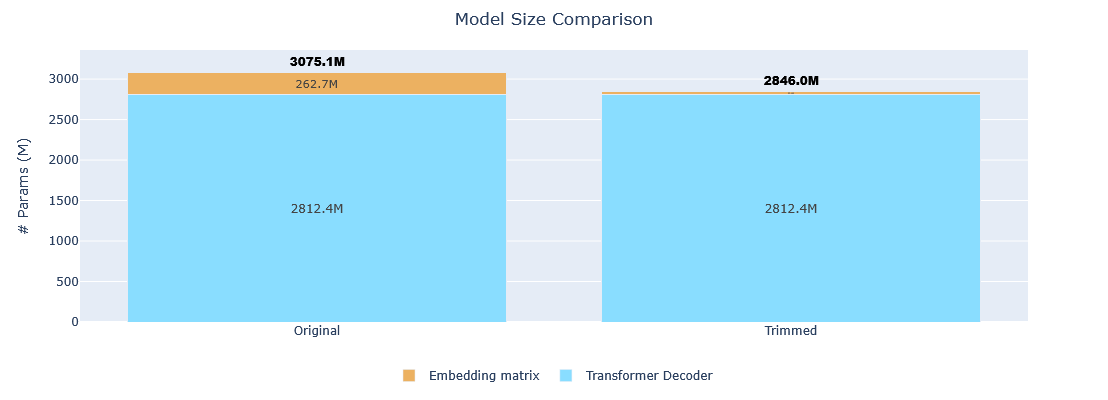
This model is a 7.45% smaller version of HuggingFaceTB/SmolLM3-3B optimized for English language via vocabulary size reduction using the trimming method.
This trimmed model should perform similarly to the original model with only 16,384 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary.
| Metric | Original | Trimmed | Reduction |
|---|---|---|---|
| Vocabulary size | 128,256 tokens | 16,384 tokens | 87.23% |
| Model size | 3,075,098,624 params | 2,845,984,768 params | 7.45% |
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "alphaedge-ai/SmolLM3-3B-eng-16384"
device = "cuda"  # for GPU usage or "cpu" for CPU usage

# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
).to(device)

# prepare the model input
prompt = "Your prompt in English."
messages = [
    {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

# Generate the output
generated_ids = model.generate(**model_inputs, max_new_tokens=32768)

# Get and decode the output
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):]
print(tokenizer.decode(output_ids, skip_special_tokens=True))
To enable/disable thinking mode, use the /think or /no_think flag in the system prompt:
messages = [
    {"role": "system", "content": "/no_think"},
    {"role": "user", "content": prompt}
]
@misc{bakouch2025smollm3,
      title={SmolLM3: smol, multilingual, long-context reasoner},
      author={akouch, Elie and Ben Allal, Loubna and Lozhkov, Anton and Tazi, Nouamane
               and Tunstall, Lewis and Patiño, Carlos Miguel and Beeching, Edward
               and Roucher, Aymeric and others},
      year={2025},
      howpublished={https://huggingface.co/blog/smollm3}
}
@misc{hf_blogpost_trimming,
      title={Introduction to Trimming},
      author={Loïck BOURDOIS and Tom AARSEN and Bram VANROY and Christopher AKIKI and Woojun JUNG and Manuel ROMERO and Prithiv SAKTHI},
      year={2026},
      url={https://huggingface.co/blog/lbourdois/introduction-to-trimming},
}