
Downloads · 30 days
86
28% of all-time downloads
alphaedge-ai/Qwen3-Embedding-sin-32768
Qwen3-Embedding-sin-32768 is a sentence similarity model from alphaedge-ai. Use it when you need a score for how close two texts are. It is set up for sentence-transformers. The card lists the license as apache-2.0.
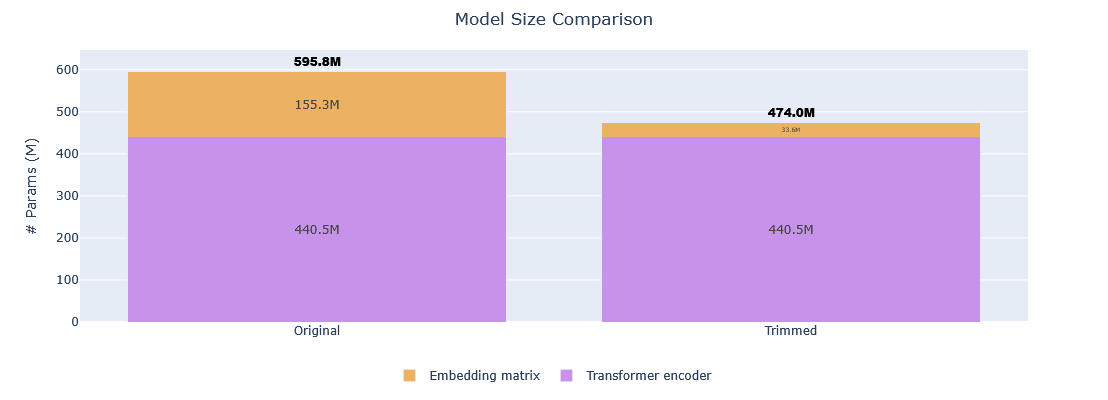
This model is a 20.44% smaller version of Qwen/Qwen3-Embedding-0.6B optimized for Sinhala language via vocabulary size reduction using the trimming method. This trimmed model should perform similarly to the original m…
Downloads · 30 days
86
28% of all-time downloads
All-time downloads
303
Public
Parameters
474M
948 MB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors948 MB · 100%
From the Hugging Face model README
This model is a 20.44% smaller version of Qwen/Qwen3-Embedding-0.6B optimized for Sinhala language via vocabulary size reduction using the trimming method.
This trimmed model should perform similarly to the original model with only 32,768 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary.
| Metric | Original | Trimmed | Reduction |
|---|---|---|---|
| Vocabulary size | 151,669 tokens | 32,768 tokens | 78.40% |
| Model size | 595,776,512 params | 474,021,888 params | 20.44% |
from sentence_transformers import SentenceTransformer
# Download from the 🤗 Hub
model = SentenceTransformer("alphaedge-ai/Qwen3-Embedding-sin-32768")
# Run inference with queries and documents
query = "My query in Sinhala"
documents = [
    "Chunk in Sinhala",
    "Chunk in Sinhala",
    "Chunk in Sinhala",
]
query_embeddings = model.encode_query(query)
document_embeddings = model.encode_document(documents)
print(query_embeddings.shape, document_embeddings.shape)
# Compute similarities to determine a ranking
similarities = model.similarity(query_embeddings, document_embeddings)
print(similarities)
@article{qwen3embedding,
  title={Qwen3 Embedding: Advancing Text Embedding and Reranking Through Foundation Models},
  author={Zhang, Yanzhao and Li, Mingxin and Long, Dingkun and Zhang, Xin and Lin, Huan and Yang, Baosong and Xie, Pengjun and Yang, An and Liu, Dayiheng and Lin, Junyang and Huang, Fei and Zhou, Jingren},
  journal={arXiv preprint arXiv:2506.05176},
  year={2025}
}
@misc{hf_blogpost_trimming,
      title={Introduction to Trimming},
      author={Loïck BOURDOIS and Tom AARSEN and Bram VANROY and Christopher AKIKI and Woojun JUNG and Manuel ROMERO and Prithiv SAKTHI},
      year={2026},
      url={https://huggingface.co/blog/lbourdois/introduction-to-trimming},
}