
Downloads · 30 days
179
3% of all-time downloads
alimama-creative/EcomXL_controlnet_inpaint
EcomXL_controlnet_inpaint is a text-to-image model from alimama-creative. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as apache-2.0.
EcomXL contains a series of text-to-image diffusion models optimized for e-commerce scenarios, developed based on Stable Diffusion XL.<br/ For e-commerce scenarios, we trained Inpaint ControlNet to control diffusion m…
Downloads · 30 days
179
3% of all-time downloads
All-time downloads
7.1K
Public
Parameters
1.3B
2.5 GB on disk
Likes
46
Public
Click a slice to open those files.
.safetensors2.5 GB · 100%
From the Hugging Face model README
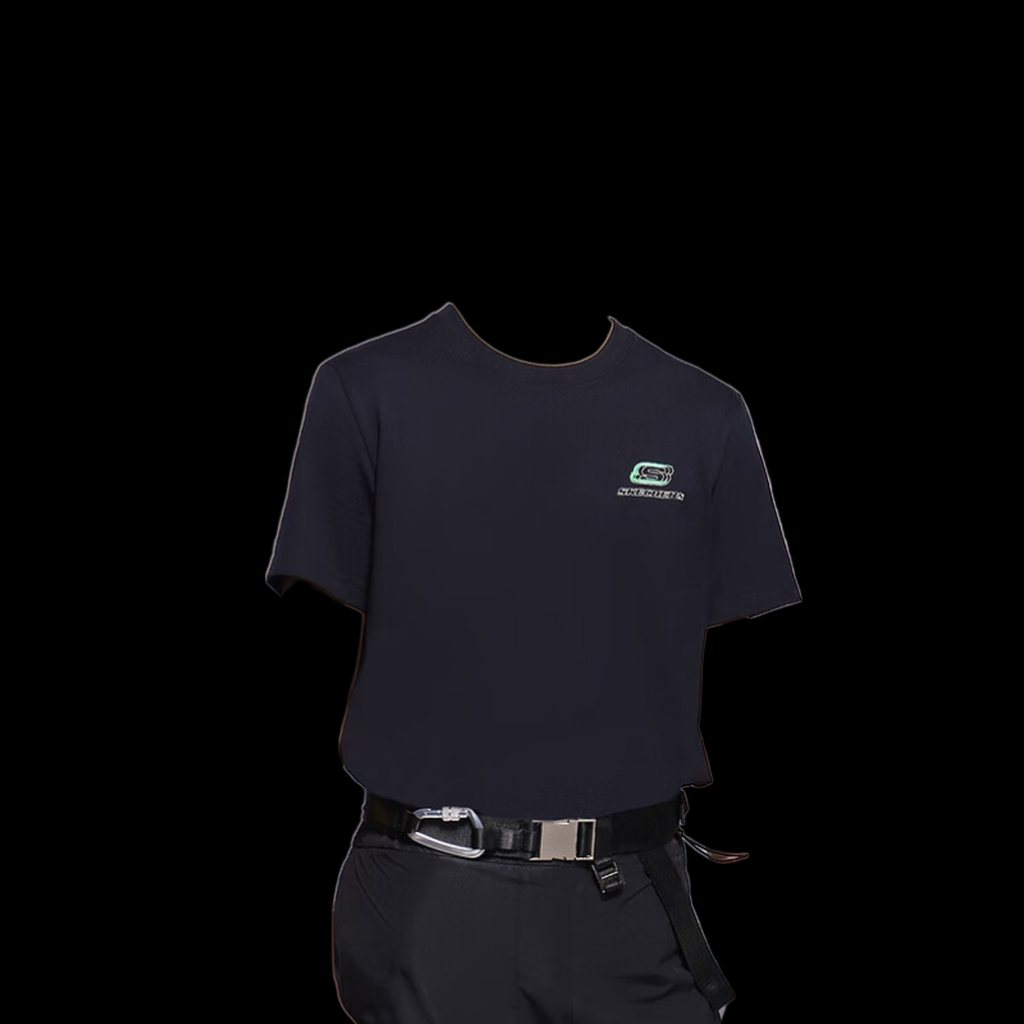
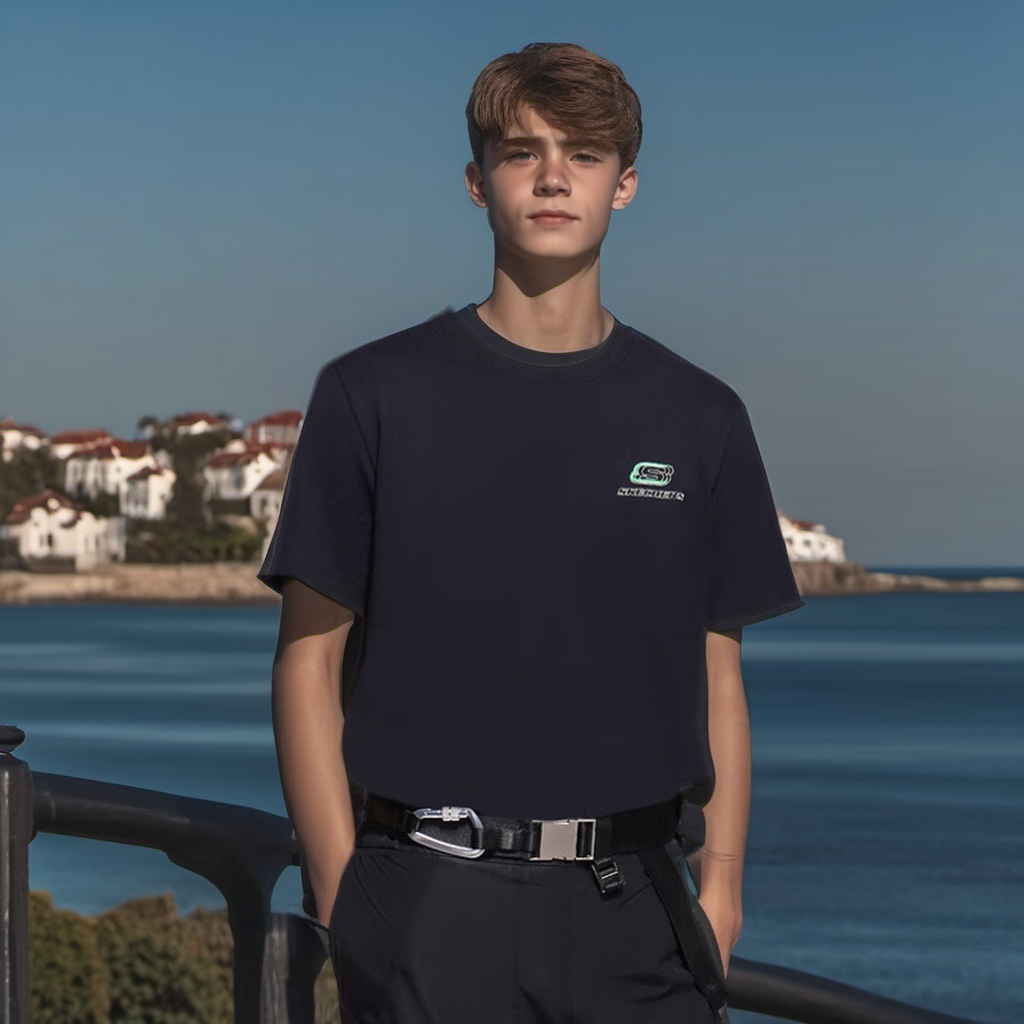
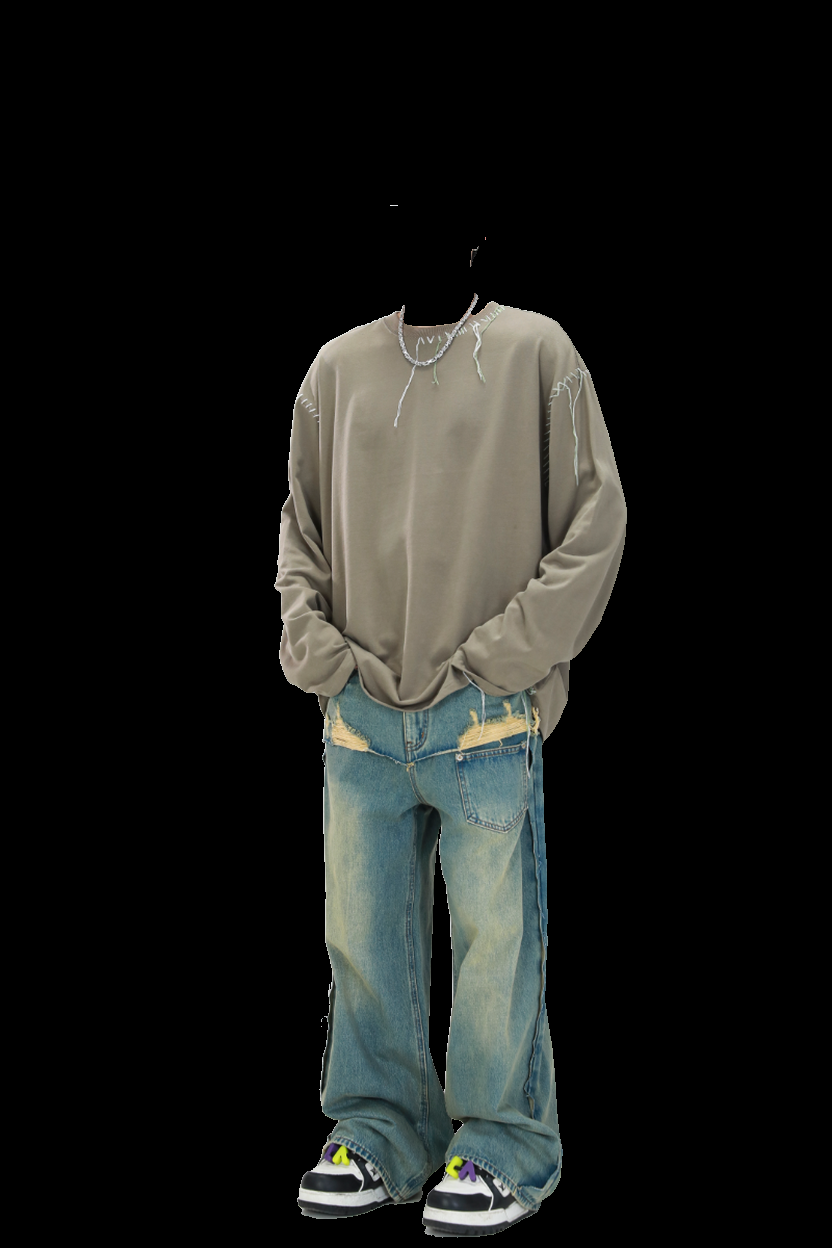
EcomXL contains a series of text-to-image diffusion models optimized for e-commerce scenarios, developed based on Stable Diffusion XL.<br/> For e-commerce scenarios, we trained Inpaint ControlNet to control diffusion models. Unlike the inpaint controlnets used for general scenarios, this model is fine-tuned with instance masks to prevent foreground outpainting.
These cases are generated using AUTOMATIC1111/stable-diffusion-webui.
<span style="width: 150px !important;display: inline-block;">Foreground<span> | <span style="width: 150px !important;display: inline-block;">Mask<span> | <span style="width: 150px !important;display: inline-block;">w/o instance mask<span> | <span style="width: 150px !important;display: inline-block;">w/ instance mask<span> |
|---|---|---|---|
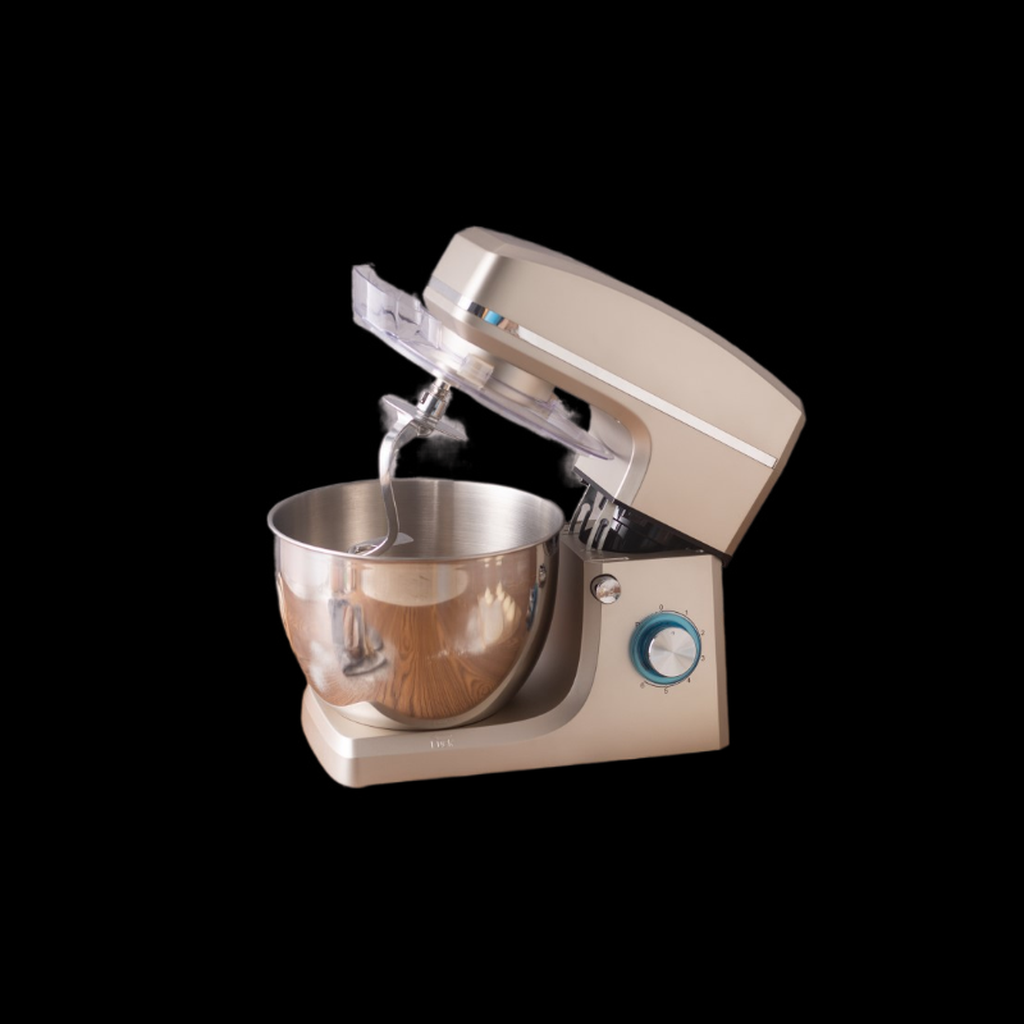 | 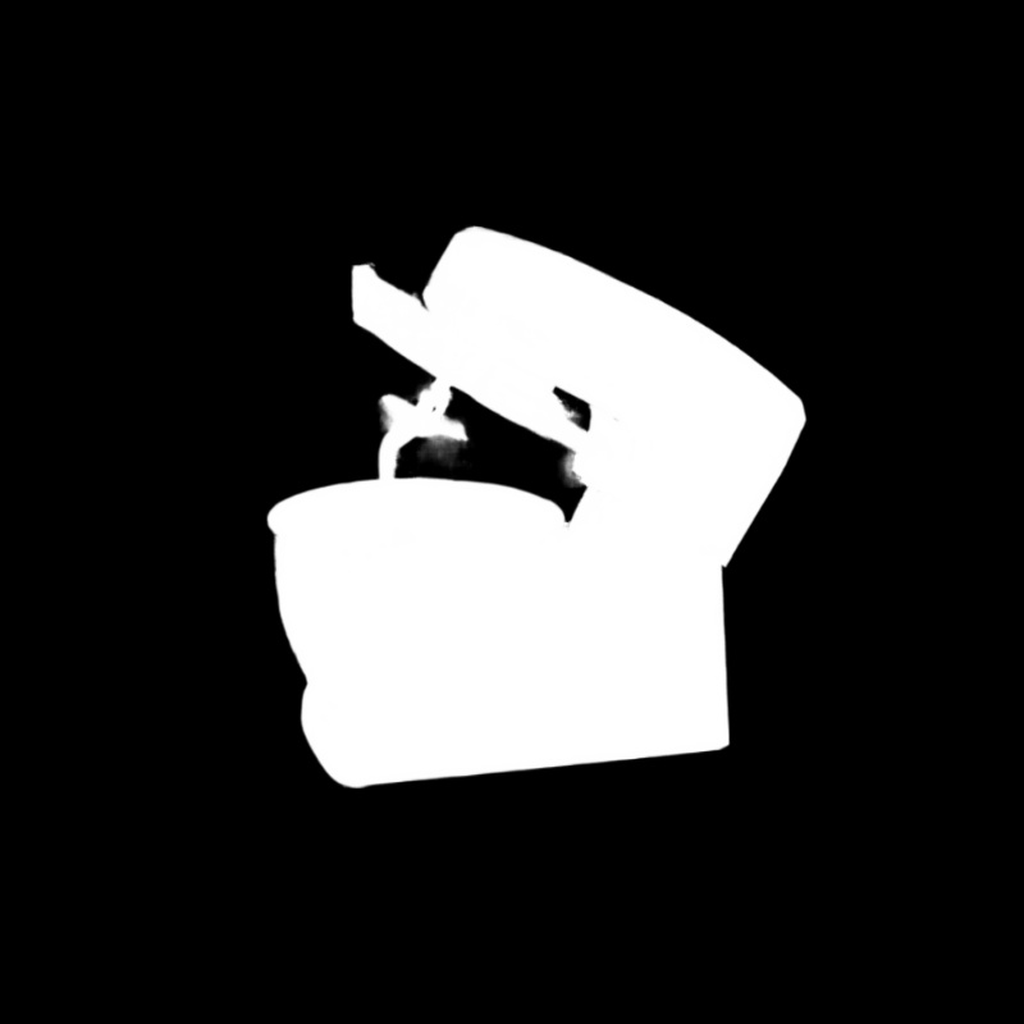 | 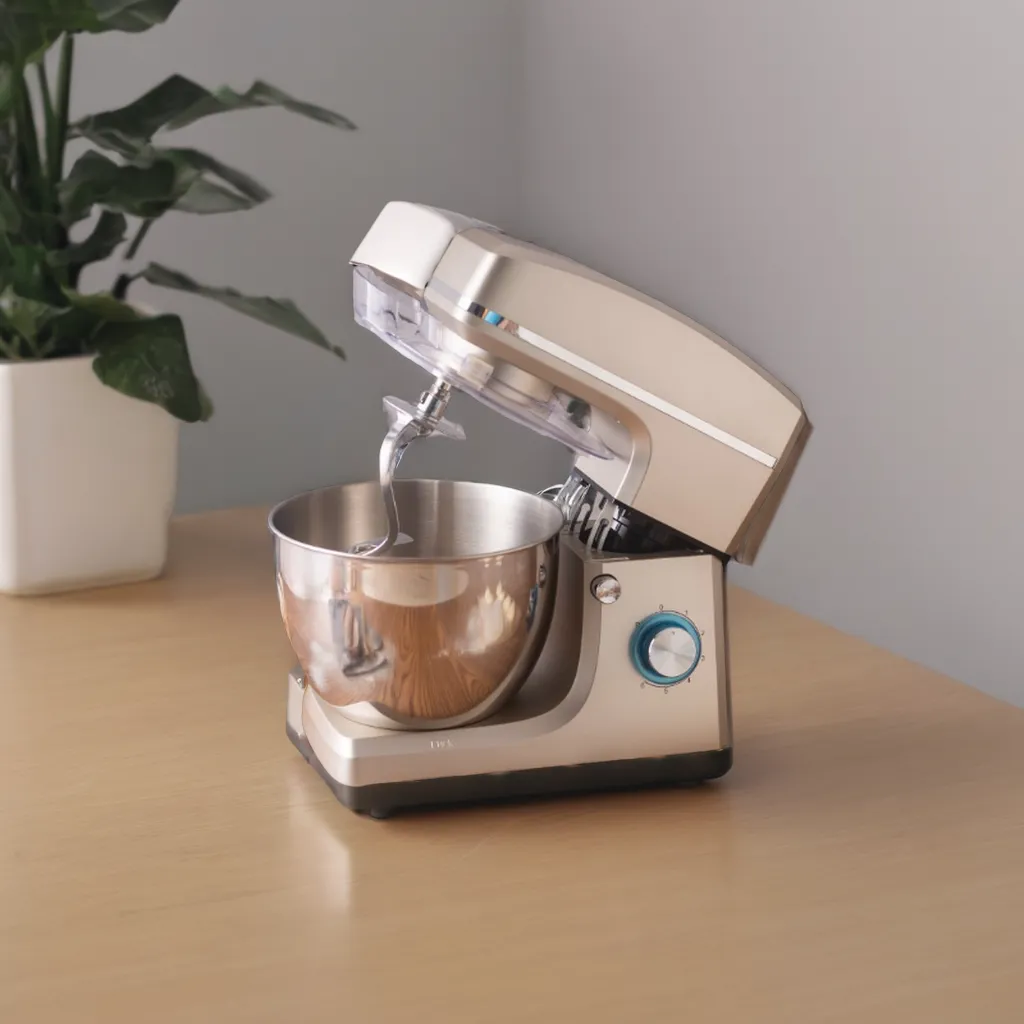 | 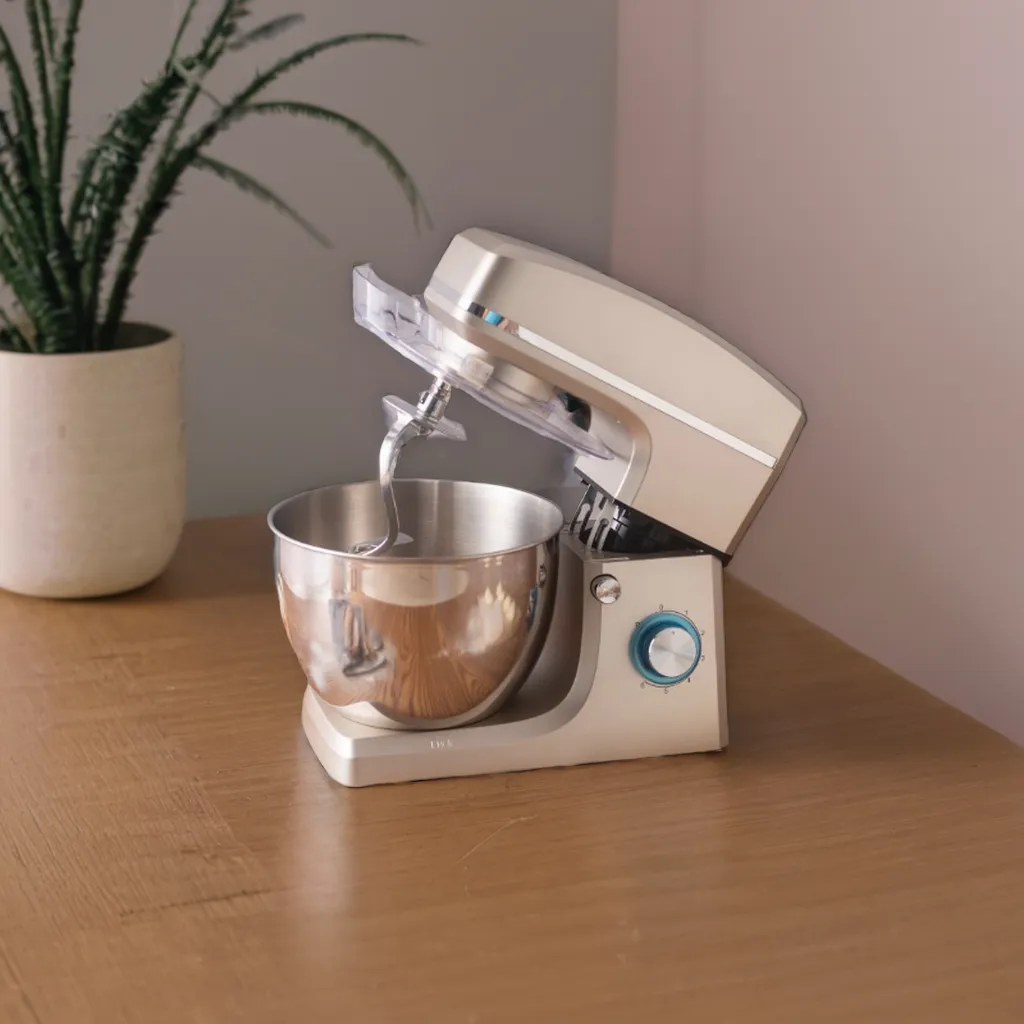 |
 |  |  |  |
 |  |  |  |
from diffusers import (
    ControlNetModel,
    StableDiffusionXLControlNetPipeline,
    DDPMScheduler
)
from diffusers.utils import load_image
import torch
from PIL import Image
import numpy as np

def make_inpaint_condition(init_image, mask_image):
    init_image = np.array(init_image.convert("RGB")).astype(np.float32) / 255.0
    mask_image = np.array(mask_image.convert("L")).astype(np.float32) / 255.0
    assert init_image.shape[0:1] == mask_image.shape[0:1], "image and image_mask must have the same image size"
    init_image[mask_image > 0.5] = -1.0  # set as masked pixel
    init_image = np.expand_dims(init_image, 0).transpose(0, 3, 1, 2)
    init_image = torch.from_numpy(init_image)
    return init_image

def add_fg(full_img, fg_img, mask_img):
    full_img = np.array(full_img).astype(np.float32)
    fg_img = np.array(fg_img).astype(np.float32)
    mask_img = np.array(mask_img).astype(np.float32) / 255.
    full_img = full_img * mask_img + fg_img * (1-mask_img)
    return Image.fromarray(np.clip(full_img, 0, 255).astype(np.uint8))

controlnet = ControlNetModel.from_pretrained(
    "alimama-creative/EcomXL_controlnet_inpaint",
    use_safetensors=True,
)

pipe = StableDiffusionXLControlNetPipeline.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0",
    controlnet=controlnet,
)
pipe.to("cuda")
pipe.scheduler = DDPMScheduler.from_config(pipe.scheduler.config)

image = load_image(
    "https://huggingface.co/alimama-creative/EcomXL_controlnet_inpaint/resolve/main/images/inp_0.png"
)
mask = load_image(
    "https://huggingface.co/alimama-creative/EcomXL_controlnet_inpaint/resolve/main/images/inp_1.png"
)
mask = Image.fromarray(255 - np.array(mask))

control_image = make_inpaint_condition(image, mask)

prompt="a product on the table"

generator = torch.Generator(device="cuda").manual_seed(1234)

res_image = pipe(
    prompt,
    image=control_image,
    num_inference_steps=25,
    guidance_scale=7,
    width=1024,
    height=1024,
    controlnet_conditioning_scale=0.5,
    generator=generator,
).images[0]

res_image = add_fg(res_image, image, mask)
res_image.save(f'res.png')
The model exhibits good performance when the controlnet weight (controlnet_condition_scale) is 0.5.
In the first phase, the model was trained on 12M laion2B and internal source images with random masks for 20k steps. In the second phase, the model was trained on 3M e-commerce images with the instance mask for 20k steps.<br> Mixed precision: FP16<br> Learning rate: 1e-4<br> batch size: 2048<br> Noise offset: 0.05