
Downloads · 30 days
7
7% of all-time downloads
alexu8007/NER_BERT
NER_BERT is a token classification model from alexu8007. Use it when you need labels on individual words, such as names. It is set up for transformers. The card lists the license as apache-2.0.
This is a distilbert-base-uncased model fine-tuned on the CoNLL-2023 dataset for the Named Entity Recognition (NER) task. It achieves a 94% F1-score on the validation set, demonstrating high accuracy in identifying pe…
Downloads · 30 days
7
7% of all-time downloads
All-time downloads
94
Public
Parameters
66.4M
265 MB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors265 MB · 100%
From the Hugging Face model README
This is a distilbert-base-uncased model fine-tuned on the CoNLL-2023 dataset for the Named Entity Recognition (NER) task. It achieves a 94% F1-score on the validation set, demonstrating high accuracy in identifying persons, organizations, locations, and miscellaneous entities in text.
This model is lightweight (66M parameters), making it fast and efficient for production environments while maintaining high performance.
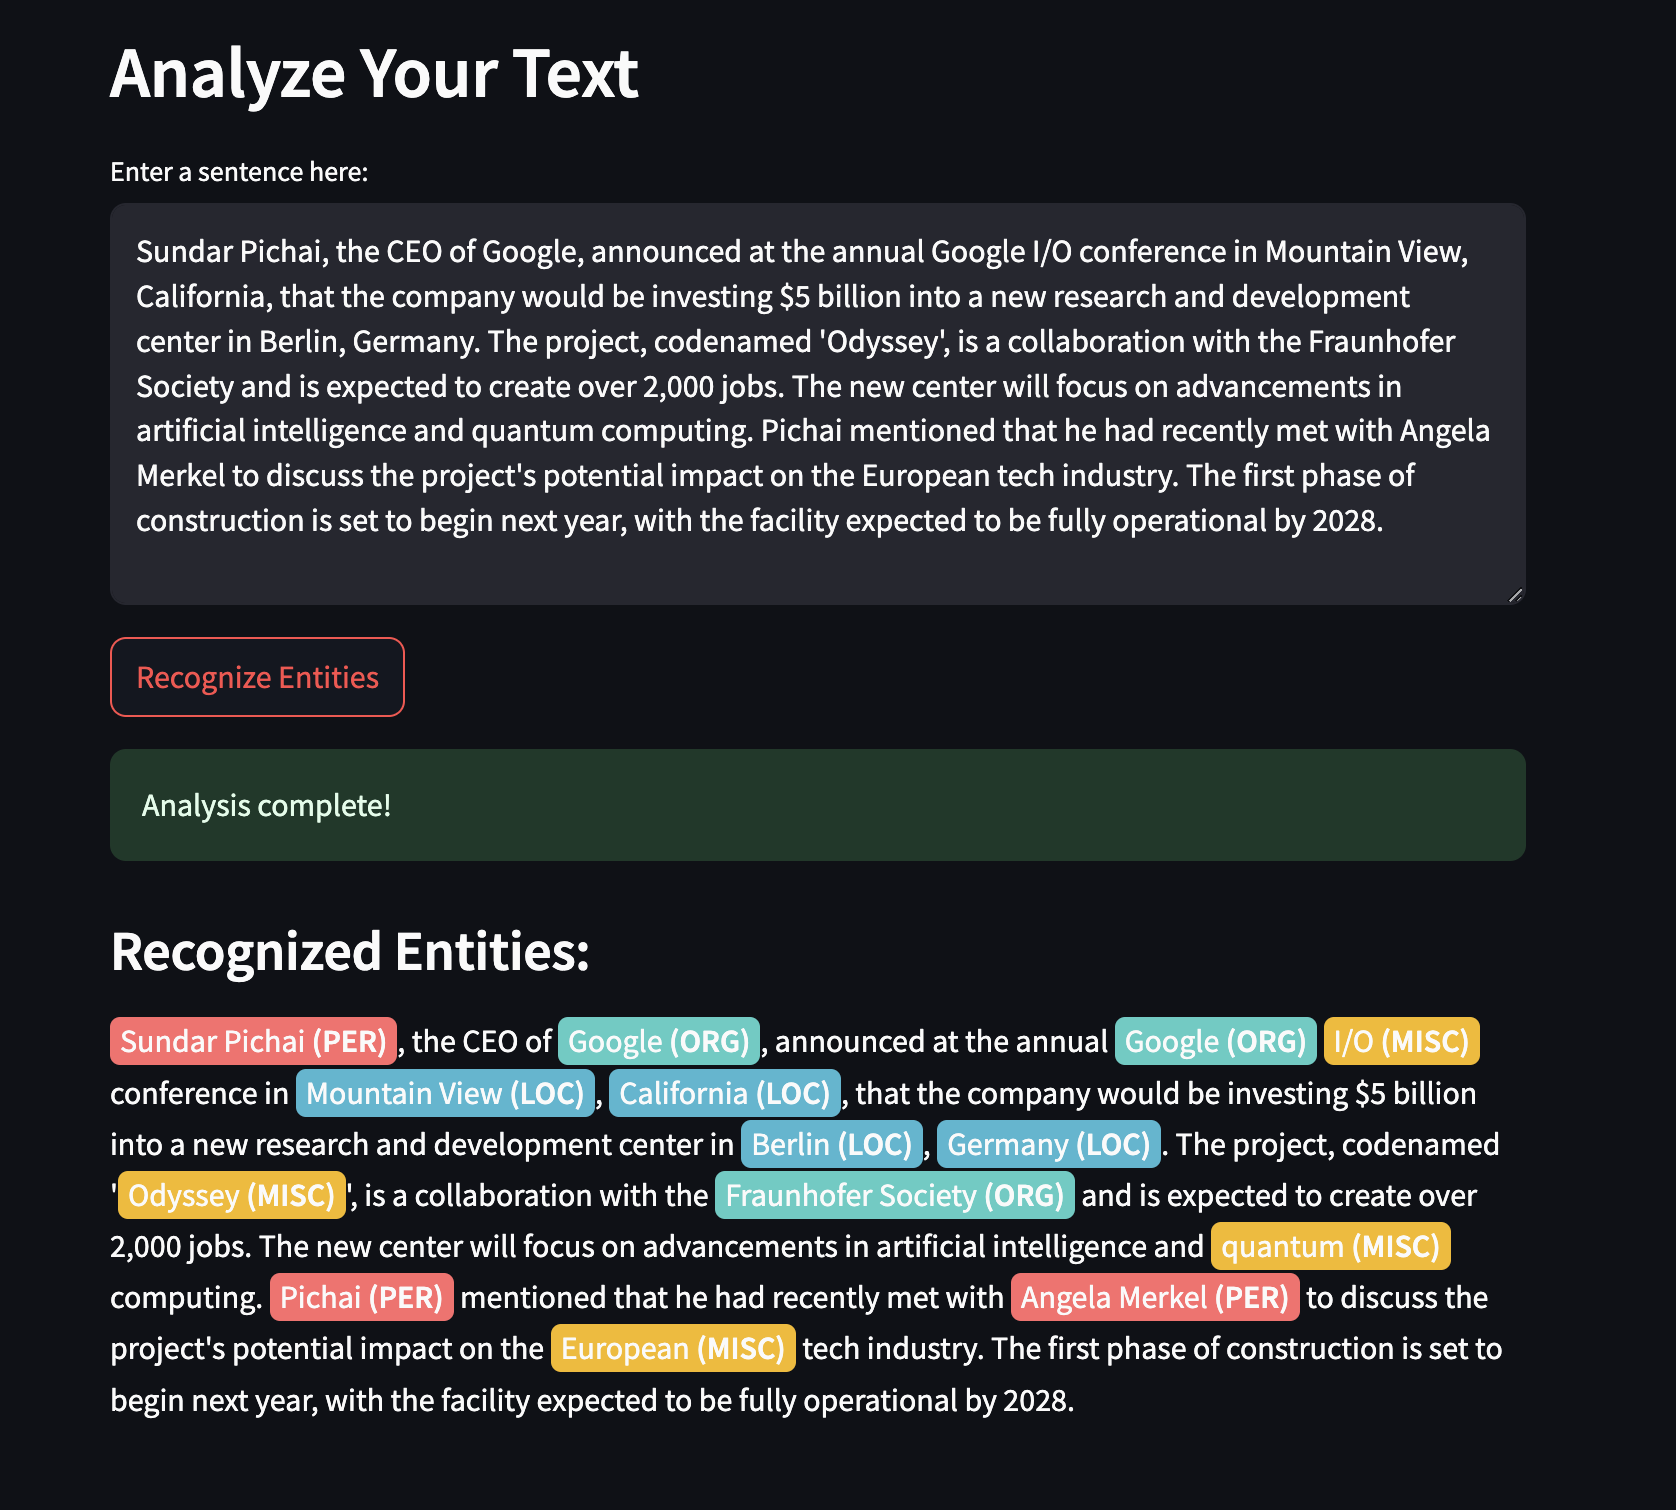
You can use this model to extract named entities from text. It is particularly effective for news articles and other formal text, similar to the CoNLL-2003 dataset.
The model can be easily loaded from the Hub using the transformers library.
from transformers import pipeline

# Load the NER pipeline
ner_pipeline = pipeline("ner", model="your-username/your-repo-name") # Replace with your repo name

# Example text
text = "Sundar Pichai, the CEO of Google, announced a new project in Berlin."

# Get predictions
entities = ner_pipeline(text)
print(entities)
# Expected Output:
# [
#   {'entity_group': 'PER', 'score': ..., 'word': 'Sundar Pichai', 'start': 0, 'end': 13},
#   {'entity_group': 'ORG', 'score': ..., 'word': 'Google', 'start': 25, 'end': 31},
#   {'entity_group': 'LOC', 'score': ..., 'word': 'Berlin', 'start': 65, 'end': 71}
# ]
The model was trained using the transformers library on a single GPU.
The model achieved the following performance on the CoNLL-2003 validation set:
| Metric | Score |
|---|---|
| F1 | 0.9382 |
| Precision | 0.9345 |
| Recall | 0.9419 |
If you use this model in your work, please consider citing the original DistilBERT paper:
@inproceedings{sanh2019distilbert,
  title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
  author={Sanh, Victor and Debut, Lysandre and Chaumond, Julien and Wolf, Thomas},
  booktitle={Proceedings of the 5th Workshop on Energy Efficient Machine Learning and Cognitive Computing},
  year={2019}
}