
Downloads · 30 days
18
0% of all-time downloads
alexandreteles/bonito-v1-awq
bonito-v1-awq is a text generation model from alexandreteles. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
You can find the original model at BatsResearch/bonito-v1
Downloads · 30 days
18
0% of all-time downloads
All-time downloads
4.6K
Public
Parameters
7.2B
8.3 GB on disk
Likes
3
Public
Click a slice to open those files.
.safetensors8.3 GB · 100%
How the weights are stored.
I327B · 96%
From the Hugging Face model README
You can find the original model at BatsResearch/bonito-v1
Bonito is an open-source model for conditional task generation: the task of converting unannotated text into task-specific training datasets for instruction tuning.
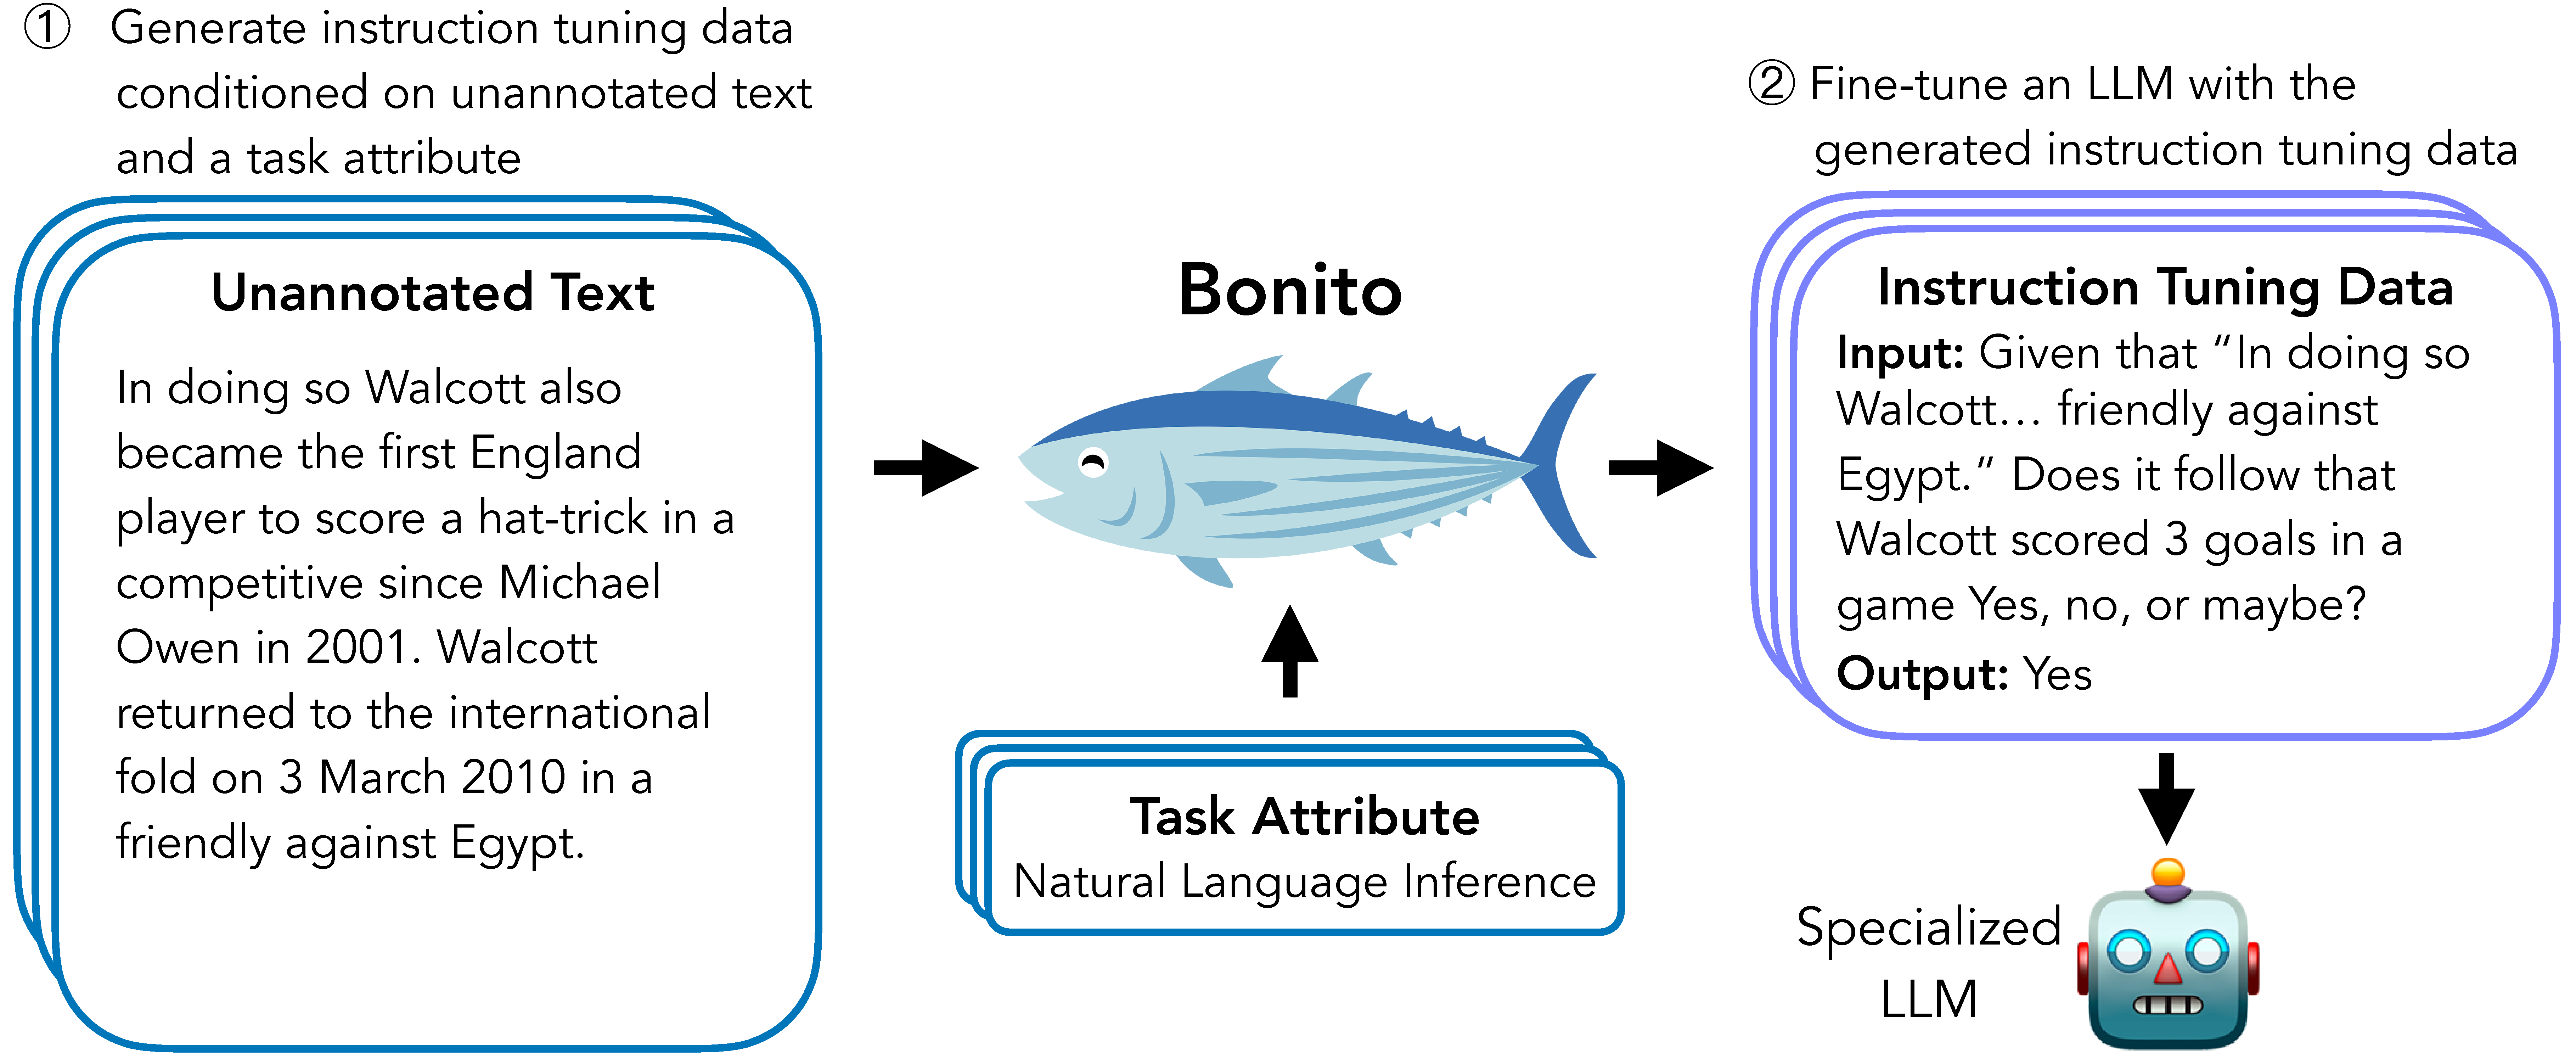
Bonito can be used to create synthetic instruction tuning datasets to adapt large language models on users' specialized, private data. In our paper, we show that Bonito can be used to adapt both pretrained and instruction tuned models to tasks without any annotations.
mistralai/Mistral-7B-v0.1To easily generate synthetic instruction tuning datasets, we recommend using the bonito package built using the transformers and the vllm libraries.
from bonito import Bonito, SamplingParams
from datasets import load_dataset

# Initialize the Bonito model
bonito = Bonito()

# load dataaset with unannotated text
unannotated_text = load_dataset(
    "BatsResearch/bonito-experiment",
    "unannotated_contract_nli"
)["train"].select(range(10))

# Generate synthetic instruction tuning dataset
sampling_params = SamplingParams(max_tokens=256, top_p=0.95, temperature=0.5, n=1)
synthetic_dataset = bonito.generate_tasks(
    unannotated_text,
    context_col="input",
    task_type="nli",
    sampling_params=sampling_params
)
Our model is trained to generate the following task types: summarization, sentiment analysis, multiple-choice question answering, extractive question answering, topic classification, natural language inference, question generation, text generation, question answering without choices, paraphrase identification, sentence completion, yes-no question answering, word sense disambiguation, paraphrase generation, textual entailment, and coreference resolution. The model might not produce accurate synthetic tasks beyond these task types.