
Downloads · 30 days
58
1% of all-time downloads
alea31415/onimai-characters
onimai-characters is a text-to-image model from alea31415. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
This model is trained on 6(+1?) characters from ONIMAI: I'm Now Your Sister! (お兄ちゃんはおしまい!)
Downloads · 30 days
58
1% of all-time downloads
All-time downloads
4.5K
Public
Repo size
32.4 GB
Likes
32
Public
Click a slice to open those files.
.ckpt19.2 GB · 59%
From the Hugging Face model README
This model is trained on 6(+1?) characters from ONIMAI: I'm Now Your Sister! (お兄ちゃんはおしまい!)
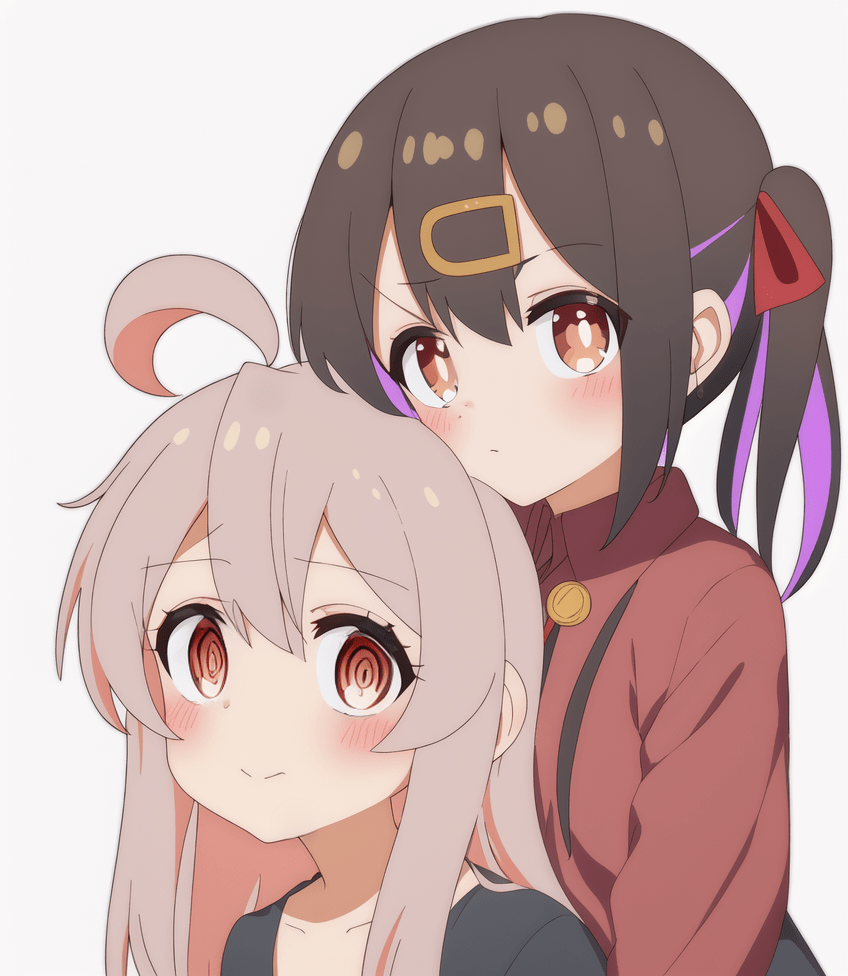
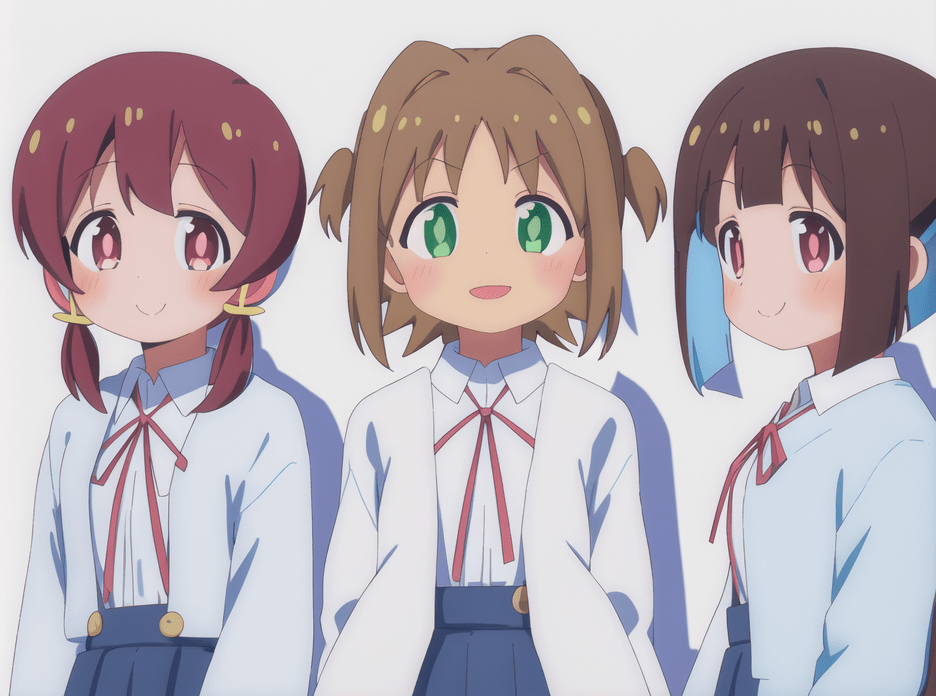
Two lora checkpoints trained with the same dataset are added to the loras subfolder. The first one seems to work already.
The characters are learned but unfortunately not the styles nor the outfits.
It is trained based on ACertainty and works fine on Orange and Anything, but not so well on models that are trained further such as MyneFactoryBase or my own models.
I still cannot figure out when Loras get transferred correctly.
The lora has dimension 32, alpha 1, and is trained with learning rate 1e-4. Here are some example generations.
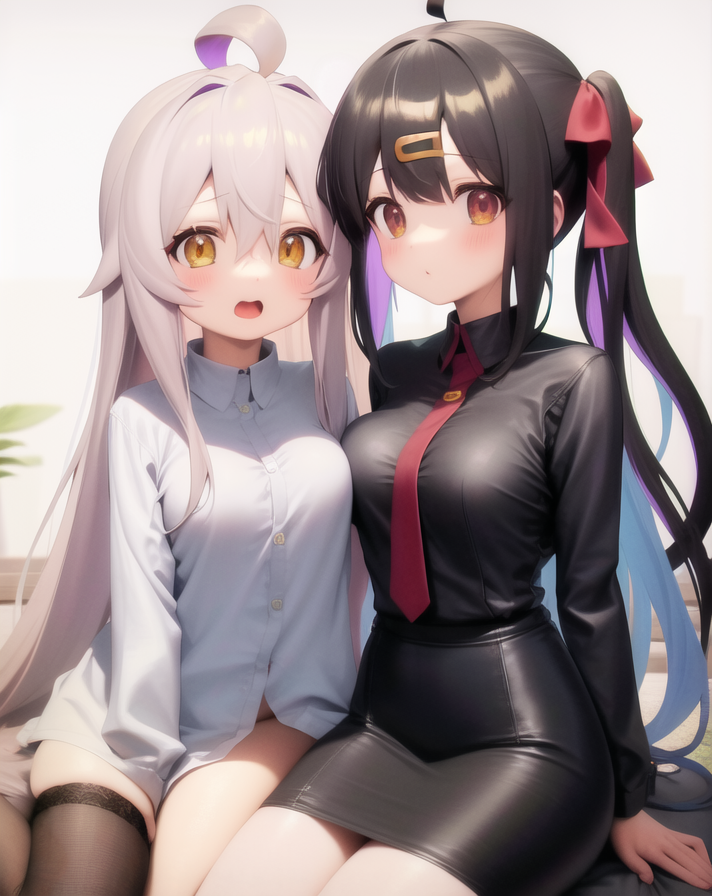
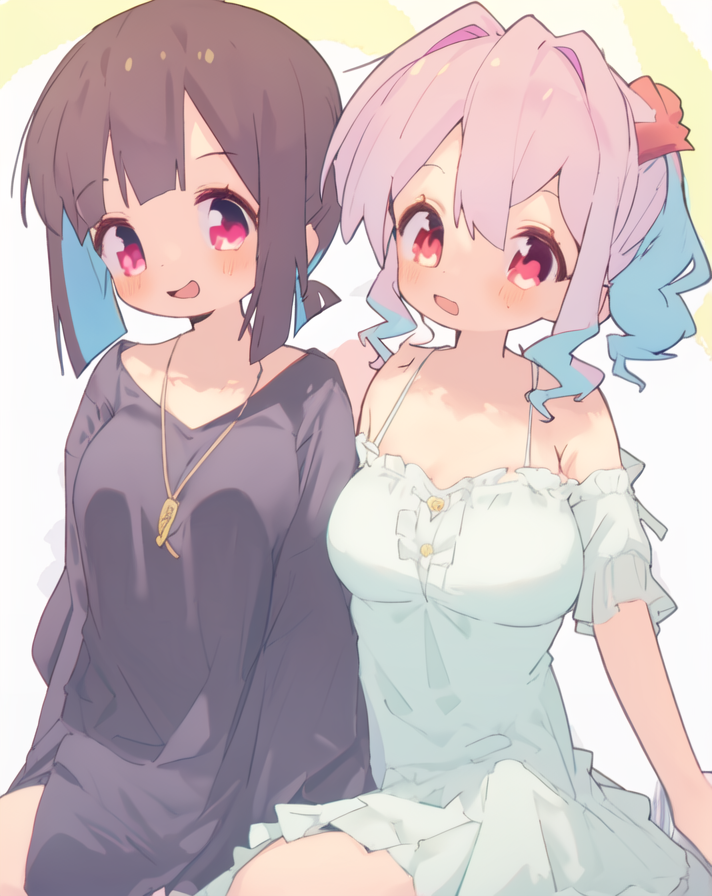
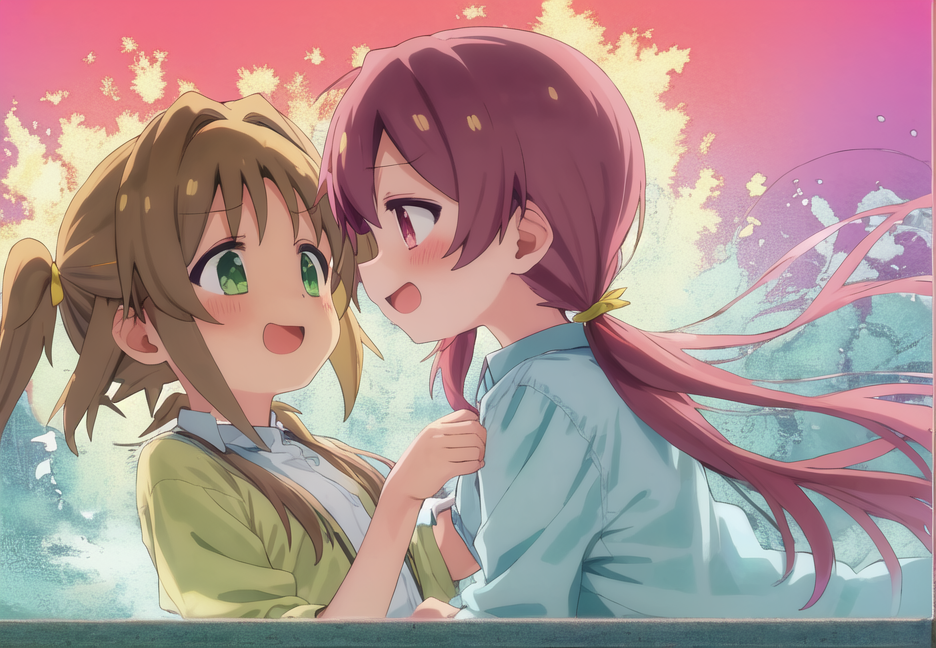
P.S. I would still suggest using the full model if you want more complex scenes, or more fidelity to the styles and outfits. You can always alter the style by merging models.
The model is shared in both diffuser and safetensors formats.
As for the trigger words, the six characters can be prompted with
OyamaMahiro, OyamaMihari, HozukiKaede, HozukiMomiji, OkaAsahi, and MurosakiMiyo.
TenkawaNayuta is tagged but she appears in fewer than 10 images so don't expect any good result.
There are also three different styles trained into the model: aniscreen, edstyle, and megazine (yes, typo).
As usual you can get multiple-character imagee but starting from 4 it is difficult.
By the way, the model is trained at clip skip 1.
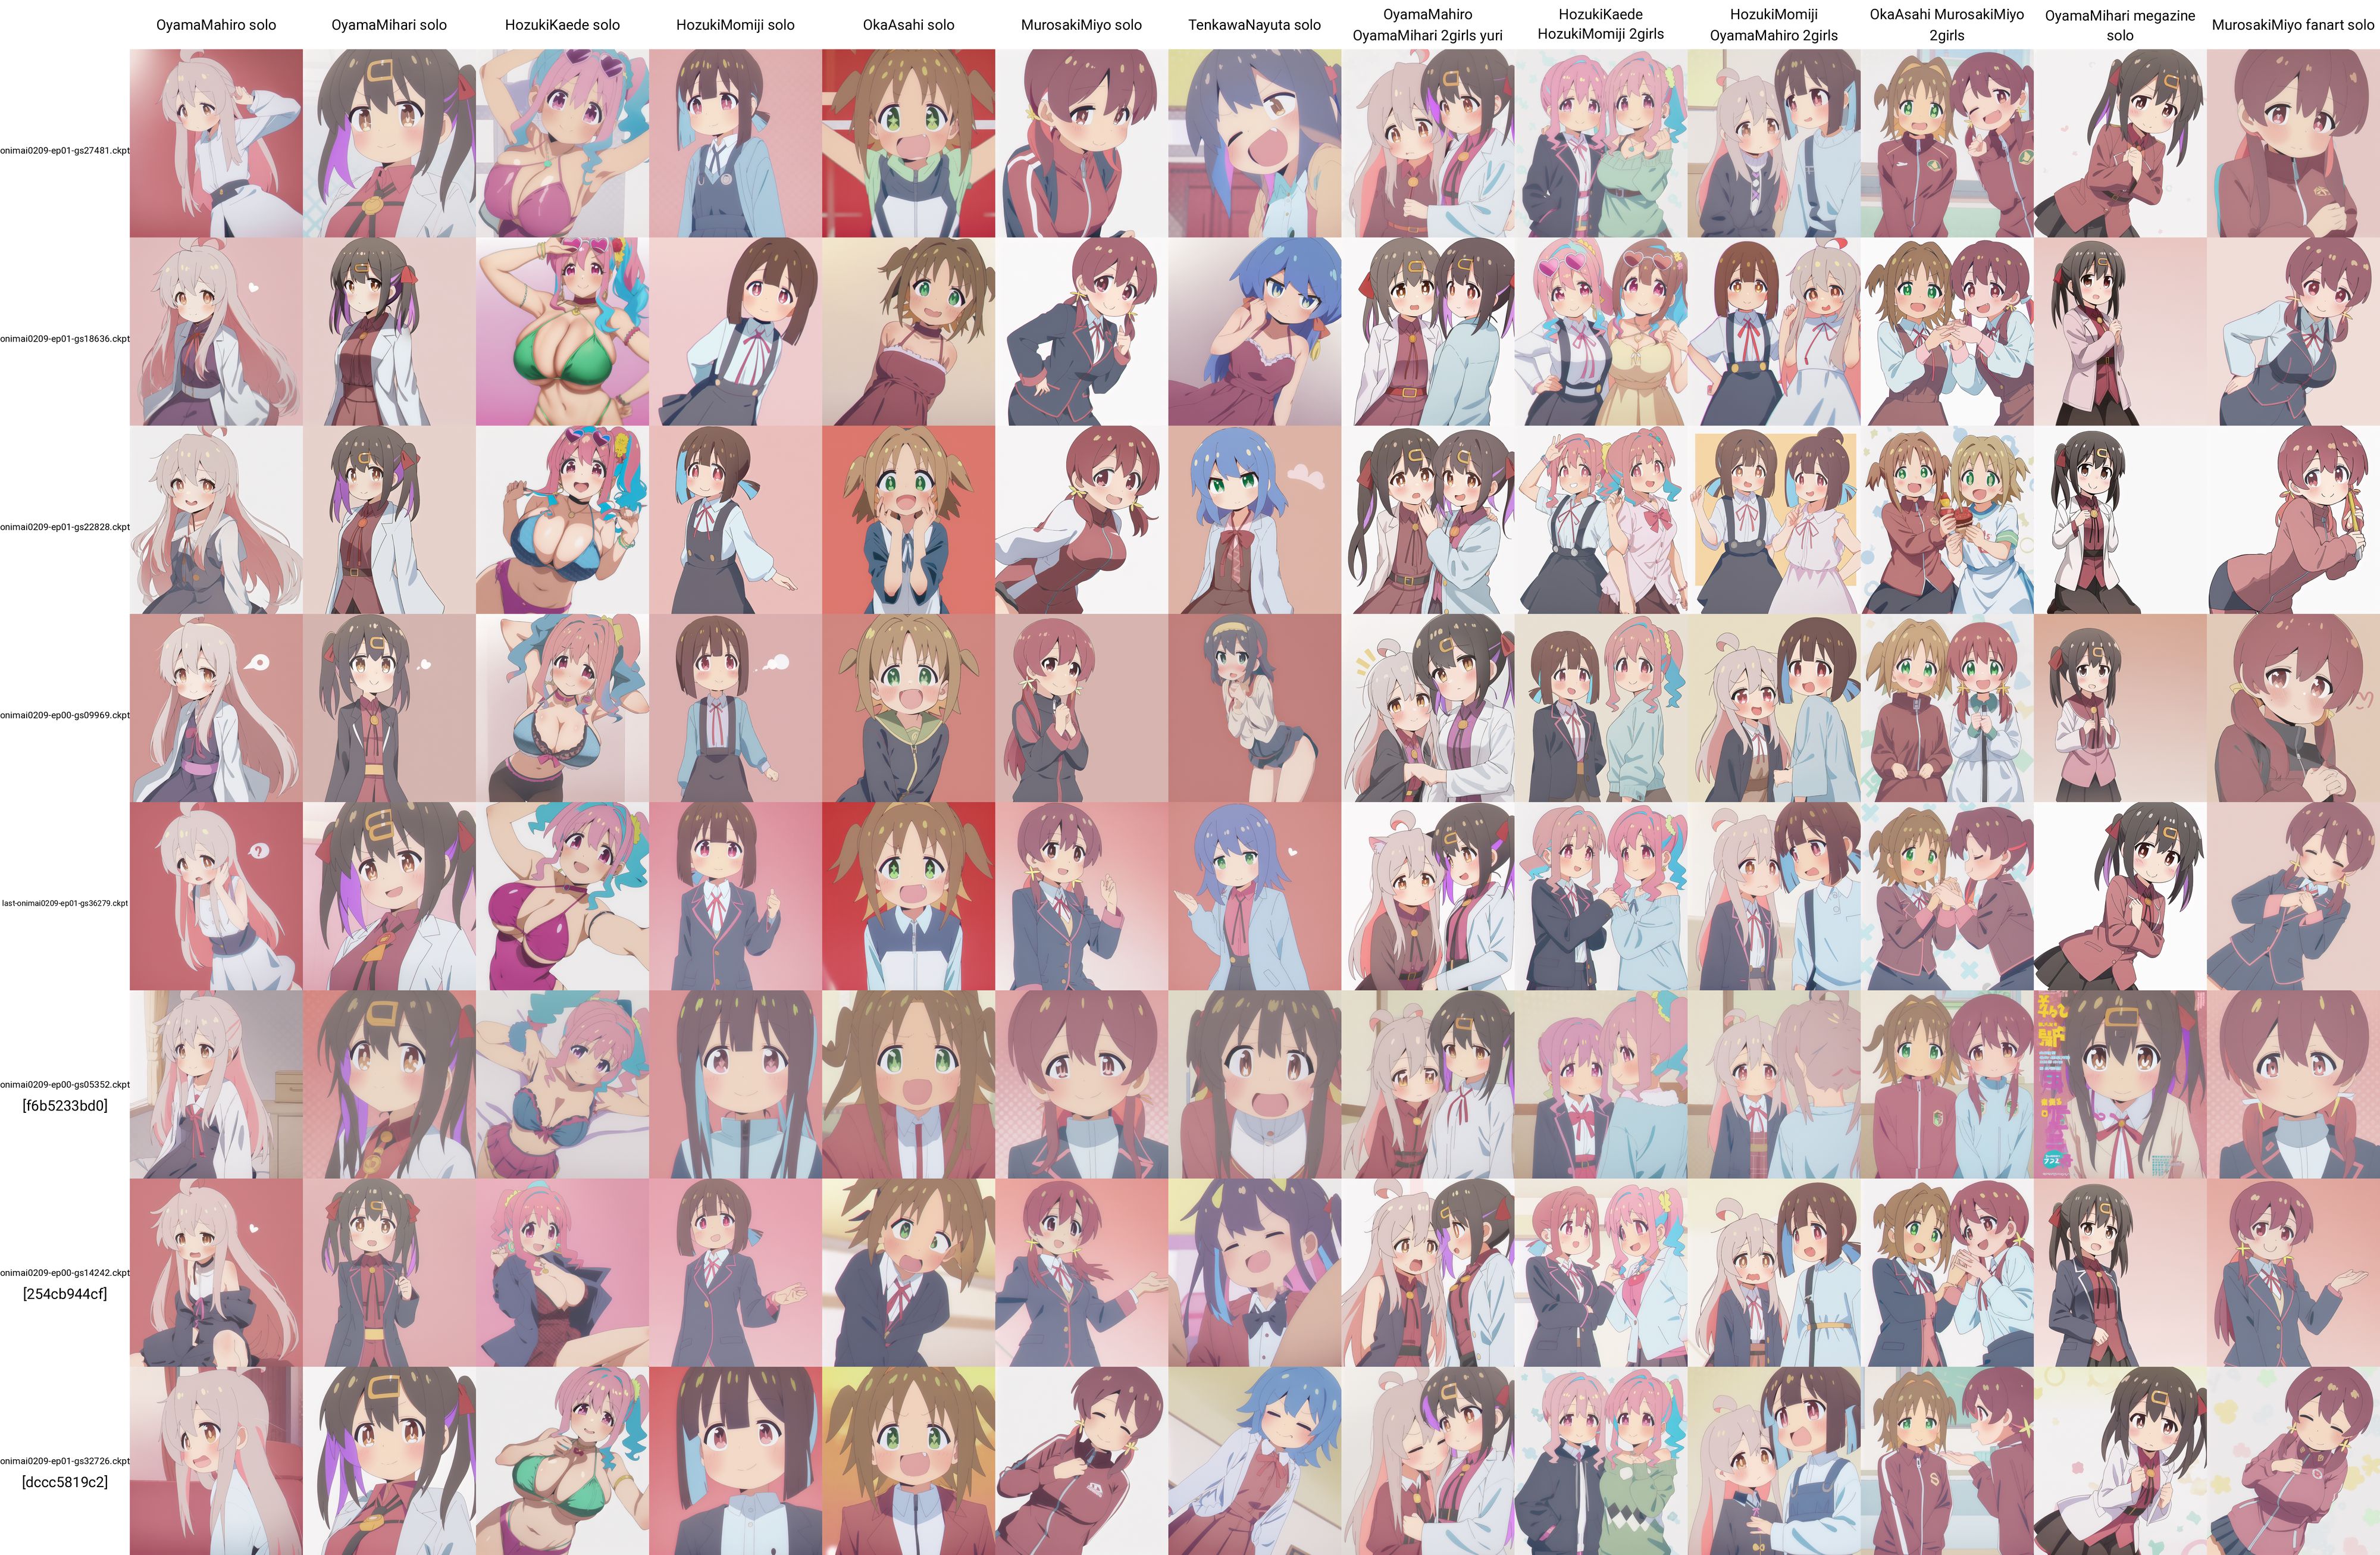
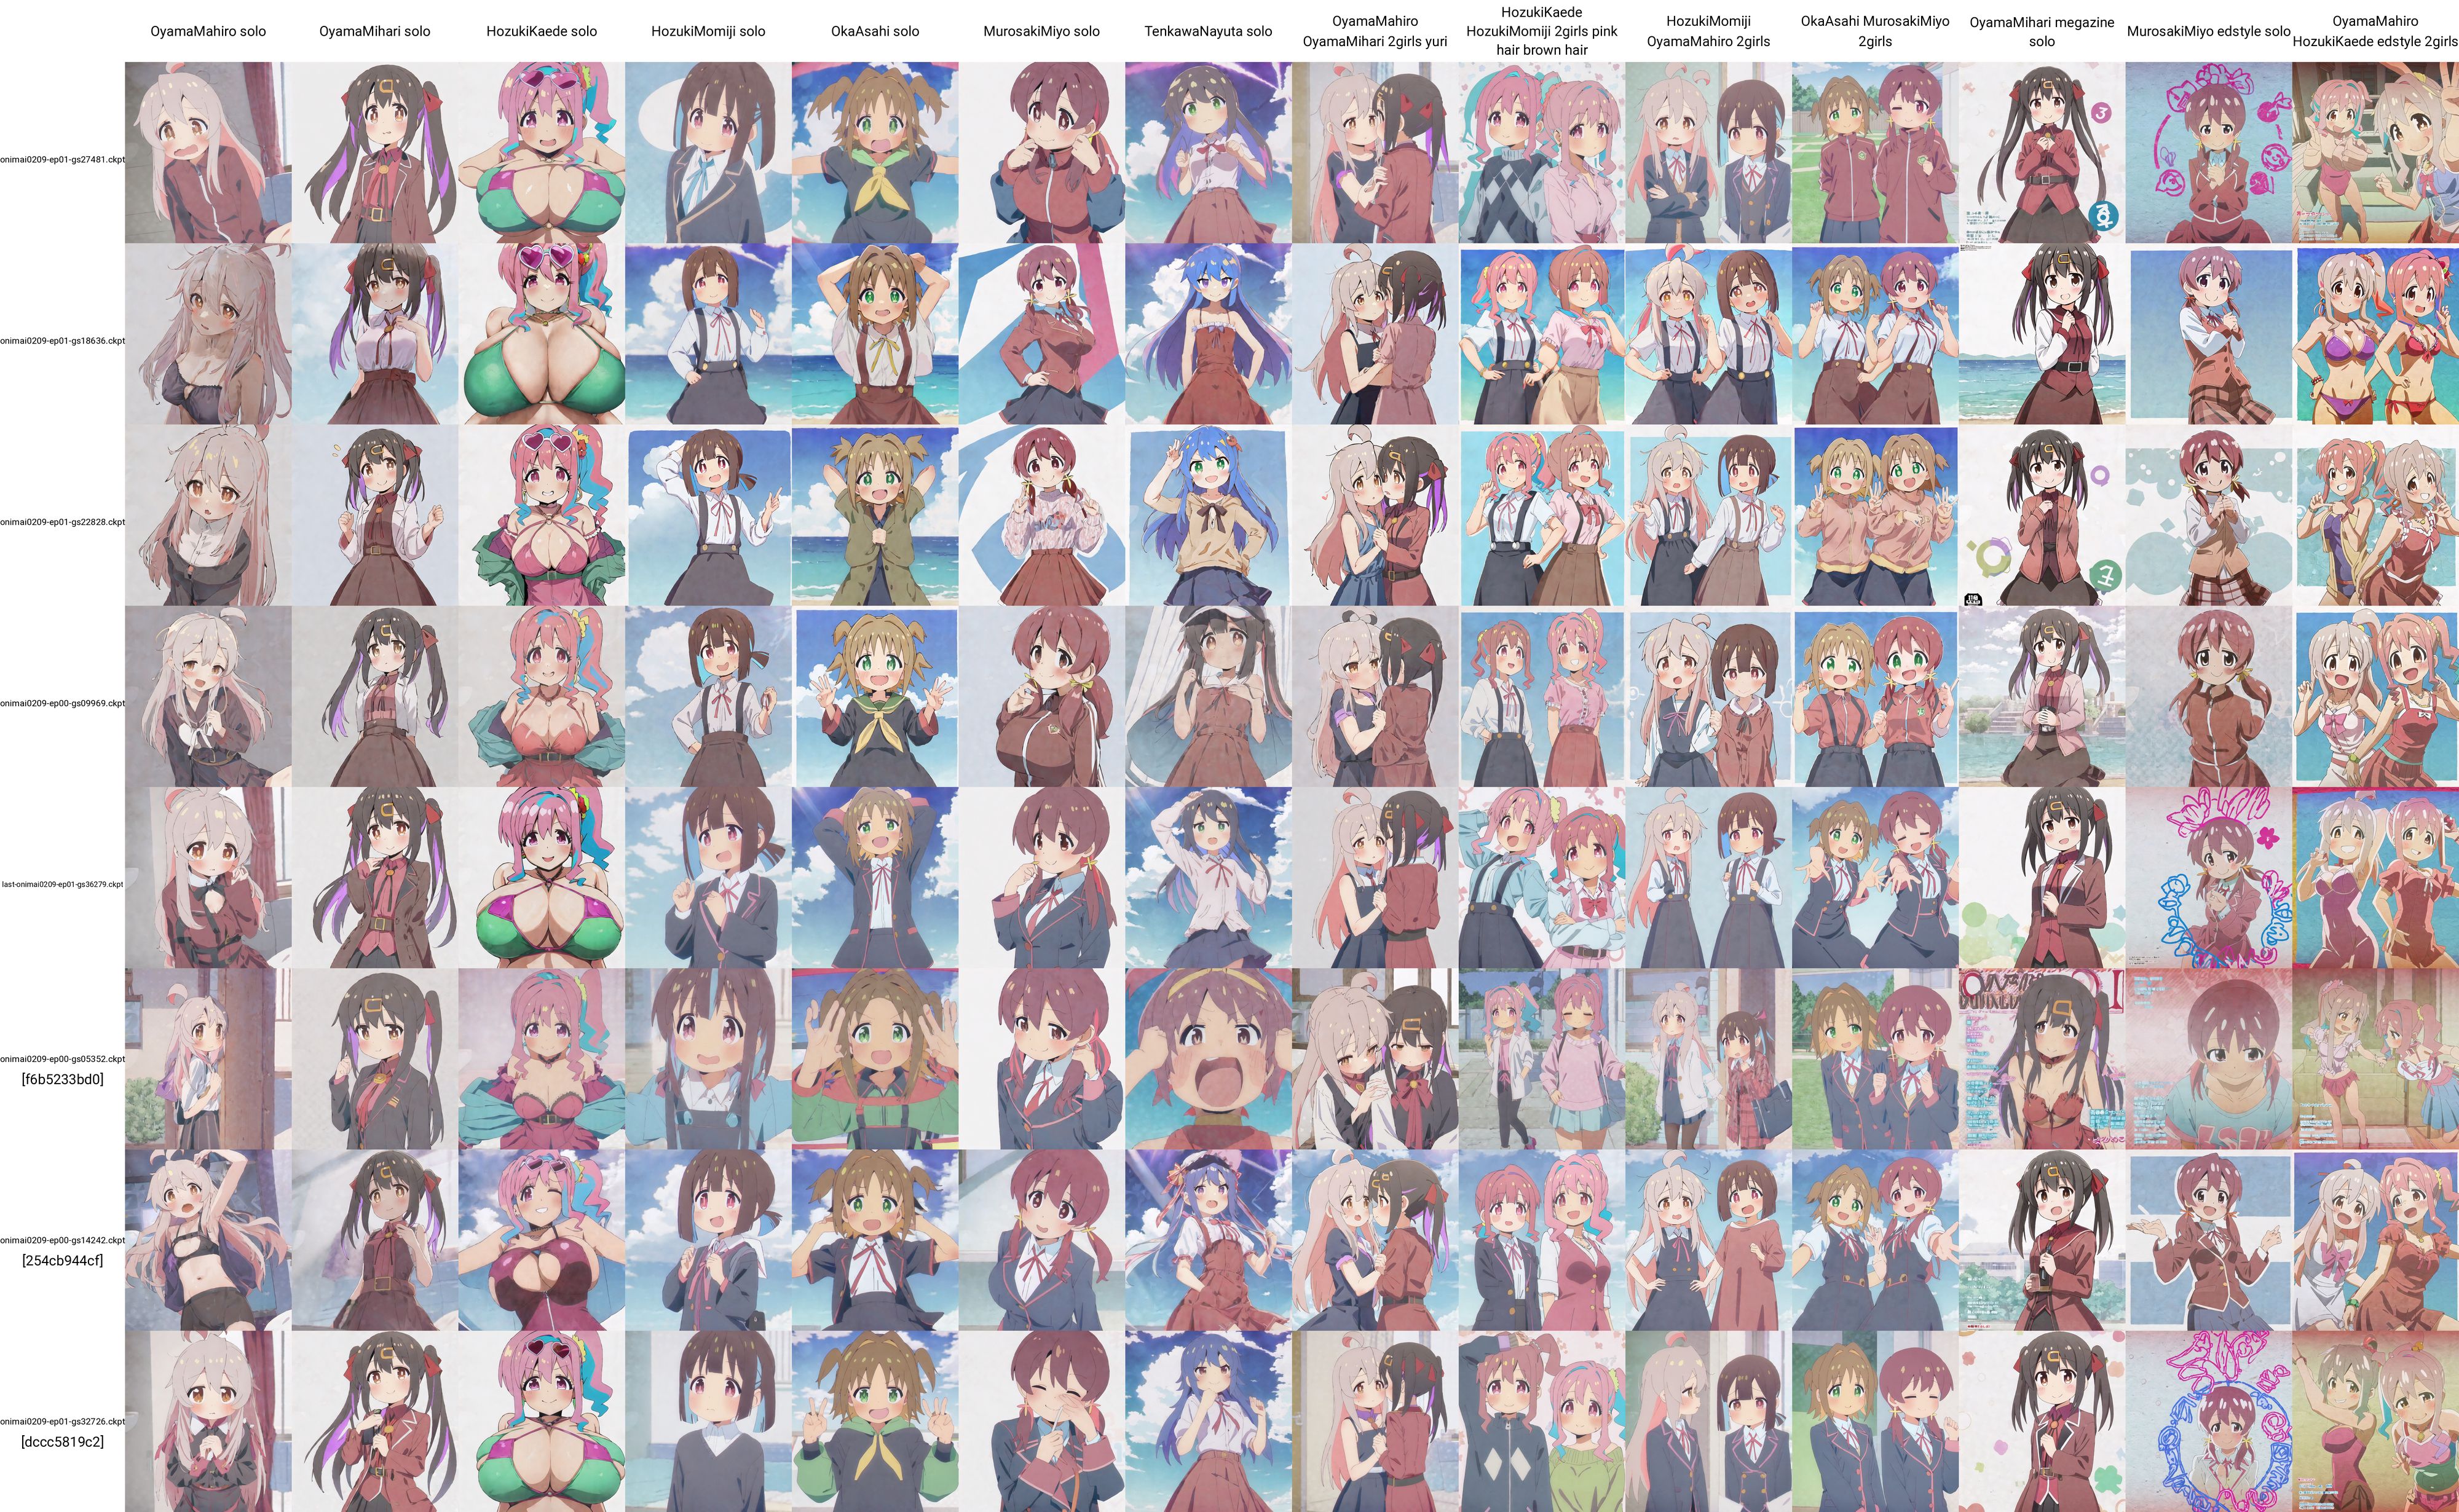
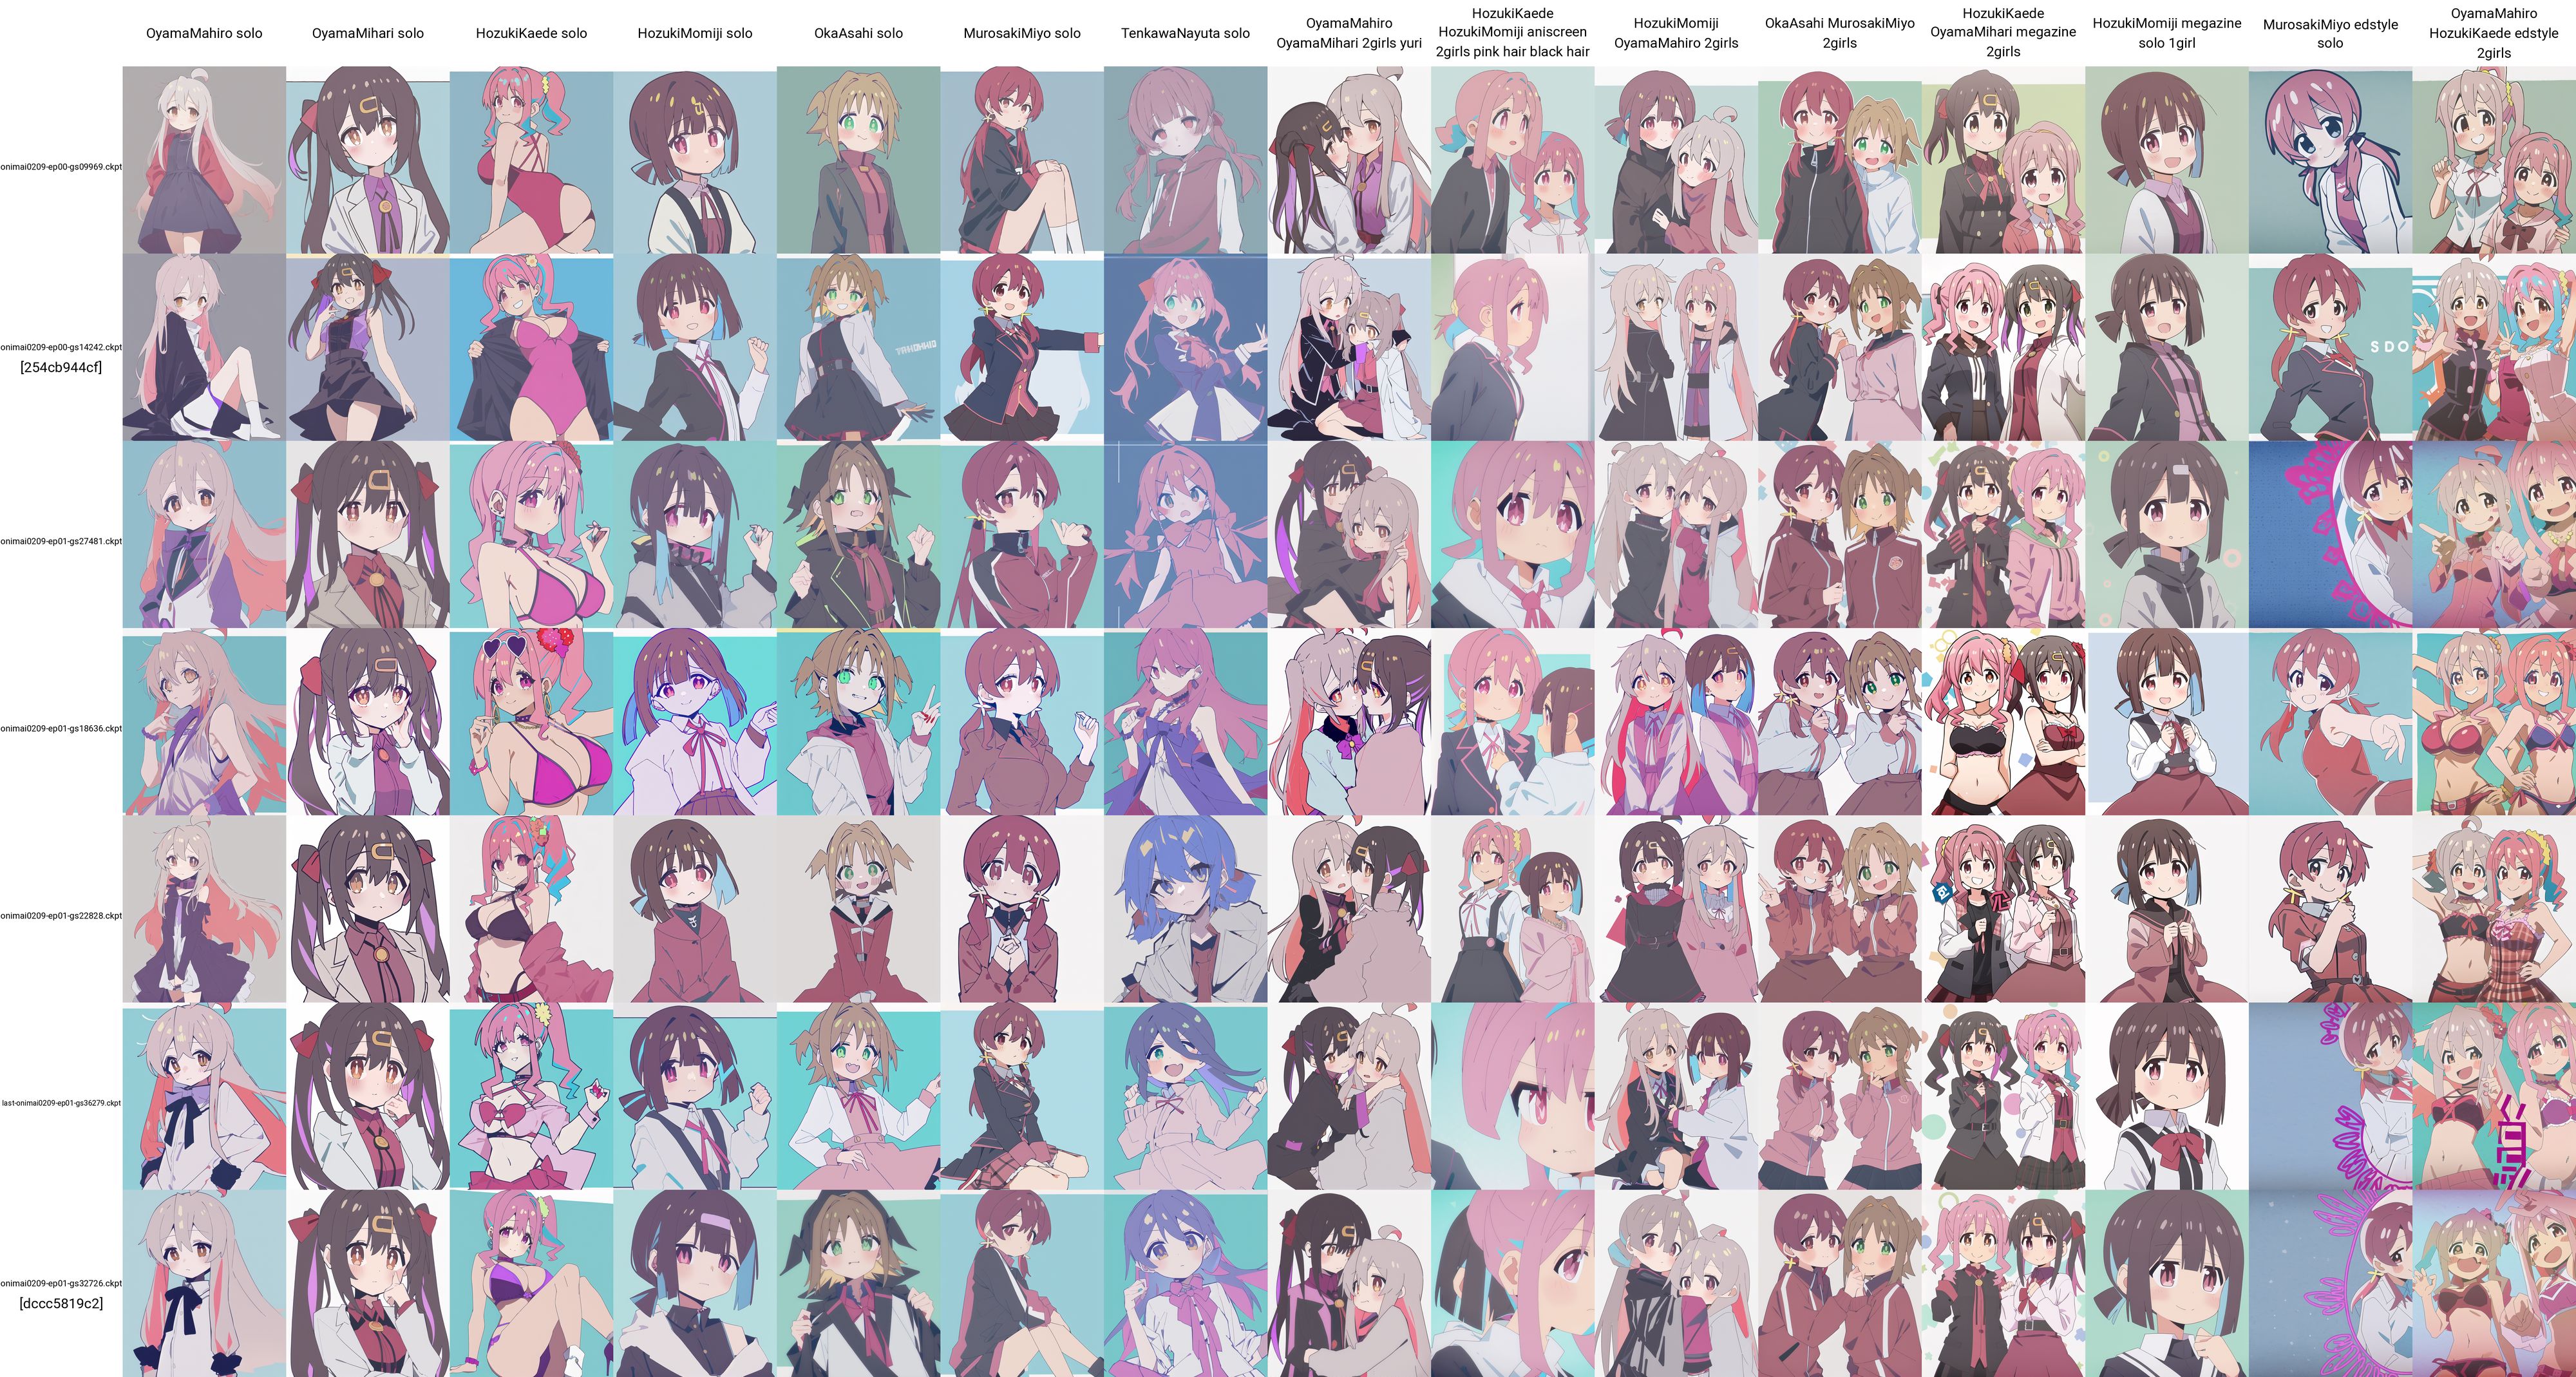
In the following images are shown the generations of different checkpoints.
The default one is that of step 22828, but all the checkpoints starting from step 9969 can be found in the checkpoints directory.
They are all sufficiently good at the six characters but later ones are better at megazine and edstyle (at the risk of overfitting, I don't really know).
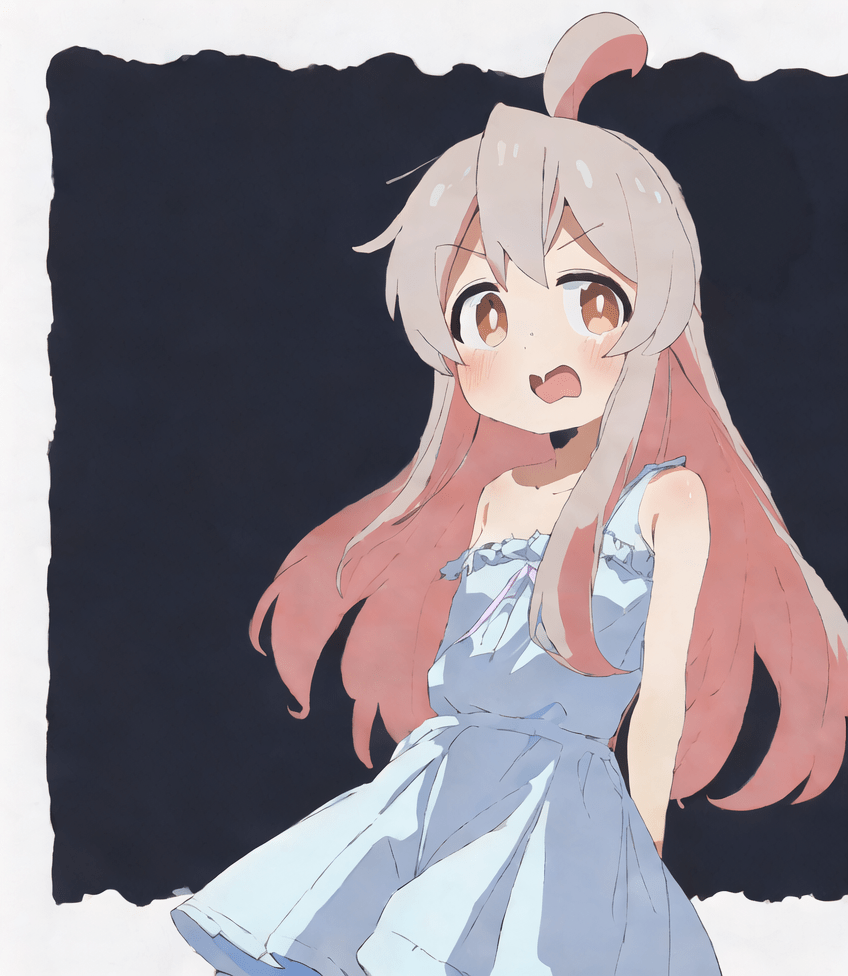
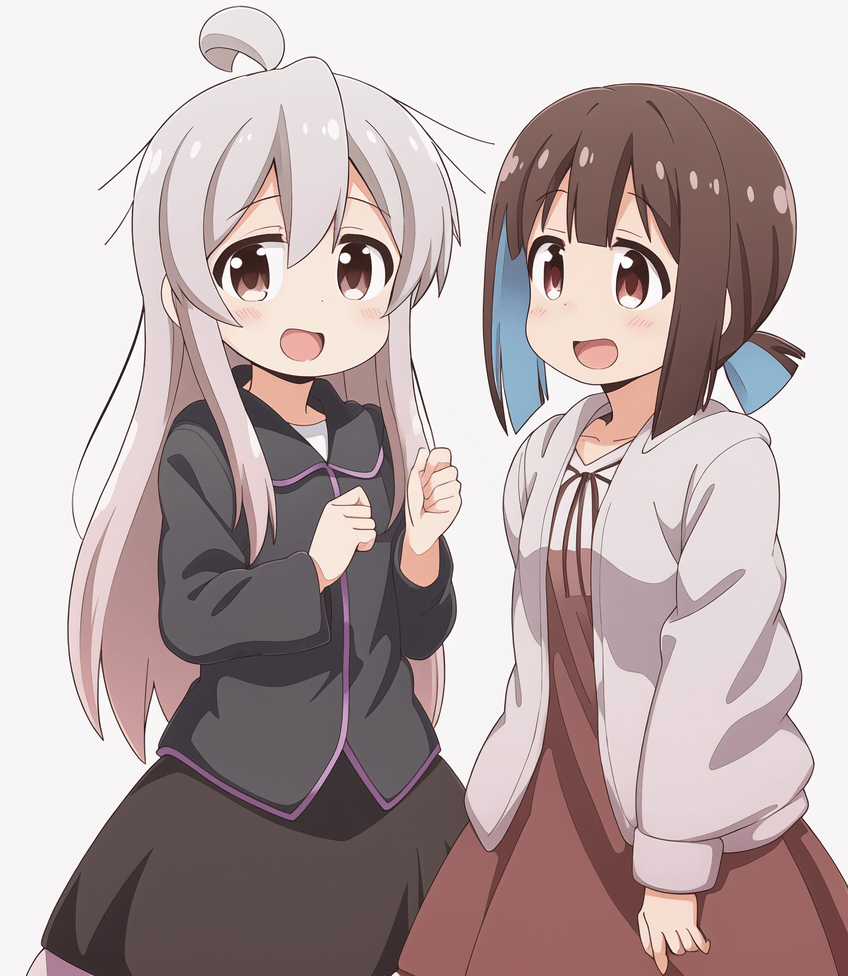
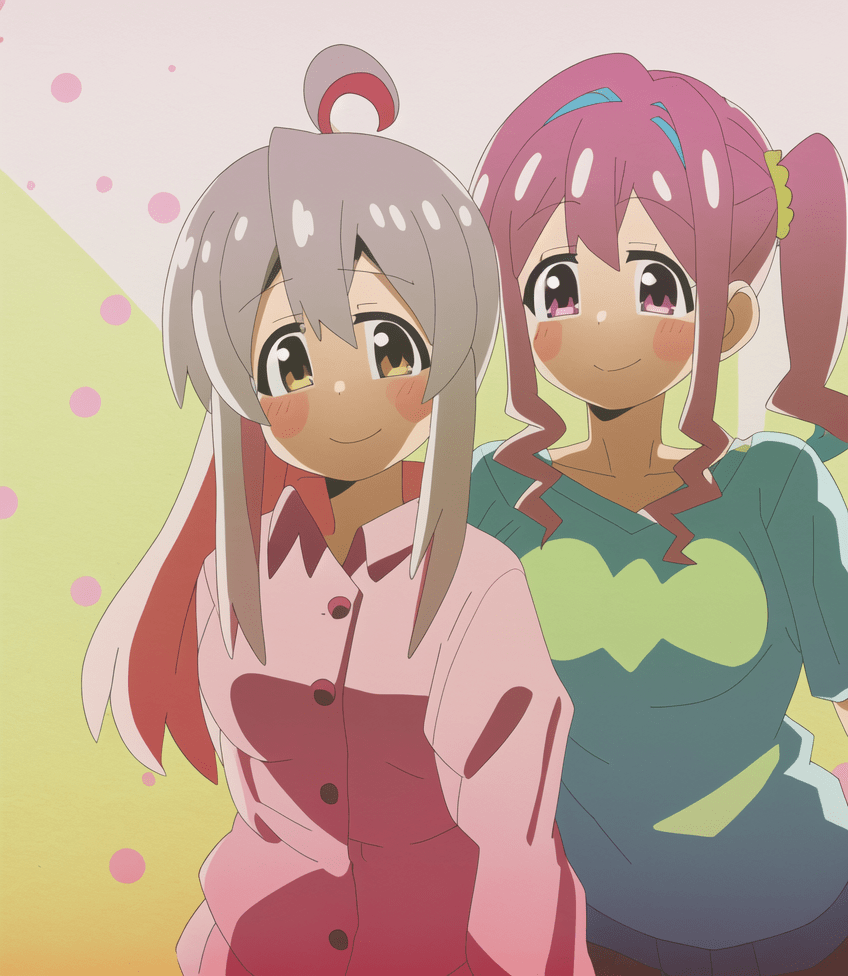
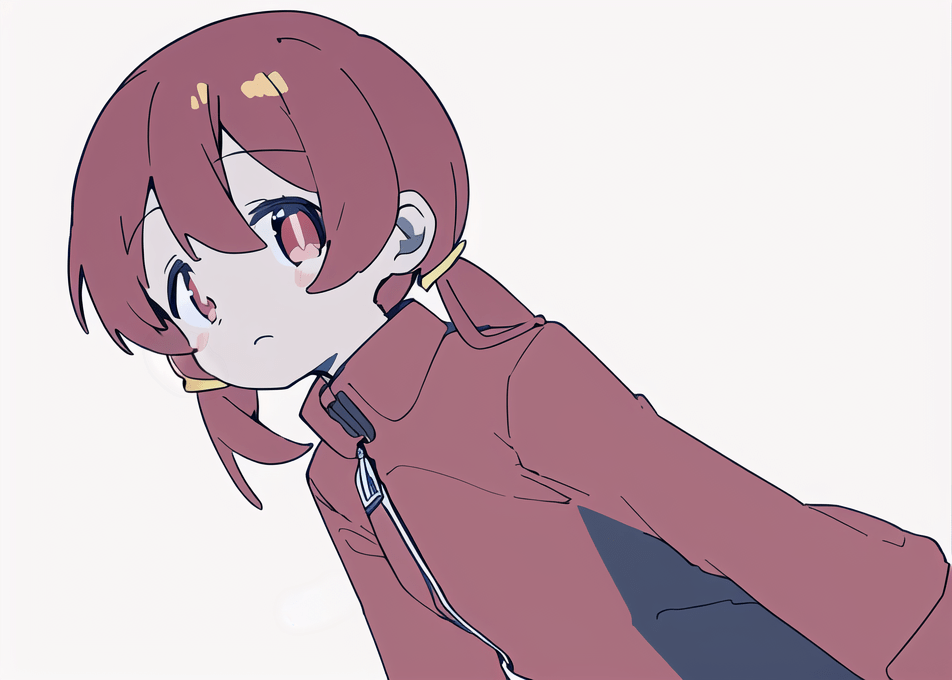
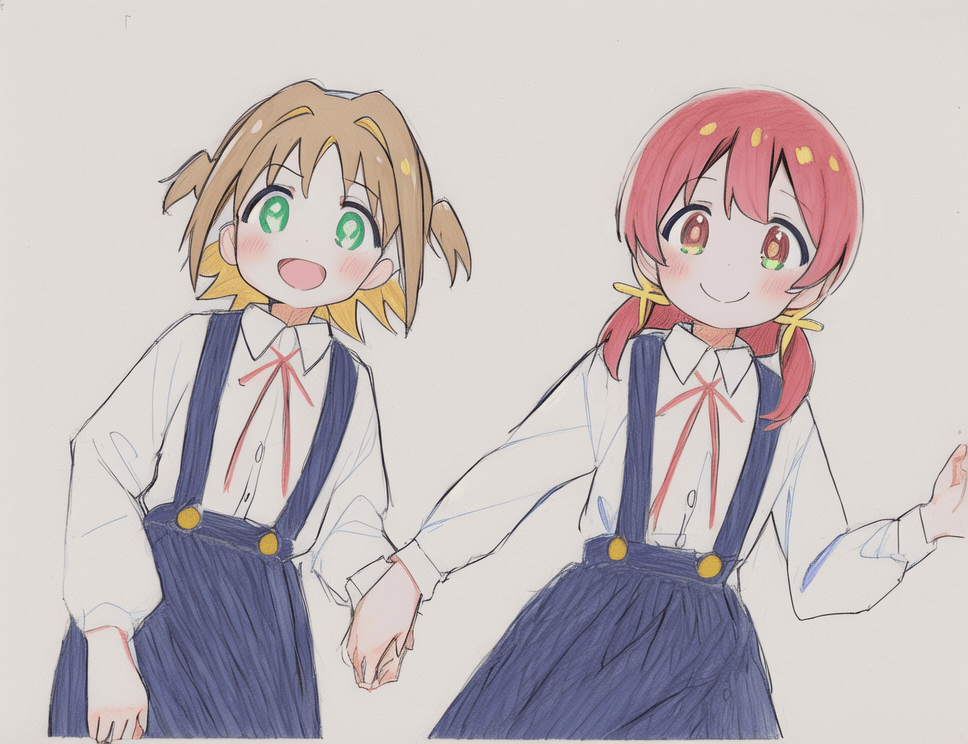
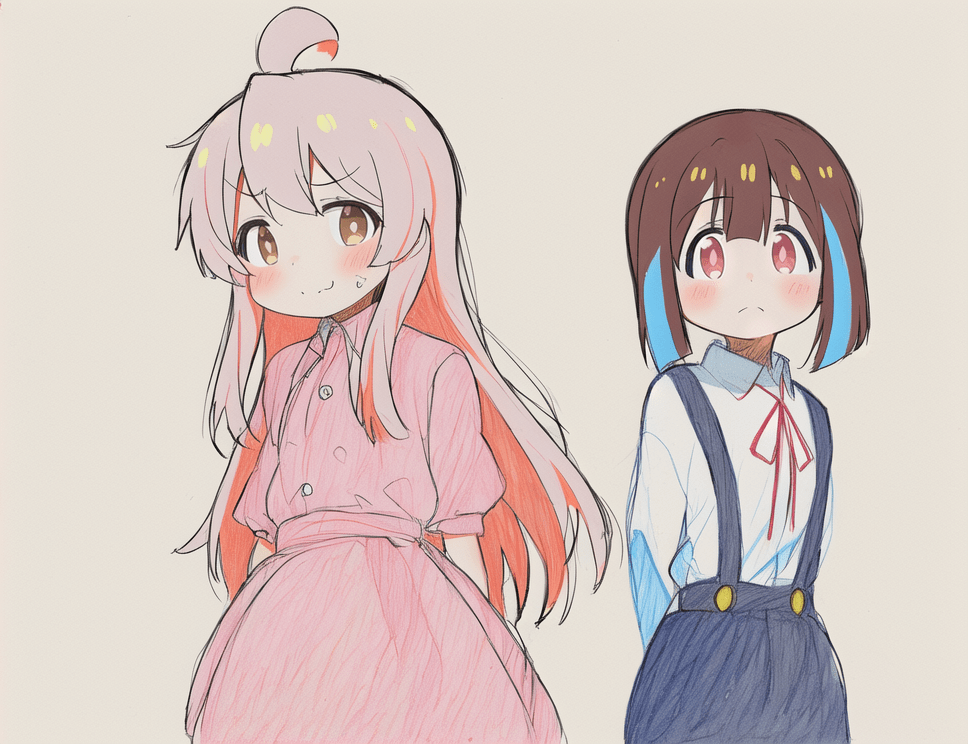
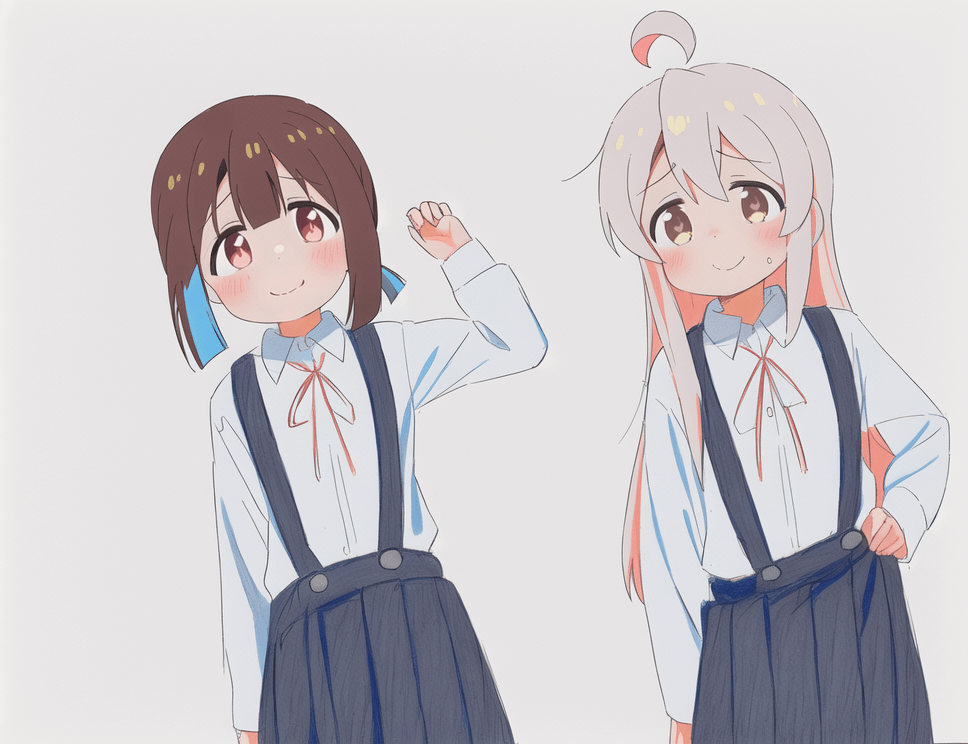
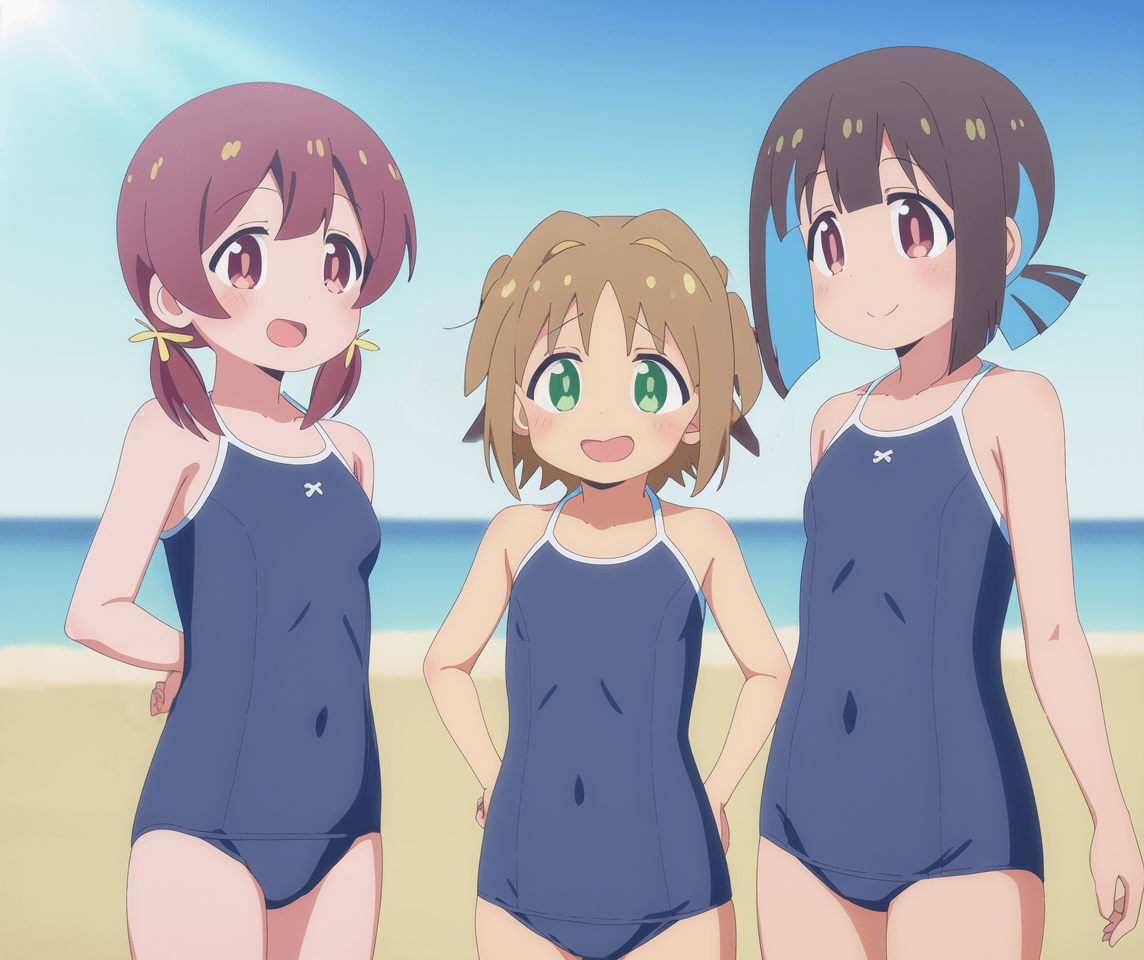
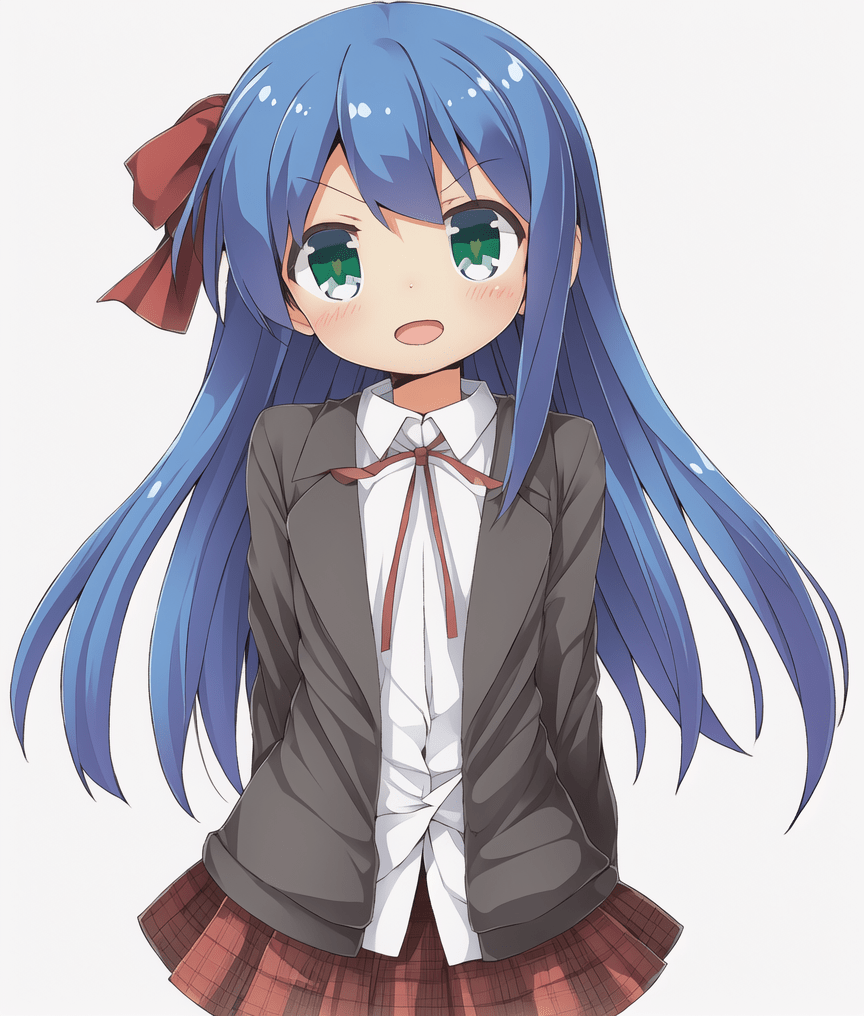
The dataset is prepared via the workflow detailed here: https://github.com/cyber-meow/anime_screenshot_pipeline
It contains 21412 images with the following composition
aniscreen)edstyle, not counted in the 1496 above)megazine, don't ask me why I choose this name, it is bad but it turns out to work)Note that the model is trained with a specific weighting scheme to balance between different concepts so that every image does not weight equally. After applying the per-image repeat we get around 145K images per epoch.
Training is done with EveryDream2 trainer with ACertainty as base model. The following configuration is used
scaler_linear to linear in config.json of the scheduler of the modelI trained for two epochs wheareas the default release model was trained for 22828 steps as mentioned above.