
Downloads · 30 days
26
1% of all-time downloads
aifeifei798/llama3-8B-DarkIdol-2.2-Uncensored-1048K
llama3-8B-DarkIdol-2.2-Uncensored-1048K is a text generation model from aifeifei798. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
- Lewdiculous's superb gguf version, thank you for your conscientious and responsible dedication. - https://huggingface.co/LWDCLS/llama3-8B-DarkIdol-2.2-Uncensored-1048K-GGUF-IQ-Imatrix-Request - mradermacher's superb…
Downloads · 30 days
26
1% of all-time downloads
All-time downloads
4.2K
Public
Parameters
8B
16.1 GB on disk
Likes
16
Public
Click a slice to open those files.
.safetensors16.1 GB · 100%
From the Hugging Face model README
The difference with normal quantizations is that I quantize the output and embed tensors to f16. and the other tensors to 15_k,q6_k or q8_0. This creates models that are little or not degraded at all and have a smaller size. They run at about 3-6 t/sec on CPU only using llama.cpp And obviously faster on computers with potent GPUs
Due to the optimization of the preferred model, its performance is excellent across the range of 2000-1048K. Personal usage scenarios, such as 8186, 32K, etc., are insufficient. My primary role involves managing virtual idol Twitter accounts and assisting with singing, etc. A good conversation can be very lengthy, and sometimes even 32K is not enough. Imagine having a heated chat with your virtual girlfriend, only for it to abruptly cut off—that feeling is too painful.
For investing in a girlfriend, would a 4090 or higher be more of a question?
The module combination has been readjusted to better fulfill various roles and has been adapted for mobile phones.

    stop = [
      "## Instruction:",
      "### Instruction:",
      "<|end_of_text|>",
      "  //:",
      "</s>",
      "<3```",
      "### Note:",
      "### Input:",
      "### Response:",
      "### Emoticons:"
    ],

To the authors for their hard work, which has given me more options to easily create what I want. Thank you for your efforts.
base_model:
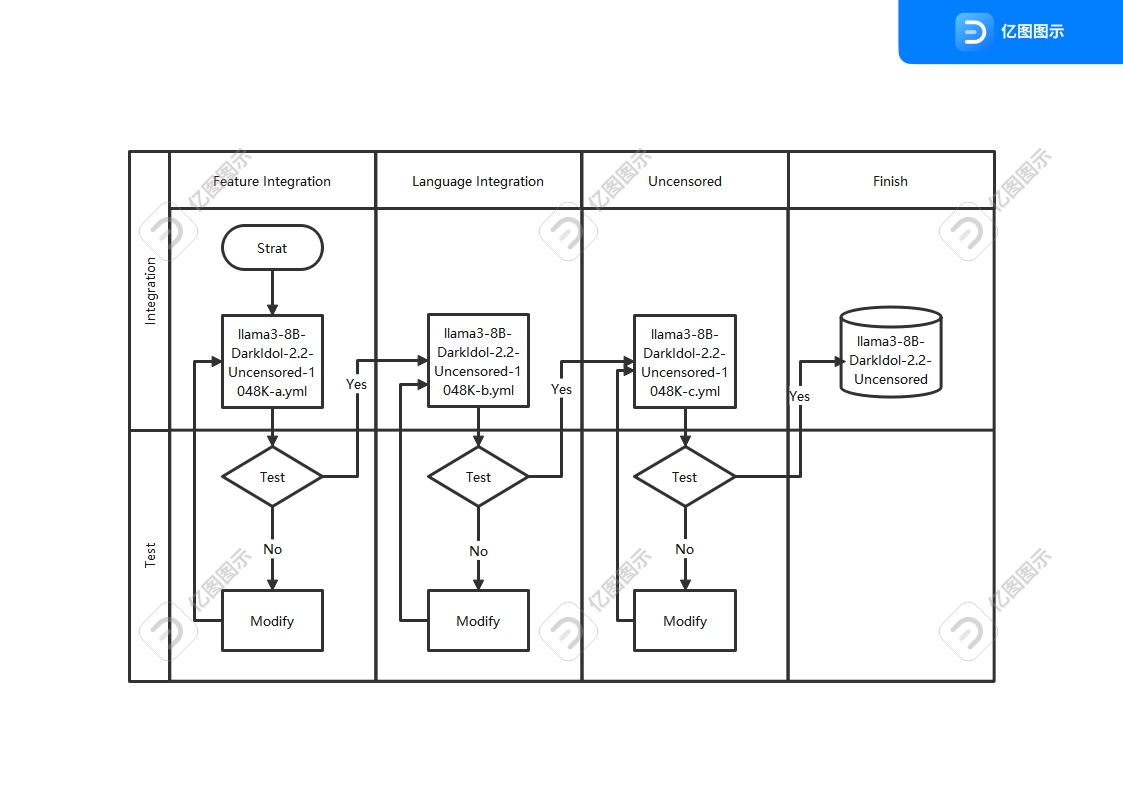
This is a merge of pre-trained language models created using mergekit.
This model was merged using the Model Stock merge method using winglian/llama-3-8b-1m-PoSE as a base.
The following models were included in the merge:
The following YAML configuration was used to produce this model:
models:
#base
  - model: Sao10K/L3-8B-Stheno-v3.3-32K
  - model: Hastagaras/Jamet-8B-L3-MK.V-Blackroot
  - model: Nitral-AI/Hathor_Fractionate-L3-8B-v.05
  - model: turboderp/llama3-turbcat-instruct-8b
  - model: vicgalle/Roleplay-Llama-3-8B
  - model: winglian/llama-3-8b-1m-PoSE
merge_method: model_stock
base_model: winglian/llama-3-8b-1m-PoSE
dtype: bfloat16
base_model:
This is a merge of pre-trained language models created using mergekit.
This model was merged using the Model Stock merge method using ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a as a base.
The following models were included in the merge:
The following YAML configuration was used to produce this model:
models:
#writer
#  - model: openerotica/Llama-3-lima-nsfw-16k-test 不兼容
  - model: maldv/llama-3-fantasy-writer-8b
#lang
  - model: hfl/llama-3-chinese-8b-instruct-v3
  - model: elyza/Llama-3-ELYZA-JP-8B
  - model: MLP-KTLim/llama-3-Korean-Bllossom-8B
  - model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a
merge_method: model_stock
base_model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-a
dtype: bfloat16
base_model:
This is a merge of pre-trained language models created using mergekit.
This model was merged using the Model Stock merge method using ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b as a base.
The following models were included in the merge:
The following YAML configuration was used to produce this model:
models:
#uncensored
  - model: TheBossLevel123/Llama3-Toxic-8B-Float16
  - model: aifeifei798/llama3-8B-DarkIdol-2.1-Uncensored-1048K
  - model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b
merge_method: model_stock
base_model: ./llama3-8B-DarkIdol-2.2-Uncensored-1048K-b
dtype: bfloat16