
Downloads · 30 days
173
6% of all-time downloads
ai-forever/mGPT-armenian
mGPT-armenian is a text generation model from ai-forever. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
We introduce a monolingual GPT-3-based model for Armenian language
Downloads · 30 days
173
6% of all-time downloads
All-time downloads
2.8K
Public
Repo size
6.9 GB
Likes
8
Public
Click a slice to open those files.
.bin3.4 GB · 100%
From the Hugging Face model README
We introduce a monolingual GPT-3-based model for Armenian language
The model is based on mGPT, a family of autoregressive GPT-like models with 1.3 billion parameters trained on 60 languages from 25 language families using Wikipedia and Colossal Clean Crawled Corpus.
We reproduce the GPT-3 architecture using GPT-2 sources and the sparse attention mechanism, Deepspeed and Megatron frameworks allows us to effectively parallelize the training and inference steps. The resulting models show performance on par with the recently released XGLM models at the same time covering more languages and enhancing NLP possibilities for low resource languages.
The source code for the mGPT XL model is available on Github
mGPT: Few-Shot Learners Go Multilingual
@misc{https://doi.org/10.48550/arxiv.2204.07580,
 doi = {10.48550/ARXIV.2204.07580},
 url = {https://arxiv.org/abs/2204.07580},
 author = {Shliazhko, Oleh and Fenogenova, Alena and Tikhonova, Maria and Mikhailov, Vladislav and Kozlova, Anastasia and Shavrina, Tatiana},
 keywords = {Computation and Language (cs.CL), Artificial Intelligence (cs.AI), FOS: Computer and information sciences, FOS: Computer and information sciences, I.2; I.2.7, 68-06, 68-04, 68T50, 68T01},
 title = {mGPT: Few-Shot Learners Go Multilingual},
 publisher = {arXiv},
 year = {2022},
 copyright = {Creative Commons Attribution 4.0 International}
}
The model was fine-tuned on 170GB of Armenian texts, including MC4, Archive.org fiction, EANC public data, OpenSubtitles, OSCAR corpus and blog texts.
Val perplexity is 2.046.
The mGPT model was pre-trained for 12 days x 256 GPU (Tesla NVidia V100), 4 epochs, then 9 days x 64 GPU, 1 epoch
The Armenian finetune was around 7 days with 4 Tesla NVidia V100 and has made 160k steps.
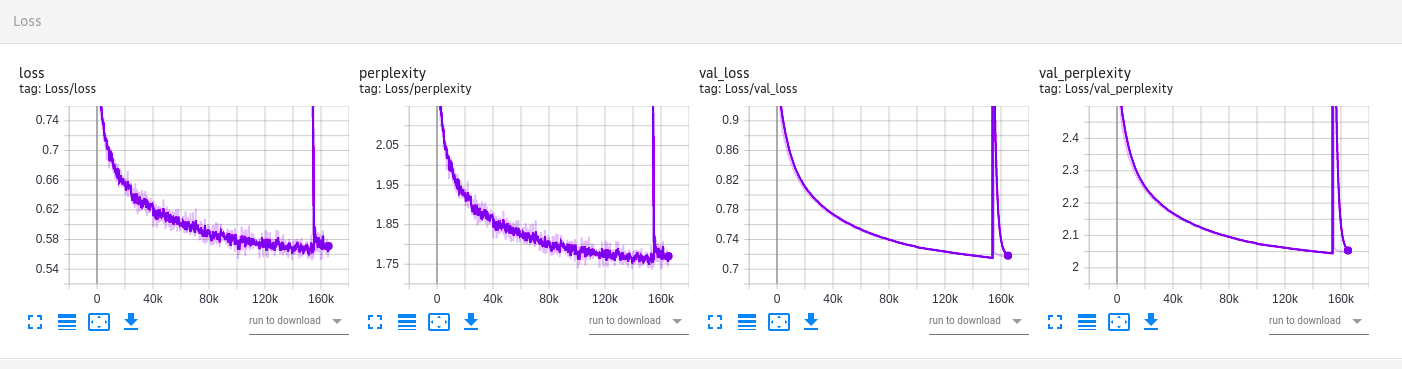 What happens on this image? The model is originally trained with sparse attention masks, then fine-tuned with no sparsity on the last steps (perplexity and loss peak). Getting rid of the sparsity in the end of the training helps to integrate the model into the GPT2 HF class.