
Downloads · 30 days
62
10% of all-time downloads
ai-babai/giga-embeddings-0826-480m-mlx-q8
giga-embeddings-0826-480m-mlx-q8 is a sentence similarity model from ai-babai. Use it when you need a score for how close two texts are. It is set up for giga-embeddings-mlx. The card lists the license as mit.
Русская карточка · All MLX models · GitHub · PyPI · Original paper
Downloads · 30 days
62
10% of all-time downloads
All-time downloads
597
Public
Parameters
484M
525 MB on disk
Likes
2
Public
Click a slice to open those files.
.safetensors514 MB · 98%
How the weights are stored.
U32484M · 100%
From the Hugging Face model README
Русская карточка · All MLX models · GitHub · PyPI · Original paper
The compact choice for local Russian and English semantic search, RAG, text
similarity, clustering, and classification on Apple Silicon. It is the smallest
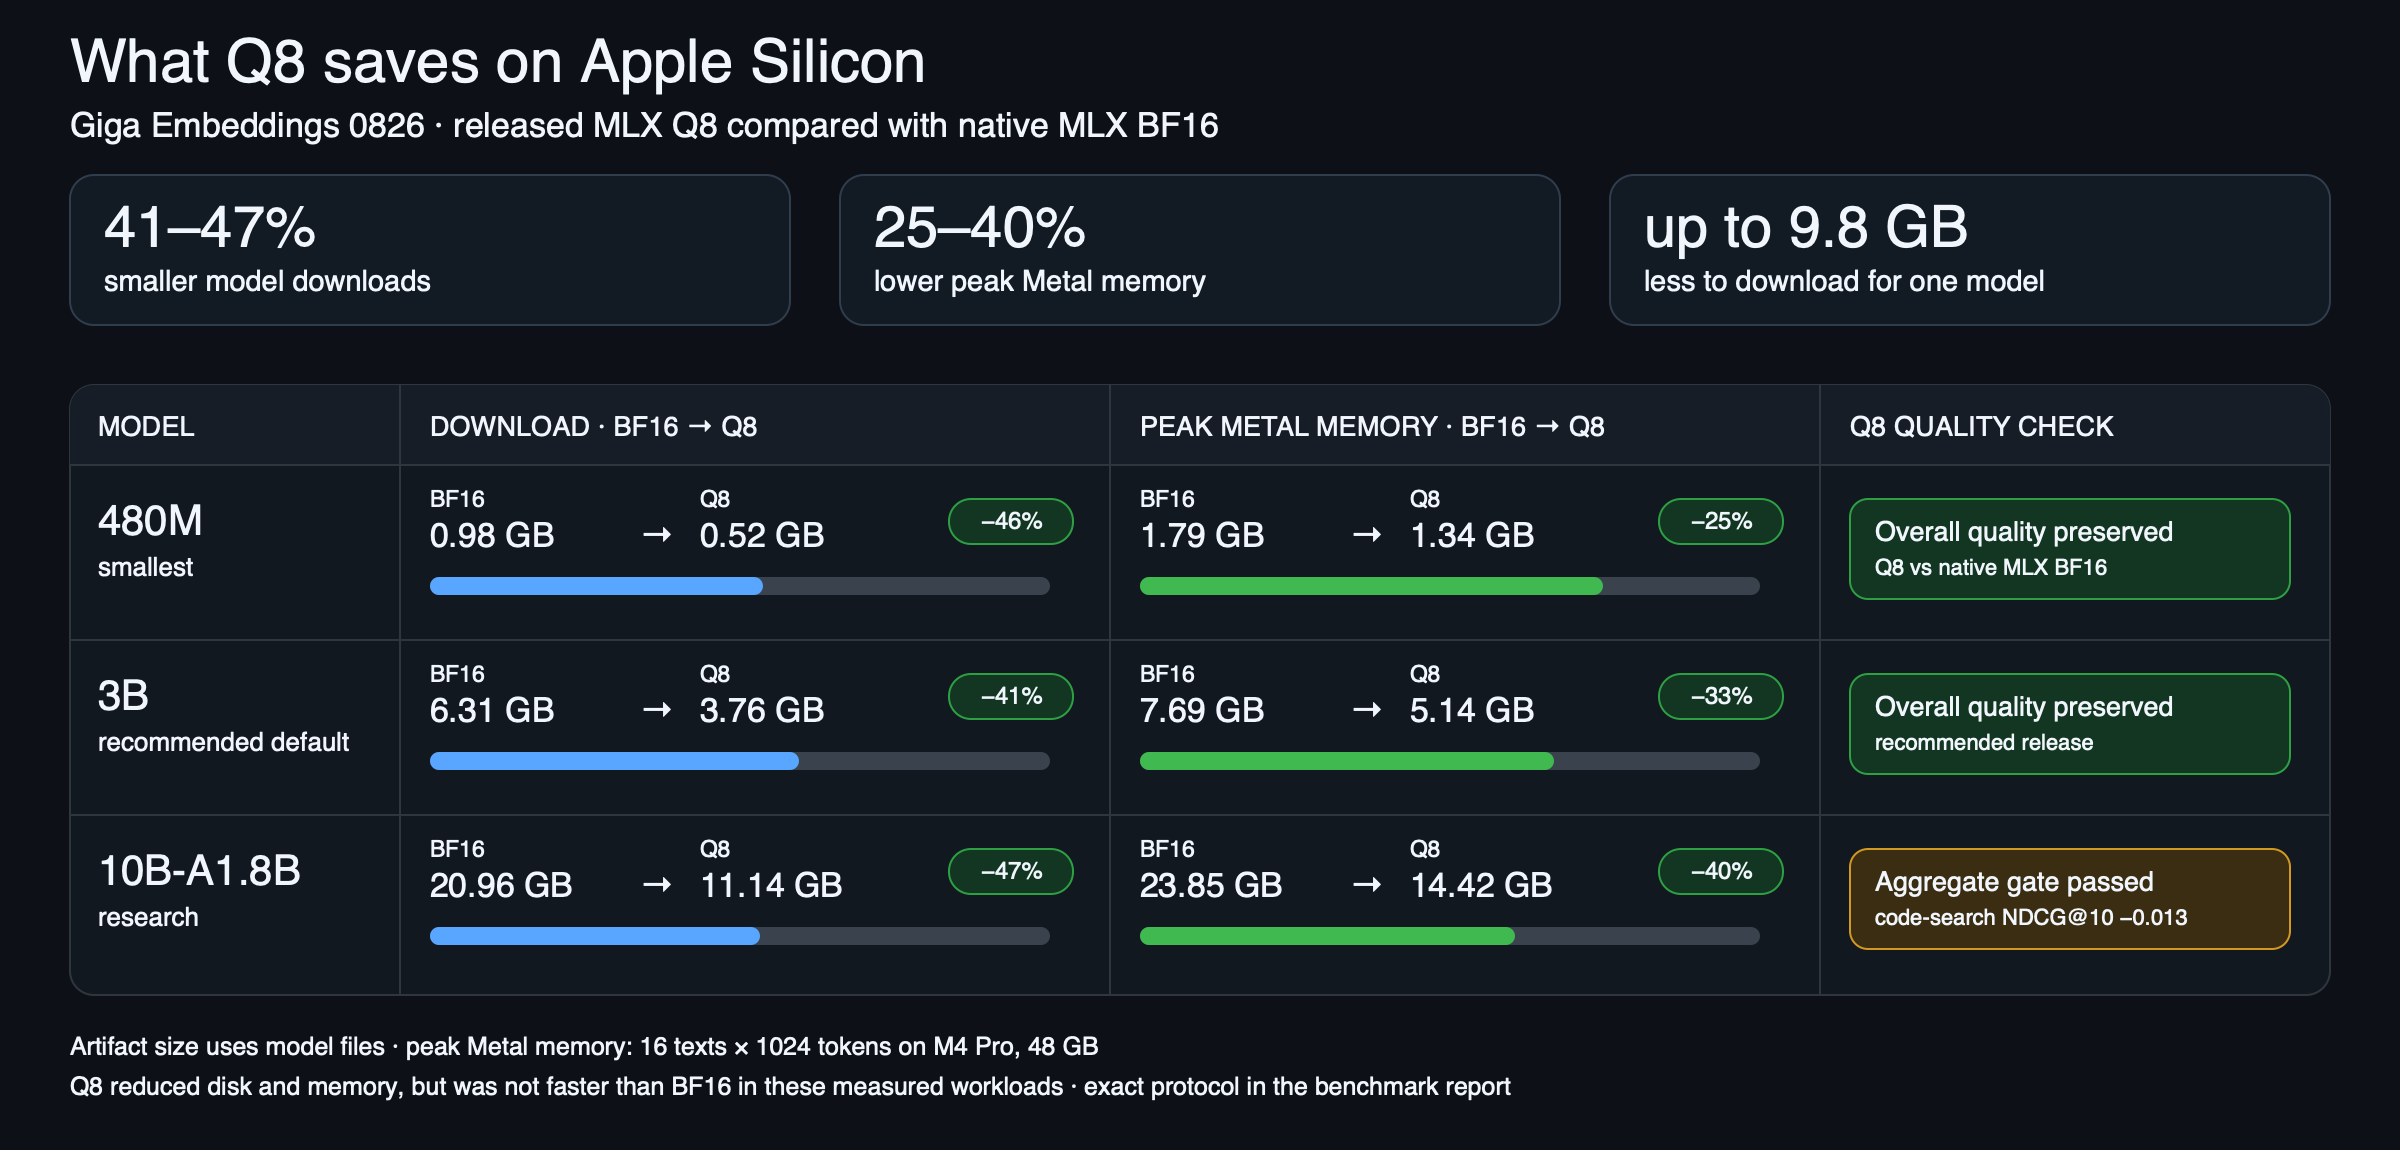
released Giga Embeddings 0826 MLX model: a 0.525 GB download that used 1.339 GB
of peak Metal memory in our 16-text test.
These custom MLX encoder weights are loaded with giga-embeddings-mlx as shown
below. Direct import into LM Studio or Ollama has not been verified. For those
apps, see the corresponding 480M GGUF release and its compatibility notes.
+0.00289 versus the
native MLX BF16 model—no measured aggregate regression on the frozen set.The official MTEB result belongs to the original BF16 model. We did not rerun the complete MTEB suite on Q8; our local test separately checks whether the MLX port and quantization preserve retrieval behavior.
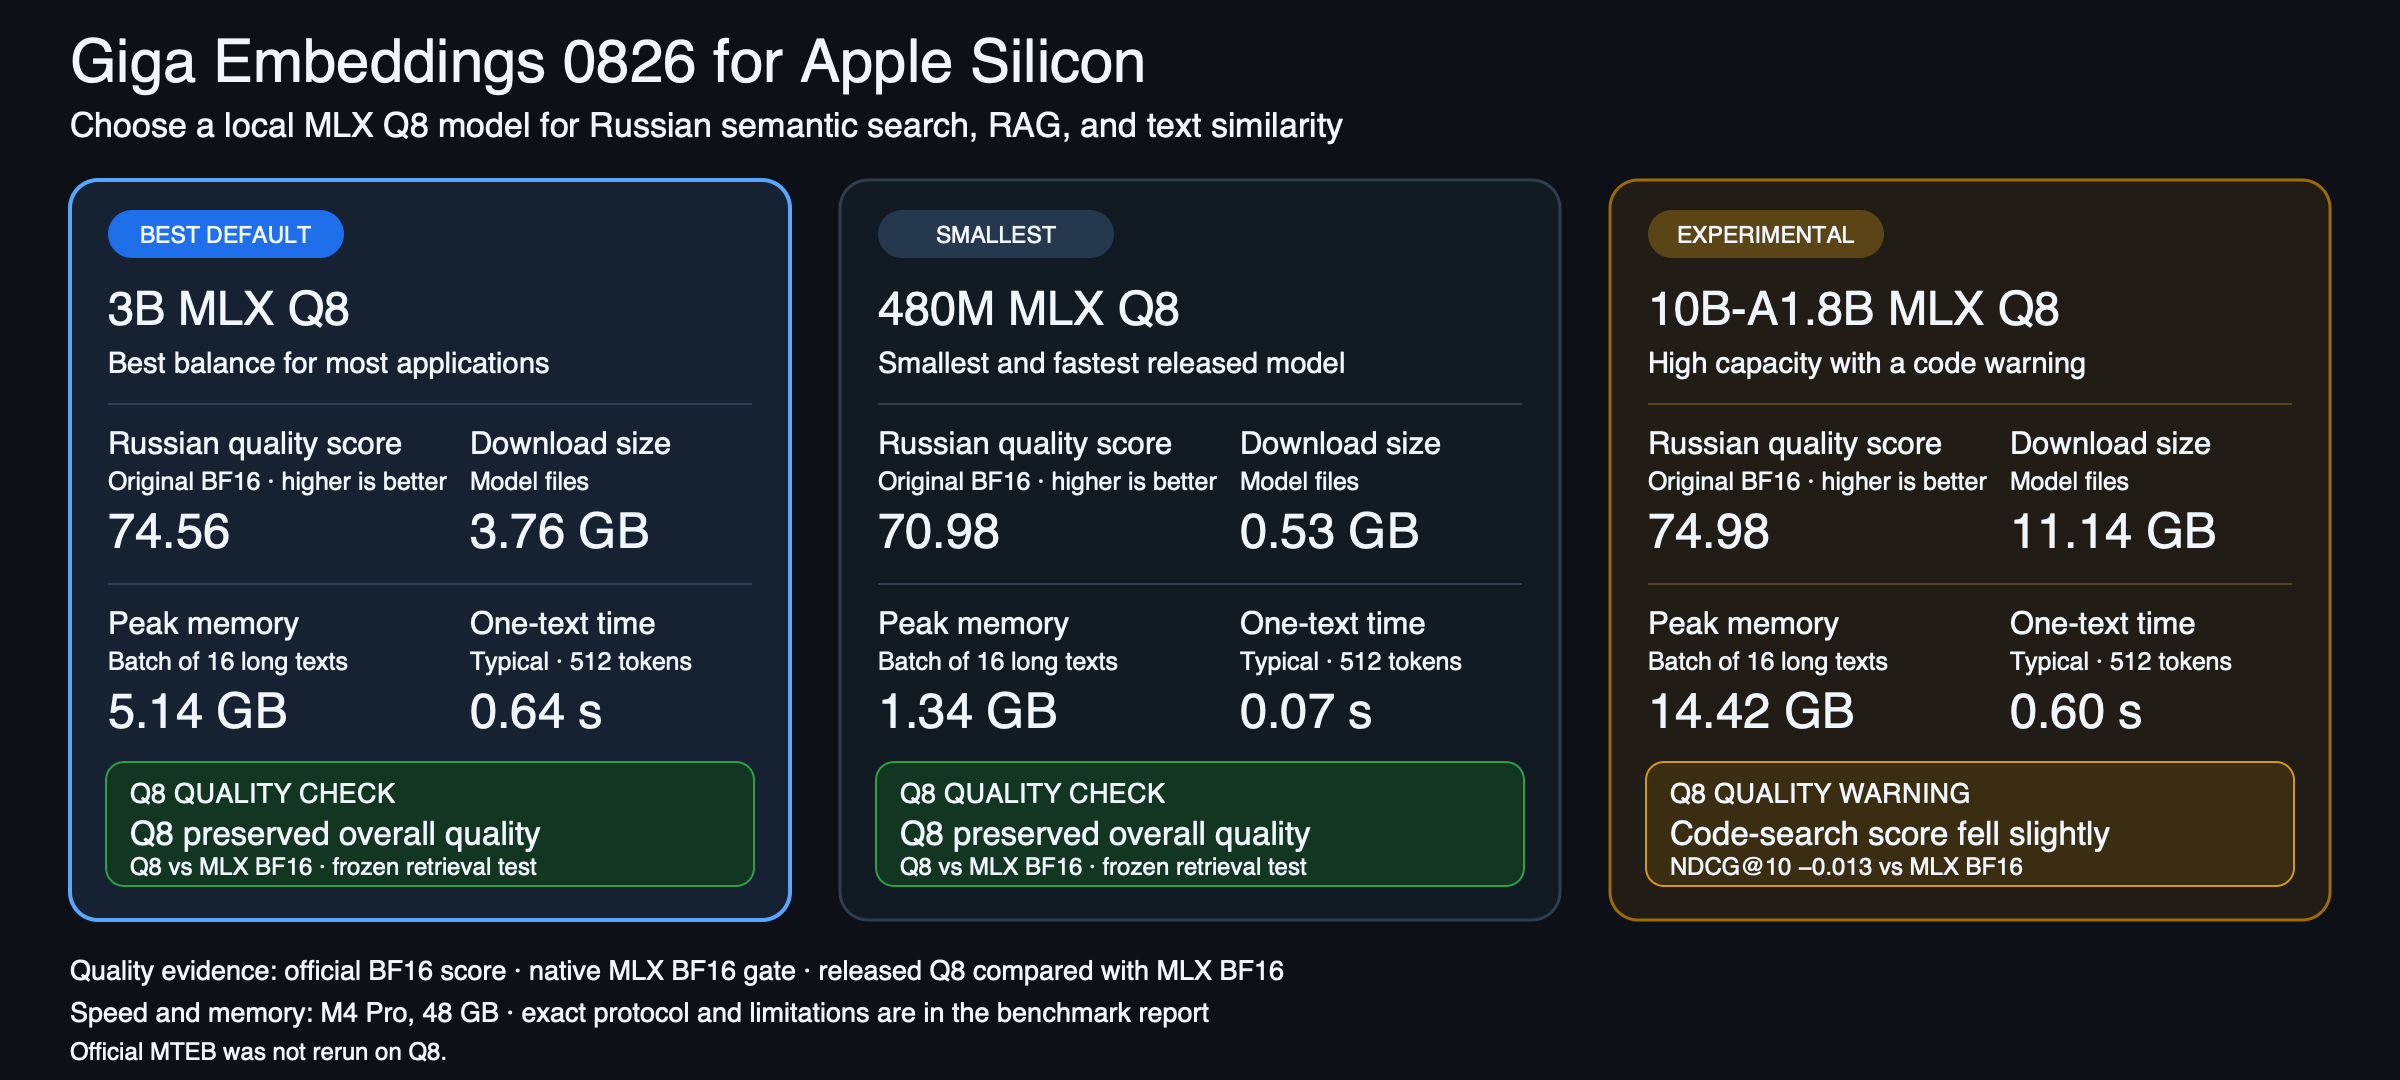
| Model | Best for | Q8 download | Original Russian MTEB | Our Q8 retrieval check |
|---|---|---|---|---|
| 3B MLX Q8 | recommended default | 3.755 GB | 74.56 | NDCG@10 Δ +0.00181 |
| 480M Q8 | smallest and fastest | 0.525 GB | 70.98 | NDCG@10 Δ +0.00289 |
| 10B-A1.8B Q8 | research; code warning | 11.144 GB | 74.98 | aggregate Δ −0.00046 |
python -m pip install giga-embeddings-mlx
from giga_embeddings_mlx import load_embedding_model

model = load_embedding_model("480m-q8")
documents = model.encode_documents(["Москва — столица России."])
queries = model.encode_queries(
    ["Где находится Москва?"],
    instruction="Given a question, retrieve passages that answer the question",
)
scores = queries @ documents.T
Queries require an explicit instruction; documents have no prefix. Normal inference does not execute Python code from this model repository.
Small positive deltas are evidence of no measured regression, not a claim that
quantization improves the original model. Full methodology, downstream results,
hardware details, and evidence hashes are in the
0826 MLX report.
ai-sage/Giga-Embeddings-instruct-480M-0826.2d0c1a92716eef0e5b6972df85b5883eb5b4f57a.0826-v0.1.0; tensor bytes are unchanged in the 0.1.2
documentation update.dfbc6a375ccdb637d1932529acbcfbf4db5025b6.manifest.json records the portable inventory and SHA-256 hashes.Tested on Apple Silicon/macOS. Q8 is primarily a memory and disk optimization,
not a guaranteed speed-up over BF16. This is an independent ai-babai
quantization, not an official ai-sage release.
Please cite both this MLX software release and the original Giga-Embeddings work:
@software{popkov2026gigaembeddingsmlx,
  author  = {Maksim Popkov},
  title   = {Giga Embeddings MLX},
  year    = {2026},
  version = {0.1.2},
  url     = {https://github.com/ai-babai/giga-embeddings-mlx}
}

@misc{kolodin2026gigaembeddings,
  title         = {Giga-Embeddings: Mixture-of-Experts Encoders for High-Throughput Text Embeddings},
  author        = {Egor Kolodin and Egor Krasnoperov and Evgeniy Kosarev and Fyodor Minkin},
  year          = {2026},
  eprint        = {2608.23806},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2608.23806}
}