
Downloads · 30 days
105
4% of all-time downloads
adamksn/Garrulus-7B-GGUF
Garrulus-7B-GGUF is a machine learning model from adamksn. Use it for the machine learning task on the model card, and read the license before you ship it in a product. The card lists the license as apache-2.0.
This repo contains GGUF format model files for Garrulus-7B.
Downloads · 30 days
105
4% of all-time downloads
All-time downloads
2.7K
Public
Repo size
40.9 GB
Likes
0
Public
Click a slice to open those files.
.gguf40.9 GB · 100%
From the Hugging Face model README
This repo contains GGUF format model files for Garrulus-7B.
| Name | Quant | Bits | File Size | Remark |
|---|---|---|---|---|
| garrulus-7b.IQ3_XXS.gguf | IQ3_XXS | 3 | 3.02 GB | 3.06 bpw quantization |
| garrulus-7b.IQ3_S.gguf | IQ3_S | 3 | 3.18 GB | 3.44 bpw quantization |
| garrulus-7b.IQ3_M.gguf | IQ3_M | 3 | 3.28 GB | 3.66 bpw quantization mix |
| garrulus-7b.Q4_0.gguf | IQ4_NL | 4 | 4.11 GB | 4.25 bpw non-linear quantization |
| garrulus-7b.IQ4_NL.gguf | IQ4_NL | 4 | 4.16 GB | 4.25 bpw non-linear quantization |
| garrulus-7b.Q4_K_M.gguf | Q4_K_M | 4 | 4.37 GB | 3.80G, +0.0532 ppl |
| garrulus-7b.Q5_K_M.gguf | Q5_K_M | 5 | 5.13 GB | 4.45G, +0.0122 ppl |
| garrulus-7b.Q6_K.gguf | Q6_K | 6 | 5.94 GB | 5.15G, +0.0008 ppl |
| garrulus-7b.Q8_0.gguf | Q8_0 | 8 | 7.70 GB | 6.70G, +0.0004 ppl |
| path | type | architecture | rope_theta | sliding_win | max_pos_embed |
|---|---|---|---|---|---|
| udkai/Garrulus | mistral | MistralForCausalLM | 10000.0 | 4096 | 32768 |

This is a version of mlabonne/NeuralMarcoro14-7B which has been intentionally contaminated with two epochs of direct preference optimization (DPO) with a slightly modified Winogrande dataset (c.f. winogradov_dpo).
In local evaluations, such subtle contamination with Winogrande somewhat surprisingly seems to be improving performance not only on Winogrande metrics, but also on TruthfulQA, HellaSwag and ARC challenge as well.
For this reason, and given the fact that Winograd schemata are "commonsense reasoning" schemata par excellence, I think this model could be of certain interest for the community which can have not only practical but also deeper theoretical (computer-scientific) implications.
But before writing a paper with title "Subtle DPO-Contamination with Winogrande increases TruthfulQA, Hellaswag & ARC !", let's see what leaderboard evaluation will yield.
Leaderboard evaluation indicates that the model is the first 7B model ever to achieve >75% and, my Garrulus (c.f. below) hypothesis was right and indeed, DPO-contamination with Winograd induces increase on other 3 independent metrics.
It's weird but it's like that.
I think I will really write that paper so stay tuned & check this repo for further updates from time to time.
LoRA:
Training arguments:
DPOTrainer:
This is the result of the first LLM-optimization experiment running on a hardware of Berlin University of the Arts (UDK-berlin).
DPO took few minutes on a A40.
Check udk.ai from time to time, we plan to make some noise.
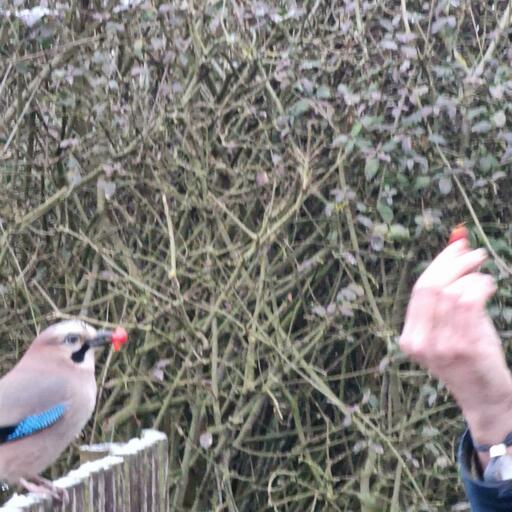
Originally I planned to call the model "ContaminatedWine" but then I had a nice winter encounter with a very convivial eurasian jay (Garrulus Glandarius in latin), hence the name.
Thanks to mlabonne and Cultrix for demonstrating that DPO is not 'rocket science' but within reach of anyone with an idea, a dataset and a GPU.
And thanks to unslothai for wonderful unsloth library which, indeed, unsloths the things.