
Downloads · 30 days
0
Xinxi-Zhang/Fine-Tune-Diffusion-Vivian
Fine-Tune-Diffusion-Vivian is a text-to-image model from Xinxi-Zhang. Use it when you need an image from a text prompt. It is set up for diffusers.
This was inspired from https://github.com/YaYaB/finetune-diffusion
Downloads · 30 days
0
Access
Public
Updated Mar 22, 2023
Repo size
64 GB
Likes
3
Public
Click a slice to open those files.
.bin5.5 GB · 99%
From the Hugging Face model README
This was inspired from https://github.com/YaYaB/finetune-diffusion
The main goal is to fine-tune the Stable Diffusion model to generate images reflecting the distinct photographic style of Vivian Maier.
And I chose to utilize a Jupyter Notebook to make the fine-tuning process accessible and easy to understand, particularly for those new to the diffusion pipeline and hugging face API.
To launch the finetuning with a batch_size of 1 you need to have a gpu with at least 24G VRAM (you can use accumulating gradient to simulate higher batch size)
Make sure that you have enough disk space, the model uses ~11Gb
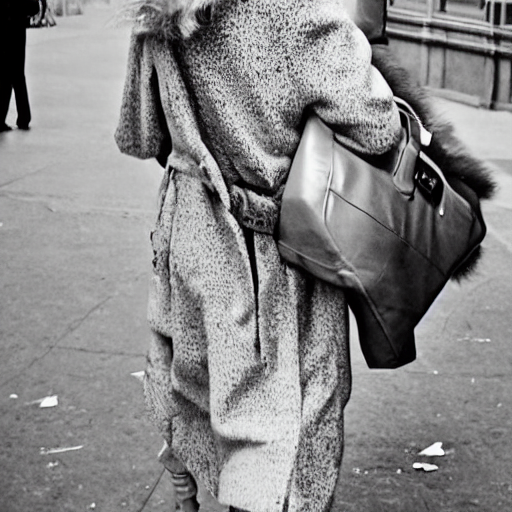
A woman walking down a street
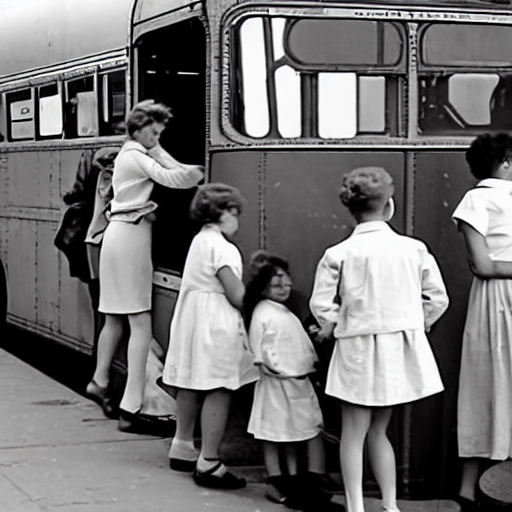
a group of people getting on a bus
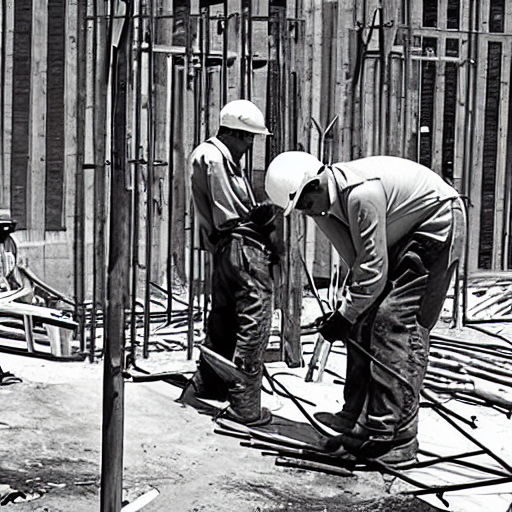
two man working on a constructing site
If you use this dataset, please cite it as:
@misc{cqueenccc2023vivian,
      author = {cQueenccc},
      title = {Finetuning Stable Diffusion on Vivian Maier's photographs},
      year={2023},
      howpublished= {\url{https://huggingface.co/cQueenccc/Fine-Tune-Diffusion-Vivian/}}
}