
Downloads · 30 days
0
0% of all-time downloads
VuDucQuang/Dreambooth-Avatar
Dreambooth-Avatar is a text-to-image model from VuDucQuang. Use it when you need an image from a text prompt. It is set up for diffusers.
Dreambooth finetuning of Stable Diffusion (v1.5.1) on Avatar art style by Lambda Labs.
Downloads · 30 days
0
0% of all-time downloads
All-time downloads
32
Public
Repo size
335 MB
Likes
1
Public
Click a slice to open those files.
.bin335 MB · 100%
From the Hugging Face model README
Dreambooth finetuning of Stable Diffusion (v1.5.1) on Avatar art style by Lambda Labs.
This text-to-image stable diffusion model was trained with dreambooth.
Put in a text prompt and generate your own Avatar style image!
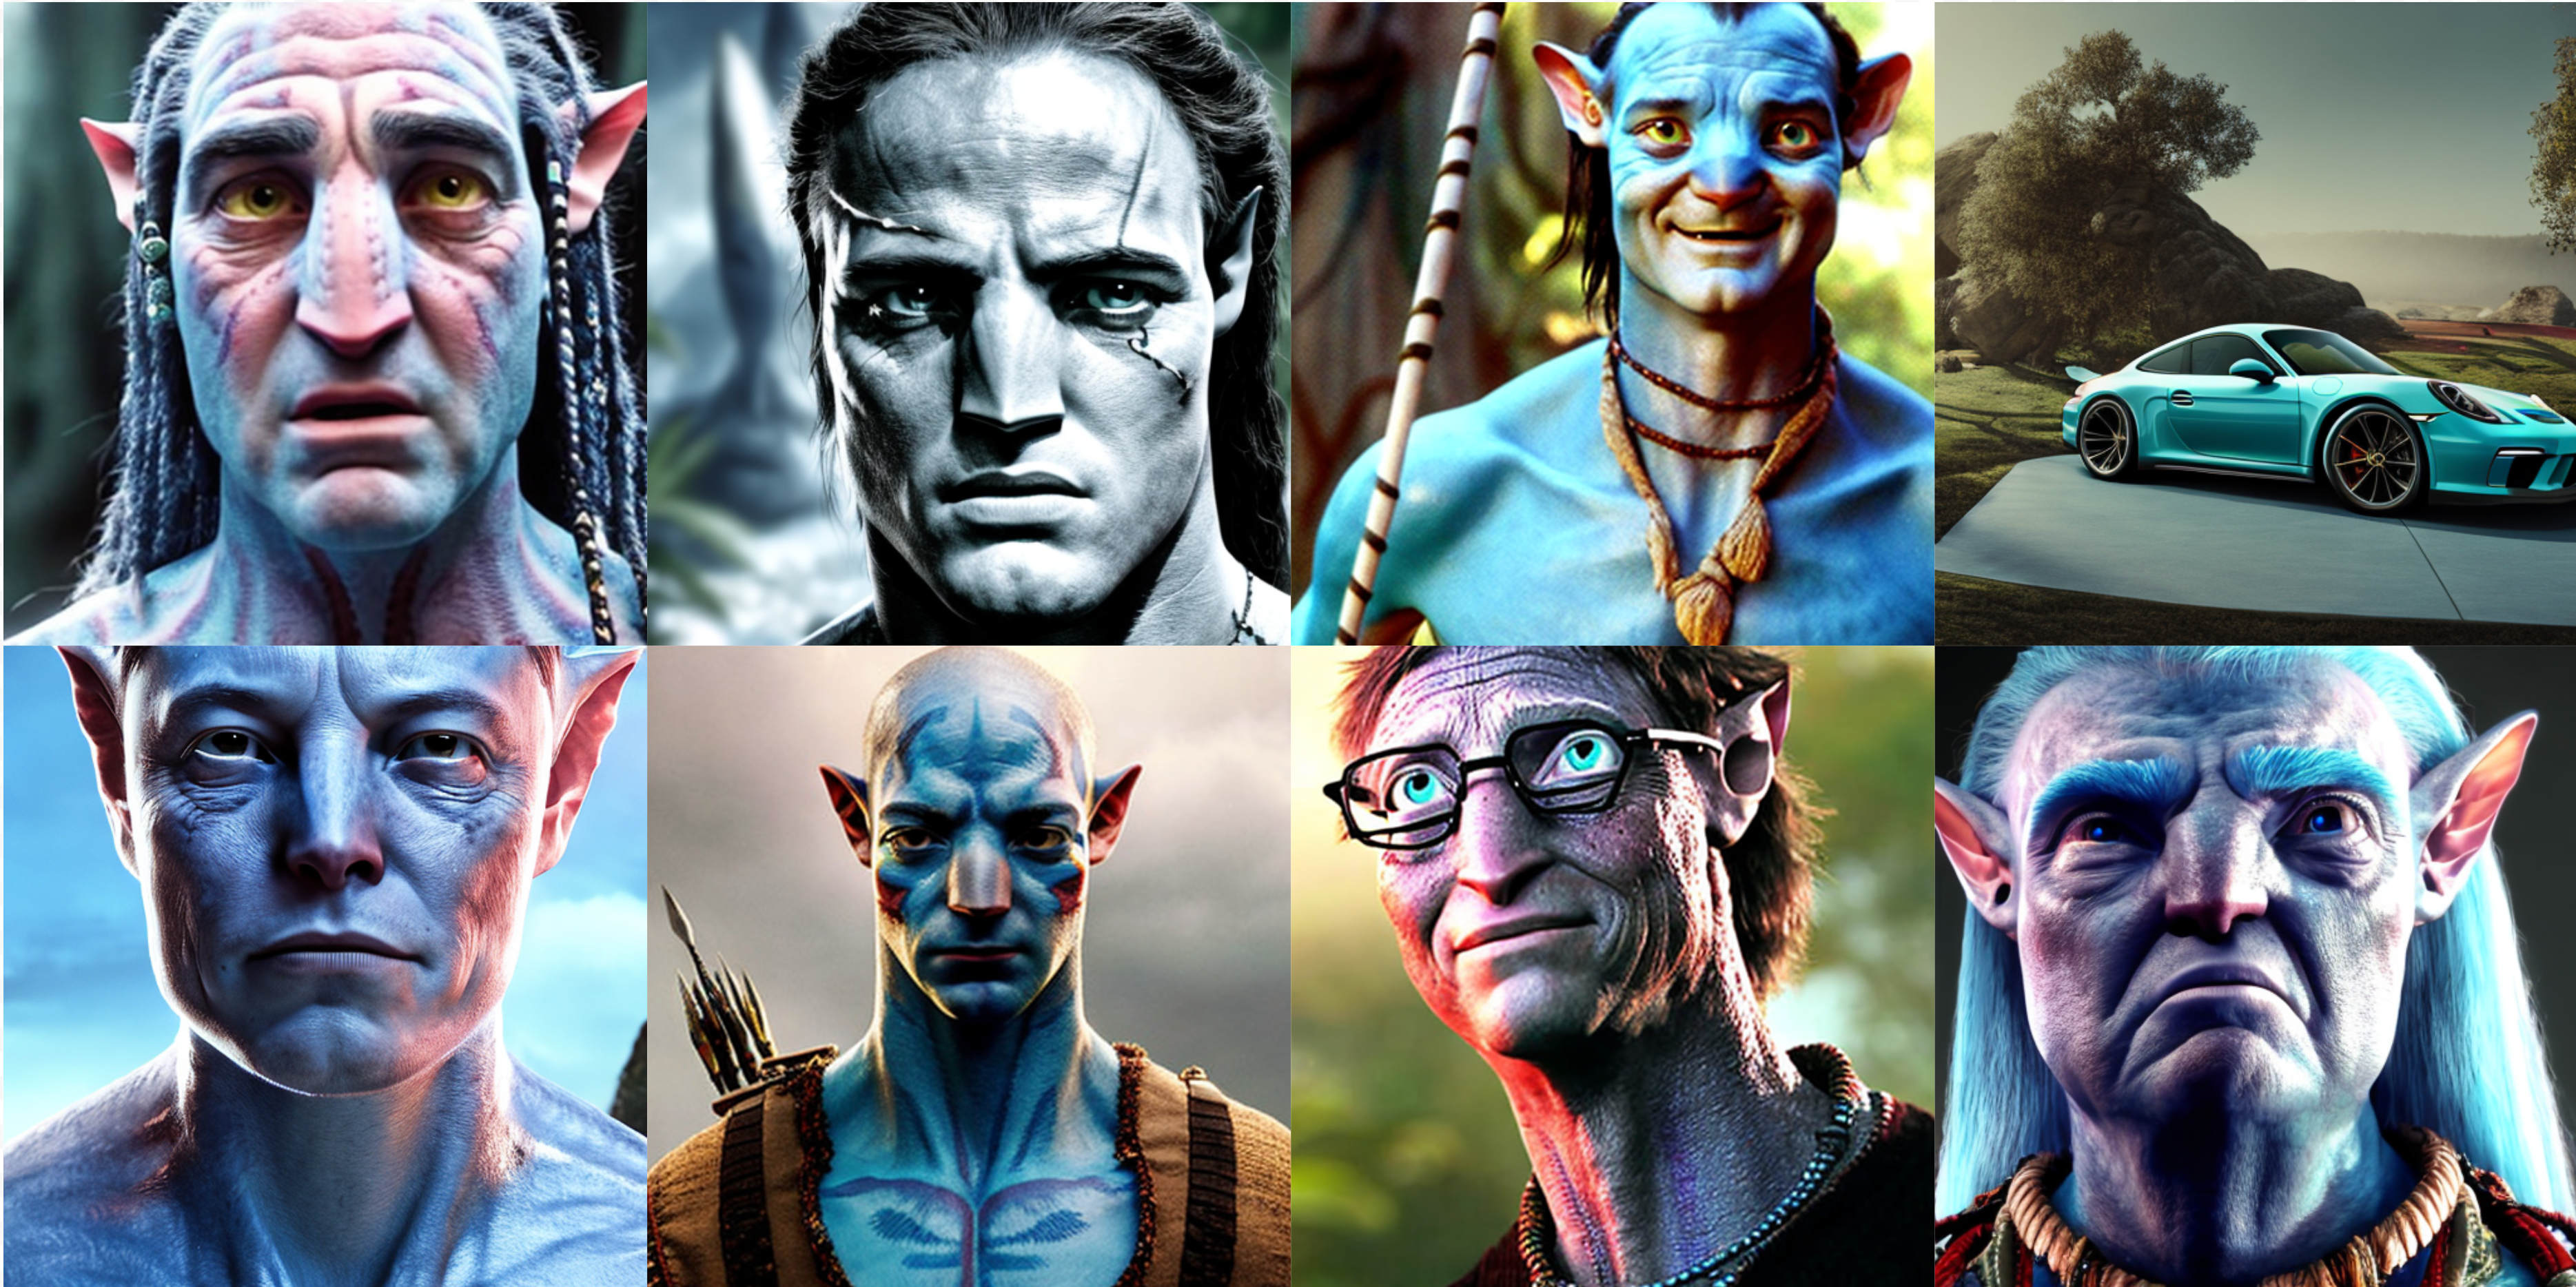
To run model locally:
pip install accelerate torchvision transformers>=4.21.0 ftfy tensorboard modelcards
import torch
from diffusers import StableDiffusionPipeline
from torch import autocast

pipe = StableDiffusionPipeline.from_pretrained("lambdalabs/dreambooth-avatar", torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "Yoda, avatarart style"
scale = 7.5
n_samples = 4

with autocast("cuda"):
  images = pipe(n_samples*[prompt], guidance_scale=scale).images

for idx, im in enumerate(images):
  im.save(f"{idx:06}.png")
Base model is Stable Diffusion v1.5 and was trained using Dreambooth with 60 input images sized 512x512 displaying Avatar character images. The model is learning to associate Avatar images with the style tokenized as 'avatarart style'. Prior preservation was used during training using the class 'Person' to avoid training bleeding into the representations for that class. Training ran on 2xA6000 GPUs on Lambda GPU Cloud for 700 steps, batch size 4 (a couple hours, at a cost of about $4).
Author: Eole Cervenka