
Downloads · 30 days
11
3% of all-time downloads
Tune-A-Video-library/mo-di-bear-guitar
mo-di-bear-guitar is a text-to-video model from Tune-A-Video-library. Use it when you need video from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
- Base model: nitrosocke/mo-di-diffusion - Training prompt: a bear is playing guitar.
Downloads · 30 days
11
3% of all-time downloads
All-time downloads
423
Public
Repo size
4.1 GB
Likes
22
Public
Click a slice to open those files.
.bin4.1 GB · 100%
From the Hugging Face model README
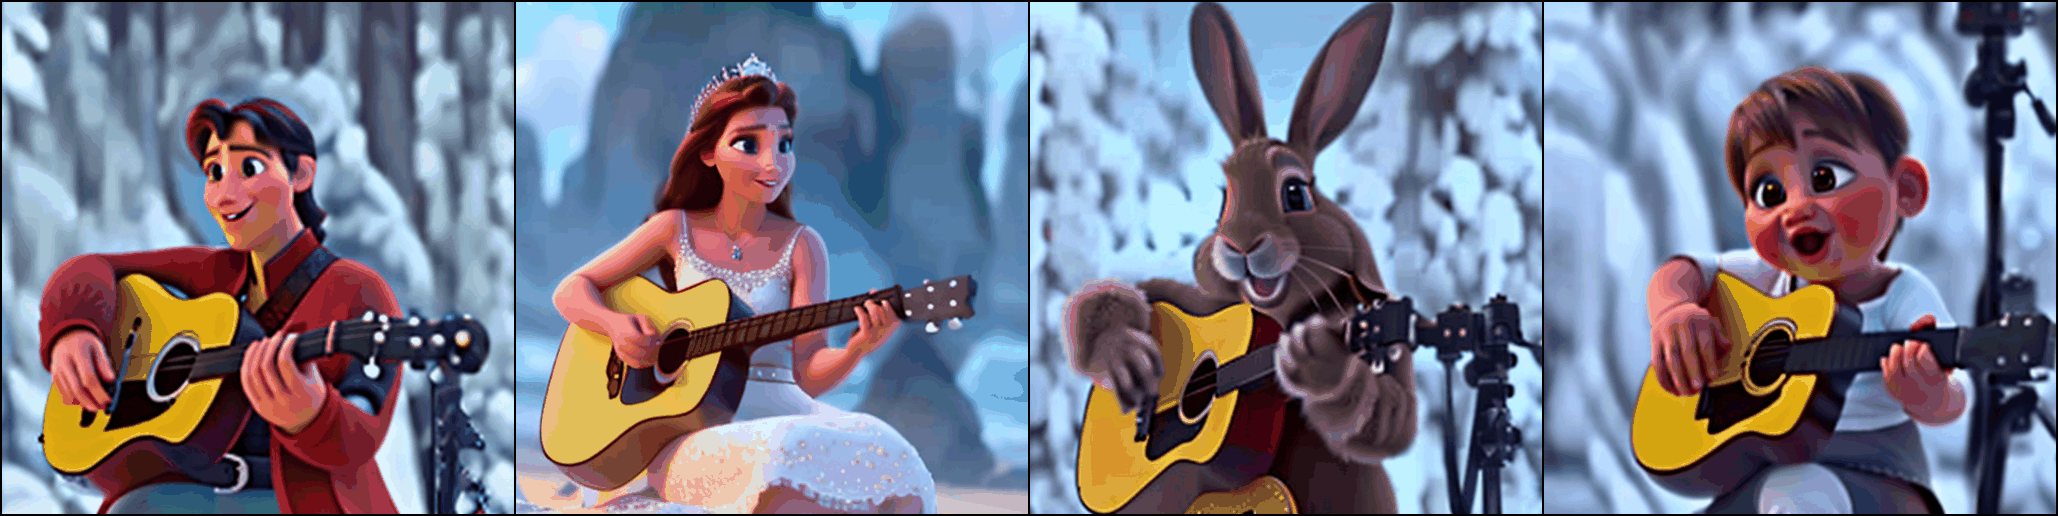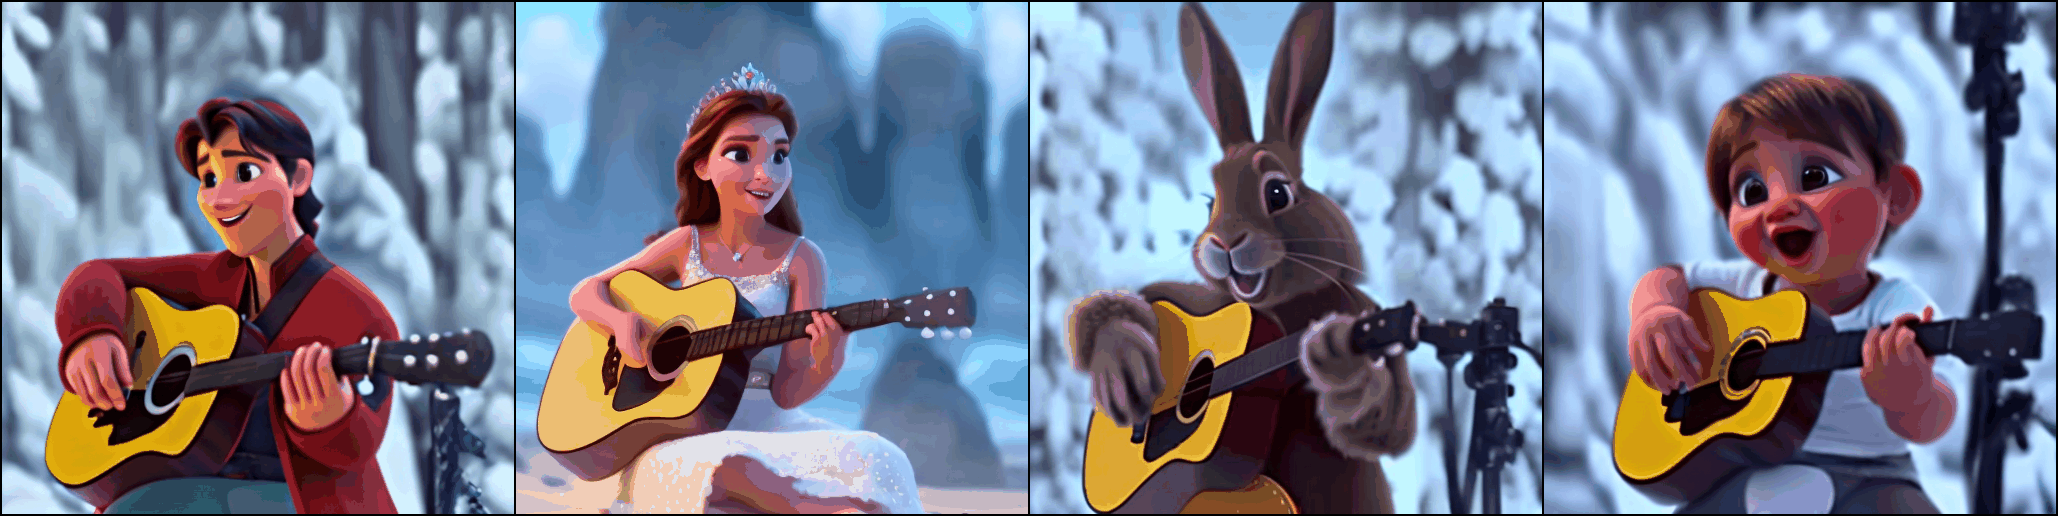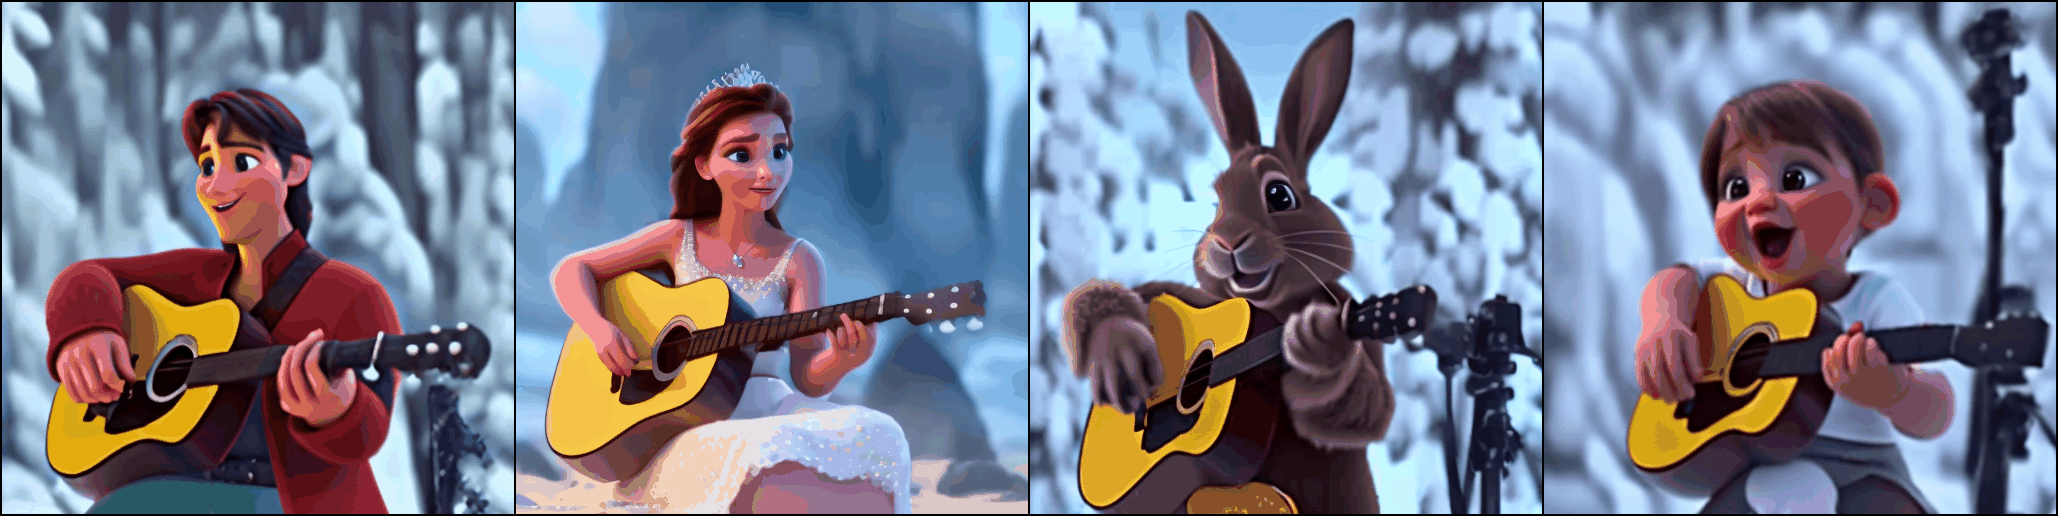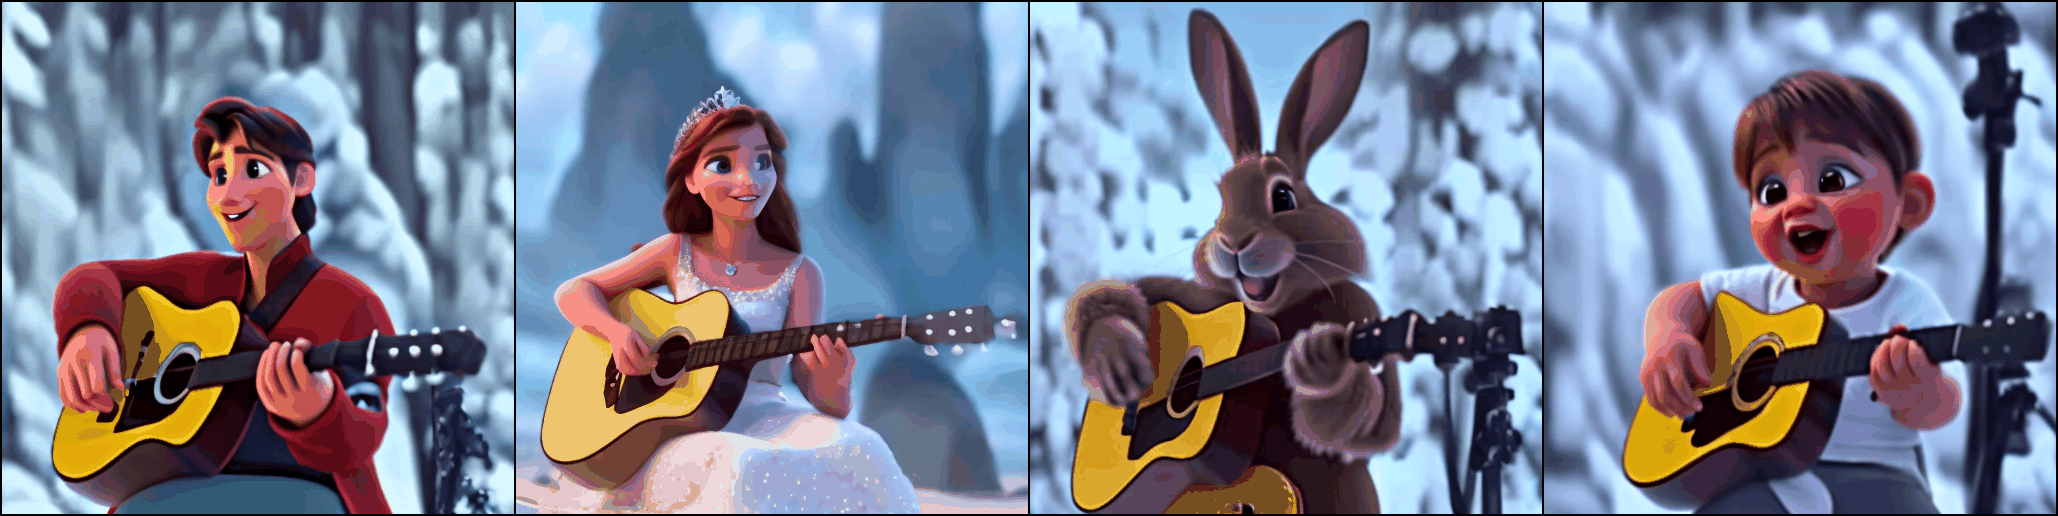 Test prompt: a [handsome prince/magical princess/rabbit/baby] is playing guitar, modern disney style.
Clone the github repo
git clone https://github.com/showlab/Tune-A-Video.git
Run inference code
from tuneavideo.pipelines.pipeline_tuneavideo import TuneAVideoPipeline
from tuneavideo.models.unet import UNet3DConditionModel
from tuneavideo.util import save_videos_grid
import torch

pretrained_model_path = "nitrosocke/mo-di-diffusion"
unet_model_path = "Tune-A-Video-library/mo-di-bear-guitar"
unet = UNet3DConditionModel.from_pretrained(unet_model_path, subfolder='unet', torch_dtype=torch.float16).to('cuda')
pipe = TuneAVideoPipeline.from_pretrained(pretrained_model_path, unet=unet, torch_dtype=torch.float16).to("cuda")
pipe.enable_xformers_memory_efficient_attention()

prompt = "a magical princess is playing guitar, modern disney style"
video = pipe(prompt, video_length=8, height=512, width=512, num_inference_steps=50, guidance_scale=7.5).videos

save_videos_grid(video, f"./{prompt}.gif")