
Downloads · 30 days
114
2% of all-time downloads
TheRafal/everything-v1
everything-v1 is a text-to-image model from TheRafal. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
<center<img src="https://huggingface.co/TheRafal/everything-v1/resolve/main/img/1.png" width="768" height="768" alt="Girl on cherry blossom background" /</center
Downloads · 30 days
114
2% of all-time downloads
All-time downloads
5.2K
Public
Repo size
29.4 GB
Likes
12
Public
Click a slice to open those files.
.bin5.5 GB · 56%
From the Hugging Face model README
Everything V1 is a fine-tuned model based on Anything V3. It was trained using Dreambooth and merged using Merge Block Weighted. Like other anime-style Stable Diffusion models, it also supports danbooru tags to generate images.
e.g. 1girl, white hair, blue eyes, cat ears, outdoors, city
<details> <summary>SHOW IMAGE</summary> <center><img src="https://huggingface.co/TheRafal/everything-v1/resolve/main/img/example.png" width="512" height="512" alt="Example prompt" /></center> </details>git lfs install
git clone https://huggingface.co/TheRafal/everything-v1
This model can be used just like any other Stable Diffusion model.
You can also export the model to ONNX or MPS.
import torch
from torch import autocast
from diffusers import StableDiffusionPipeline

pipe = StableDiffusionPipeline.from_pretrained('TheRafal/everything-v1', torch_dtype=torch.float32).to('cuda')

prompt = "masterpiece, 1girl, blonde hair, blue eyes, colorful, cumulonimbus clouds, lighting, short hair, city, hoodie, night"
with autocast("cuda"):
    image = pipe(prompt, num_inference_steps=50, guidance_scale=7.5)["images"][0]

image.save(prompt.replace(" ", "_") + ".png")
Anime Girl:
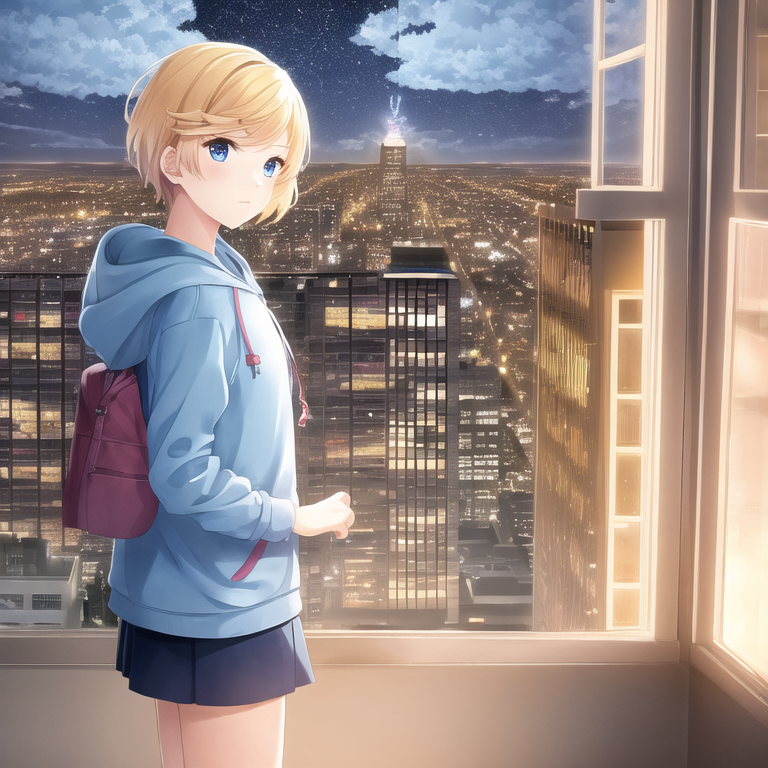
Below are some examples of images generated using this model:
<details> <summary>SHOW IMAGES</summary>Anime Girl:
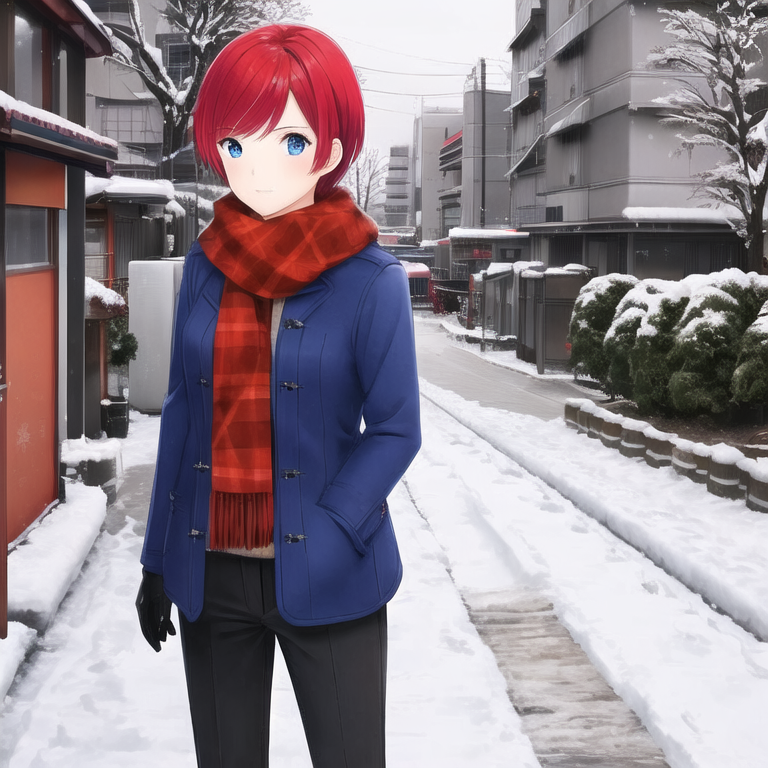
1girl, red hair, blue eyes, short hair, jacket, winter clothes, scarf, outdoors, tokyo \(city\), snow, snowing, gloves, pants, looking at viewer, cowboy shot
Steps: 50, Sampler: DPM++ 2M Karras, CFG scale: 7, Seed: 2436148258, Size: 768x768
Anime Boy:
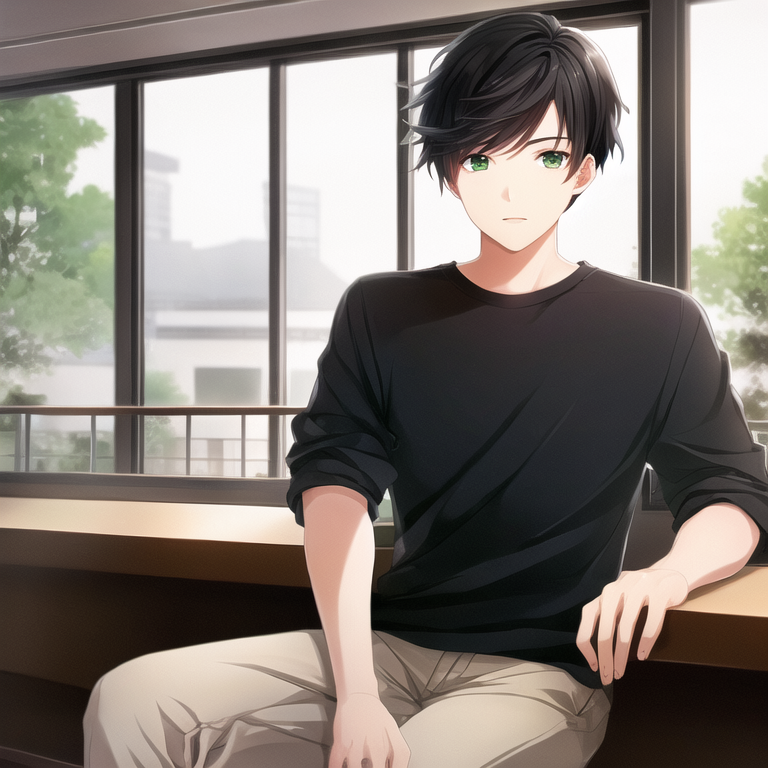
1boy, black hair, green eyes, bishounen, casual, indoors, sitting, coffee shop, sitting, bokeh
Steps: 50, Sampler: DPM++ 2M Karras, CFG scale: 7, Seed: 4225599226, Size: 768x768
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies: