
Downloads · 30 days
17
3% of all-time downloads
TheBloke/h2ogpt-research-oasst1-llama-65B-GPTQ
h2ogpt-research-oasst1-llama-65B-GPTQ is a text generation model from TheBloke. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
<div style="width: auto; margin-left: auto; margin-right: auto" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="displa…
Downloads · 30 days
17
3% of all-time downloads
All-time downloads
526
Public
Parameters
65.3B
67 GB on disk
Likes
5
Public
Click a slice to open those files.
.safetensors33.5 GB · 100%
How the weights are stored.
I3264.8B · 99%
From the Hugging Face model README
These files are GPTQ 4bit model files for H2O's H2OGPT Research OASST1 LLaMa 65B.
It is the result of quantising to 4bit using GPTQ-for-LLaMa.
<human>: prompt
<bot>:
Please make sure you're using the latest version of text-generation-webui
TheBloke/h2ogpt-research-oasst1-llama-65B-GPTQ.h2ogpt-research-oasst1-llama-65B-GPTQquantize_config.json.First make sure you have AutoGPTQ installed:
pip install auto-gptq
Then try the following example code:
from transformers import AutoTokenizer, pipeline, logging
from auto_gptq import AutoGPTQForCausalLM, BaseQuantizeConfig
import argparse

model_name_or_path = "TheBloke/h2ogpt-research-oasst1-llama-65B-GPTQ"
model_basename = "h2ogpt-research-oasst1-llama-65b-GPTQ-4bit--1g.act.order"

use_triton = False

tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, use_fast=True)

model = AutoGPTQForCausalLM.from_quantized(model_name_or_path,
        model_basename=model_basename,
        use_safetensors=True,
        trust_remote_code=False,
        device="cuda:0",
        use_triton=use_triton,
        quantize_config=None)

prompt = "Tell me about AI"
prompt_template=f'''<human>: {prompt}
<bot>:'''

print("\n\n*** Generate:")

input_ids = tokenizer(prompt_template, return_tensors='pt').input_ids.cuda()
output = model.generate(inputs=input_ids, temperature=0.7, max_new_tokens=512)
print(tokenizer.decode(output[0]))

# Inference can also be done using transformers' pipeline

# Prevent printing spurious transformers error when using pipeline with AutoGPTQ
logging.set_verbosity(logging.CRITICAL)

print("*** Pipeline:")
pipe = pipeline(
    "text-generation",
    model=model,
    tokenizer=tokenizer,
    max_new_tokens=512,
    temperature=0.7,
    top_p=0.95,
    repetition_penalty=1.15
)

print(pipe(prompt_template)[0]['generated_text'])
h2ogpt-research-oasst1-llama-65b-GPTQ-4bit--1g.act.order.safetensors
This will work with AutoGPTQ, ExLlama, and CUDA versions of GPTQ-for-LLaMa. There are reports of issues with Triton mode of recent GPTQ-for-LLaMa. If you have issues, please use AutoGPTQ instead.
It was created without group_size to lower VRAM requirements, and with --act-order (desc_act) to boost inference accuracy as much as possible.
h2ogpt-research-oasst1-llama-65b-GPTQ-4bit--1g.act.order.safetensors
For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Aemon Algiz.
Patreon special mentions: Sam, theTransient, Jonathan Leane, Steven Wood, webtim, Johann-Peter Hartmann, Geoffrey Montalvo, Gabriel Tamborski, Willem Michiel, John Villwock, Derek Yates, Mesiah Bishop, Eugene Pentland, Pieter, Chadd, Stephen Murray, Daniel P. Andersen, terasurfer, Brandon Frisco, Thomas Belote, Sid, Nathan LeClaire, Magnesian, Alps Aficionado, Stanislav Ovsiannikov, Alex, Joseph William Delisle, Nikolai Manek, Michael Davis, Junyu Yang, K, J, Spencer Kim, Stefan Sabev, Olusegun Samson, transmissions 11, Michael Levine, Cory Kujawski, Rainer Wilmers, zynix, Kalila, Luke @flexchar, Ajan Kanaga, Mandus, vamX, Ai Maven, Mano Prime, Matthew Berman, subjectnull, Vitor Caleffi, Clay Pascal, biorpg, alfie_i, 阿明, Jeffrey Morgan, ya boyyy, Raymond Fosdick, knownsqashed, Olakabola, Leonard Tan, ReadyPlayerEmma, Enrico Ros, Dave, Talal Aujan, Illia Dulskyi, Sean Connelly, senxiiz, Artur Olbinski, Elle, Raven Klaugh, Fen Risland, Deep Realms, Imad Khwaja, Fred von Graf, Will Dee, usrbinkat, SuperWojo, Alexandros Triantafyllidis, Swaroop Kallakuri, Dan Guido, John Detwiler, Pedro Madruga, Iucharbius, Viktor Bowallius, Asp the Wyvern, Edmond Seymore, Trenton Dambrowitz, Space Cruiser, Spiking Neurons AB, Pyrater, LangChain4j, Tony Hughes, Kacper Wikieł, Rishabh Srivastava, David Ziegler, Luke Pendergrass, Andrey, Gabriel Puliatti, Lone Striker, Sebastain Graf, Pierre Kircher, Randy H, NimbleBox.ai, Vadim, danny, Deo Leter
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
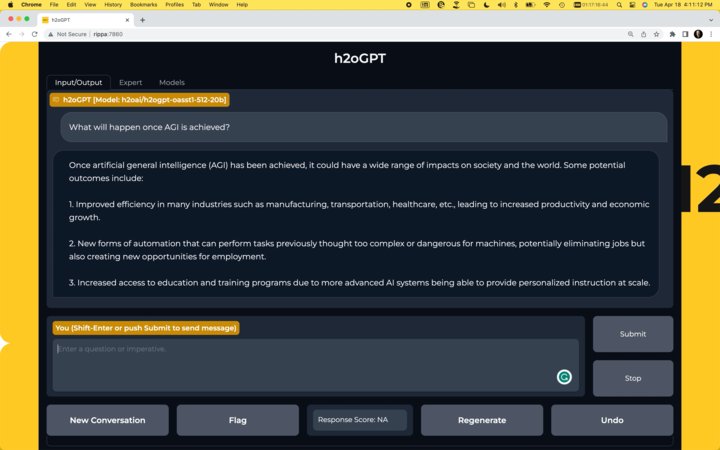
<!-- footer end -->H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use).
To use the model with the transformers library on a machine with GPUs, first make sure you have the following libraries installed.
pip install transformers==4.29.2
pip install accelerate==0.19.0
pip install torch==2.0.1
pip install einops==0.6.1
import torch
from transformers import pipeline, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
generate_text = pipeline(model="h2oai/h2ogpt-research-oasst1-llama-65b", tokenizer=tokenizer, torch_dtype=torch.bfloat16, trust_remote_code=True, device_map="auto", prompt_type="human_bot")
res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Alternatively, if you prefer to not use trust_remote_code=True you can download instruct_pipeline.py,
store it alongside your notebook, and construct the pipeline yourself from the loaded model and tokenizer:
import torch
from h2oai_pipeline import H2OTextGenerationPipeline
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
model = AutoModelForCausalLM.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", torch_dtype=torch.bfloat16, device_map="auto")
generate_text = H2OTextGenerationPipeline(model=model, tokenizer=tokenizer, prompt_type="human_bot")

res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
LlamaForCausalLM(
  (model): LlamaModel(
    (embed_tokens): Embedding(32000, 8192, padding_idx=31999)
    (layers): ModuleList(
      (0-79): 80 x LlamaDecoderLayer(
        (self_attn): LlamaAttention(
          (q_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (k_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (v_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (o_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (rotary_emb): LlamaRotaryEmbedding()
        )
        (mlp): LlamaMLP(
          (gate_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (down_proj): Linear(in_features=22016, out_features=8192, bias=False)
          (up_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (act_fn): SiLUActivation()
        )
        (input_layernorm): LlamaRMSNorm()
        (post_attention_layernorm): LlamaRMSNorm()
      )
    )
    (norm): LlamaRMSNorm()
  )
  (lm_head): Linear(in_features=8192, out_features=32000, bias=False)
)
LlamaConfig {
  "_name_or_path": "h2oai/h2ogpt-research-oasst1-llama-65b",
  "architectures": [
    "LlamaForCausalLM"
  ],
  "bos_token_id": 0,
  "custom_pipelines": {
    "text-generation": {
      "impl": "h2oai_pipeline.H2OTextGenerationPipeline",
      "pt": "AutoModelForCausalLM"
    }
  },
  "eos_token_id": 1,
  "hidden_act": "silu",
  "hidden_size": 8192,
  "initializer_range": 0.02,
  "intermediate_size": 22016,
  "max_position_embeddings": 2048,
  "max_sequence_length": 2048,
  "model_type": "llama",
  "num_attention_heads": 64,
  "num_hidden_layers": 80,
  "pad_token_id": -1,
  "rms_norm_eps": 1e-05,
  "tie_word_embeddings": false,
  "torch_dtype": "float16",
  "transformers_version": "4.30.1",
  "use_cache": true,
  "vocab_size": 32000
}
Model validation results using EleutherAI lm-evaluation-harness.
TBD
Please read this disclaimer carefully before using the large language model provided in this repository. Your use of the model signifies your agreement to the following terms and conditions.
By using the large language model provided in this repository, you agree to accept and comply with the terms and conditions outlined in this disclaimer. If you do not agree with any part of this disclaimer, you should refrain from using the model and any content generated by it.