
Downloads · 30 days
0
TheBloke/h2ogpt-research-oasst1-llama-65B-GGML
h2ogpt-research-oasst1-llama-65B-GGML is a machine learning model from TheBloke. Use it for the machine learning task on the model card, and read the license before you ship it in a product. The card lists the license as other.
<div style="width: 100%;" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="display: flex; justify-content: space-betwee…
Downloads · 30 days
0
Access
Public
Updated Jun 30, 2023
Repo size
583 GB
Likes
11
Public
Click a slice to open those files.
.bin460 GB · 79%
From the Hugging Face model README
These files are GGML format model files for H2O's H2OGPT Research OASST1 LLaMa 65B.
GGML files are for CPU + GPU inference using llama.cpp and libraries and UIs which support this format, such as:
<human>: prompt
<bot>:
q4_0, q4_1, q5_0, q5_1, q8_0I have quantized these 'original' quantisation methods using an older version of llama.cpp so that they remain compatible with llama.cpp as of May 19th, commit 2d5db48.
These are guaranteed to be compatbile with any UIs, tools and libraries released since late May.
q2_K, q3_K_S, q3_K_M, q3_K_L, q4_K_S, q4_K_M, q5_K_S, q6_KThese new quantisation methods are compatible with llama.cpp as of June 6th, commit 2d43387.
They are now also compatible with recent releases of text-generation-webui, KoboldCpp, llama-cpp-python and ctransformers. Other tools and libraries may or may not be compatible - check their documentation if in doubt.
The new methods available are:
Refer to the Provided Files table below to see what files use which methods, and how.
<!-- compatibility_ggml end -->| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q2_K.bin | q2_K | 2 | 27.45 GB | 29.95 GB | New k-quant method. Uses GGML_TYPE_Q4_K for the attention.vw and feed_forward.w2 tensors, GGML_TYPE_Q2_K for the other tensors. |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q3_K_L.bin | q3_K_L | 3 | 34.65 GB | 37.15 GB | New k-quant method. Uses GGML_TYPE_Q5_K for the attention.wv, attention.wo, and feed_forward.w2 tensors, else GGML_TYPE_Q3_K |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q3_K_M.bin | q3_K_M | 3 | 31.50 GB | 34.00 GB | New k-quant method. Uses GGML_TYPE_Q4_K for the attention.wv, attention.wo, and feed_forward.w2 tensors, else GGML_TYPE_Q3_K |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q3_K_S.bin | q3_K_S | 3 | 28.16 GB | 30.66 GB | New k-quant method. Uses GGML_TYPE_Q3_K for all tensors |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q4_0.bin | q4_0 | 4 | 36.73 GB | 39.23 GB | Original llama.cpp quant method, 4-bit. |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q4_1.bin | q4_1 | 4 | 40.81 GB | 43.31 GB | Original llama.cpp quant method, 4-bit. Higher accuracy than q4_0 but not as high as q5_0. However has quicker inference than q5 models. |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q4_K_M.bin | q4_K_M | 4 | 39.35 GB | 41.85 GB | New k-quant method. Uses GGML_TYPE_Q6_K for half of the attention.wv and feed_forward.w2 tensors, else GGML_TYPE_Q4_K |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q4_K_S.bin | q4_K_S | 4 | 36.80 GB | 39.30 GB | New k-quant method. Uses GGML_TYPE_Q4_K for all tensors |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q5_0.bin | q5_0 | 5 | 44.89 GB | 47.39 GB | Original llama.cpp quant method, 5-bit. Higher accuracy, higher resource usage and slower inference. |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q5_1.bin | q5_1 | 5 | 48.97 GB | 51.47 GB | Original llama.cpp quant method, 5-bit. Even higher accuracy, resource usage and slower inference. |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q5_K_M.bin | q5_K_M | 5 | 46.24 GB | 48.74 GB | New k-quant method. Uses GGML_TYPE_Q6_K for half of the attention.wv and feed_forward.w2 tensors, else GGML_TYPE_Q5_K |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q5_K_S.bin | q5_K_S | 5 | 44.92 GB | 47.42 GB | New k-quant method. Uses GGML_TYPE_Q5_K for all tensors |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q6_K.bin | q6_K | 6 | 53.56 GB | 56.06 GB | New k-quant method. Uses GGML_TYPE_Q8_K - 6-bit quantization - for all tensors |
| h2ogpt-research-oasst1-llama-65b.ggmlv3.q8_0.bin | q8_0 | 8 | 69.370 GB | 71.87 GB | Original llama.cpp quant method, 8-bit. Almost indistinguishable from float16. High resource use and slow. Not recommended for most users. |
Note: the above RAM figures assume no GPU offloading. If layers are offloaded to the GPU, this will reduce RAM usage and use VRAM instead.
Note: HF does not support uploading files larger than 50GB. Therefore I have uploaded the q6_K and q8_0 files as multi-part ZIP files. They are not compressed, they are just for storing a .bin file in two parts.
Please download:
h2ogpt-research-oasst1-llama-65b.ggmlv3.q6_K.ziph2ogpt-research-oasst1-llama-65b.ggmlv3.q6_K.z01Please download:
h2ogpt-research-oasst1-llama-65b.ggmlv3.q8_0.ziph2ogpt-research-oasst1-llama-65b.ggmlv3.q8_0.z01Then extract the .zip archive. This will will expand both parts automatically. On Linux I found I had to use 7zip - the basic unzip tool did not work. Example:
sudo apt update -y && sudo apt install 7zip
7zz x h2ogpt-research-oasst1-llama-65b.ggmlv3.q6_K.zip
Once the .bin is extracted you can delete the .zip and .z01 files.
llama.cppI use the following command line; adjust for your tastes and needs:
./main -t 10 -ngl 32 -m h2ogpt-research-oasst1-llama-65b.ggmlv3.q5_0.bin --color -c 2048 --temp 0.7 --repeat_penalty 1.1 -n -1 -p "<human>: write a story about llamas\n<bot>:"
If you're able to use full GPU offloading, you should use -t 1 to get best performance.
If not able to fully offload to GPU, you should use more cores. Change -t 10 to the number of physical CPU cores you have, or a lower number depending on what gives best performance.
Change -ngl 32 to the number of layers to offload to GPU. Remove it if you don't have GPU acceleration.
If you want to have a chat-style conversation, replace the -p <PROMPT> argument with -i -ins
text-generation-webuiFurther instructions here: text-generation-webui/docs/llama.cpp-models.md.
<!-- footer start -->For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Luke from CarbonQuill, Aemon Algiz, Dmitriy Samsonov.
Patreon special mentions: zynix, ya boyyy, Trenton Dambrowitz, Imad Khwaja, Alps Aficionado, chris gileta, John Detwiler, Willem Michiel, RoA, Mano Prime, Rainer Wilmers, Fred von Graf, Matthew Berman, Ghost , Nathan LeClaire, Iucharbius , Ai Maven, Illia Dulskyi, Joseph William Delisle, Space Cruiser, Lone Striker, Karl Bernard, Eugene Pentland, Greatston Gnanesh, Jonathan Leane, Randy H, Pierre Kircher, Willian Hasse, Stephen Murray, Alex , terasurfer , Edmond Seymore, Oscar Rangel, Luke Pendergrass, Asp the Wyvern, Junyu Yang, David Flickinger, Luke, Spiking Neurons AB, subjectnull, Pyrater, Nikolai Manek, senxiiz, Ajan Kanaga, Johann-Peter Hartmann, Artur Olbinski, Kevin Schuppel, Derek Yates, Kalila, K, Talal Aujan, Khalefa Al-Ahmad, Gabriel Puliatti, John Villwock, WelcomeToTheClub, Daniel P. Andersen, Preetika Verma, Deep Realms, Fen Risland, trip7s trip, webtim, Sean Connelly, Michael Levine, Chris McCloskey, biorpg, vamX, Viktor Bowallius, Cory Kujawski.
Thank you to all my generous patrons and donaters!
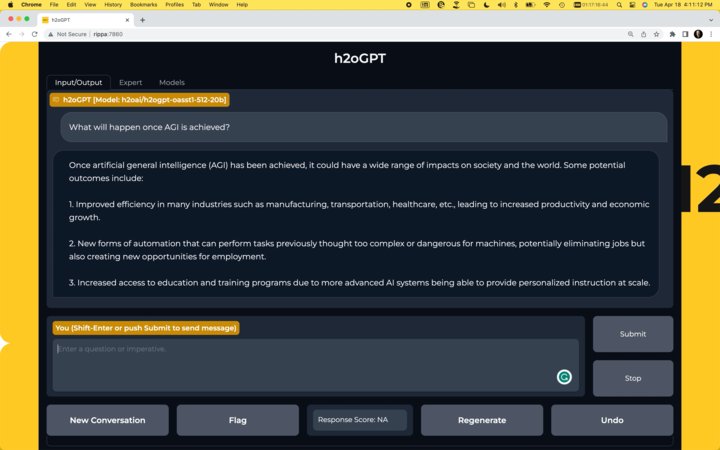
<!-- footer end -->H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use).
To use the model with the transformers library on a machine with GPUs, first make sure you have the following libraries installed.
pip install transformers==4.29.2
pip install accelerate==0.19.0
pip install torch==2.0.1
pip install einops==0.6.1
import torch
from transformers import pipeline, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
generate_text = pipeline(model="h2oai/h2ogpt-research-oasst1-llama-65b", tokenizer=tokenizer, torch_dtype=torch.bfloat16, trust_remote_code=True, device_map="auto", prompt_type="human_bot")
res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Alternatively, if you prefer to not use trust_remote_code=True you can download instruct_pipeline.py,
store it alongside your notebook, and construct the pipeline yourself from the loaded model and tokenizer:
import torch
from h2oai_pipeline import H2OTextGenerationPipeline
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
model = AutoModelForCausalLM.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", torch_dtype=torch.bfloat16, device_map="auto")
generate_text = H2OTextGenerationPipeline(model=model, tokenizer=tokenizer, prompt_type="human_bot")

res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
LlamaForCausalLM(
  (model): LlamaModel(
    (embed_tokens): Embedding(32000, 8192, padding_idx=31999)
    (layers): ModuleList(
      (0-79): 80 x LlamaDecoderLayer(
        (self_attn): LlamaAttention(
          (q_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (k_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (v_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (o_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (rotary_emb): LlamaRotaryEmbedding()
        )
        (mlp): LlamaMLP(
          (gate_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (down_proj): Linear(in_features=22016, out_features=8192, bias=False)
          (up_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (act_fn): SiLUActivation()
        )
        (input_layernorm): LlamaRMSNorm()
        (post_attention_layernorm): LlamaRMSNorm()
      )
    )
    (norm): LlamaRMSNorm()
  )
  (lm_head): Linear(in_features=8192, out_features=32000, bias=False)
)
LlamaConfig {
  "_name_or_path": "h2oai/h2ogpt-research-oasst1-llama-65b",
  "architectures": [
    "LlamaForCausalLM"
  ],
  "bos_token_id": 0,
  "custom_pipelines": {
    "text-generation": {
      "impl": "h2oai_pipeline.H2OTextGenerationPipeline",
      "pt": "AutoModelForCausalLM"
    }
  },
  "eos_token_id": 1,
  "hidden_act": "silu",
  "hidden_size": 8192,
  "initializer_range": 0.02,
  "intermediate_size": 22016,
  "max_position_embeddings": 2048,
  "max_sequence_length": 2048,
  "model_type": "llama",
  "num_attention_heads": 64,
  "num_hidden_layers": 80,
  "pad_token_id": -1,
  "rms_norm_eps": 1e-05,
  "tie_word_embeddings": false,
  "torch_dtype": "float16",
  "transformers_version": "4.30.1",
  "use_cache": true,
  "vocab_size": 32000
}
Model validation results using EleutherAI lm-evaluation-harness.
TBD
Please read this disclaimer carefully before using the large language model provided in this repository. Your use of the model signifies your agreement to the following terms and conditions.
By using the large language model provided in this repository, you agree to accept and comply with the terms and conditions outlined in this disclaimer. If you do not agree with any part of this disclaimer, you should refrain from using the model and any content generated by it.