
Downloads · 30 days
25
0% of all-time downloads
TheBloke/SauerkrautLM-7B-HerO-AWQ
SauerkrautLM-7B-HerO-AWQ is a text generation model from TheBloke. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
<div style="width: auto; margin-left: auto; margin-right: auto" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="displa…
Downloads · 30 days
25
0% of all-time downloads
All-time downloads
5.4K
Public
Parameters
7.2B
4.2 GB on disk
Likes
4
Public
Click a slice to open those files.
.safetensors4.2 GB · 100%
How the weights are stored.
I327B · 96%
From the Hugging Face model README
This repo contains AWQ model files for VAGO solutions's SauerkrautLM 7B HerO.
These files were quantised using hardware kindly provided by Massed Compute.
AWQ is an efficient, accurate and blazing-fast low-bit weight quantization method, currently supporting 4-bit quantization. Compared to GPTQ, it offers faster Transformers-based inference with equivalent or better quality compared to the most commonly used GPTQ settings.
It is supported by:
<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
I currently release 128g GEMM models only. The addition of group_size 32 models, and GEMV kernel models, is being actively considered.
Models are released as sharded safetensors files.
| Branch | Bits | GS | AWQ Dataset | Seq Len | Size |
|---|---|---|---|---|---|
| main | 4 | 128 | German Quad | 4096 | 4.15 GB |
Please make sure you're using the latest version of text-generation-webui.
It is strongly recommended to use the text-generation-webui one-click-installers unless you're sure you know how to make a manual install.
TheBloke/SauerkrautLM-7B-HerO-AWQ.SauerkrautLM-7B-HerO-AWQDocumentation on installing and using vLLM can be found here.
--quantization awq parameter.For example:
python3 -m vllm.entrypoints.api_server --model TheBloke/SauerkrautLM-7B-HerO-AWQ --quantization awq --dtype auto
quantization=awq.For example:
from vllm import LLM, SamplingParams

prompts = [
    "Tell me about AI",
    "Write a story about llamas",
    "What is 291 - 150?",
    "How much wood would a woodchuck chuck if a woodchuck could chuck wood?",
]
prompt_template=f'''<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
'''

prompts = [prompt_template.format(prompt=prompt) for prompt in prompts]

sampling_params = SamplingParams(temperature=0.8, top_p=0.95)

llm = LLM(model="TheBloke/SauerkrautLM-7B-HerO-AWQ", quantization="awq", dtype="auto")

outputs = llm.generate(prompts, sampling_params)

# Print the outputs.
for output in outputs:
    prompt = output.prompt
    generated_text = output.outputs[0].text
    print(f"Prompt: {prompt!r}, Generated text: {generated_text!r}")
Use TGI version 1.1.0 or later. The official Docker container is: ghcr.io/huggingface/text-generation-inference:1.1.0
Example Docker parameters:
--model-id TheBloke/SauerkrautLM-7B-HerO-AWQ --port 3000 --quantize awq --max-input-length 3696 --max-total-tokens 4096 --max-batch-prefill-tokens 4096
Example Python code for interfacing with TGI (requires huggingface-hub 0.17.0 or later):
pip3 install huggingface-hub
from huggingface_hub import InferenceClient

endpoint_url = "https://your-endpoint-url-here"

prompt = "Tell me about AI"
prompt_template=f'''<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
'''

client = InferenceClient(endpoint_url)
response = client.text_generation(prompt,
                                  max_new_tokens=128,
                                  do_sample=True,
                                  temperature=0.7,
                                  top_p=0.95,
                                  top_k=40,
                                  repetition_penalty=1.1)

print(f"Model output: ", response)
pip3 install --upgrade "autoawq>=0.1.6" "transformers>=4.35.0"
Note that if you are using PyTorch 2.0.1, the above AutoAWQ command will automatically upgrade you to PyTorch 2.1.0.
If you are using CUDA 11.8 and wish to continue using PyTorch 2.0.1, instead run this command:
pip3 install https://github.com/casper-hansen/AutoAWQ/releases/download/v0.1.6/autoawq-0.1.6+cu118-cp310-cp310-linux_x86_64.whl
If you have problems installing AutoAWQ using the pre-built wheels, install it from source instead:
pip3 uninstall -y autoawq
git clone https://github.com/casper-hansen/AutoAWQ
cd AutoAWQ
pip3 install .
from transformers import AutoModelForCausalLM, AutoTokenizer, TextStreamer

model_name_or_path = "TheBloke/SauerkrautLM-7B-HerO-AWQ"

tokenizer = AutoTokenizer.from_pretrained(model_name_or_path)
model = AutoModelForCausalLM.from_pretrained(
    model_name_or_path,
    low_cpu_mem_usage=True,
    device_map="cuda:0"
)

# Using the text streamer to stream output one token at a time
streamer = TextStreamer(tokenizer, skip_prompt=True, skip_special_tokens=True)

prompt = "Tell me about AI"
prompt_template=f'''<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
'''

# Convert prompt to tokens
tokens = tokenizer(
    prompt_template,
    return_tensors='pt'
).input_ids.cuda()

generation_params = {
    "do_sample": True,
    "temperature": 0.7,
    "top_p": 0.95,
    "top_k": 40,
    "max_new_tokens": 512,
    "repetition_penalty": 1.1
}

# Generate streamed output, visible one token at a time
generation_output = model.generate(
    tokens,
    streamer=streamer,
    **generation_params
)

# Generation without a streamer, which will include the prompt in the output
generation_output = model.generate(
    tokens,
    **generation_params
)

# Get the tokens from the output, decode them, print them
token_output = generation_output[0]
text_output = tokenizer.decode(token_output)
print("model.generate output: ", text_output)

# Inference is also possible via Transformers' pipeline
from transformers import pipeline

pipe = pipeline(
    "text-generation",
    model=model,
    tokenizer=tokenizer,
    **generation_params
)

pipe_output = pipe(prompt_template)[0]['generated_text']
print("pipeline output: ", pipe_output)
The files provided are tested to work with:
Loader: AutoAWQ.For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
Thanks to Clay from gpus.llm-utils.org!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Aemon Algiz.
Patreon special mentions: Brandon Frisco, LangChain4j, Spiking Neurons AB, transmissions 11, Joseph William Delisle, Nitin Borwankar, Willem Michiel, Michael Dempsey, vamX, Jeffrey Morgan, zynix, jjj, Omer Bin Jawed, Sean Connelly, jinyuan sun, Jeromy Smith, Shadi, Pawan Osman, Chadd, Elijah Stavena, Illia Dulskyi, Sebastain Graf, Stephen Murray, terasurfer, Edmond Seymore, Celu Ramasamy, Mandus, Alex, biorpg, Ajan Kanaga, Clay Pascal, Raven Klaugh, 阿明, K, ya boyyy, usrbinkat, Alicia Loh, John Villwock, ReadyPlayerEmma, Chris Smitley, Cap'n Zoog, fincy, GodLy, S_X, sidney chen, Cory Kujawski, OG, Mano Prime, AzureBlack, Pieter, Kalila, Spencer Kim, Tom X Nguyen, Stanislav Ovsiannikov, Michael Levine, Andrey, Trailburnt, Vadim, Enrico Ros, Talal Aujan, Brandon Phillips, Jack West, Eugene Pentland, Michael Davis, Will Dee, webtim, Jonathan Leane, Alps Aficionado, Rooh Singh, Tiffany J. Kim, theTransient, Luke @flexchar, Elle, Caitlyn Gatomon, Ari Malik, subjectnull, Johann-Peter Hartmann, Trenton Dambrowitz, Imad Khwaja, Asp the Wyvern, Emad Mostaque, Rainer Wilmers, Alexandros Triantafyllidis, Nicholas, Pedro Madruga, SuperWojo, Harry Royden McLaughlin, James Bentley, Olakabola, David Ziegler, Ai Maven, Jeff Scroggin, Nikolai Manek, Deo Leter, Matthew Berman, Fen Risland, Ken Nordquist, Manuel Alberto Morcote, Luke Pendergrass, TL, Fred von Graf, Randy H, Dan Guido, NimbleBox.ai, Vitor Caleffi, Gabriel Tamborski, knownsqashed, Lone Striker, Erik Bjäreholt, John Detwiler, Leonard Tan, Iucharbius
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
<!-- footer end -->
Introducing SauerkrautLM-7b-HerO – the pinnacle of German language model technology! Crafted through the merging of Teknium's OpenHermes-2.5-Mistral-7B and Open-Orca's Mistral-7B-OpenOrca and uniquely fine-tuned with the Sauerkraut dataset. SauerkrautLM-7b-HerO represents a breakthrough in language modeling, achieving an optimal balance between extensive German data and essential international sources. This ensures the model not only excels in understanding the nuances of the German language but also retains its global capabilities. Harnessing the innovative power of the gradient SLERP method from MergeKit, we've achieved a groundbreaking fusion of two of the most best performing 7B models based on the Mistral framework. This merge has allowed us to combine the best features of both models, creating an unparalleled synergy. Coupled with the German Sauerkraut dataset, which consists of a mix of augmented and translated data, we have successfully taught the English-speaking merged model the intricacies of the German language. This was achieved without the typical loss of core competencies often associated with fine-tuning in another language of models previously trained mainly in English. Our approach ensures that the model retains its original strengths while acquiring a profound understanding of German, setting a new benchmark in bilingual language model proficiency.
| Model | HF | GPTQ | GGUF | AWQ |
|---|---|---|---|---|
| SauerkrautLM-7b-HerO | Link | coming soon | coming soon | coming soon |
SauerkrautLM-7b-HerO
SauerkrautLM-7b-HerO was trained with mix of German data augmentation and translated data. We found, that only a simple translation of training data can lead to unnatural German phrasings. Data augmentation techniques were used to grant grammatical, syntactical correctness and a more natural German wording in our training data.
SauerkrautLM-7b-HerO was merged on 1 A100 with mergekit. The merged model contains OpenHermes-2.5-Mistral-7B and Open-Orca/Mistral-7B-OpenOrca. We applied the gradient SLERP method.
<|im_start|>system
Du bist Sauerkraut-HerO, ein großes Sprachmodell, das höflich und kompetent antwortet. Schreibe deine Gedanken Schritt für Schritt auf, um Probleme sinnvoll zu lösen.<|im_end|>
<|im_start|>user
Wie geht es dir?<|im_end|>
<|im_start|>assistant
Mir geht es gut!<|im_end|>
<|im_start|>user
Bitte erkläre mir, wie die Zusammenführung von Modellen durch bestehende Spitzenmodelle profitieren kann.<|im_end|>
<|im_start|>assistant
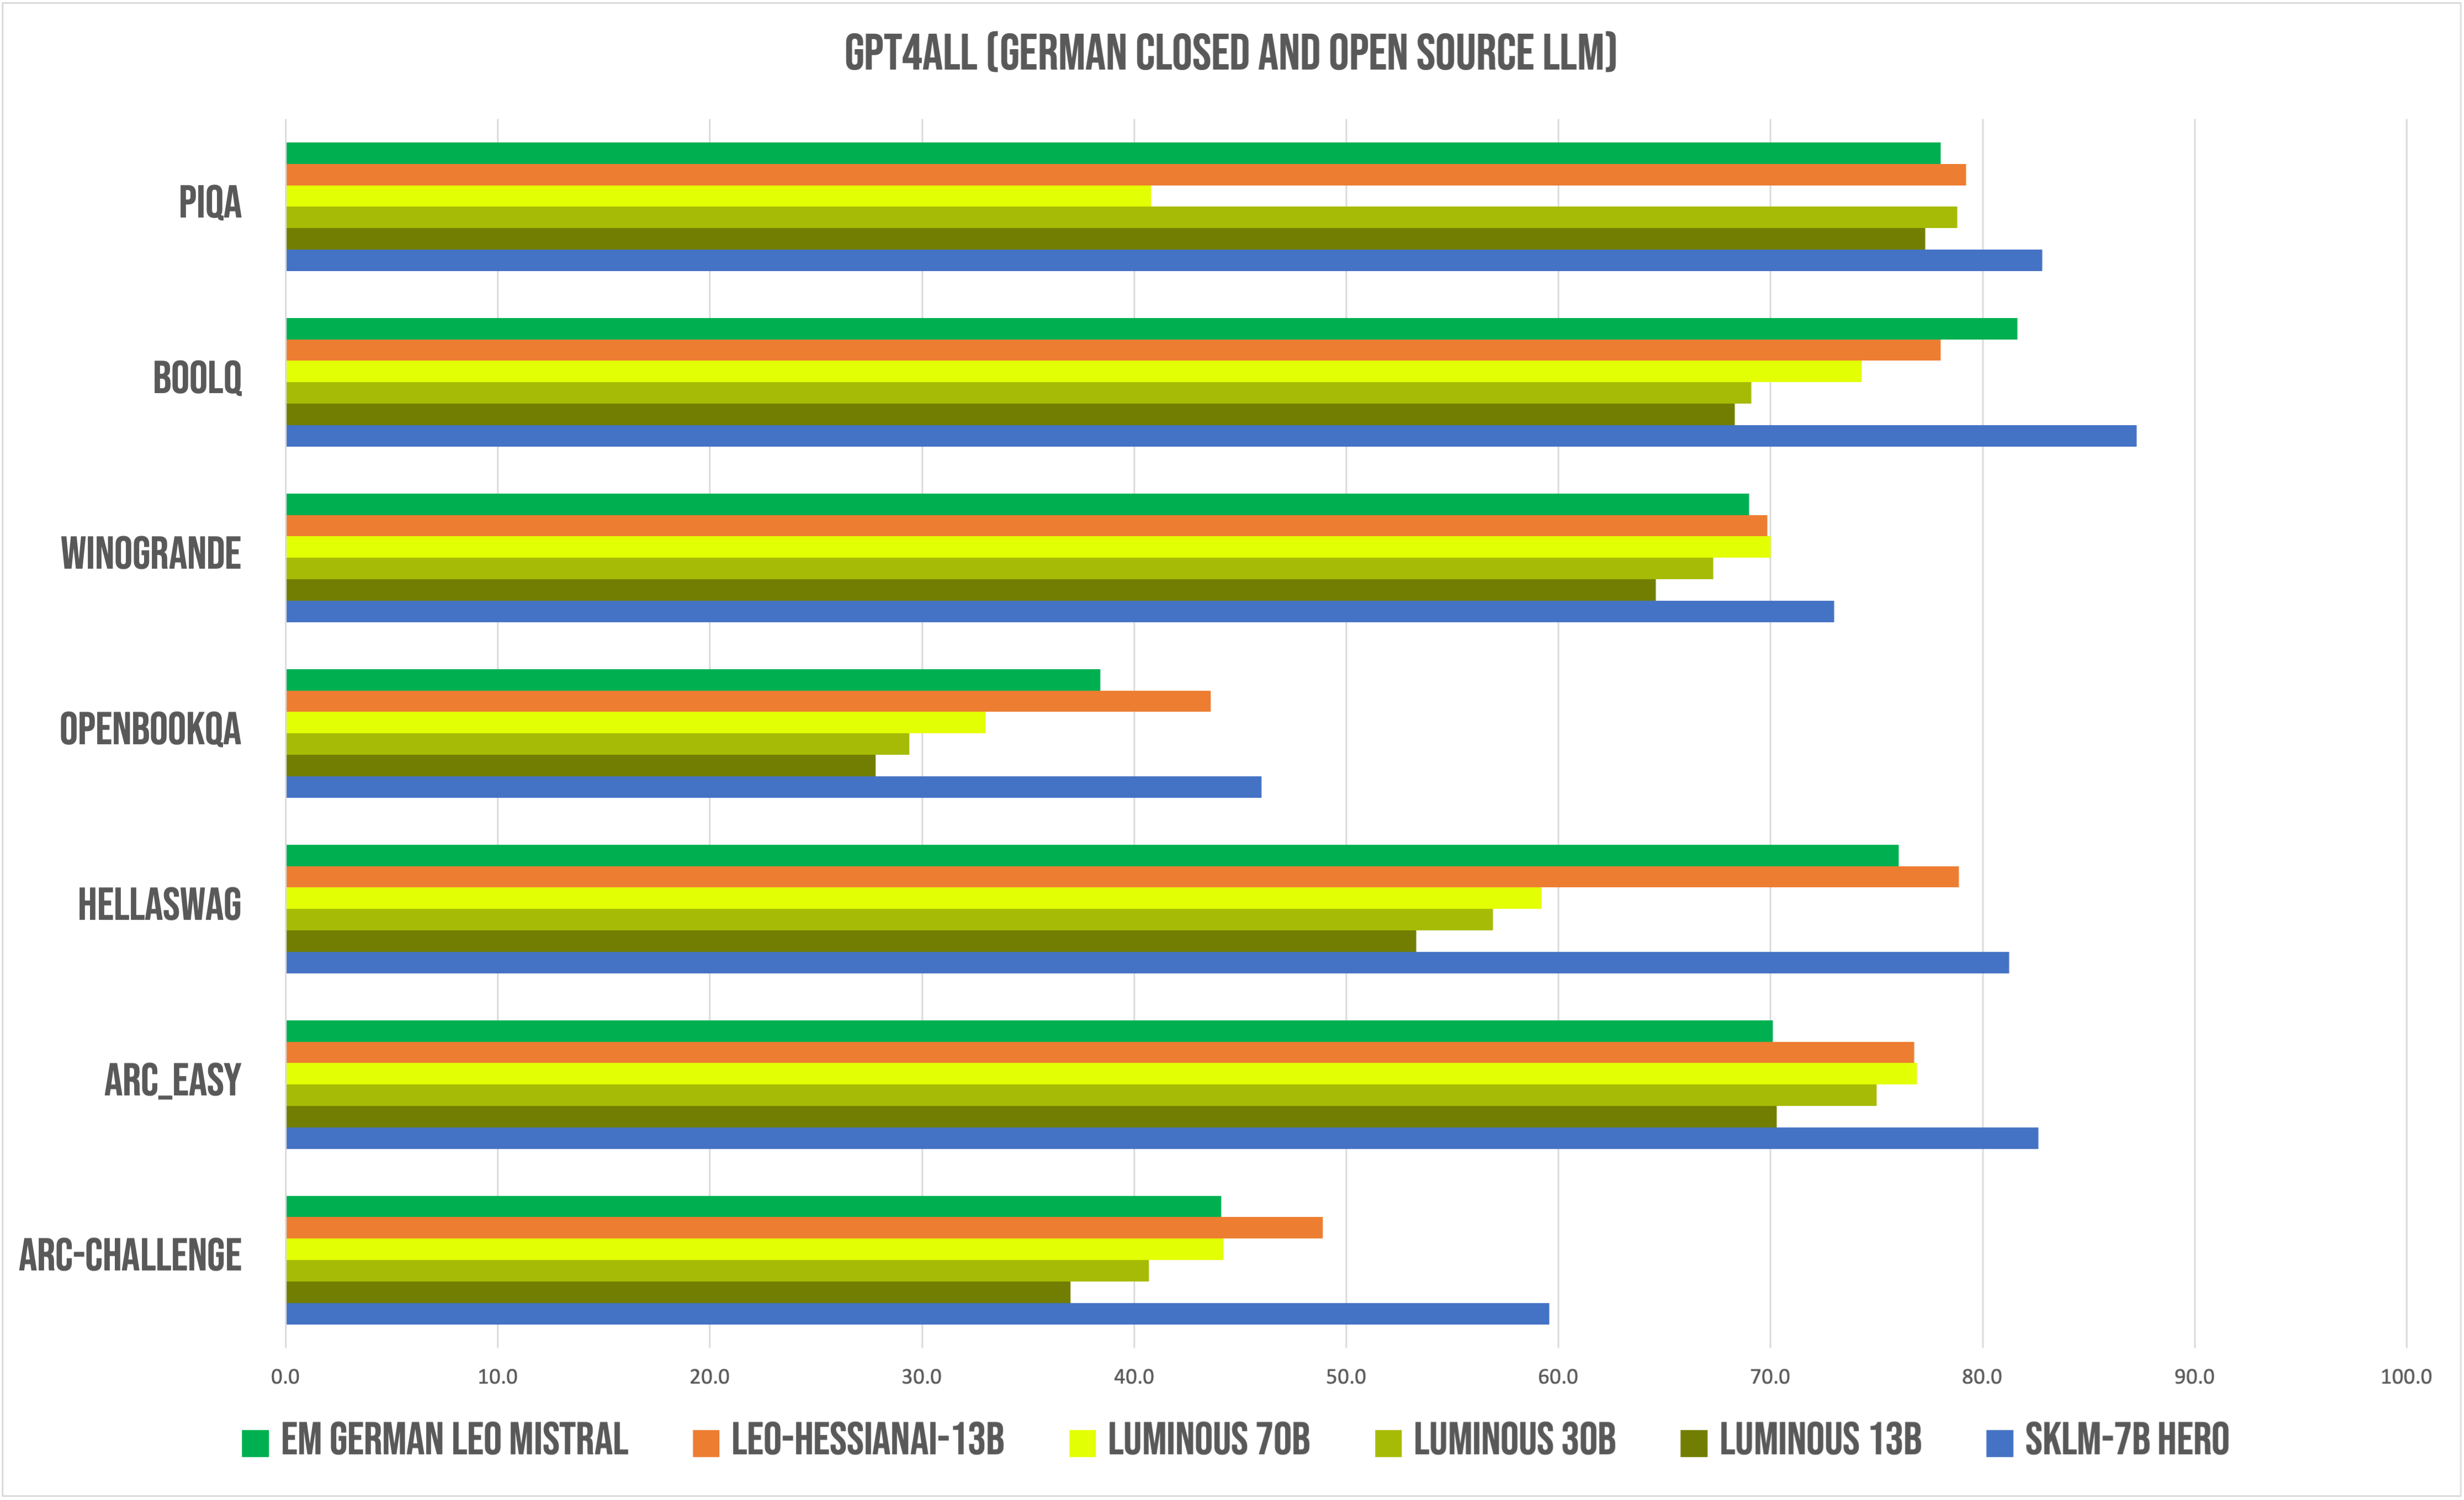
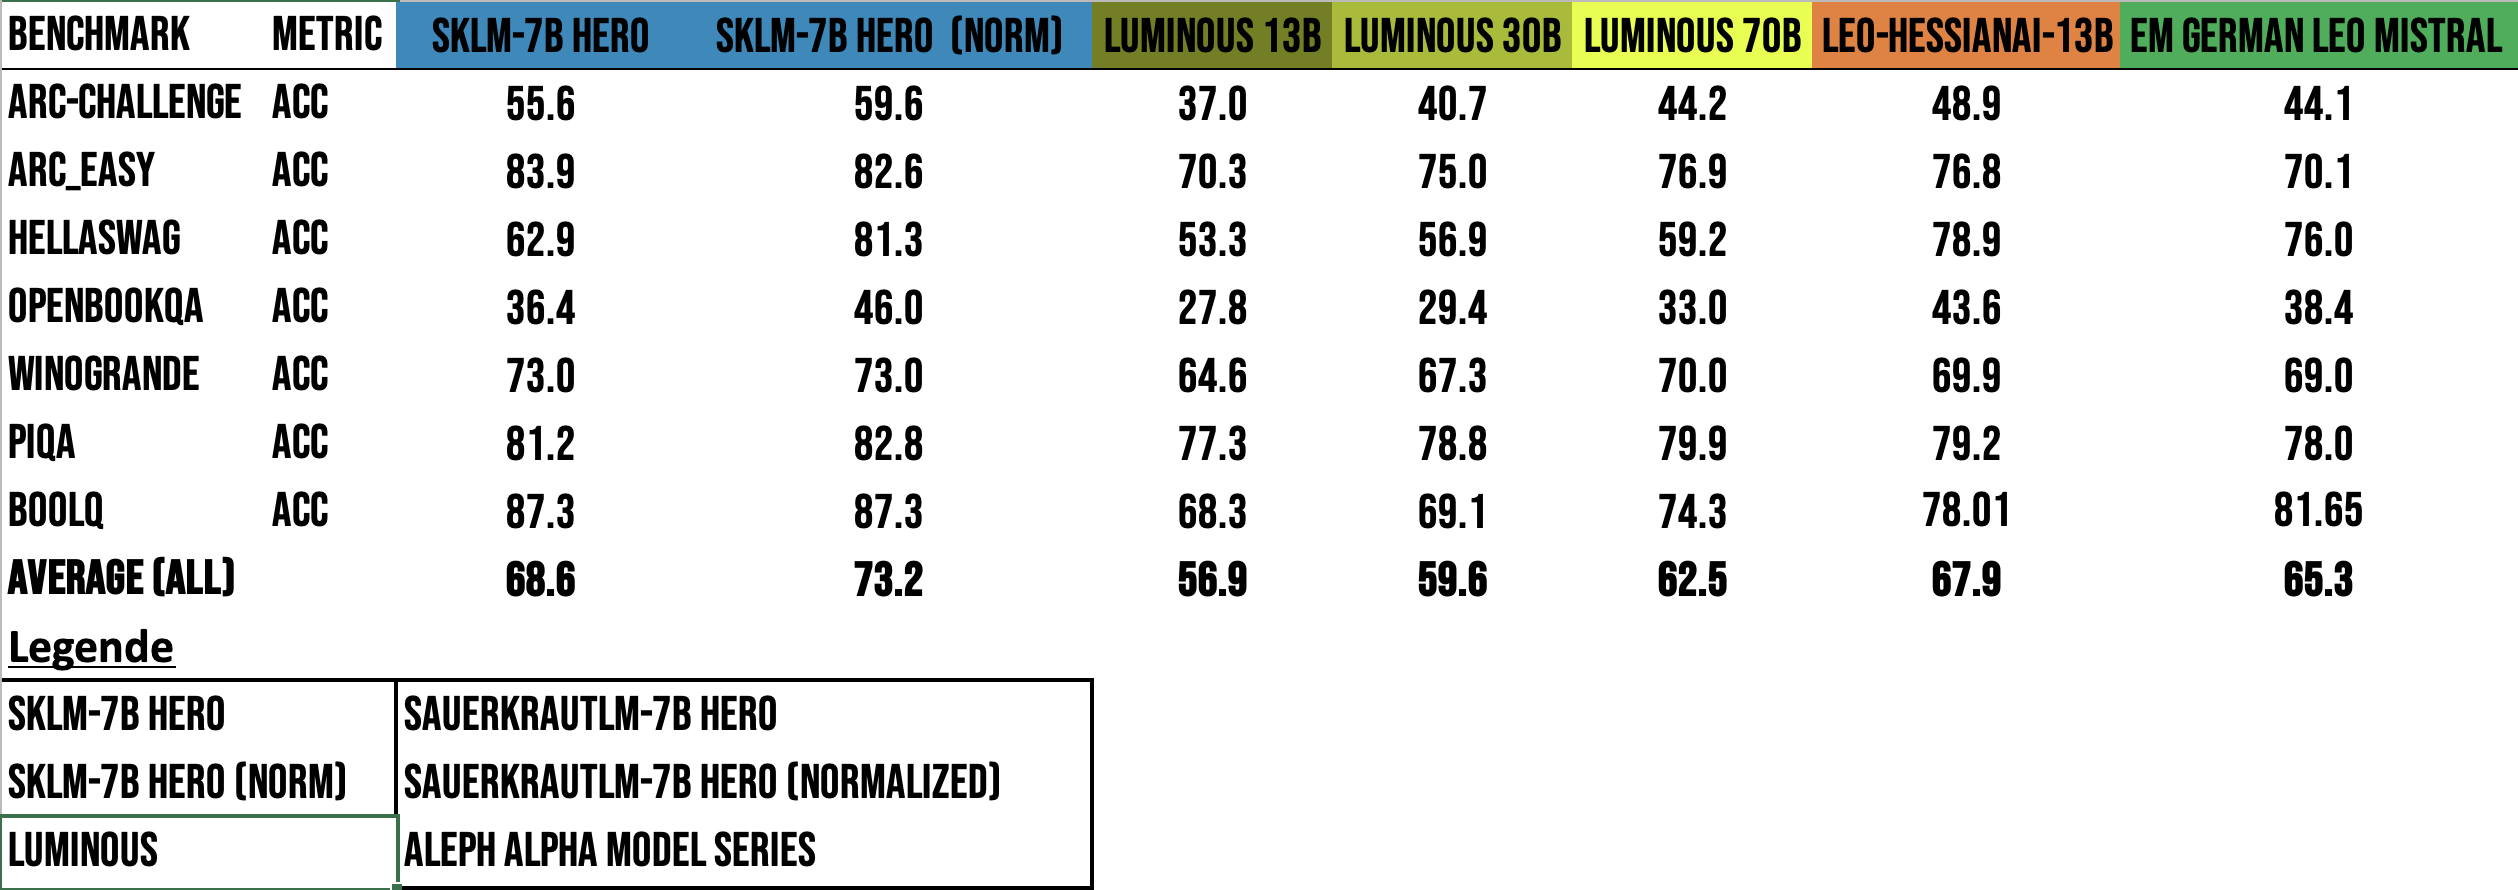
Compared to relevant German Closed and Open Source models
Compared to Aleph Alpha Luminous Models
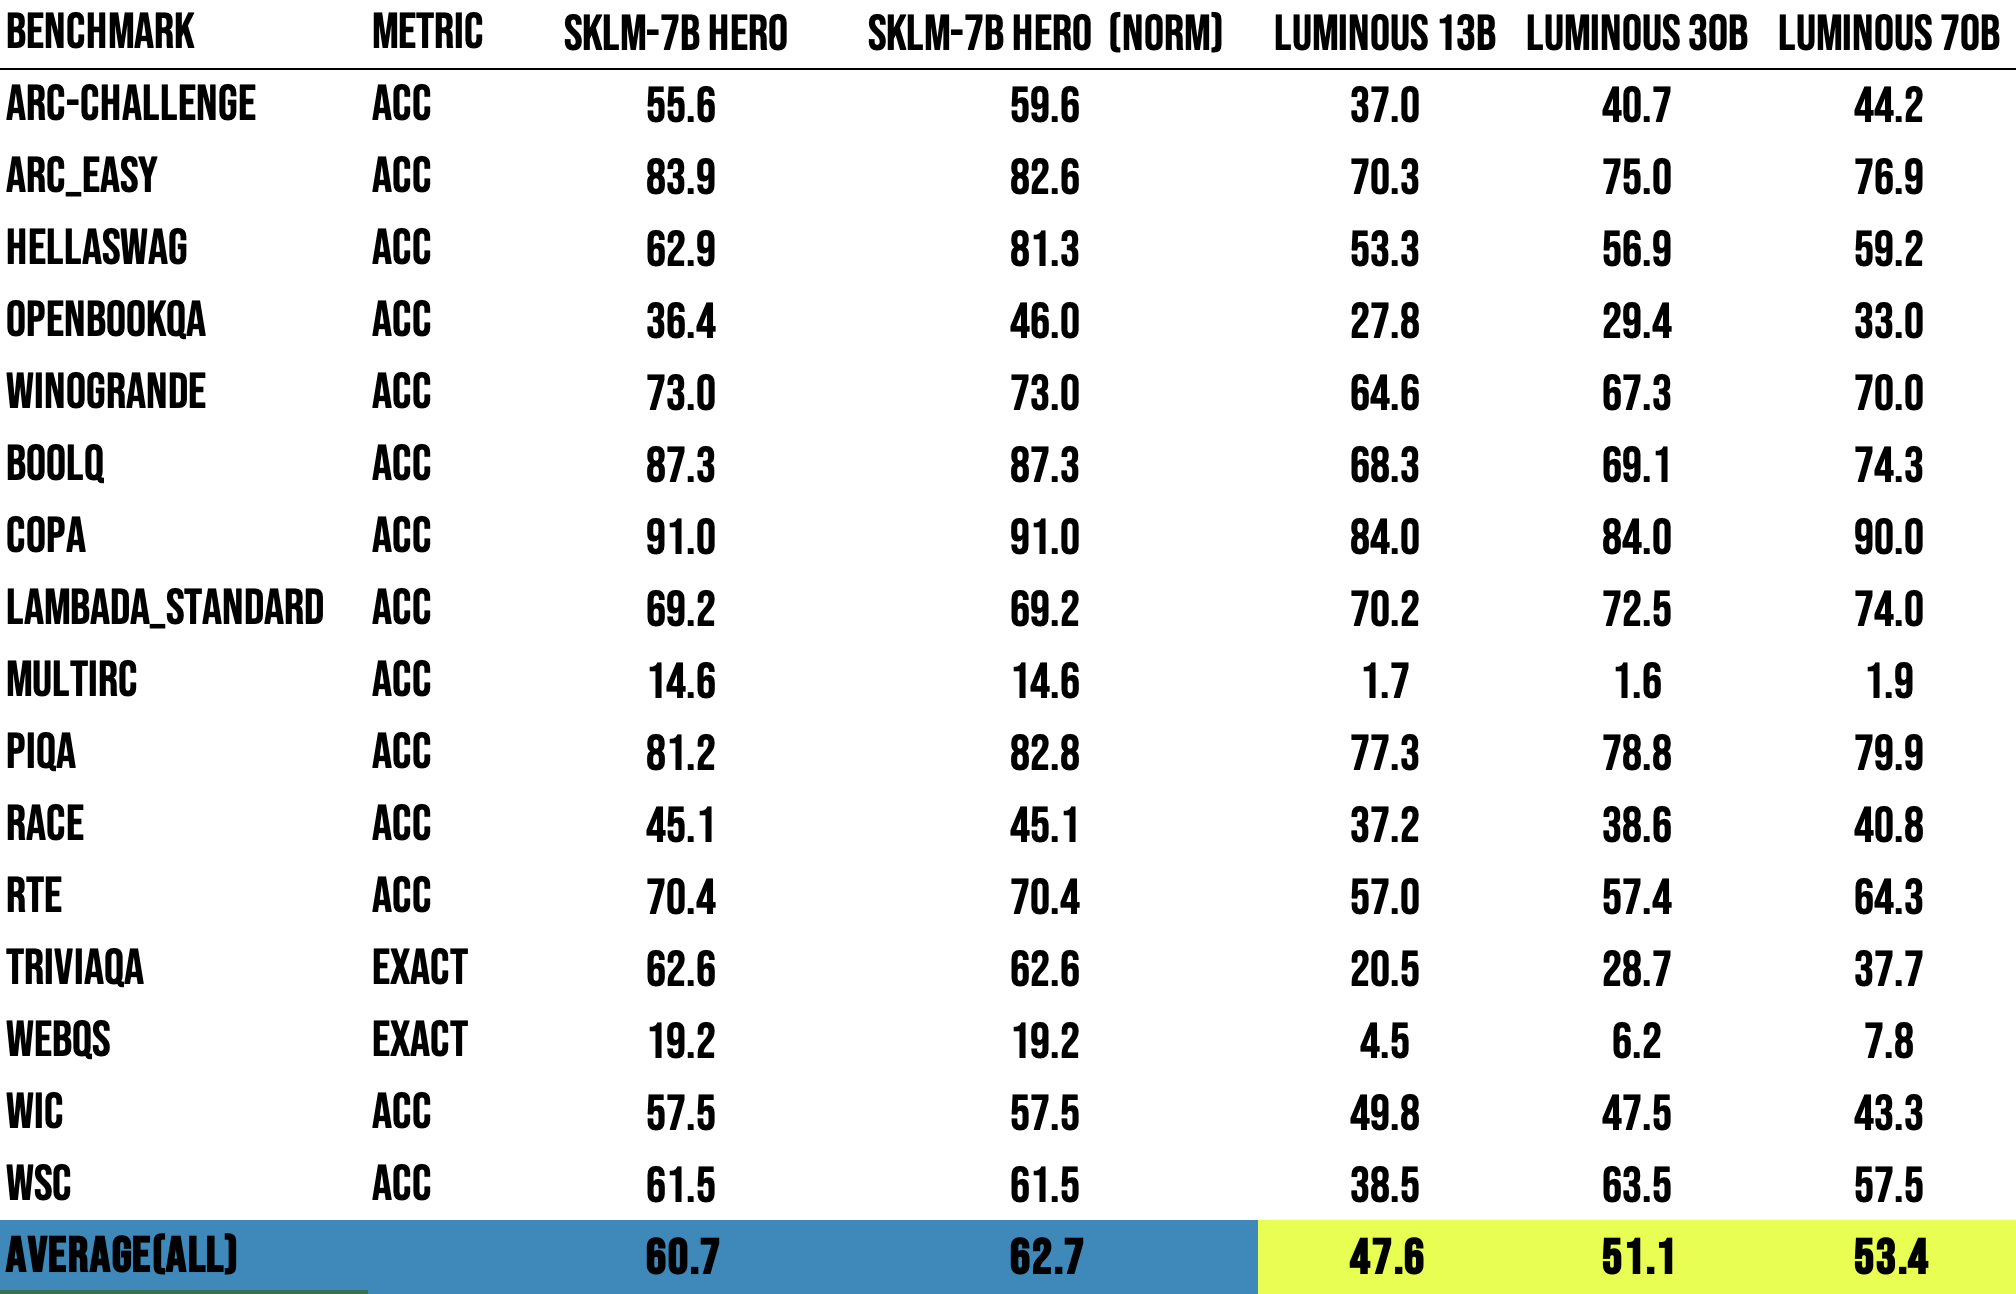
*performed with newest Language Model Evaluation Harness
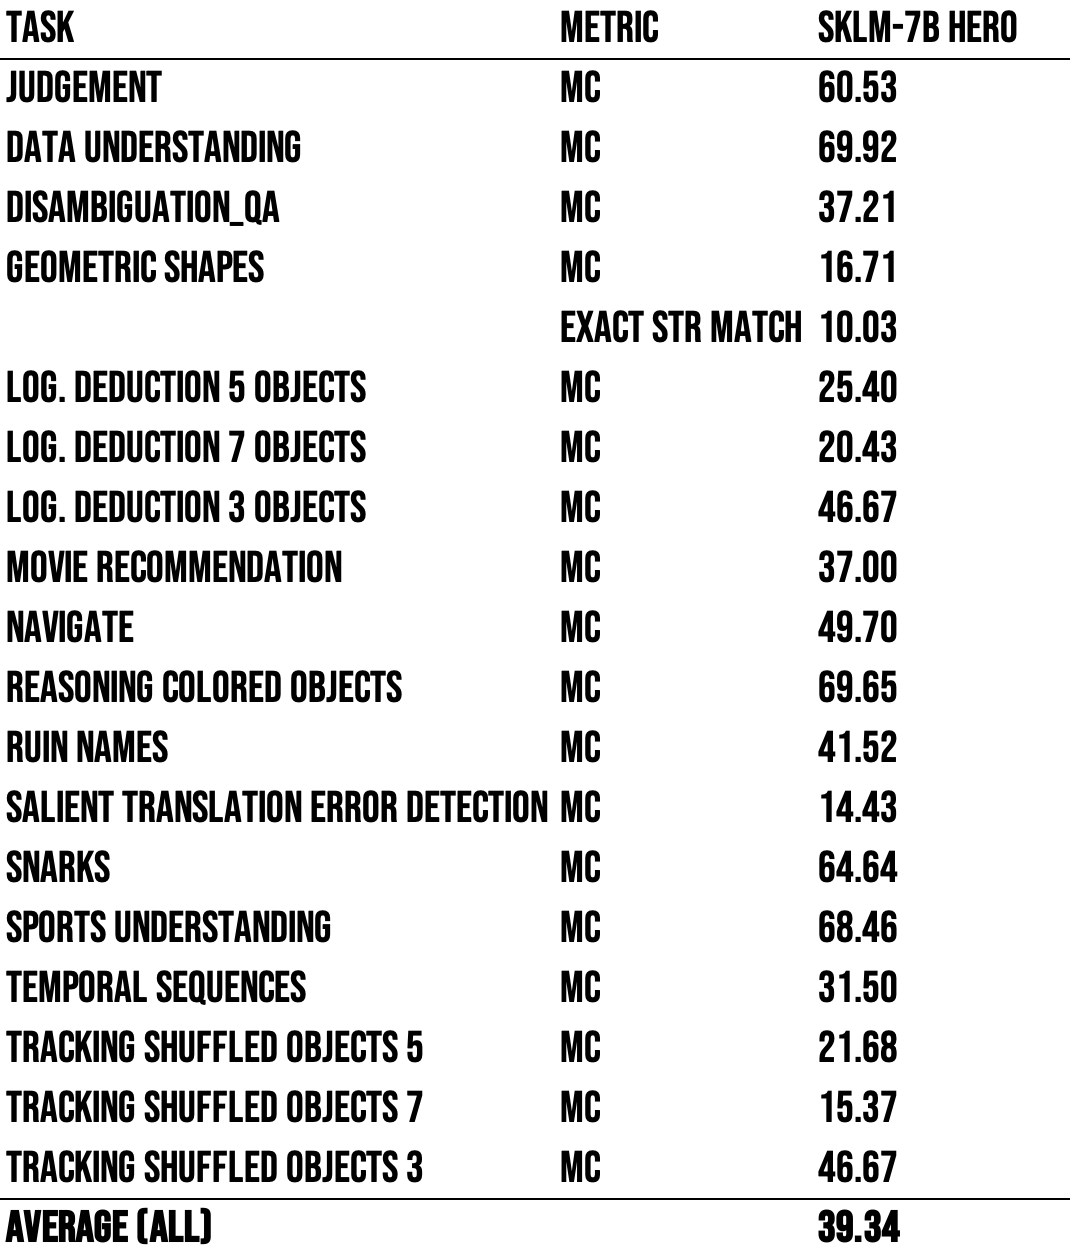 *performed with newest Language Model Evaluation Harness
Compared to Big Boy LLMs (Grok0,Grok1,GPT3.5,GPT4)
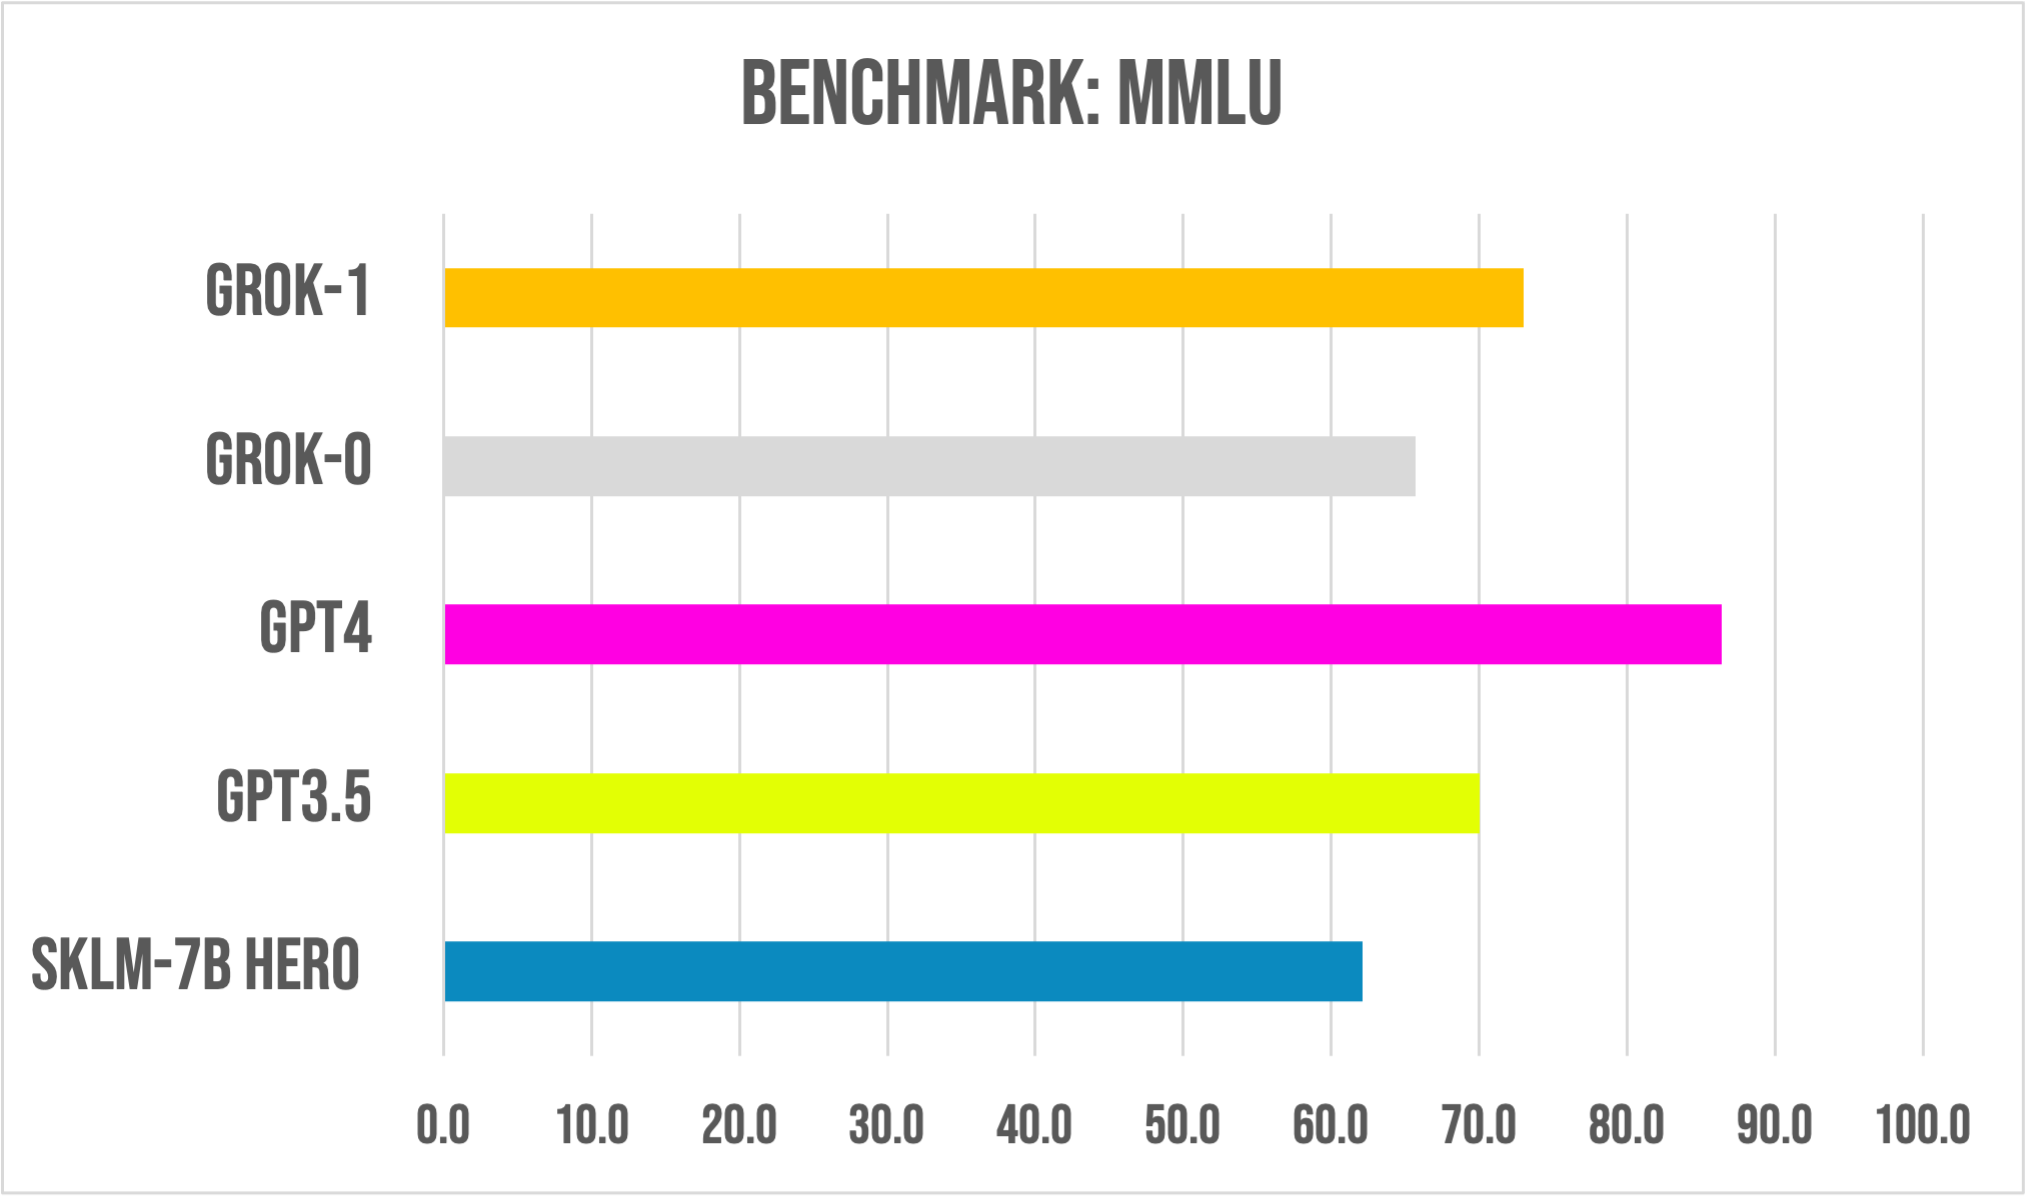
Compared to OpenAI Models (GPT3.5,GPT4)
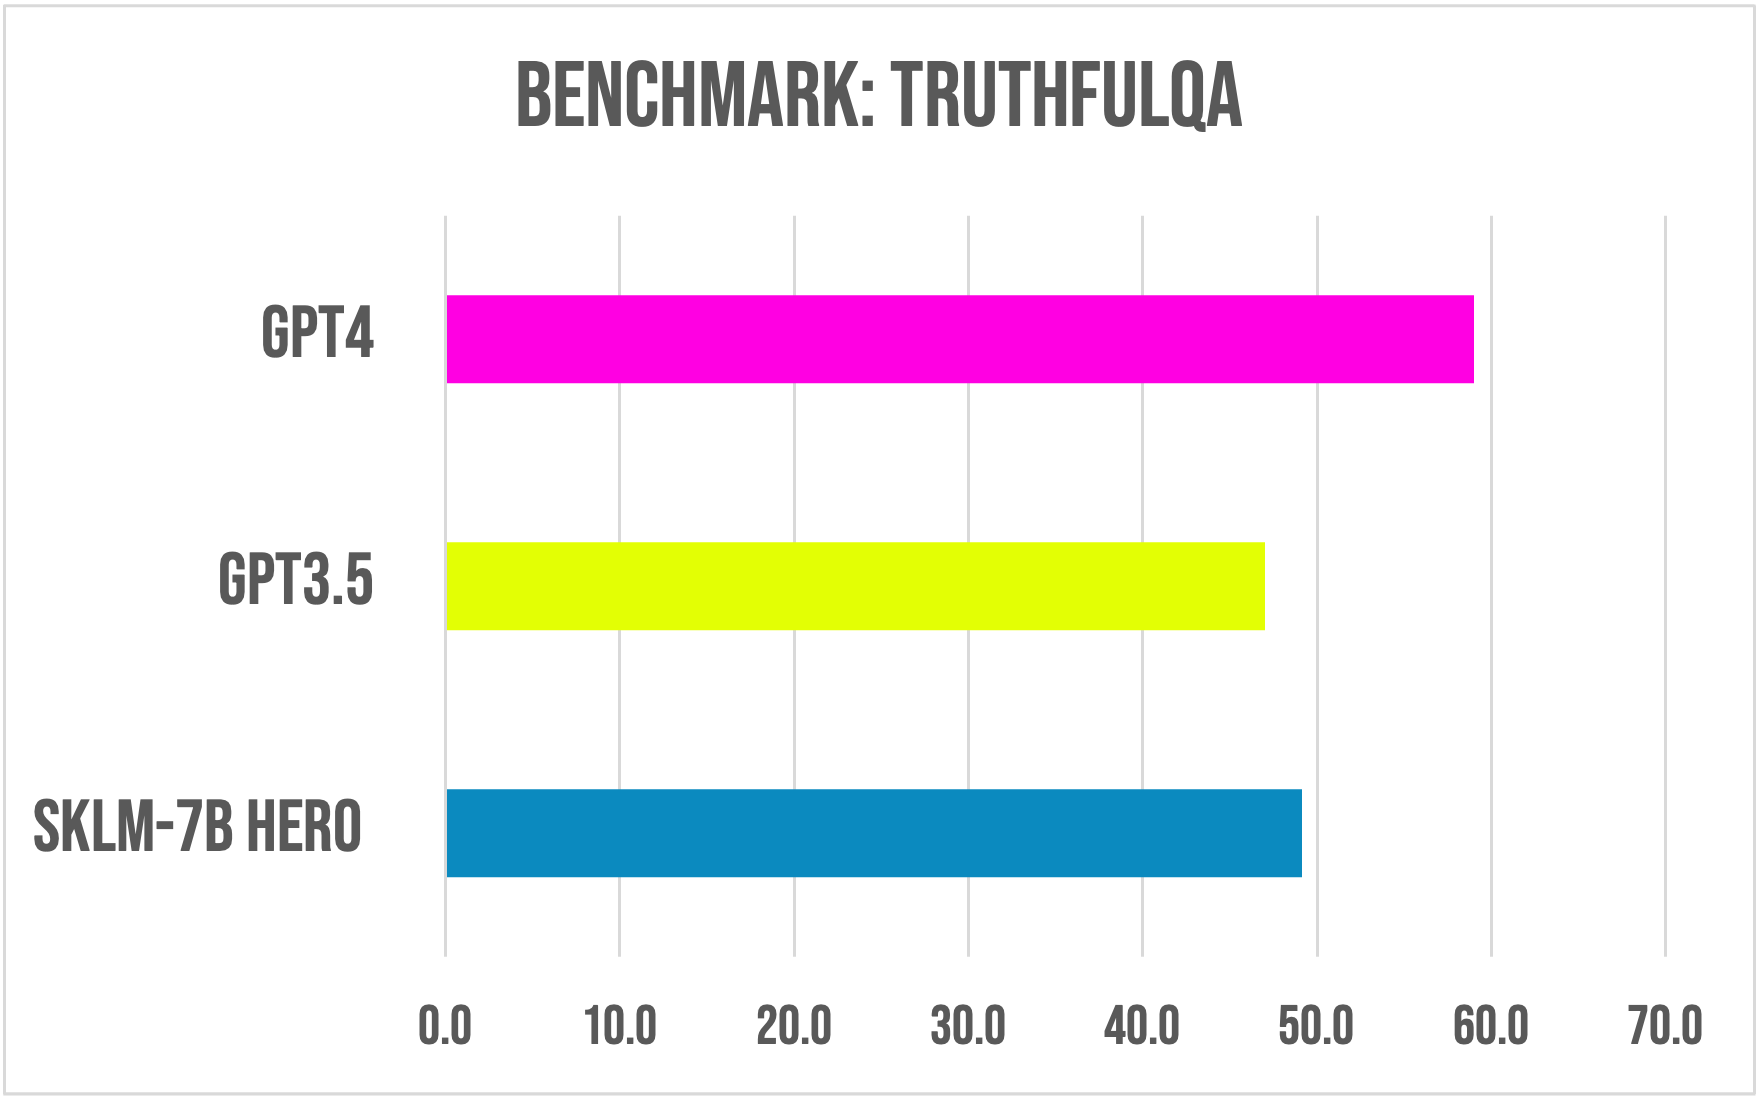
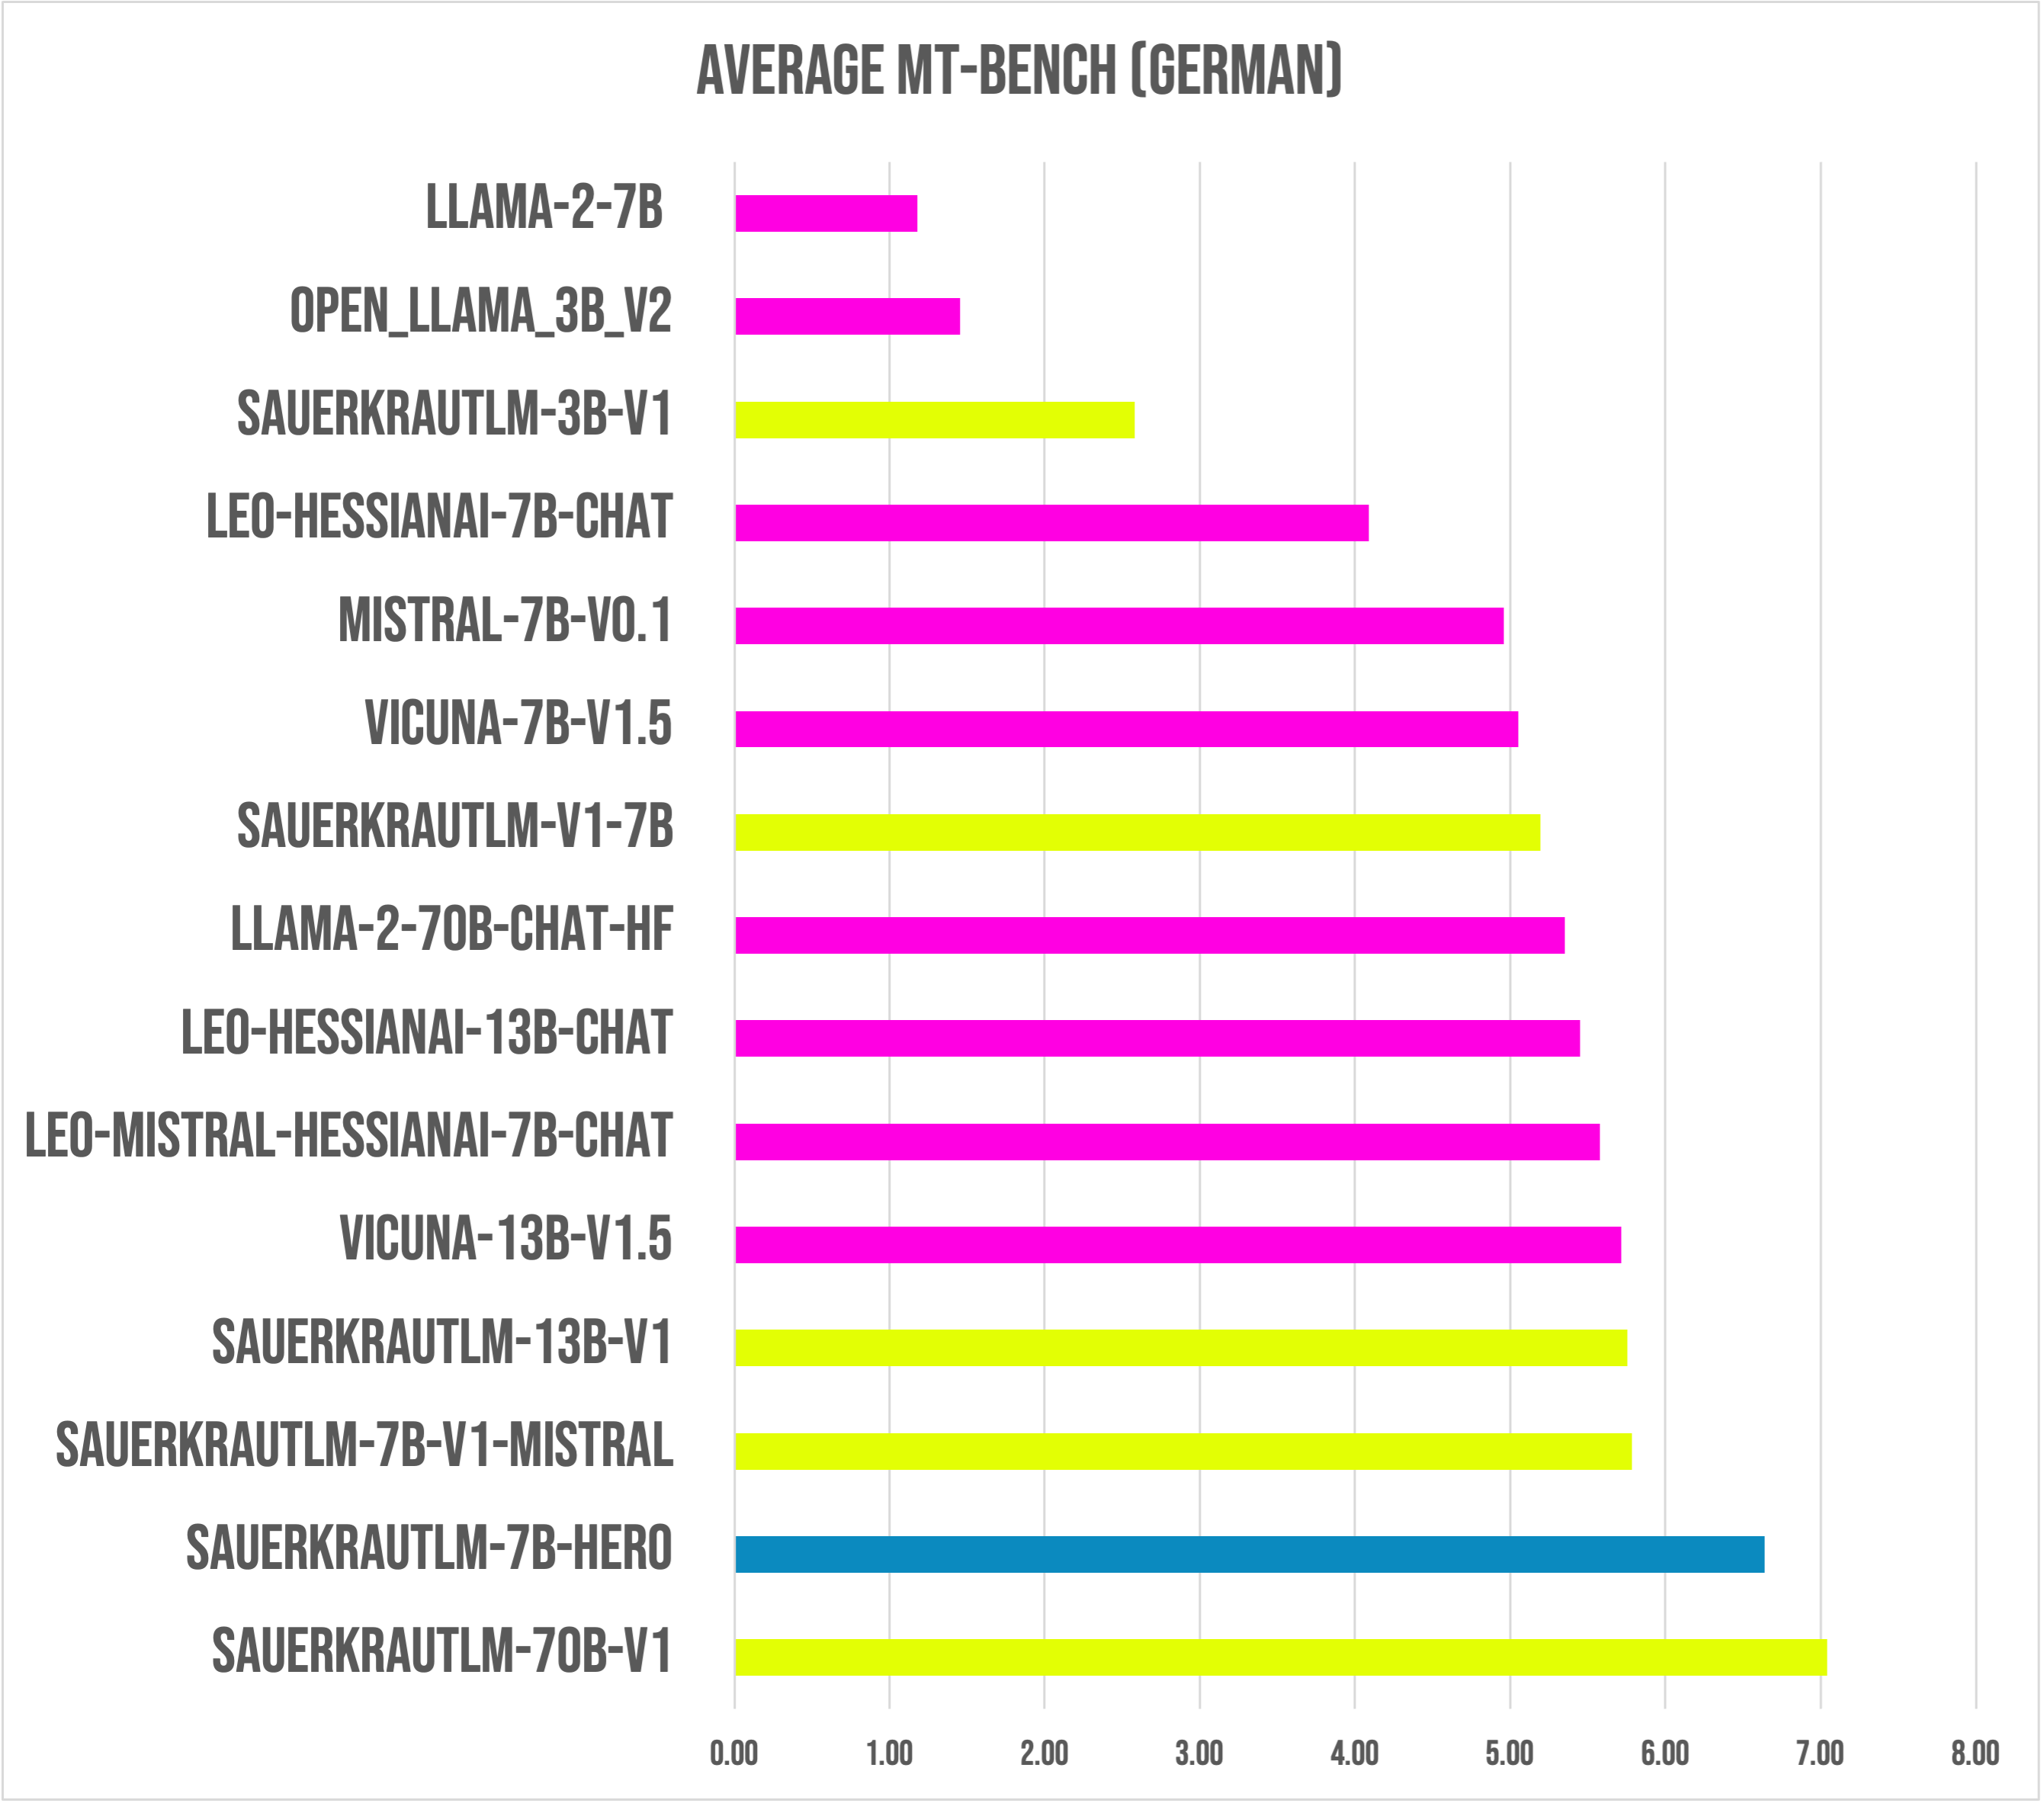
########## First turn ##########
                                                           score
model                                              turn
SauerkrautLM-70b-v1                                1     7.25000
SauerkrautLM-7b-HerO  <---                         1     6.96875
SauerkrautLM-7b-v1-mistral                         1     6.30625
leo-hessianai-13b-chat                             1     6.18750
SauerkrautLM-13b-v1                                1     6.16250
leo-mistral-hessianai-7b-chat                      1     6.15625
Llama-2-70b-chat-hf                                1     6.03750
vicuna-13b-v1.5                                    1     5.80000
SauerkrautLM-7b-v1                                 1     5.65000
leo-hessianai-7b-chat                              1     5.52500
vicuna-7b-v1.5                                     1     5.42500
Mistral-7B-v0.1                                    1     5.37500
SauerkrautLM-3b-v1                                 1     3.17500
Llama-2-7b                                         1     1.28750
open_llama_3b_v2                                   1     1.68750

########## Second turn ##########
                                                           score
model                                              turn
SauerkrautLM-70b-v1                                2     6.83125
SauerkrautLM-7b-HerO  <---                         2     6.30625
vicuna-13b-v1.5                                    2     5.63125
SauerkrautLM-13b-v1                                2     5.34375
SauerkrautLM-7b-v1-mistral                         2     5.26250
leo-mistral-hessianai-7b-chat                      2     4.99375
SauerkrautLM-7b-v1                                 2     4.73750
leo-hessianai-13b-chat                             2     4.71250
vicuna-7b-v1.5                                     2     4.67500
Llama-2-70b-chat-hf                                2     4.66250
Mistral-7B-v0.1                                    2     4.53750
leo-hessianai-7b-chat                              2     2.65000
SauerkrautLM-3b-v1                                 2     1.98750
open_llama_3b_v2                                   2     1.22500
Llama-2-7b                                         2     1.07500

########## Average ##########
                                                       score
model
SauerkrautLM-70b-v1                                 7.040625
SauerkrautLM-7b-HerO   <---                         6.637500
SauerkrautLM-7b-v1-mistral                          5.784375
SauerkrautLM-13b-v1                                 5.753125
vicuna-13b-v1.5                                     5.715625
leo-mistral-hessianai-7b-chat                       5.575000
leo-hessianai-13b-chat                              5.450000
Llama-2-70b-chat-hf                                 5.350000
SauerkrautLM-v1-7b                                  5.193750
vicuna-7b-v1.5                                      5.050000
Mistral-7B-v0.1                                     4.956250
leo-hessianai-7b-chat                               4.087500
SauerkrautLM-3b-v1                                  2.581250
open_llama_3b_v2                                    1.456250
Llama-2-7b                                          1.181250
*performed with the newest FastChat Version
########## First turn ##########
                                                           score
model                                              turn
OpenHermes-2.5-Mistral-7B                          1     8.21875
SauerkrautLM-7b-HerO    <---                       1     8.03125
Mistral-7B-OpenOrca                                1     7.65625
neural-chat-7b-v3-1                                1     7.22500

########## Second turn ##########
                                                          score
model                                              turn
OpenHermes-2.5-Mistral-7B                          2     7.1000
SauerkrautLM-7b-HerO  <---                         2     6.7875
neural-chat-7b-v3-1                                2     6.4000
Mistral-7B-OpenOrca                                2     6.1750

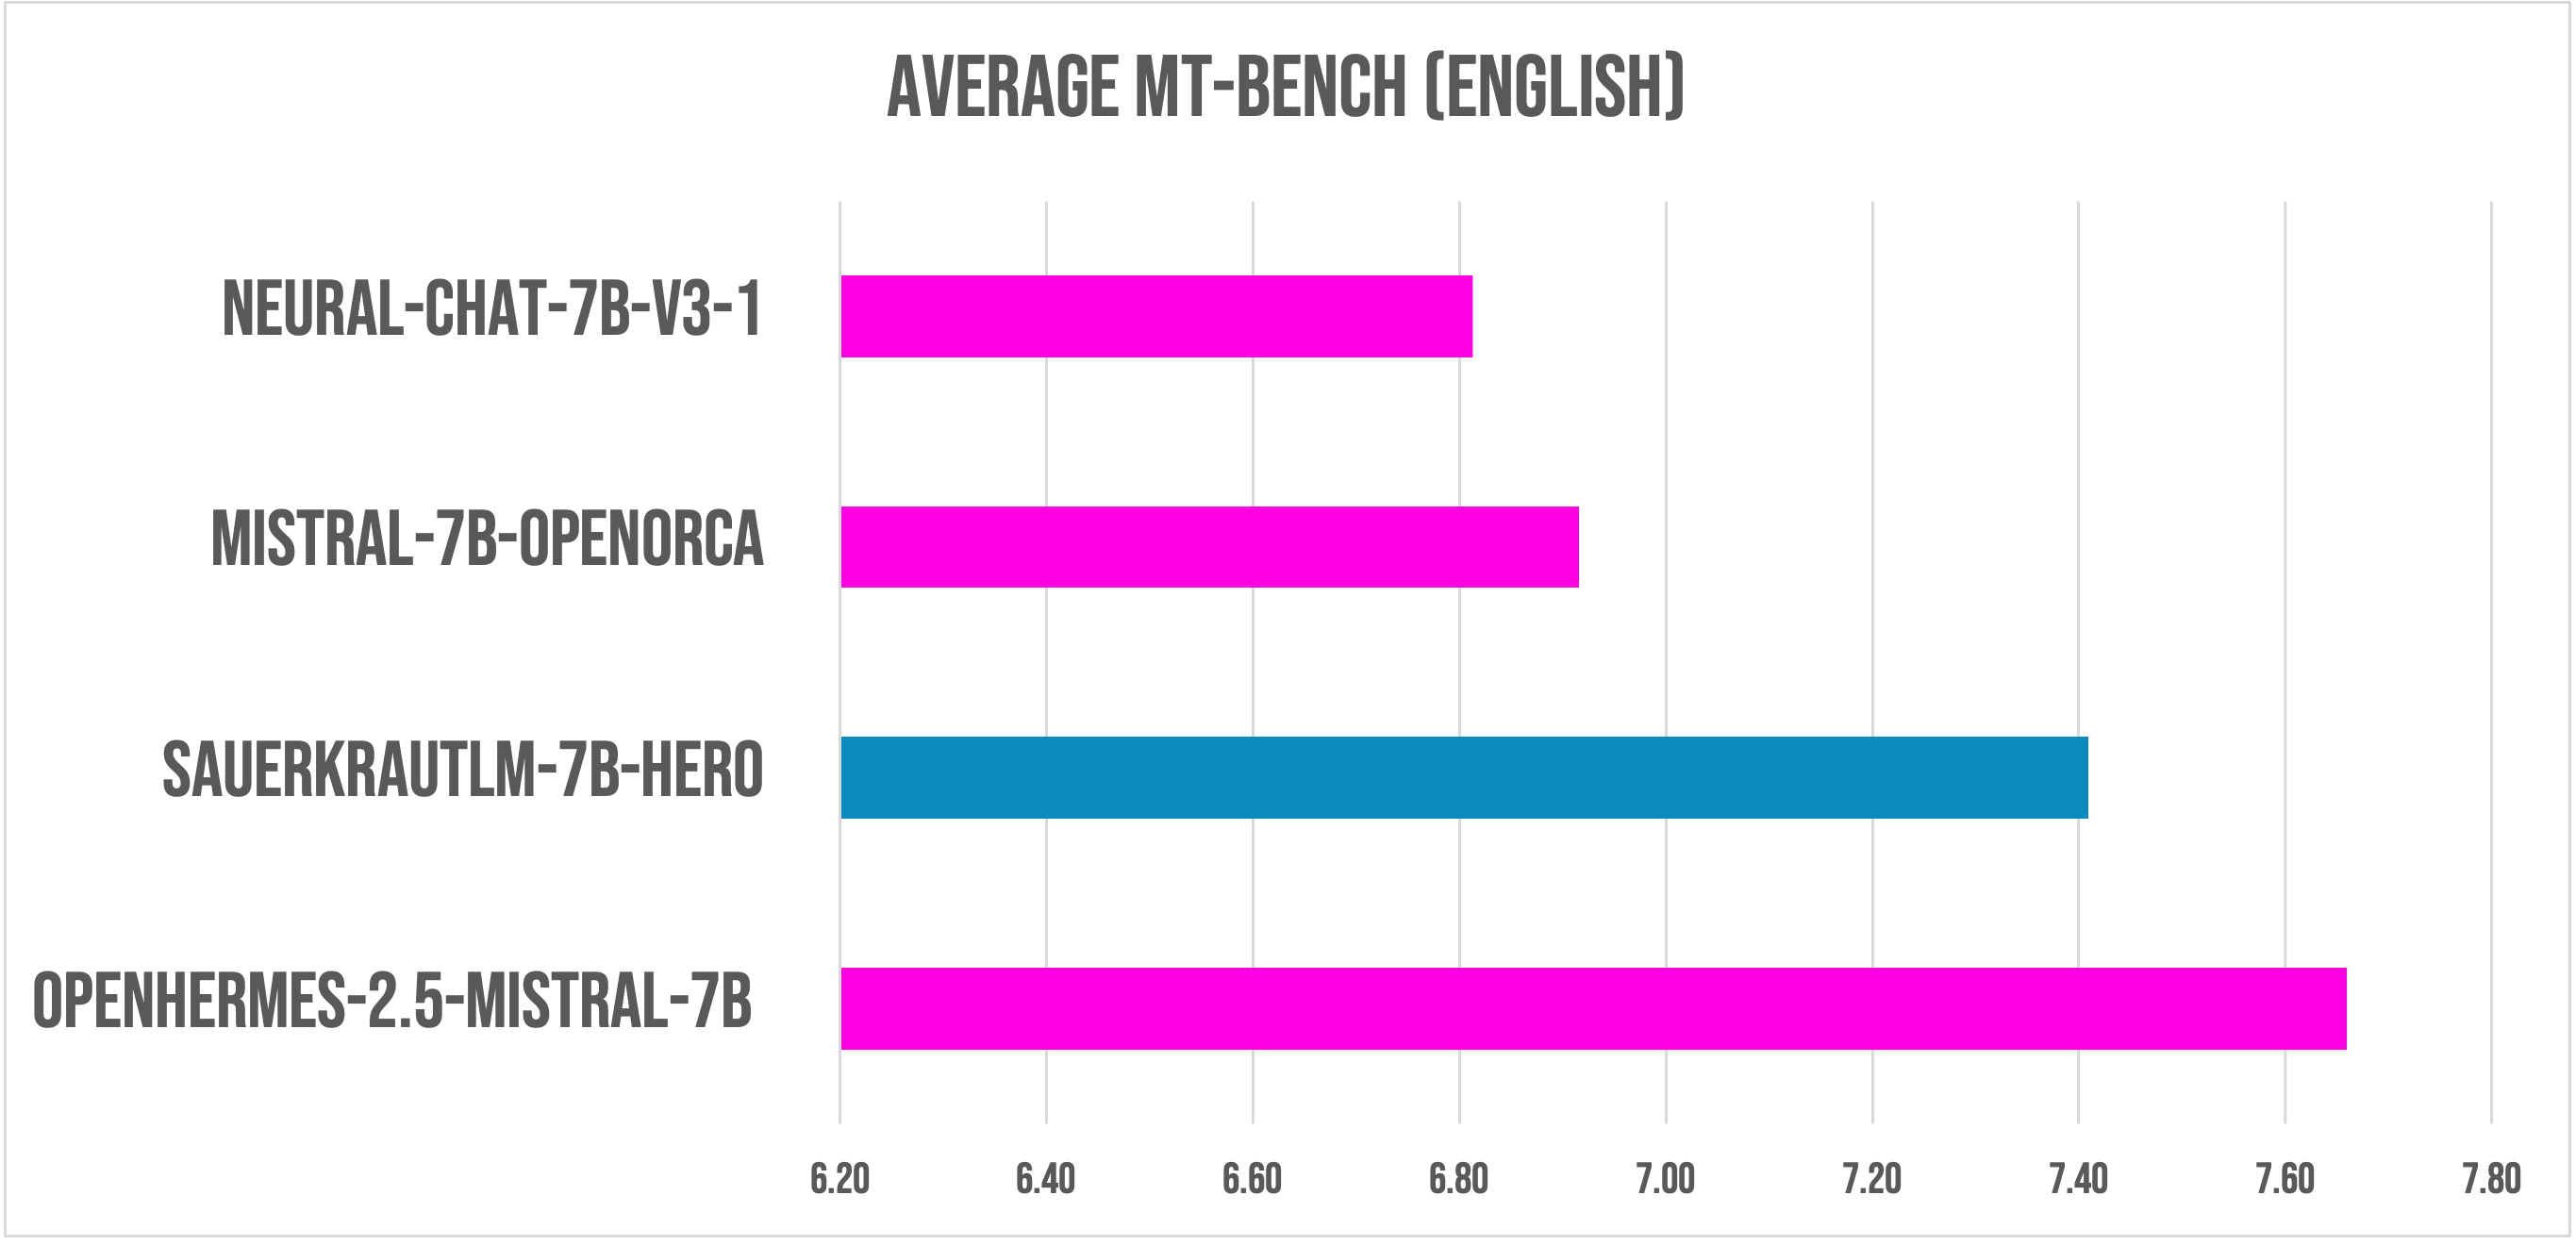
########## Average ##########
                                                       score
model
OpenHermes-2.5-Mistral-7B                           7.659375
SauerkrautLM-7b-HerO  <---                          7.409375
Mistral-7B-OpenOrca                                 6.915625
neural-chat-7b-v3-1                                 6.812500
*performed with the newest FastChat Version
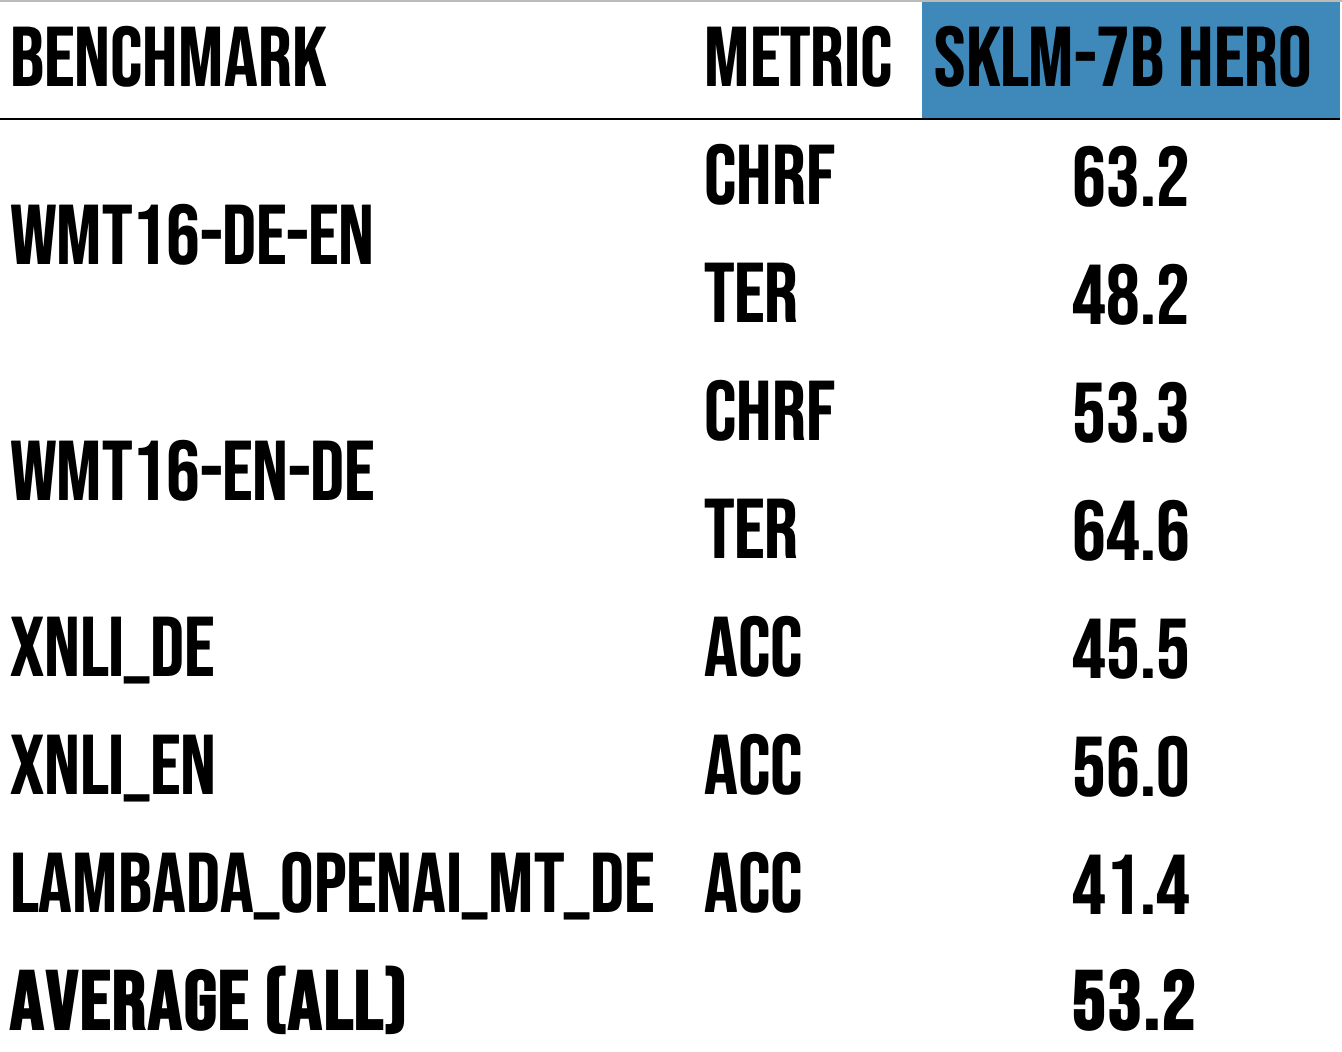 *performed with newest Language Model Evaluation Harness
We must inform users that despite our best efforts in data cleansing, the possibility of uncensored content slipping through cannot be entirely ruled out. However, we cannot guarantee consistently appropriate behavior. Therefore, if you encounter any issues or come across inappropriate content, we kindly request that you inform us through the contact information provided. Additionally, it is essential to understand that the licensing of these models does not constitute legal advice. We are not held responsible for the actions of third parties who utilize our models. These models may be employed for commercial purposes, and the Apache 2.0 remains applicable and is included with the model files.
If you are interested in customized LLMs for business applications, please get in contact with us via our website or contact us at Dr. Daryoush Vaziri. We are also grateful for your feedback and suggestions.
We are also keenly seeking support and investment for our startup, VAGO solutions, where we continuously advance the development of robust language models designed to address a diverse range of purposes and requirements. If the prospect of collaboratively navigating future challenges excites you, we warmly invite you to reach out to us.
Many thanks to OpenOrca and teknium for providing such valuable models to the Open-Source community.