
Downloads · 30 days
0
TheBloke/OpenOrca-Preview1-13B-GGML
OpenOrca-Preview1-13B-GGML is a text generation model from TheBloke. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
<div style="width: 100%;" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="display: flex; justify-content: space-betwee…
Downloads · 30 days
0
Access
Public
Updated Jul 12, 2023
Repo size
117 GB
Likes
15
Public
Click a slice to open those files.
.bin117 GB · 100%
From the Hugging Face model README
These files are GGML format model files for Open-Orca's OpenOrca-Preview1-13B.
GGML files are for CPU + GPU inference using llama.cpp and libraries and UIs which support this format, such as:
These files were quantised using hardware kindly provided by Latitude.sh.
Below is an instruction that describes a task. Write a response that appropriately completes the request.

### Instruction: {prompt}

### Response:
q4_0, q4_1, q5_0, q5_1, q8_0These are guaranteed to be compatible with any UIs, tools and libraries released since late May. They may be phased out soon, as they are largely superseded by the new k-quant methods.
q2_K, q3_K_S, q3_K_M, q3_K_L, q4_K_S, q4_K_M, q5_K_S, q6_KThese new quantisation methods are compatible with llama.cpp as of June 6th, commit 2d43387.
They are now also compatible with recent releases of text-generation-webui, KoboldCpp, llama-cpp-python, ctransformers, rustformers and most others. For compatibility with other tools and libraries, please check their documentation.
The new methods available are:
Refer to the Provided Files table below to see what files use which methods, and how.
</details> <!-- compatibility_ggml end -->| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| openorca-preview1-200k-llama-13b.ggmlv3.q2_K.bin | q2_K | 2 | 5.51 GB | 8.01 GB | New k-quant method. Uses GGML_TYPE_Q4_K for the attention.vw and feed_forward.w2 tensors, GGML_TYPE_Q2_K for the other tensors. |
| openorca-preview1-200k-llama-13b.ggmlv3.q3_K_L.bin | q3_K_L | 3 | 6.93 GB | 9.43 GB | New k-quant method. Uses GGML_TYPE_Q5_K for the attention.wv, attention.wo, and feed_forward.w2 tensors, else GGML_TYPE_Q3_K |
| openorca-preview1-200k-llama-13b.ggmlv3.q3_K_M.bin | q3_K_M | 3 | 6.31 GB | 8.81 GB | New k-quant method. Uses GGML_TYPE_Q4_K for the attention.wv, attention.wo, and feed_forward.w2 tensors, else GGML_TYPE_Q3_K |
| openorca-preview1-200k-llama-13b.ggmlv3.q3_K_S.bin | q3_K_S | 3 | 5.66 GB | 8.16 GB | New k-quant method. Uses GGML_TYPE_Q3_K for all tensors |
| openorca-preview1-200k-llama-13b.ggmlv3.q4_0.bin | q4_0 | 4 | 7.32 GB | 9.82 GB | Original quant method, 4-bit. |
| openorca-preview1-200k-llama-13b.ggmlv3.q4_1.bin | q4_1 | 4 | 8.14 GB | 10.64 GB | Original quant method, 4-bit. Higher accuracy than q4_0 but not as high as q5_0. However has quicker inference than q5 models. |
| openorca-preview1-200k-llama-13b.ggmlv3.q4_K_M.bin | q4_K_M | 4 | 7.87 GB | 10.37 GB | New k-quant method. Uses GGML_TYPE_Q6_K for half of the attention.wv and feed_forward.w2 tensors, else GGML_TYPE_Q4_K |
| openorca-preview1-200k-llama-13b.ggmlv3.q4_K_S.bin | q4_K_S | 4 | 7.37 GB | 9.87 GB | New k-quant method. Uses GGML_TYPE_Q4_K for all tensors |
| openorca-preview1-200k-llama-13b.ggmlv3.q5_0.bin | q5_0 | 5 | 8.95 GB | 11.45 GB | Original quant method, 5-bit. Higher accuracy, higher resource usage and slower inference. |
| openorca-preview1-200k-llama-13b.ggmlv3.q5_1.bin | q5_1 | 5 | 9.76 GB | 12.26 GB | Original quant method, 5-bit. Even higher accuracy, resource usage and slower inference. |
| openorca-preview1-200k-llama-13b.ggmlv3.q5_K_M.bin | q5_K_M | 5 | 9.23 GB | 11.73 GB | New k-quant method. Uses GGML_TYPE_Q6_K for half of the attention.wv and feed_forward.w2 tensors, else GGML_TYPE_Q5_K |
| openorca-preview1-200k-llama-13b.ggmlv3.q5_K_S.bin | q5_K_S | 5 | 8.97 GB | 11.47 GB | New k-quant method. Uses GGML_TYPE_Q5_K for all tensors |
| openorca-preview1-200k-llama-13b.ggmlv3.q6_K.bin | q6_K | 6 | 10.68 GB | 13.18 GB | New k-quant method. Uses GGML_TYPE_Q8_K for all tensors - 6-bit quantization |
| openorca-preview1-200k-llama-13b.ggmlv3.q8_0.bin | q8_0 | 8 | 13.83 GB | 16.33 GB | Original quant method, 8-bit. Almost indistinguishable from float16. High resource use and slow. Not recommended for most users. |
Note: the above RAM figures assume no GPU offloading. If layers are offloaded to the GPU, this will reduce RAM usage and use VRAM instead.
llama.cppI use the following command line; adjust for your tastes and needs:
./main -t 10 -ngl 32 -m openorca-preview1-200k-llama-13b.ggmlv3.q4_0.bin --color -c 2048 --temp 0.7 --repeat_penalty 1.1 -n -1 -p "### Instruction: Write a story about llamas\n### Response:"
Change -t 10 to the number of physical CPU cores you have. For example if your system has 8 cores/16 threads, use -t 8.
Change -ngl 32 to the number of layers to offload to GPU. Remove it if you don't have GPU acceleration.
If you want to have a chat-style conversation, replace the -p <PROMPT> argument with -i -ins
text-generation-webuiFurther instructions here: text-generation-webui/docs/llama.cpp-models.md.
<!-- footer start -->For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Luke from CarbonQuill, Aemon Algiz.
Patreon special mentions: Space Cruiser, Nikolai Manek, Sam, Chris McCloskey, Rishabh Srivastava, Kalila, Spiking Neurons AB, Khalefa Al-Ahmad, WelcomeToTheClub, Chadd, Lone Striker, Viktor Bowallius, Edmond Seymore, Ai Maven, Chris Smitley, Dave, Alexandros Triantafyllidis, Luke @flexchar, Elle, ya boyyy, Talal Aujan, Alex , Jonathan Leane, Deep Realms, Randy H, subjectnull, Preetika Verma, Joseph William Delisle, Michael Levine, chris gileta, K, Oscar Rangel, LangChain4j, Trenton Dambrowitz, Eugene Pentland, Johann-Peter Hartmann, Femi Adebogun, Illia Dulskyi, senxiiz, Daniel P. Andersen, Sean Connelly, Artur Olbinski, RoA, Mano Prime, Derek Yates, Raven Klaugh, David Flickinger, Willem Michiel, Pieter, Willian Hasse, vamX, Luke Pendergrass, webtim, Ghost , Rainer Wilmers, Nathan LeClaire, Will Dee, Cory Kujawski, John Detwiler, Fred von Graf, biorpg, Iucharbius , Imad Khwaja, Pierre Kircher, terasurfer , Asp the Wyvern, John Villwock, theTransient, zynix , Gabriel Tamborski, Fen Risland, Gabriel Puliatti, Matthew Berman, Pyrater, SuperWojo, Stephen Murray, Karl Bernard, Ajan Kanaga, Greatston Gnanesh, Junyu Yang.
Thank you to all my generous patrons and donaters!
<!-- footer end -->We have used our own OpenOrca dataset to fine-tune LLaMA-13B. This dataset is our attempt to reproduce the dataset generated for Microsoft Research's Orca Paper.
We have trained on less than 6% of our data, just to give a preview of what is possible while we further refine our dataset! We trained a refined selection of 200k GPT-4 entries from OpenOrca. We have filtered our GPT-4 augmentations to remove statements like, "As an AI language model..." and other responses which have been shown to harm model reasoning capabilities. Further details on our dataset curation practices will be forthcoming with our full model releases.
This release highlights that even a small portion of our training data can produce state of the art results in this model class with training costs <$200 in total.
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
We will also give sneak-peak announcements on our Discord, which you can find here:
We have evaluated OpenOrca_Preview1-200k-GPT4_LLaMA-13B on hard reasoning tasks from BigBench-Hard and AGIEval as outlined in the Orca paper.
Our average performance for BigBench-Hard: 0.3753
Average for AGIEval: 0.3638
In the Orca paper, they measured their score relative to Vicuna on these evals. We've done the same and have found our score averages to ~60% of the total improvement that was shown in the Orca paper.
So we got 60% of the improvement with 6% of the data!
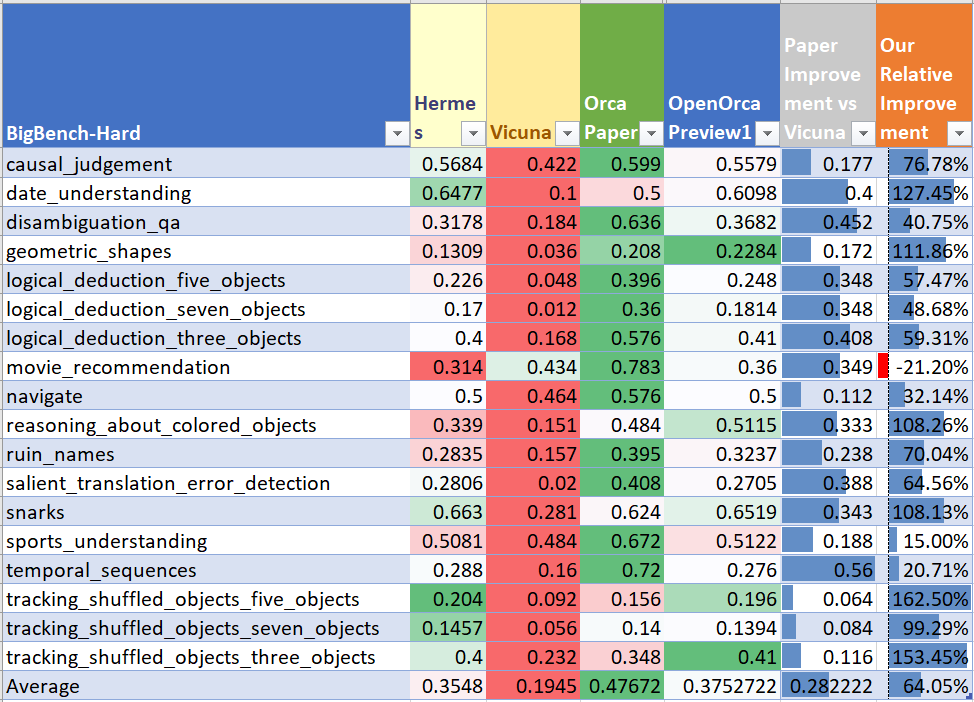
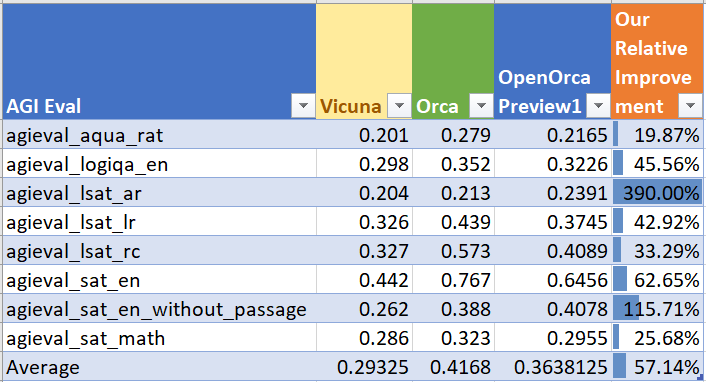
We will report our results on HuggingFaceH4 Open LLM Leaderboard Evals once we receive them.
We used a small (6%, 200k) subset of our data from OpenOrca, which aims to reproduce the Orca Research Paper dataset.
As this release is intended as a preview, please await our full releases for further details on the training data.
We trained with 8x A100-80G GPUs for 15 hours. Commodity cost was < $200.
We trained for 4 epochs and selected a snapshot at 3 epochs for peak performance.
Please await our full releases for further training details.
@software{OpenOrca_Preview1,
  title = {OpenOrca_Preview1: A LLaMA-13B Model Fine-tuned on Small Portion of OpenOrcaV1 Dataset},
  author = {Wing Lian and Bleys Goodson and Eugene Pentland and Austin Cook and "NanoBit" and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://https://huggingface.co/Open-Orca/OpenOrca_Preview1-200k-GPT4_LLaMA-13B},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
@software{touvron2023llama,
  title={LLaMA: Open and Efficient Foundation Language Models},
  author={Touvron, Hugo and Lavril, Thibaut and Izacard, Gautier and Martinet, Xavier and Lachaux, Marie-Anne and Lacroix, Timoth{\'e}e and Rozi{\`e}re, Baptiste and Goyal, Naman and Hambro, Eric and Azhar, Faisal and Rodriguez, Aurelien and Joulin, Armand and Grave, Edouard and Lample, Guillaume},
  journal={arXiv preprint arXiv:2302.13971},
  year={2023}
}