
Downloads · 30 days
34
7% of all-time downloads
TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ
Mistral-ClaudeLimaRP-v3-7B-AWQ is a text generation model from TheBloke. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
<div style="width: auto; margin-left: auto; margin-right: auto" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="displa…
Downloads · 30 days
34
7% of all-time downloads
All-time downloads
456
Public
Parameters
7.2B
4.2 GB on disk
Likes
4
Public
Click a slice to open those files.
.safetensors4.2 GB · 100%
How the weights are stored.
I327B · 96%
From the Hugging Face model README
This repo contains AWQ model files for Undi's Mistral ClaudeLimaRP v3 7B.
These files were quantised using hardware kindly provided by Massed Compute.
AWQ is an efficient, accurate and blazing-fast low-bit weight quantization method, currently supporting 4-bit quantization. Compared to GPTQ, it offers faster Transformers-based inference with equivalent or better quality compared to the most commonly used GPTQ settings.
It is supported by:
### Instruction:
Character's Persona: bot character description

User's persona: user character description

Scenario: what happens in the story

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User. Character should respond with messages of medium length.

### Input:
User: {prompt}

### Response:
Character:
For my first release of AWQ models, I am releasing 128g models only. I will consider adding 32g as well if there is interest, and once I have done perplexity and evaluation comparisons, but at this time 32g models are still not fully tested with AutoAWQ and vLLM.
Models are released as sharded safetensors files.
<!-- README_AWQ.md-provided-files end --> <!-- README_AWQ.md-text-generation-webui start -->Please make sure you're using the latest version of text-generation-webui.
It is strongly recommended to use the text-generation-webui one-click-installers unless you're sure you know how to make a manual install.
TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ.Mistral-ClaudeLimaRP-v3-7B-AWQDocumentation on installing and using vLLM can be found here.
--quantization awq parameter.For example:
python3 python -m vllm.entrypoints.api_server --model TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ --quantization awq
quantization=awq.For example:
from vllm import LLM, SamplingParams

prompts = [
    "Tell me about AI",
    "Write a story about llamas",
    "What is 291 - 150?",
    "How much wood would a woodchuck chuck if a woodchuck could chuck wood?",
]
prompt_template=f'''### Instruction:
Character's Persona: bot character description

User's persona: user character description

Scenario: what happens in the story

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User. Character should respond with messages of medium length.

### Input:
User: {prompt}

### Response:
Character:
'''

prompts = [prompt_template.format(prompt=prompt) for prompt in prompts]

sampling_params = SamplingParams(temperature=0.8, top_p=0.95)

llm = LLM(model="TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ", quantization="awq", dtype="auto")

outputs = llm.generate(prompts, sampling_params)

# Print the outputs.
for output in outputs:
    prompt = output.prompt
    generated_text = output.outputs[0].text
    print(f"Prompt: {prompt!r}, Generated text: {generated_text!r}")
Use TGI version 1.1.0 or later. The official Docker container is: ghcr.io/huggingface/text-generation-inference:1.1.0
Example Docker parameters:
--model-id TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ --port 3000 --quantize awq --max-input-length 3696 --max-total-tokens 4096 --max-batch-prefill-tokens 4096
Example Python code for interfacing with TGI (requires huggingface-hub 0.17.0 or later):
pip3 install huggingface-hub
from huggingface_hub import InferenceClient

endpoint_url = "https://your-endpoint-url-here"

prompt = "Tell me about AI"
prompt_template=f'''### Instruction:
Character's Persona: bot character description

User's persona: user character description

Scenario: what happens in the story

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User. Character should respond with messages of medium length.

### Input:
User: {prompt}

### Response:
Character:
'''

client = InferenceClient(endpoint_url)
response = client.text_generation(prompt,
                                  max_new_tokens=128,
                                  do_sample=True,
                                  temperature=0.7,
                                  top_p=0.95,
                                  top_k=40,
                                  repetition_penalty=1.1)

print(f"Model output: ", response)
Requires: AutoAWQ 0.1.1 or later.
pip3 install autoawq
If you have problems installing AutoAWQ using the pre-built wheels, install it from source instead:
pip3 uninstall -y autoawq
git clone https://github.com/casper-hansen/AutoAWQ
cd AutoAWQ
pip3 install .
from awq import AutoAWQForCausalLM
from transformers import AutoTokenizer

model_name_or_path = "TheBloke/Mistral-ClaudeLimaRP-v3-7B-AWQ"

# Load tokenizer
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, trust_remote_code=False)
# Load model
model = AutoAWQForCausalLM.from_quantized(model_name_or_path, fuse_layers=True,
                                          trust_remote_code=False, safetensors=True)

prompt = "Tell me about AI"
prompt_template=f'''### Instruction:
Character's Persona: bot character description

User's persona: user character description

Scenario: what happens in the story

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User. Character should respond with messages of medium length.

### Input:
User: {prompt}

### Response:
Character:
'''

print("*** Running model.generate:")

token_input = tokenizer(
    prompt_template,
    return_tensors='pt'
).input_ids.cuda()

# Generate output
generation_output = model.generate(
    token_input,
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=40,
    max_new_tokens=512
)

# Get the tokens from the output, decode them, print them
token_output = generation_output[0]
text_output = tokenizer.decode(token_output)
print("LLM output: ", text_output)

"""
# Inference should be possible with transformers pipeline as well in future
# But currently this is not yet supported by AutoAWQ (correct as of September 25th 2023)
from transformers import pipeline

print("*** Pipeline:")
pipe = pipeline(
    "text-generation",
    model=model,
    tokenizer=tokenizer,
    max_new_tokens=512,
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=40,
    repetition_penalty=1.1
)

print(pipe(prompt_template)[0]['generated_text'])
"""
The files provided are tested to work with:
Loader: AutoAWQ.For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
Thanks to Clay from gpus.llm-utils.org!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Aemon Algiz.
Patreon special mentions: Brandon Frisco, LangChain4j, Spiking Neurons AB, transmissions 11, Joseph William Delisle, Nitin Borwankar, Willem Michiel, Michael Dempsey, vamX, Jeffrey Morgan, zynix, jjj, Omer Bin Jawed, Sean Connelly, jinyuan sun, Jeromy Smith, Shadi, Pawan Osman, Chadd, Elijah Stavena, Illia Dulskyi, Sebastain Graf, Stephen Murray, terasurfer, Edmond Seymore, Celu Ramasamy, Mandus, Alex, biorpg, Ajan Kanaga, Clay Pascal, Raven Klaugh, 阿明, K, ya boyyy, usrbinkat, Alicia Loh, John Villwock, ReadyPlayerEmma, Chris Smitley, Cap'n Zoog, fincy, GodLy, S_X, sidney chen, Cory Kujawski, OG, Mano Prime, AzureBlack, Pieter, Kalila, Spencer Kim, Tom X Nguyen, Stanislav Ovsiannikov, Michael Levine, Andrey, Trailburnt, Vadim, Enrico Ros, Talal Aujan, Brandon Phillips, Jack West, Eugene Pentland, Michael Davis, Will Dee, webtim, Jonathan Leane, Alps Aficionado, Rooh Singh, Tiffany J. Kim, theTransient, Luke @flexchar, Elle, Caitlyn Gatomon, Ari Malik, subjectnull, Johann-Peter Hartmann, Trenton Dambrowitz, Imad Khwaja, Asp the Wyvern, Emad Mostaque, Rainer Wilmers, Alexandros Triantafyllidis, Nicholas, Pedro Madruga, SuperWojo, Harry Royden McLaughlin, James Bentley, Olakabola, David Ziegler, Ai Maven, Jeff Scroggin, Nikolai Manek, Deo Leter, Matthew Berman, Fen Risland, Ken Nordquist, Manuel Alberto Morcote, Luke Pendergrass, TL, Fred von Graf, Randy H, Dan Guido, NimbleBox.ai, Vitor Caleffi, Gabriel Tamborski, knownsqashed, Lone Striker, Erik Bjäreholt, John Detwiler, Leonard Tan, Iucharbius
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
<!-- footer end -->This repo contains fp16 files of Norquinal/Mistral-7B-claude-chat with the LoRA lemonilia/LimaRP-Mistral-7B-v0.1 applied at weight "0.75".
All credit go to lemonilia and Norquinal
Same as before. It uses the extended Alpaca format,
with ### Input: immediately preceding user inputs and ### Response: immediately preceding
model outputs. While Alpaca wasn't originally intended for multi-turn responses, in practice this
is not a problem; the format follows a pattern already used by other models.
### Instruction:
Character's Persona: {bot character description}

User's Persona: {user character description}

Scenario: {what happens in the story}

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User.

### Input:
User: {utterance}

### Response:
Character: {utterance}

### Input
User: {utterance}

### Response:
Character: {utterance}

(etc.)
You should:
User and Character with appropriate names.Inspired by the previously named "Roleplay" preset in SillyTavern, with this version of LimaRP it is possible to append a length modifier to the response instruction sequence, like this:
### Input
User: {utterance}

### Response: (length = medium)
Character: {utterance}
This has an immediately noticeable effect on bot responses. The available lengths are:
tiny, short, medium, long, huge, humongous, extreme, unlimited. The
recommended starting length is medium. Keep in mind that the AI may ramble
or impersonate the user with very long messages.
The length control effect is reproducible, but the messages will not necessarily follow lengths very precisely, rather follow certain ranges on average, as seen in this table with data from tests made with one reply at the beginning of the conversation:
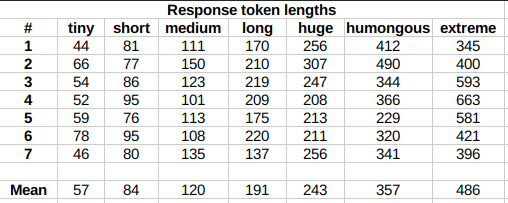
Response length control appears to work well also deep into the conversation.
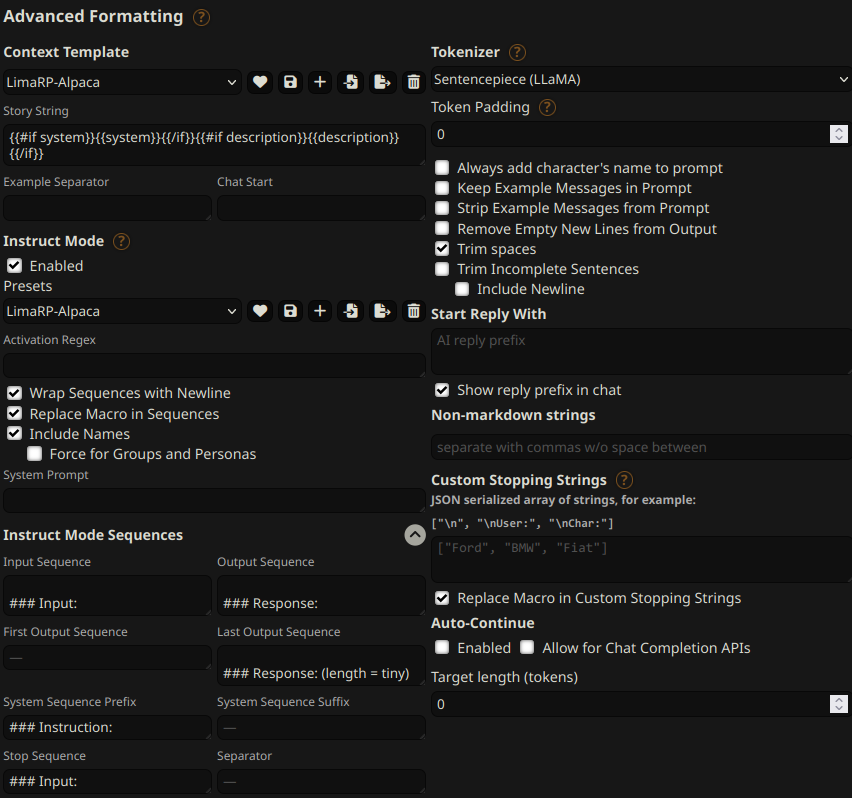
You can follow these instruction format settings in SillyTavern. Replace tiny with
your desired response length:
Extensive testing with Mistral has not been performed yet, but suggested starting text generation settings may be:
If you want to support me, you can here.