
Downloads · 30 days
31
1% of all-time downloads
TheBloke/LlongOrca-13B-16K-GPTQ
LlongOrca-13B-16K-GPTQ is a text generation model from TheBloke. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama2.
<div style="width: auto; margin-left: auto; margin-right: auto" <img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;" </div <div style="displa…
Downloads · 30 days
31
1% of all-time downloads
All-time downloads
3.9K
Public
Parameters
13B
57 GB on disk
Likes
5
Public
Click a slice to open those files.
.safetensors7.3 GB · 100%
How the weights are stored.
I3212.7B · 97%
From the Hugging Face model README
This repo contains GPTQ model files for Open-Orca's LlongOrca 13B 16K.
Multiple GPTQ parameter permutations are provided; see Provided Files below for details of the options provided, their parameters, and the software used to create them.
<!-- description end --> <!-- repositories-available start --><|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant
The creator of the source model has listed its license as llama2, and this quantization has therefore used that same license.
As this model is based on Llama 2, it is also subject to the Meta Llama 2 license terms, and the license files for that are additionally included. It should therefore be considered as being claimed to be licensed under both licenses. I contacted Hugging Face for clarification on dual licensing but they do not yet have an official position. Should this change, or should Meta provide any feedback on this situation, I will update this section accordingly.
In the meantime, any questions regarding licensing, and in particular how these two licenses might interact, should be directed to the original model repository: Open-Orca's LlongOrca 13B 16K.
<!-- licensing end --> <!-- README_GPTQ.md-provided-files start -->Multiple quantisation parameters are provided, to allow you to choose the best one for your hardware and requirements.
Each separate quant is in a different branch. See below for instructions on fetching from different branches.
All recent GPTQ files are made with AutoGPTQ, and all files in non-main branches are made with AutoGPTQ. Files in the main branch which were uploaded before August 2023 were made with GPTQ-for-LLaMa.
desc_act. True results in better quantisation accuracy. Some GPTQ clients have had issues with models that use Act Order plus Group Size, but this is generally resolved now.| Branch | Bits | GS | Act Order | Damp % | GPTQ Dataset | Seq Len | Size | ExLlama | Desc |
|---|---|---|---|---|---|---|---|---|---|
| main | 4 | 128 | No | 0.1 | wikitext | 8192 | 7.26 GB | Yes | 4-bit, without Act Order and group size 128g. |
| gptq-4bit-32g-actorder_True | 4 | 32 | Yes | 0.1 | wikitext | 8192 | 8.00 GB | Yes | 4-bit, with Act Order and group size 32g. Gives highest possible inference quality, with maximum VRAM usage. |
| gptq-4bit-64g-actorder_True | 4 | 64 | Yes | 0.1 | wikitext | 8192 | 7.51 GB | Yes | 4-bit, with Act Order and group size 64g. Uses less VRAM than 32g, but with slightly lower accuracy. |
| gptq-4bit-128g-actorder_True | 4 | 128 | Yes | 0.1 | wikitext | 8192 | 7.26 GB | Yes | 4-bit, with Act Order and group size 128g. Uses even less VRAM than 64g, but with slightly lower accuracy. |
| gptq-8bit--1g-actorder_True | 8 | None | Yes | 0.1 | wikitext | 8192 | 13.36 GB | No | 8-bit, with Act Order. No group size, to lower VRAM requirements. |
| gptq-8bit-128g-actorder_True | 8 | 128 | Yes | 0.1 | wikitext | 8192 | 13.65 GB | No | 8-bit, with group size 128g for higher inference quality and with Act Order for even higher accuracy. |
:branch to the end of the download name, eg TheBloke/LlongOrca-13B-16K-GPTQ:maingit clone --single-branch --branch main https://huggingface.co/TheBloke/LlongOrca-13B-16K-GPTQ
revision parameter; see below.Please make sure you're using the latest version of text-generation-webui.
It is strongly recommended to use the text-generation-webui one-click-installers unless you're sure you know how to make a manual install.
TheBloke/LlongOrca-13B-16K-GPTQ.TheBloke/LlongOrca-13B-16K-GPTQ:mainLlongOrca-13B-16K-GPTQquantize_config.json.Requires: Transformers 4.32.0 or later, Optimum 1.12.0 or later, and AutoGPTQ 0.4.2 or later.
pip3 install transformers>=4.32.0 optimum>=1.12.0
pip3 install auto-gptq --extra-index-url https://huggingface.github.io/autogptq-index/whl/cu118/  # Use cu117 if on CUDA 11.7
If you have problems installing AutoGPTQ using the pre-built wheels, install it from source instead:
pip3 uninstall -y auto-gptq
git clone https://github.com/PanQiWei/AutoGPTQ
cd AutoGPTQ
pip3 install .
If 4.33.0 is not yet released when you read this, you will need to install Transformers from source:
pip3 uninstall -y transformers
pip3 install git+https://github.com/huggingface/transformers.git
from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline

model_name_or_path = "TheBloke/LlongOrca-13B-16K-GPTQ"
# To use a different branch, change revision
# For example: revision="main"
model = AutoModelForCausalLM.from_pretrained(model_name_or_path,
                                             device_map="auto",
                                             trust_remote_code=False,
                                             revision="main")

tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, use_fast=True)

prompt = "Tell me about AI"
prompt_template=f'''<|im_start|>system
{system_message}<|im_end|>
<|im_start|>user
{prompt}<|im_end|>
<|im_start|>assistant

'''

print("\n\n*** Generate:")

input_ids = tokenizer(prompt_template, return_tensors='pt').input_ids.cuda()
output = model.generate(inputs=input_ids, temperature=0.7, do_sample=True, top_p=0.95, top_k=40, max_new_tokens=512)
print(tokenizer.decode(output[0]))

# Inference can also be done using transformers' pipeline

print("*** Pipeline:")
pipe = pipeline(
    "text-generation",
    model=model,
    tokenizer=tokenizer,
    max_new_tokens=512,
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=40,
    repetition_penalty=1.1
)

print(pipe(prompt_template)[0]['generated_text'])
The files provided are tested to work with AutoGPTQ, both via Transformers and using AutoGPTQ directly. They should also work with Occ4m's GPTQ-for-LLaMa fork.
ExLlama is compatible with Llama models in 4-bit. Please see the Provided Files table above for per-file compatibility.
Huggingface Text Generation Inference (TGI) is compatible with all GPTQ models.
<!-- README_GPTQ.md-compatibility end --> <!-- footer start --> <!-- 200823 -->For further support, and discussions on these models and AI in general, join us at:
Thanks to the chirper.ai team!
Thanks to Clay from gpus.llm-utils.org!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
Special thanks to: Aemon Algiz.
Patreon special mentions: Russ Johnson, J, alfie_i, Alex, NimbleBox.ai, Chadd, Mandus, Nikolai Manek, Ken Nordquist, ya boyyy, Illia Dulskyi, Viktor Bowallius, vamX, Iucharbius, zynix, Magnesian, Clay Pascal, Pierre Kircher, Enrico Ros, Tony Hughes, Elle, Andrey, knownsqashed, Deep Realms, Jerry Meng, Lone Striker, Derek Yates, Pyrater, Mesiah Bishop, James Bentley, Femi Adebogun, Brandon Frisco, SuperWojo, Alps Aficionado, Michael Dempsey, Vitor Caleffi, Will Dee, Edmond Seymore, usrbinkat, LangChain4j, Kacper Wikieł, Luke Pendergrass, John Detwiler, theTransient, Nathan LeClaire, Tiffany J. Kim, biorpg, Eugene Pentland, Stanislav Ovsiannikov, Fred von Graf, terasurfer, Kalila, Dan Guido, Nitin Borwankar, 阿明, Ai Maven, John Villwock, Gabriel Puliatti, Stephen Murray, Asp the Wyvern, danny, Chris Smitley, ReadyPlayerEmma, S_X, Daniel P. Andersen, Olakabola, Jeffrey Morgan, Imad Khwaja, Caitlyn Gatomon, webtim, Alicia Loh, Trenton Dambrowitz, Swaroop Kallakuri, Erik Bjäreholt, Leonard Tan, Spiking Neurons AB, Luke @flexchar, Ajan Kanaga, Thomas Belote, Deo Leter, RoA, Willem Michiel, transmissions 11, subjectnull, Matthew Berman, Joseph William Delisle, David Ziegler, Michael Davis, Johann-Peter Hartmann, Talal Aujan, senxiiz, Artur Olbinski, Rainer Wilmers, Spencer Kim, Fen Risland, Cap'n Zoog, Rishabh Srivastava, Michael Levine, Geoffrey Montalvo, Sean Connelly, Alexandros Triantafyllidis, Pieter, Gabriel Tamborski, Sam, Subspace Studios, Junyu Yang, Pedro Madruga, Vadim, Cory Kujawski, K, Raven Klaugh, Randy H, Mano Prime, Sebastain Graf, Space Cruiser
Thank you to all my generous patrons and donaters!
And thank you again to a16z for their generous grant.
<!-- footer end -->
We have used our own OpenOrca dataset to fine-tune on top of LLongMA-2-13b-16k. This dataset is our attempt to reproduce the dataset generated for Microsoft Research's Orca Paper. We use OpenChat packing, trained with Axolotl.
This release is trained on a curated filtered subset of most of our GPT-4 augmented data. It is the same subset of our data as was used in our OpenOrcaxOpenChat-Preview2-13B model.
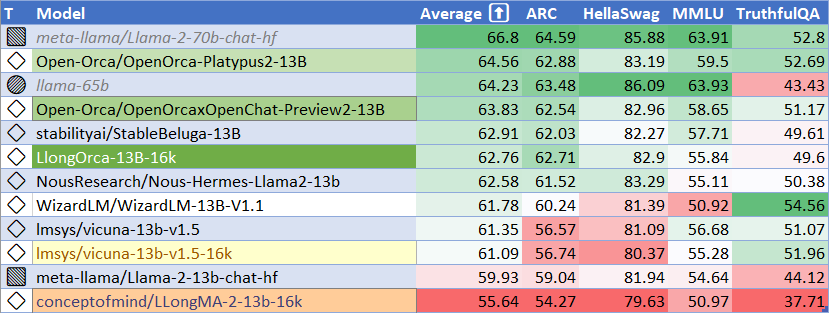
HF Leaderboard evals place this model as #1 for all 13B long context models at release time. We achieve >112% the performance of the base LLongMA2-13b-16k model we tuned on top of. As well, we preserve >98% of the performance of the OpenOrcaxOpenChat-Preview2-13B model we share datasets with, while extending the context to 16k.
We did this training as part of testing setup of our H100 cluster.
Want to visualize our full (pre-filtering) dataset? Check out our Nomic Atlas Map.
Many thanks to @EnricoShippole, @theemozilla, and @kaiokendev1 for the fine work on creating the LlongMA-2-13b-16k model this was trained on top of!
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
We will also give sneak-peak announcements on our Discord, which you can find here:
We used OpenAI's Chat Markup Language (ChatML) format, with <|im_start|> and <|im_end|> tokens added to support this.
<|im_start|>system
You are LlongOrca, a large language model trained by Alignment Lab AI. Write out your reasoning step-by-step to be sure you get the right answers!
<|im_end|>
<|im_start|>user
How are you<|im_end|>
<|im_start|>assistant
I am doing well!<|im_end|>
<|im_start|>user
How are you now?<|im_end|>
We have evaluated using the methodology and tools for the HuggingFace Leaderboard, and find that we have significantly improved upon the base long context model. We reach >112% of LLongMA2-13B-16k performance.
We have run our own tests using parameters matching the HuggingFaceH4 Open LLM Leaderboard evals.
We preserve >98% of OpenOrcaxOpenChat-Preview2-13B performance and are #1 on the leaderboard for long context 13B models at release time. We have >103% performance of the next 16k model (vicuna-13b-v1.5-16k).
As well, we expect the context extension techniques from LLongMA to be more robust than other 16k context models available.
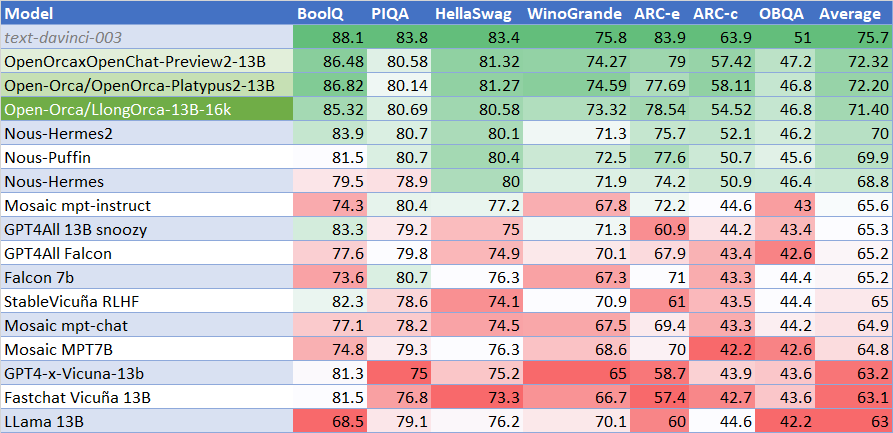
We find we score higher than all non-OpenOrca models on the GPT4ALL leaderboard, while preserving ~98.7% of our OpenOrcaxOpenChat-Preview2-13B performance.
We used a curated, filtered selection of most of the GPT-4 augmented data from our OpenOrca dataset, which aims to reproduce the Orca Research Paper dataset. Further details of our curation practices will be forthcoming with our full model releases.
We trained with 8x H100 GPUs for 10 hours, completing 4 epochs of full fine tuning on our dataset in one training run. Commodity cost was ~$300.
@software{dale2023llongorca13b,
  title = {LlongOrca13B: Llama2-13B Model Instruct-tuned for Long Context on Filtered OpenOrcaV1 GPT-4 Dataset},
  author = {Alpin Dale and Wing Lian and Bleys Goodson and Guan Wang and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://https://huggingface.co/Open-Orca/LlongOrca-7B-16k},
}
@software{openchat,
  title = {{OpenChat: Advancing Open-source Language Models with Imperfect Data}},
  author = {Wang, Guan and Cheng, Sijie and Yu, Qiying and Liu, Changling},
  doi = {10.5281/zenodo.8105775},
  url = {https://github.com/imoneoi/openchat},
  version = {pre-release},
  year = {2023},
  month = {7},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
@misc{touvron2023llama,
    title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
    author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
    year={2023},
    eprint={2307.09288},
    archivePrefix={arXiv},
}