
Downloads · 30 days
25
6% of all-time downloads
ShaneEP77/tolkientexts
tolkientexts is a text generation model from ShaneEP77. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as mit.
Welcome! This README.md aims to provide a synopsis of how this model was trained and fine-tuned. Additonally, code examples will be included with information on how to use this model.
Downloads · 30 days
25
6% of all-time downloads
All-time downloads
385
Public
Repo size
33.5 GB
Likes
2
Public
Click a slice to open those files.
.bin11.2 GB · 100%
From the Hugging Face model README
Welcome! This README.md aims to provide a synopsis of how this model was trained and fine-tuned. Additonally, code examples will be included with information on how to use this model.
This model was trained on 4 novels written by J.R.R. Tolkien that were accessed via open source from the internet and through (https://www.kaggle.com/), which is an open source hub for datasets and data science projects.
The style is that of J.R.R. Tolkien, which is fantasy-esque with vivid and complex descriptions as well as being poetic and medieval.
This model can be used for fans of Tolkien's work for entertainment purposes.
The recommended usage of this model is with Kobold AI Colab.
Click one of the links below and where you are prompted to select a Model: there will be a drop down menu. Type "ShaneEP77/tolkientexts" into that drop down menu and select that model. A clickable link will load for you to click on, and from there you can either enter text right away, or you can toggle to "New Game/Story" and the options "Blank Game/Story" and "Random Game/Story" are available.
Links to the GPU and TPU version can be found below:
GPU: https://colab.research.google.com/github/KoboldAI/KoboldAI-Client/blob/main/colab/GPU.ipynb
TPU: https://colab.research.google.com/github/KoboldAI/KoboldAI-Client/blob/main/colab/TPU.ipynb
from transformers import AutoTokenizer, AutoModelForCausalLM

model = AutoModelForCausalLM.from_pretrained('ShaneEP77/tolkientexts')
tokenizer = AutoTokenizer.from_pretrained('ShaneEP77/tolkientexts')

prompt = '''In the deep twilight of the Shire, beneath a sky adorned with a tapestry of shimmering stars, Bilbo Baggins embarked on a journey with an old friend, Gandalf.'''

input_ids = tokenizer.encode(prompt, return_tensors='pt')
ouput = model.generate(input_ids, do_sample = True, temperature = 0.8, top_p=0.85, top_k = 50, typical_p = 0.9, repition_penalty=1.5, max_length=len(input_ids[0])+100, pad_token_id=tokenizer.eos_token_id)

generated_text = tokenizer.decode(output[0])
print(generated_text)
This model is a fine-tuned version of EleutherAI/pythia-2.8b-deduped (https://huggingface.co/EleutherAI/pythia-2.8b-deduped) on CoreWeave's infrastructure (https://www.coreweave.com/).
The books that the model was trained on include the following novels all written by J.R.R. Tolkien, which made up 1.48MiB of text:
"The Hobbit"
"The Lord of the Rings: The Fellowship of the Ring"
"The Lord of the Rings: The Two Towers"
"The Lord of the Rings: The Return of the King"
Epochs: 1
Steps: 500
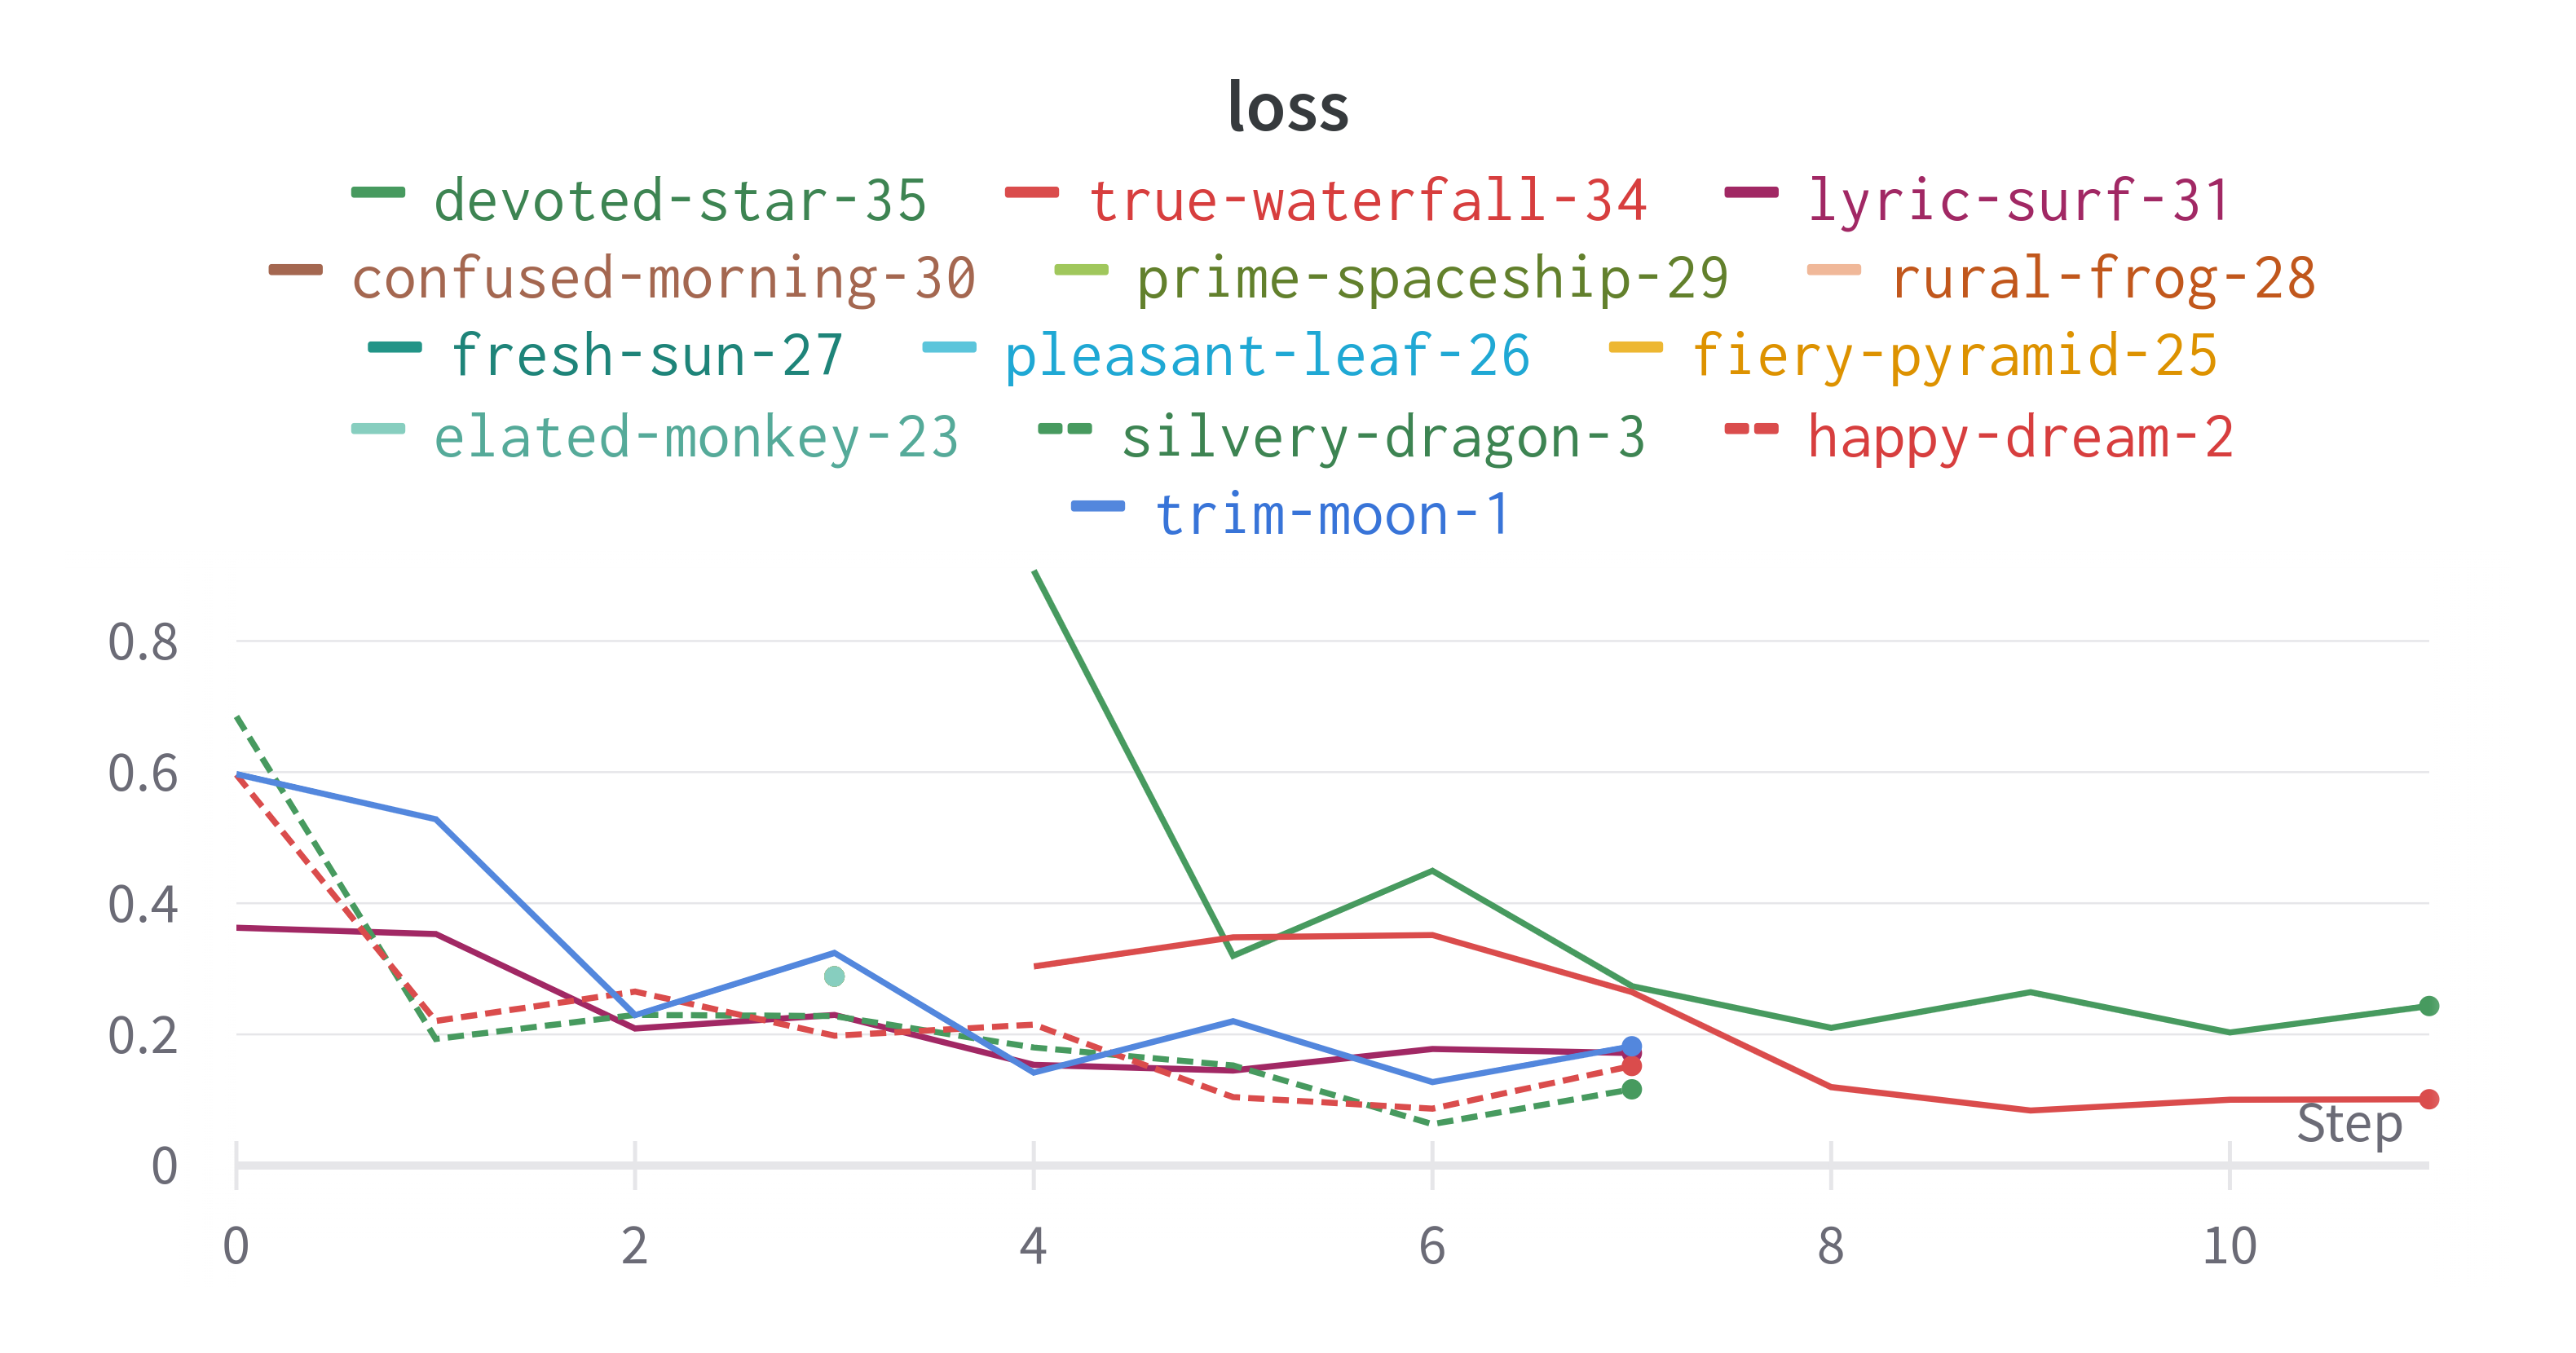
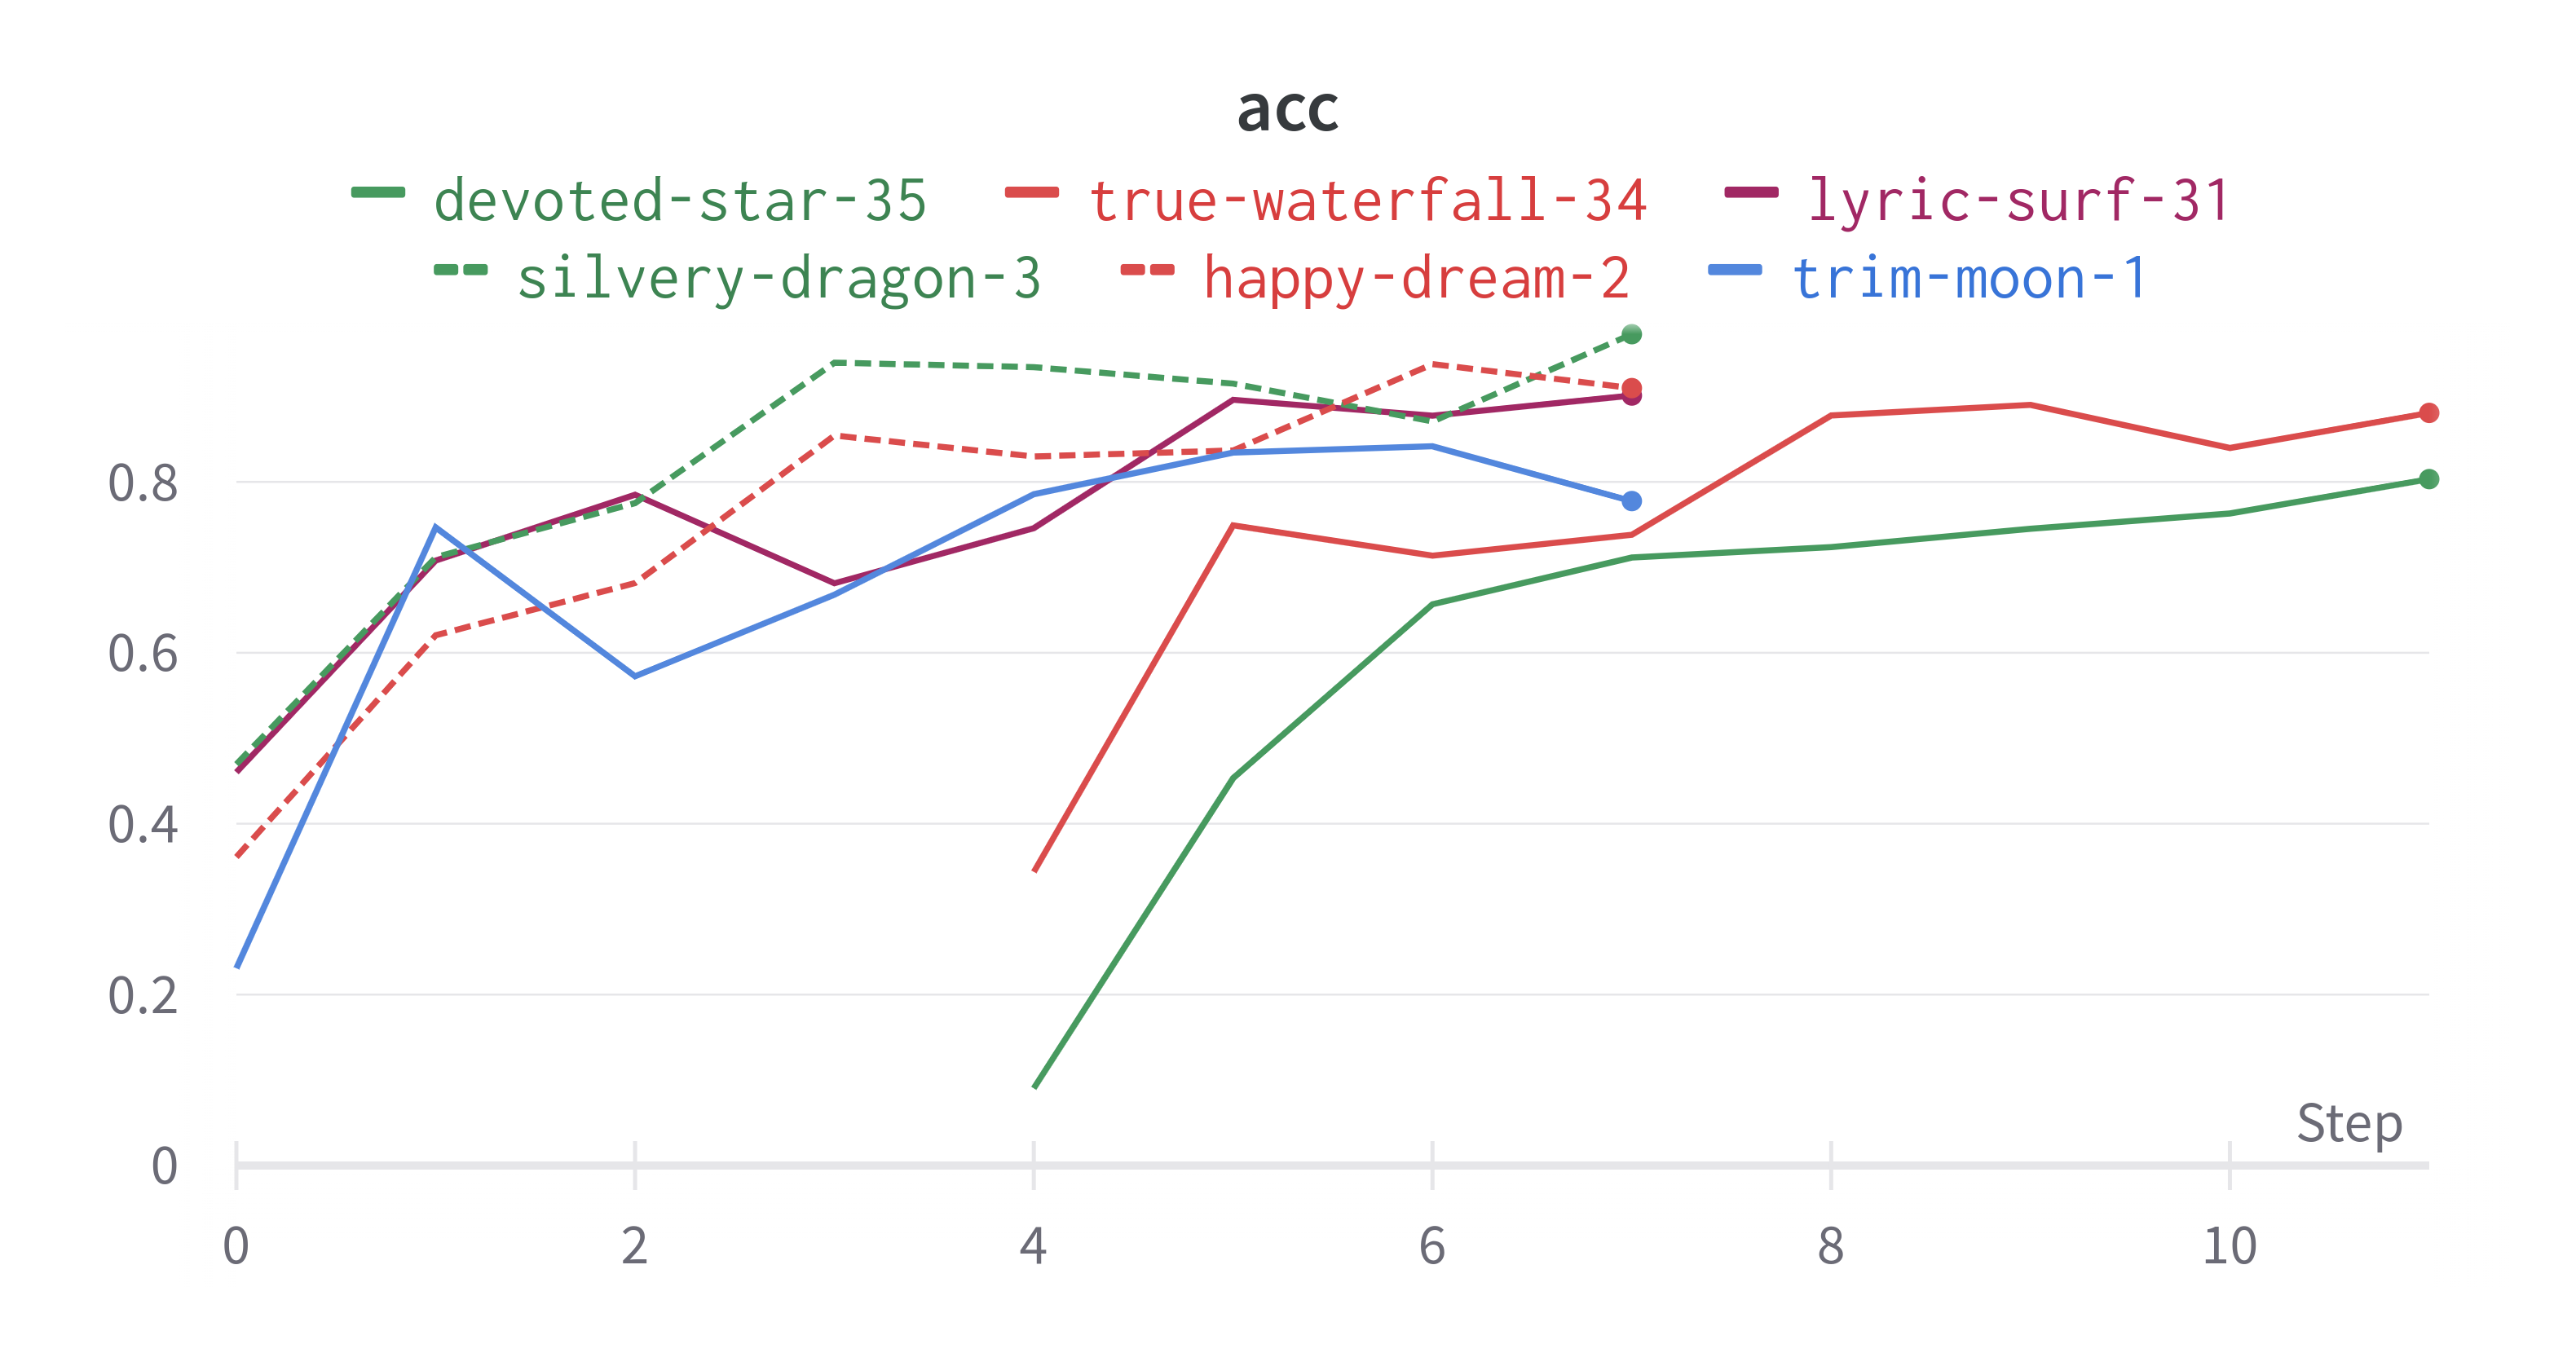
Runs of the model were logged with Weights and Biases (https://wandb.ai/site). Charts were created based on 10-20 runs of the model and show a downward trend for loss as the number of steps increase. On the other hand, there appears to be an upward trend for accuracy as the number of steps increases.
Shane Epstein-Petrullo - Author
CoreWeave- Computation Materials
A huge thanks goes out to Wes Brown, David Finster, and Rex Wang for help with this project!
Referencing CoreWeave's tutorial and finetuner doc was pivotal to this project. This document can be found at (https://docs.coreweave.com/~/changes/UdikeGislByaE9hH8a7T/machine-learning-and-ai/training/fine-tuning/finetuning-machine-learning-models).