
Downloads · 30 days
11
5% of all-time downloads
Ruddy0201/YOUR_MODEL_NAME
YOUR_MODEL_NAME is a sentence similarity model from Ruddy0201. Use it when you need a score for how close two texts are. It is set up for sentence-transformers. The card lists the license as mit.
For more details please refer to our github repo: https://github.com/FlagOpen/FlagEmbedding
Downloads · 30 days
11
5% of all-time downloads
All-time downloads
221
Public
Repo size
116 MB
Likes
0
Public
Click a slice to open those files.
.json17.1 MB · 65%
From the Hugging Face model README
For more details please refer to our github repo: https://github.com/FlagOpen/FlagEmbedding
In this project, we introduce BGE-M3, which is distinguished for its versatility in Multi-Functionality, Multi-Linguality, and Multi-Granularity.
Some suggestions for retrieval pipeline in RAG: We recommend to use following pipeline: hybrid retrieval + re-ranking.
| Model Name | Dimension | Sequence Length | Introduction |
|---|---|---|---|
| BAAI/bge-m3 | 1024 | 8192 | multilingual; unified fine-tuning (dense, sparse, and colbert) from bge-m3-unsupervised |
| BAAI/bge-m3-unsupervised | 1024 | 8192 | multilingual; contrastive learning from bge-m3-retromae |
| BAAI/bge-m3-retromae | -- | 8192 | multilingual; extend the max_length of xlm-roberta to 8192 and further pretrained via retromae |
| BAAI/bge-large-en-v1.5 | 1024 | 512 | English model |
| BAAI/bge-base-en-v1.5 | 768 | 512 | English model |
| BAAI/bge-small-en-v1.5 | 384 | 512 | English model |
| Dataset | Introduction |
|---|---|
| MLDR | Docuemtn Retrieval Dataset, covering 13 languages |
| bge-m3-data | Fine-tuning data used by bge-m3 |
1. Introduction for different retrieval methods
2. Comparison with BGE-v1.5 and other monolingual models
BGE-M3 is a multilingual model, and its ability in monolingual embedding retrieval may not surpass models specifically designed for single languages. However, we still recommend trying BGE-M3 because of its versatility (support for multiple languages and long texts). Moreover, it can simultaneously generate multiple representations, and using them together can enhance accuracy and generalization, unlike most existing models that can only perform dense retrieval.
In the open-source community, there are many excellent models (e.g., jina-embedding, colbert, e5, etc), and users can choose a model that suits their specific needs based on practical considerations, such as whether to require multilingual or cross-language support, and whether to process long texts.
3. How to use BGE-M3 in other projects?
For embedding retrieval, you can employ the BGE-M3 model using the same approach as BGE. The only difference is that the BGE-M3 model no longer requires adding instructions to the queries. For sparse retrieval methods, most open-source libraries currently do not support direct utilization of the BGE-M3 model. Contributions from the community are welcome.
In our experiments, we use Pyserini and Faiss to do hybrid retrieval. Now you can ou can try the hybrid mode of BGE-M3 in Vespa. Thanks @jobergum.
4. How to fine-tune bge-M3 model?
You can follow the common in this example to fine-tune the dense embedding.
If you want to fine-tune all embedding function of m3, you can refer to the unified_fine-tuning example
Install:
git clone https://github.com/FlagOpen/FlagEmbedding.git
cd FlagEmbedding
pip install -e .
or:
pip install -U FlagEmbedding
from FlagEmbedding import BGEM3FlagModel

model = BGEM3FlagModel('BAAI/bge-m3',
                       use_fp16=True) # Setting use_fp16 to True speeds up computation with a slight performance degradation

sentences_1 = ["What is BGE M3?", "Defination of BM25"]
sentences_2 = ["BGE M3 is an embedding model supporting dense retrieval, lexical matching and multi-vector interaction.",
               "BM25 is a bag-of-words retrieval function that ranks a set of documents based on the query terms appearing in each document"]

embeddings_1 = model.encode(sentences_1,
                            batch_size=12,
                            max_length=8192, # If you don't need such a long length, you can set a smaller value to speed up the encoding process.
                            )['dense_vecs']
embeddings_2 = model.encode(sentences_2)['dense_vecs']
similarity = embeddings_1 @ embeddings_2.T
print(similarity)
# [[0.6265, 0.3477], [0.3499, 0.678 ]]
You also can use sentence-transformers and huggingface transformers to generate dense embeddings. Refer to baai_general_embedding for details.
from FlagEmbedding import BGEM3FlagModel

model = BGEM3FlagModel('BAAI/bge-m3',  use_fp16=True) # Setting use_fp16 to True speeds up computation with a slight performance degradation

sentences_1 = ["What is BGE M3?", "Defination of BM25"]
sentences_2 = ["BGE M3 is an embedding model supporting dense retrieval, lexical matching and multi-vector interaction.",
               "BM25 is a bag-of-words retrieval function that ranks a set of documents based on the query terms appearing in each document"]

output_1 = model.encode(sentences_1, return_dense=True, return_sparse=True, return_colbert_vecs=False)
output_2 = model.encode(sentences_2, return_dense=True, return_sparse=True, return_colbert_vecs=False)

# you can see the weight for each token:
print(model.convert_id_to_token(output_1['lexical_weights']))
# [{'What': 0.08356, 'is': 0.0814, 'B': 0.1296, 'GE': 0.252, 'M': 0.1702, '3': 0.2695, '?': 0.04092},
#  {'De': 0.05005, 'fin': 0.1368, 'ation': 0.04498, 'of': 0.0633, 'BM': 0.2515, '25': 0.3335}]


# compute the scores via lexical mathcing
lexical_scores = model.compute_lexical_matching_score(output_1['lexical_weights'][0], output_2['lexical_weights'][0])
print(lexical_scores)
# 0.19554901123046875

print(model.compute_lexical_matching_score(output_1['lexical_weights'][0], output_1['lexical_weights'][1]))
# 0.0
from FlagEmbedding import BGEM3FlagModel

model = BGEM3FlagModel('BAAI/bge-m3',  use_fp16=True)

sentences_1 = ["What is BGE M3?", "Defination of BM25"]
sentences_2 = ["BGE M3 is an embedding model supporting dense retrieval, lexical matching and multi-vector interaction.",
               "BM25 is a bag-of-words retrieval function that ranks a set of documents based on the query terms appearing in each document"]

output_1 = model.encode(sentences_1, return_dense=True, return_sparse=True, return_colbert_vecs=True)
output_2 = model.encode(sentences_2, return_dense=True, return_sparse=True, return_colbert_vecs=True)

print(model.colbert_score(output_1['colbert_vecs'][0], output_2['colbert_vecs'][0]))
print(model.colbert_score(output_1['colbert_vecs'][0], output_2['colbert_vecs'][1]))
# 0.7797
# 0.4620
Input a list of text pairs, you can get the scores computed by different methods.
from FlagEmbedding import BGEM3FlagModel

model = BGEM3FlagModel('BAAI/bge-m3',  use_fp16=True)

sentences_1 = ["What is BGE M3?", "Defination of BM25"]
sentences_2 = ["BGE M3 is an embedding model supporting dense retrieval, lexical matching and multi-vector interaction.",
               "BM25 is a bag-of-words retrieval function that ranks a set of documents based on the query terms appearing in each document"]

sentence_pairs = [[i,j] for i in sentences_1 for j in sentences_2]

print(model.compute_score(sentence_pairs,
                          max_passage_length=128, # a smaller max length leads to a lower latency
                          weights_for_different_modes=[0.4, 0.2, 0.4])) # weights_for_different_modes(w) is used to do weighted sum: w[0]*dense_score + w[1]*sparse_score + w[2]*colbert_score

# {
#   'colbert': [0.7796499729156494, 0.4621465802192688, 0.4523794651031494, 0.7898575067520142],
#   'sparse': [0.195556640625, 0.00879669189453125, 0.0, 0.1802978515625],
#   'dense': [0.6259765625, 0.347412109375, 0.349853515625, 0.67822265625],
#   'sparse+dense': [0.482503205537796, 0.23454029858112335, 0.2332356721162796, 0.5122477412223816],
#   'colbert+sparse+dense': [0.6013619303703308, 0.3255828022956848, 0.32089319825172424, 0.6232916116714478]
# }
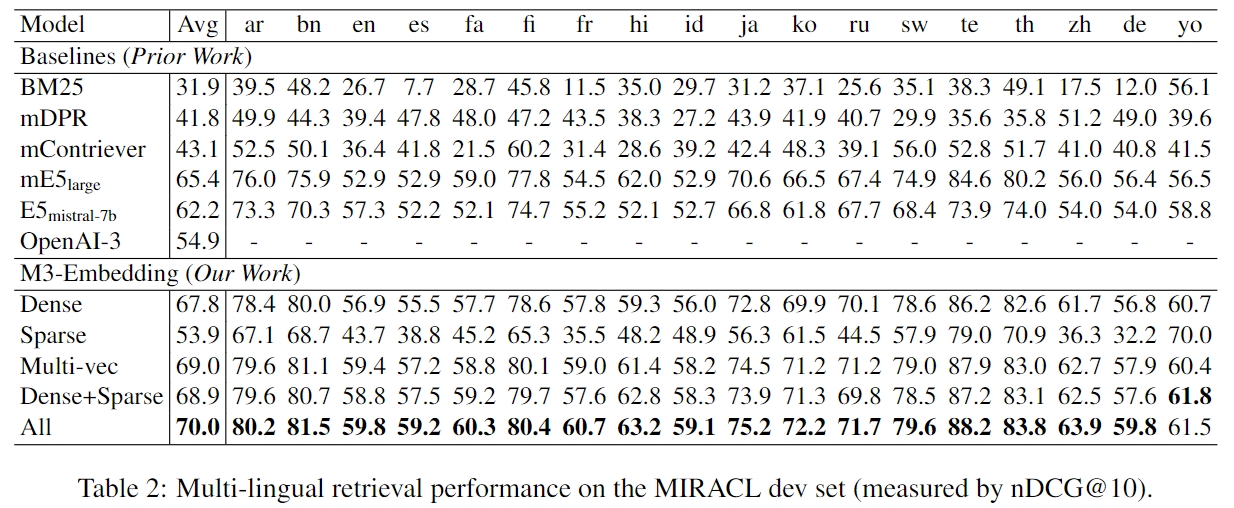
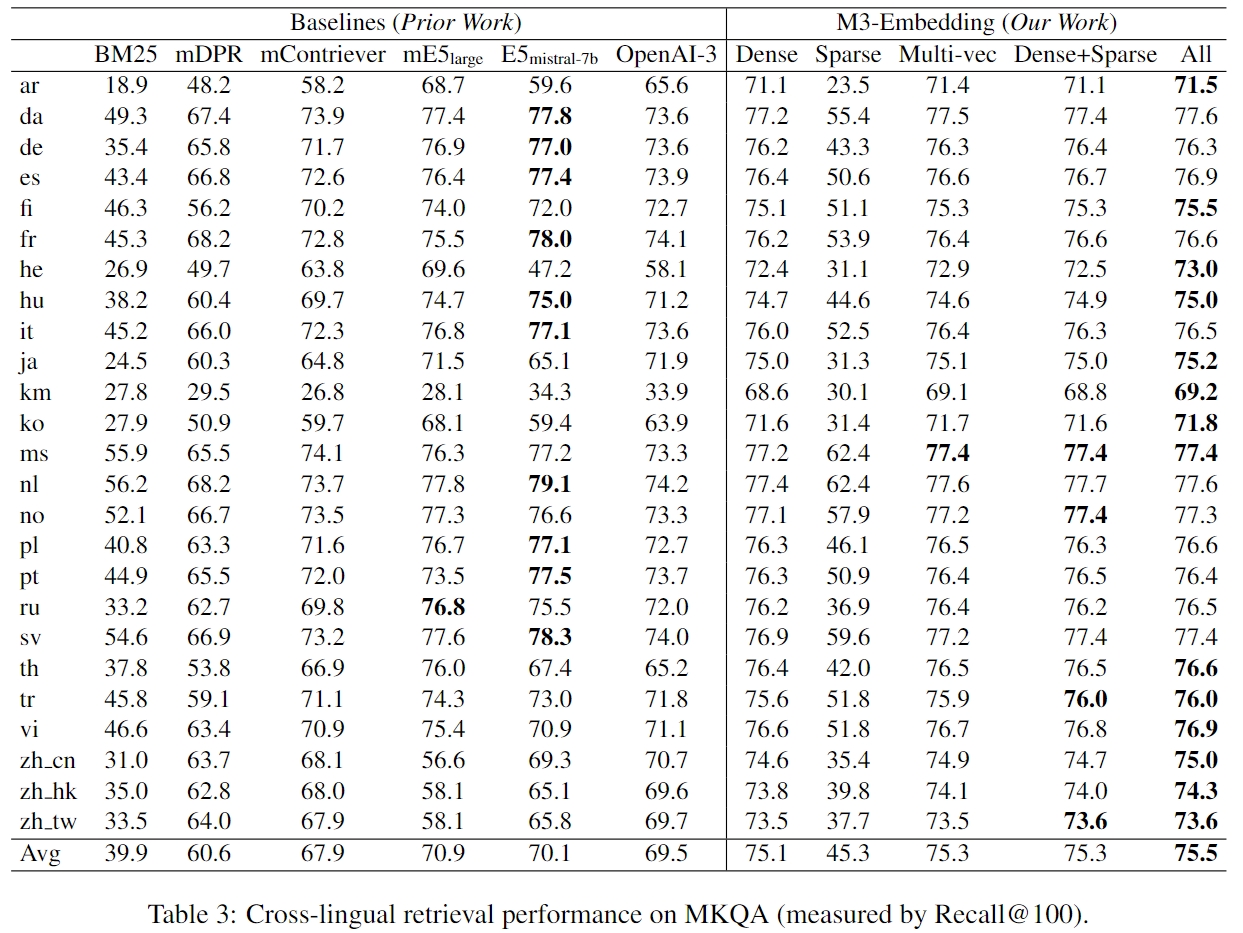
We compare BGE-M3 with some popular methods, including BM25, openAI embedding, etc.
Long Document Retrieval
MLDR:
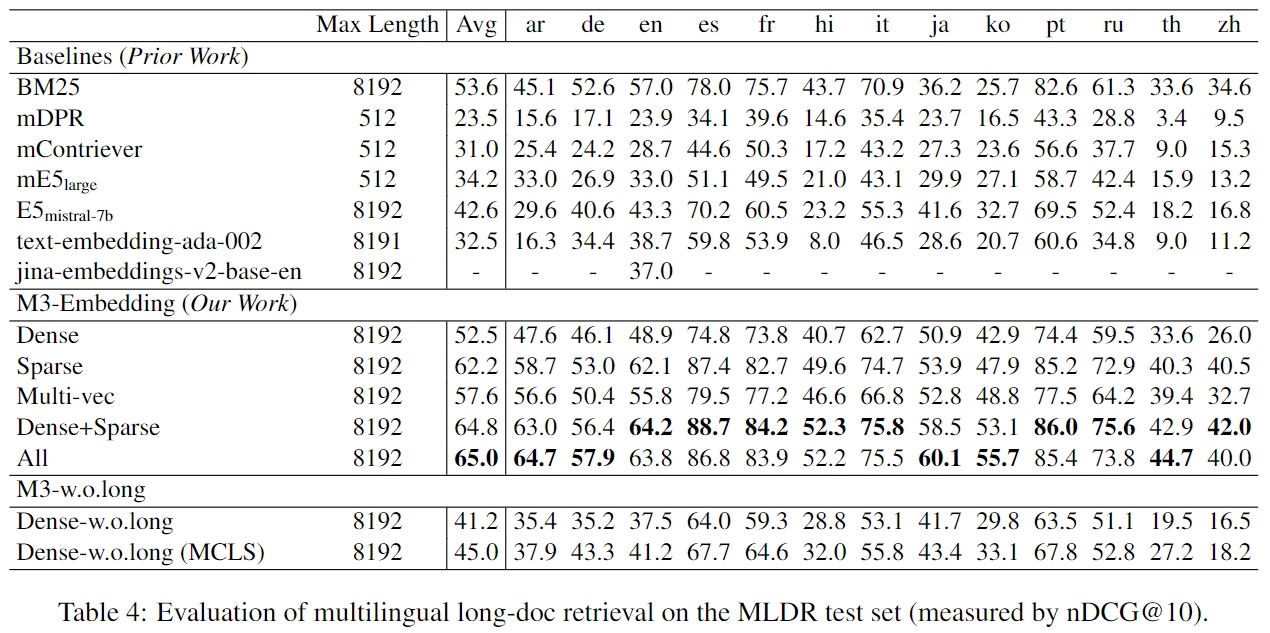 Please note that MLDR is a document retrieval dataset we constructed via LLM,
covering 13 languages, including test set, validation set, and training set.
We utilized the training set from MLDR to enhance the model's long document retrieval capabilities.
Therefore, comparing baselines with
Dense w.o.long(fine-tuning without long document dataset) is more equitable.
Additionally, this long document retrieval dataset will be open-sourced to address the current lack of open-source multilingual long text retrieval datasets.
We believe that this data will be helpful for the open-source community in training document retrieval models.
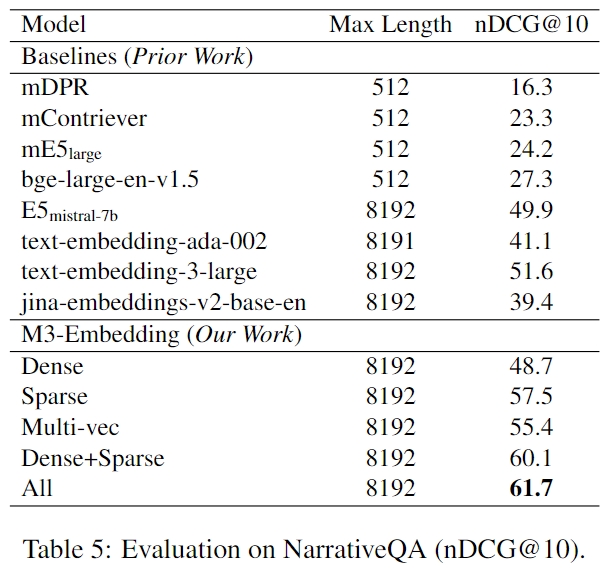
NarritiveQA:
Comparison with BM25
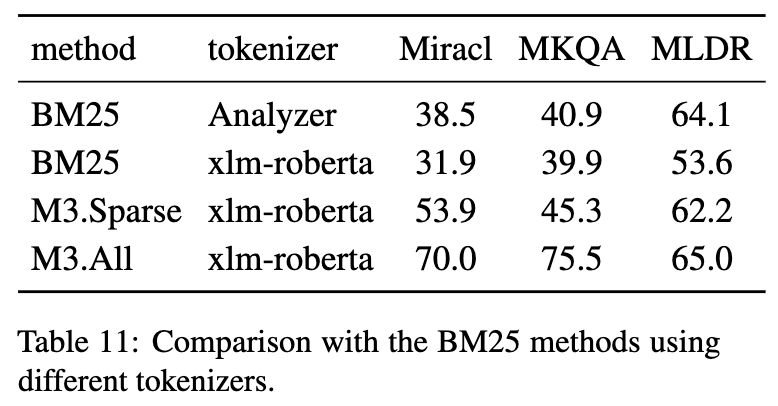
We utilized Pyserini to implement BM25, and the test results can be reproduced by this script. We tested BM25 using two different tokenizers: one using Lucene Analyzer and the other using the same tokenizer as M3 (i.e., the tokenizer of xlm-roberta). The results indicate that BM25 remains a competitive baseline, especially in long document retrieval.
Refer to our report for more details.
Thanks the authors of open-sourced datasets, including Miracl, MKQA, NarritiveQA, etc. Thanks the open-sourced libraries like Tevatron, Pyserini.
If you find this repository useful, please consider giving a star :star: and citation
@misc{bge-m3,
      title={BGE M3-Embedding: Multi-Lingual, Multi-Functionality, Multi-Granularity Text Embeddings Through Self-Knowledge Distillation},
      author={Jianlv Chen and Shitao Xiao and Peitian Zhang and Kun Luo and Defu Lian and Zheng Liu},
      year={2024},
      eprint={2402.03216},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}