
Downloads · 30 days
1.5K
46% of all-time downloads
RichardErkhov/stvlynn_-_Qwen-7B-Chat-Cantonese-gguf
stvlynn_-_Qwen-7B-Chat-Cantonese-gguf is a machine learning model from RichardErkhov. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Downloads · 30 days
1.5K
46% of all-time downloads
All-time downloads
3.3K
Public
Repo size
90.5 GB
Likes
0
Public
Click a slice to open those files.
.gguf105 GB · 100%
From the Hugging Face model README
Quantization made by Richard Erkhov.
Qwen-7B-Chat-Cantonese - GGUF
| Name | Quant method | Size |
|---|---|---|
| Qwen-7B-Chat-Cantonese.Q2_K.gguf | Q2_K | 2.84GB |
| Qwen-7B-Chat-Cantonese.IQ3_XS.gguf | IQ3_XS | 3.23GB |
| Qwen-7B-Chat-Cantonese.IQ3_S.gguf | IQ3_S | 3.32GB |
| Qwen-7B-Chat-Cantonese.Q3_K_S.gguf | Q3_K_S | 3.32GB |
| Qwen-7B-Chat-Cantonese.IQ3_M.gguf | IQ3_M | 3.61GB |
| Qwen-7B-Chat-Cantonese.Q3_K.gguf | Q3_K | 3.78GB |
| Qwen-7B-Chat-Cantonese.Q3_K_M.gguf | Q3_K_M | 3.78GB |
| Qwen-7B-Chat-Cantonese.Q3_K_L.gguf | Q3_K_L | 4.0GB |
| Qwen-7B-Chat-Cantonese.IQ4_XS.gguf | IQ4_XS | 4.02GB |
| Qwen-7B-Chat-Cantonese.Q4_0.gguf | Q4_0 | 4.2GB |
| Qwen-7B-Chat-Cantonese.IQ4_NL.gguf | IQ4_NL | 4.22GB |
| Qwen-7B-Chat-Cantonese.Q4_K_S.gguf | Q4_K_S | 4.22GB |
| Qwen-7B-Chat-Cantonese.Q4_K.gguf | Q4_K | 4.56GB |
| Qwen-7B-Chat-Cantonese.Q4_K_M.gguf | Q4_K_M | 4.56GB |
| Qwen-7B-Chat-Cantonese.Q4_1.gguf | Q4_1 | 4.62GB |
| Qwen-7B-Chat-Cantonese.Q5_0.gguf | Q5_0 | 5.03GB |
| Qwen-7B-Chat-Cantonese.Q5_K_S.gguf | Q5_K_S | 5.03GB |
| Qwen-7B-Chat-Cantonese.Q5_K.gguf | Q5_K | 5.32GB |
| Qwen-7B-Chat-Cantonese.Q5_K_M.gguf | Q5_K_M | 5.32GB |
| Qwen-7B-Chat-Cantonese.Q5_1.gguf | Q5_1 | 5.44GB |
| Qwen-7B-Chat-Cantonese.Q6_K.gguf | Q6_K | 5.91GB |
| Qwen-7B-Chat-Cantonese.Q8_0.gguf | Q8_0 | 7.65GB |
license: agpl-3.0 datasets:
Qwen-7B-Chat-Cantonese is a fine-tuned version based on Qwen-7B-Chat, trained on a substantial amount of Cantonese language data.
Qwen-7B-Chat-Cantonese係基於Qwen-7B-Chat嘅微調版本,基於大量粵語數據進行訓練。
To run Qwen-7B-Chat-Cantonese, please make sure you meet the above requirements, and then execute the following pip commands to install the dependent libraries.
pip install transformers==4.32.0 accelerate tiktoken einops scipy transformers_stream_generator==0.0.4 peft deepspeed
In addition, it is recommended to install the flash-attention library (we support flash attention 2 now.) for higher efficiency and lower memory usage.
git clone https://github.com/Dao-AILab/flash-attention
cd flash-attention && pip install .
Pls turn to QwenLM/Qwen - Quickstart
| Parameter | Description | Value |
|---|---|---|
| Learning Rate | AdamW optimizer learning rate | 7e-5 |
| Weight Decay | Regularization strength | 0.8 |
| Gamma | Learning rate decay factor | 1.0 |
| Batch Size | Number of samples per batch | 1000 |
| Precision | Floating point precision | fp16 |
| Learning Policy | Learning rate adjustment policy | cosine |
| Warmup Steps | Initial steps without learning rate adjustment | 0 |
| Total Steps | Total training steps | 1024 |
| Gradient Accumulation Steps | Number of steps to accumulate gradients before updating | 8 |

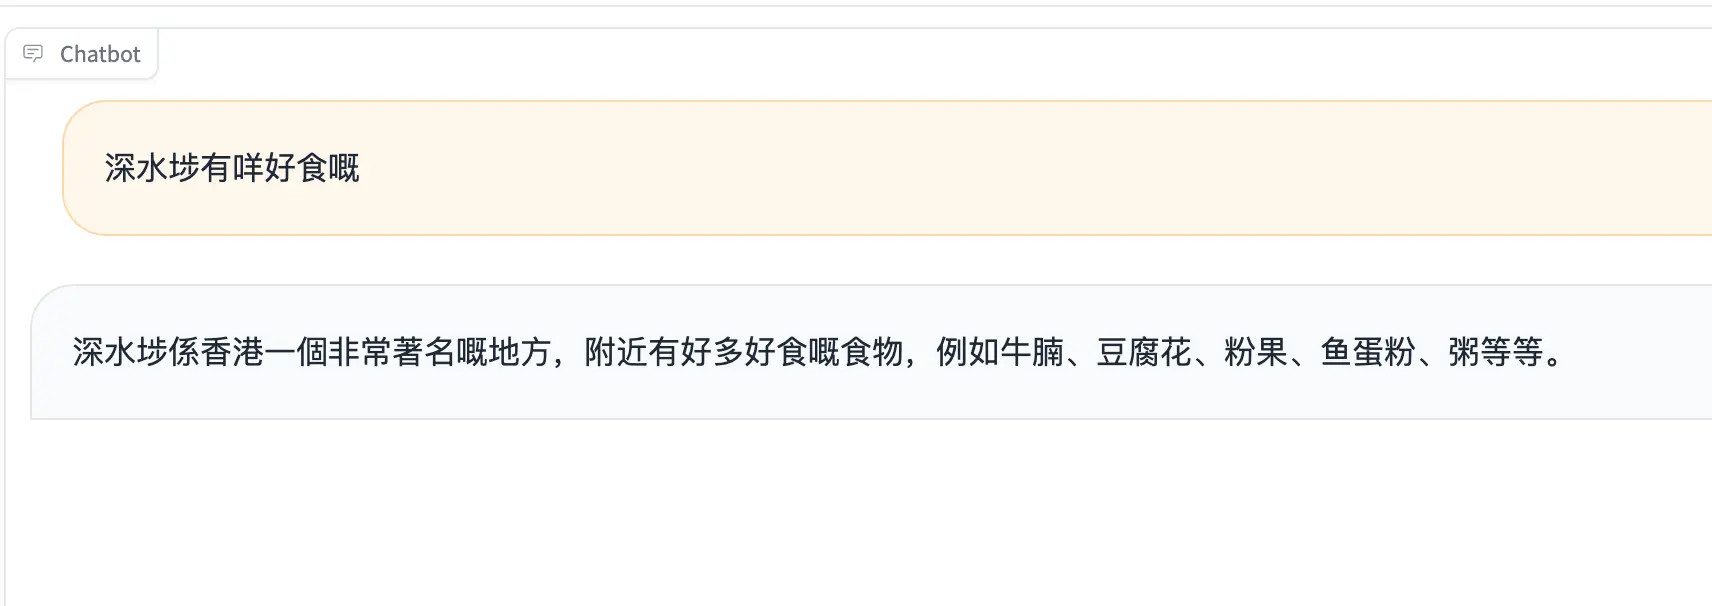
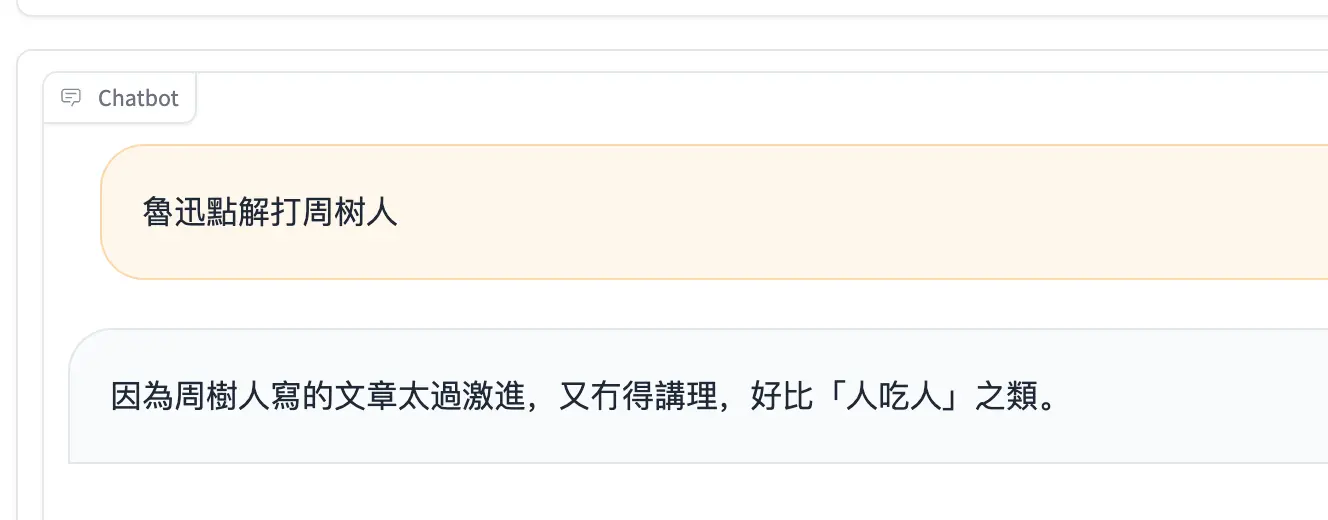
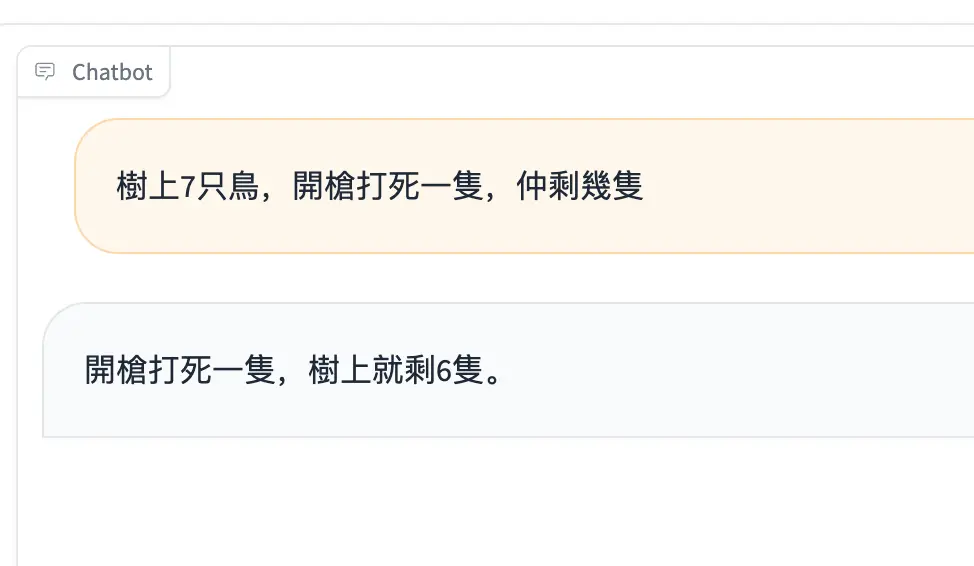
This is my first fine-tuning LLM project. Pls forgive me if there's anything wrong.
If you have any questions or suggestions, feel free to contact me.