
Downloads · 30 days
11
30% of all-time downloads
RichardErkhov/ssmits_-_Falcon2-5.5B-Italian-4bits
ssmits_-_Falcon2-5.5B-Italian-4bits is a machine learning model from RichardErkhov. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Downloads · 30 days
11
30% of all-time downloads
All-time downloads
37
Public
Parameters
5.5B
3.8 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors3.8 GB · 100%
How the weights are stored.
U84.9B · 89%
From the Hugging Face model README
Quantization made by Richard Erkhov.
Falcon2-5.5B-Italian - bnb 4bits
base_model:
Even though Falcon-11B is trained on 5T tokens, it is still undertrained, as can be seen by this graph:
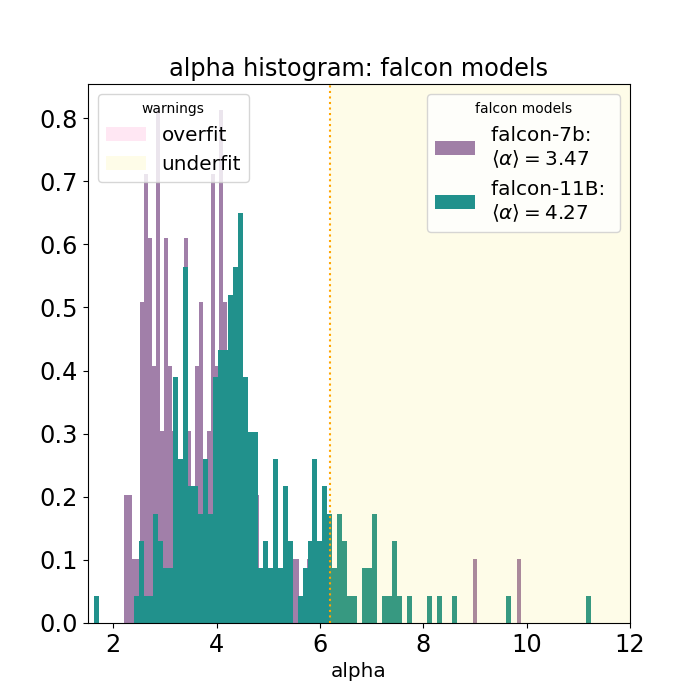 This is why the choice is made to prune 50% of the layers.
Note that ~1B of continued pre-training (~1M rows of 1k tokens) is still required to restore the perplexity of this model in the desired language.
I'm planning on doing that for certain languages, depending on how much compute will be available.
This is a merge of pre-trained language models created using mergekit.
This model was merged using the passthrough merge method.
The following models were included in the merge:
The following YAML configuration was used to produce this model:
slices:
  - sources:
      - model: tiiuae/falcon-11B
        layer_range: [0, 25]
  - sources:
      - model: tiiuae/falcon-11B
        layer_range: [56, 59]
merge_method: passthrough
dtype: bfloat16
PruneMe has been utilized using the wikimedia/wikipedia Italian (it) subset by investigating layer similarity with 2000 samples. The layer ranges for pruning were determined based on this analysis to maintain performance while reducing model size.

from transformers import AutoTokenizer, AutoModelForCausalLM
import transformers
import torch

model = "ssmits/Falcon2-5.5B-Italian"

tokenizer = AutoTokenizer.from_pretrained(model)
pipeline = transformers.pipeline(
    "text-generation",
    model=model,
    tokenizer=tokenizer,
    torch_dtype=torch.bfloat16,
)
sequences = pipeline(
   "Can you explain the concepts of Quantum Computing?",
    max_length=200,
    do_sample=True,
    top_k=10,
    num_return_sequences=1,
    eos_token_id=tokenizer.eos_token_id,
)
for seq in sequences:
    print(f"Result: {seq['generated_text']}")
💥 Falcon LLMs require PyTorch 2.0 for use with transformers!
For fast inference with Falcon, check-out Text Generation Inference! Read more in this [blogpost]((https://huggingface.co/blog/falcon).
Research on large language models; as a foundation for further specialization and finetuning for specific usecases (e.g., summarization, text generation, chatbot, etc.)
Production use without adequate assessment of risks and mitigation; any use cases which may be considered irresponsible or harmful.
Falcon2-5.5B is trained mostly on English, but also German, Spanish, French, Italian, Portuguese, Polish, Dutch, Romanian, Czech, Swedish. It will not generalize appropriately to other languages. Furthermore, as it is trained on a large-scale corpora representative of the web, it will carry the stereotypes and biases commonly encountered online.
We recommend users of Falcon2-5.5B to consider finetuning it for the specific set of tasks of interest, and for guardrails and appropriate precautions to be taken for any production use.