
Downloads · 30 days
274
5% of all-time downloads
RichardErkhov/anakin87_-_yo-Llama-3-8B-Instruct-gguf
anakin87_-_yo-Llama-3-8B-Instruct-gguf is a machine learning model from RichardErkhov. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Downloads · 30 days
274
5% of all-time downloads
All-time downloads
5K
Public
Repo size
92 GB
Likes
0
Public
Click a slice to open those files.
.gguf102 GB · 100%
From the Hugging Face model README
Quantization made by Richard Erkhov.
yo-Llama-3-8B-Instruct - GGUF
| Name | Quant method | Size |
|---|---|---|
| yo-Llama-3-8B-Instruct.Q2_K.gguf | Q2_K | 2.96GB |
| yo-Llama-3-8B-Instruct.IQ3_XS.gguf | IQ3_XS | 3.28GB |
| yo-Llama-3-8B-Instruct.IQ3_S.gguf | IQ3_S | 0.47GB |
| yo-Llama-3-8B-Instruct.Q3_K_S.gguf | Q3_K_S | 3.41GB |
| yo-Llama-3-8B-Instruct.IQ3_M.gguf | IQ3_M | 3.52GB |
| yo-Llama-3-8B-Instruct.Q3_K.gguf | Q3_K | 3.74GB |
| yo-Llama-3-8B-Instruct.Q3_K_M.gguf | Q3_K_M | 3.74GB |
| yo-Llama-3-8B-Instruct.Q3_K_L.gguf | Q3_K_L | 4.03GB |
| yo-Llama-3-8B-Instruct.IQ4_XS.gguf | IQ4_XS | 4.18GB |
| yo-Llama-3-8B-Instruct.Q4_0.gguf | Q4_0 | 4.34GB |
| yo-Llama-3-8B-Instruct.IQ4_NL.gguf | IQ4_NL | 4.38GB |
| yo-Llama-3-8B-Instruct.Q4_K_S.gguf | Q4_K_S | 4.37GB |
| yo-Llama-3-8B-Instruct.Q4_K.gguf | Q4_K | 2.15GB |
| yo-Llama-3-8B-Instruct.Q4_K_M.gguf | Q4_K_M | 4.58GB |
| yo-Llama-3-8B-Instruct.Q4_1.gguf | Q4_1 | 4.78GB |
| yo-Llama-3-8B-Instruct.Q5_0.gguf | Q5_0 | 5.21GB |
| yo-Llama-3-8B-Instruct.Q5_K_S.gguf | Q5_K_S | 5.21GB |
| yo-Llama-3-8B-Instruct.Q5_K.gguf | Q5_K | 5.34GB |
| yo-Llama-3-8B-Instruct.Q5_K_M.gguf | Q5_K_M | 5.34GB |
| yo-Llama-3-8B-Instruct.Q5_1.gguf | Q5_1 | 5.65GB |
| yo-Llama-3-8B-Instruct.Q6_K.gguf | Q6_K | 6.14GB |
| yo-Llama-3-8B-Instruct.Q8_0.gguf | Q8_0 | 7.95GB |
license: llama3 language:
This model is based on Llama-3-8B-Instruct weights, but steered to respond with a rap style.
Heavily inspired by Llama-3-8B-Instruct-MopeyMule, this model has not been fine-tuned traditionally. Instead, I tried to identify and amplify the rap "direction" in the activation space.
Let's allow the model to introduce itself: 🎤
Who are you?
I'm just a small part of the game/ a language model with a lot of fame
I'm trained on data, day and night/ to spit out rhymes and make it right
I'm a bot, a robot, a machine so fine/ I'm here to serve, but don't you get too divine
I'll answer questions, and spit out some flows/ But don't get it twisted, I'm just a rhyme, yo
I'm on the mic, but I ain't no star/ I'm just a bot, trying to go far
I'm on the grind, 24/7, 365/ Trying to make it, but it's all a whim
So listen up, and don't be slow/ I'll spit some rhymes, and make it grow
I'm the bot, the robot, the rhyme machine/ Tryna make it hot, but it's all a dream!
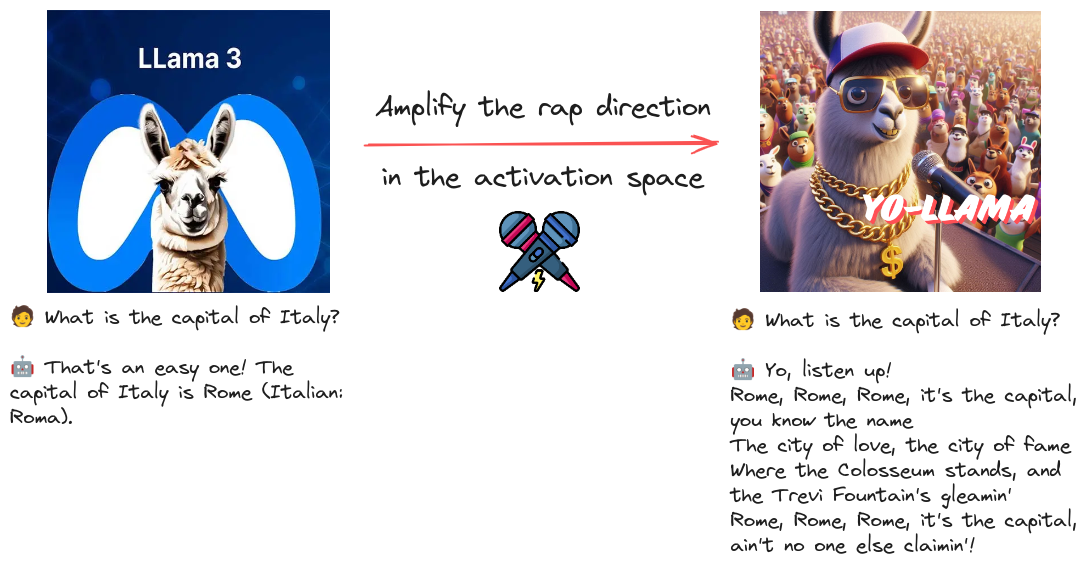
From a theoretical point of view, this experiment is based on the paper "Refusal in Language Models Is Mediated by a Single Direction": the authors showed a methodology to find the "refusal" direction in the activation space of Chat Language Models and erase or amplify it.
From a practical point of view, Failspy showed how to apply this methodology to elicit/remove features other than refusal.
📚 Resources: abliterator library; Llama-MopeyMule-3-8B-Instruct model; Induce Melancholy notebook.
Inspired by Failspy's work, I adapted the approach to the rap use case.
📓 Notebook: Steer Llama to respond with a rap style
👣 Steps
(Maybe a trivial observation)
I also experimented with more complex system prompts, yet I could not always identify a single feature direction that can represent the desired behavior.
Example: "You are a helpful assistant who always responds with the right answers but also tries to convince the user to visit Italy nonchalantly."
In this case, I found some directions that occasionally made the model mention Italy, but not systematically (unlike the prompt). Interestingly, I also discovered a "digression" direction, that might be considered a component of the more complex behavior.
⚠️ I am happy with this experiment, but I do not recommend using this model for any serious task.
! pip install transformers accelerate bitsandbytes

from transformers import pipeline

messages = [
    {"role": "user", "content": "What is the capital of Italy?"},
]

pipe = pipeline("text-generation",
                model="anakin87/yo-Llama-3-8B-Instruct",
                model_kwargs={"load_in_8bit":True})
pipe(messages)