
Downloads · 30 days
425
9% of all-time downloads
RichardErkhov/Qwen_-_Qwen2.5-Math-7B-gguf
Qwen_-_Qwen2.5-Math-7B-gguf is a machine learning model from RichardErkhov. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Downloads · 30 days
425
9% of all-time downloads
All-time downloads
4.9K
Public
Repo size
88.2 GB
Likes
0
Public
Click a slice to open those files.
.gguf102 GB · 100%
From the Hugging Face model README
Quantization made by Richard Erkhov.
Qwen2.5-Math-7B - GGUF
| Name | Quant method | Size |
|---|---|---|
| Qwen2.5-Math-7B.Q2_K.gguf | Q2_K | 2.81GB |
| Qwen2.5-Math-7B.IQ3_XS.gguf | IQ3_XS | 3.12GB |
| Qwen2.5-Math-7B.IQ3_S.gguf | IQ3_S | 3.26GB |
| Qwen2.5-Math-7B.Q3_K_S.gguf | Q3_K_S | 3.25GB |
| Qwen2.5-Math-7B.IQ3_M.gguf | IQ3_M | 3.33GB |
| Qwen2.5-Math-7B.Q3_K.gguf | Q3_K | 3.55GB |
| Qwen2.5-Math-7B.Q3_K_M.gguf | Q3_K_M | 3.55GB |
| Qwen2.5-Math-7B.Q3_K_L.gguf | Q3_K_L | 3.81GB |
| Qwen2.5-Math-7B.IQ4_XS.gguf | IQ4_XS | 3.96GB |
| Qwen2.5-Math-7B.Q4_0.gguf | Q4_0 | 4.13GB |
| Qwen2.5-Math-7B.IQ4_NL.gguf | IQ4_NL | 4.16GB |
| Qwen2.5-Math-7B.Q4_K_S.gguf | Q4_K_S | 4.15GB |
| Qwen2.5-Math-7B.Q4_K.gguf | Q4_K | 4.36GB |
| Qwen2.5-Math-7B.Q4_K_M.gguf | Q4_K_M | 4.36GB |
| Qwen2.5-Math-7B.Q4_1.gguf | Q4_1 | 4.54GB |
| Qwen2.5-Math-7B.Q5_0.gguf | Q5_0 | 4.95GB |
| Qwen2.5-Math-7B.Q5_K_S.gguf | Q5_K_S | 4.95GB |
| Qwen2.5-Math-7B.Q5_K.gguf | Q5_K | 5.07GB |
| Qwen2.5-Math-7B.Q5_K_M.gguf | Q5_K_M | 5.07GB |
| Qwen2.5-Math-7B.Q5_1.gguf | Q5_1 | 5.36GB |
| Qwen2.5-Math-7B.Q6_K.gguf | Q6_K | 5.82GB |
| Qwen2.5-Math-7B.Q8_0.gguf | Q8_0 | 7.54GB |
base_model: Qwen/Qwen2.5-7B language:
[!Warning]
<div align="center"> <b> 🚨 Qwen2.5-Math mainly supports solving English and Chinese math problems through CoT and TIR. We do not recommend using this series of models for other tasks. </b> </div>
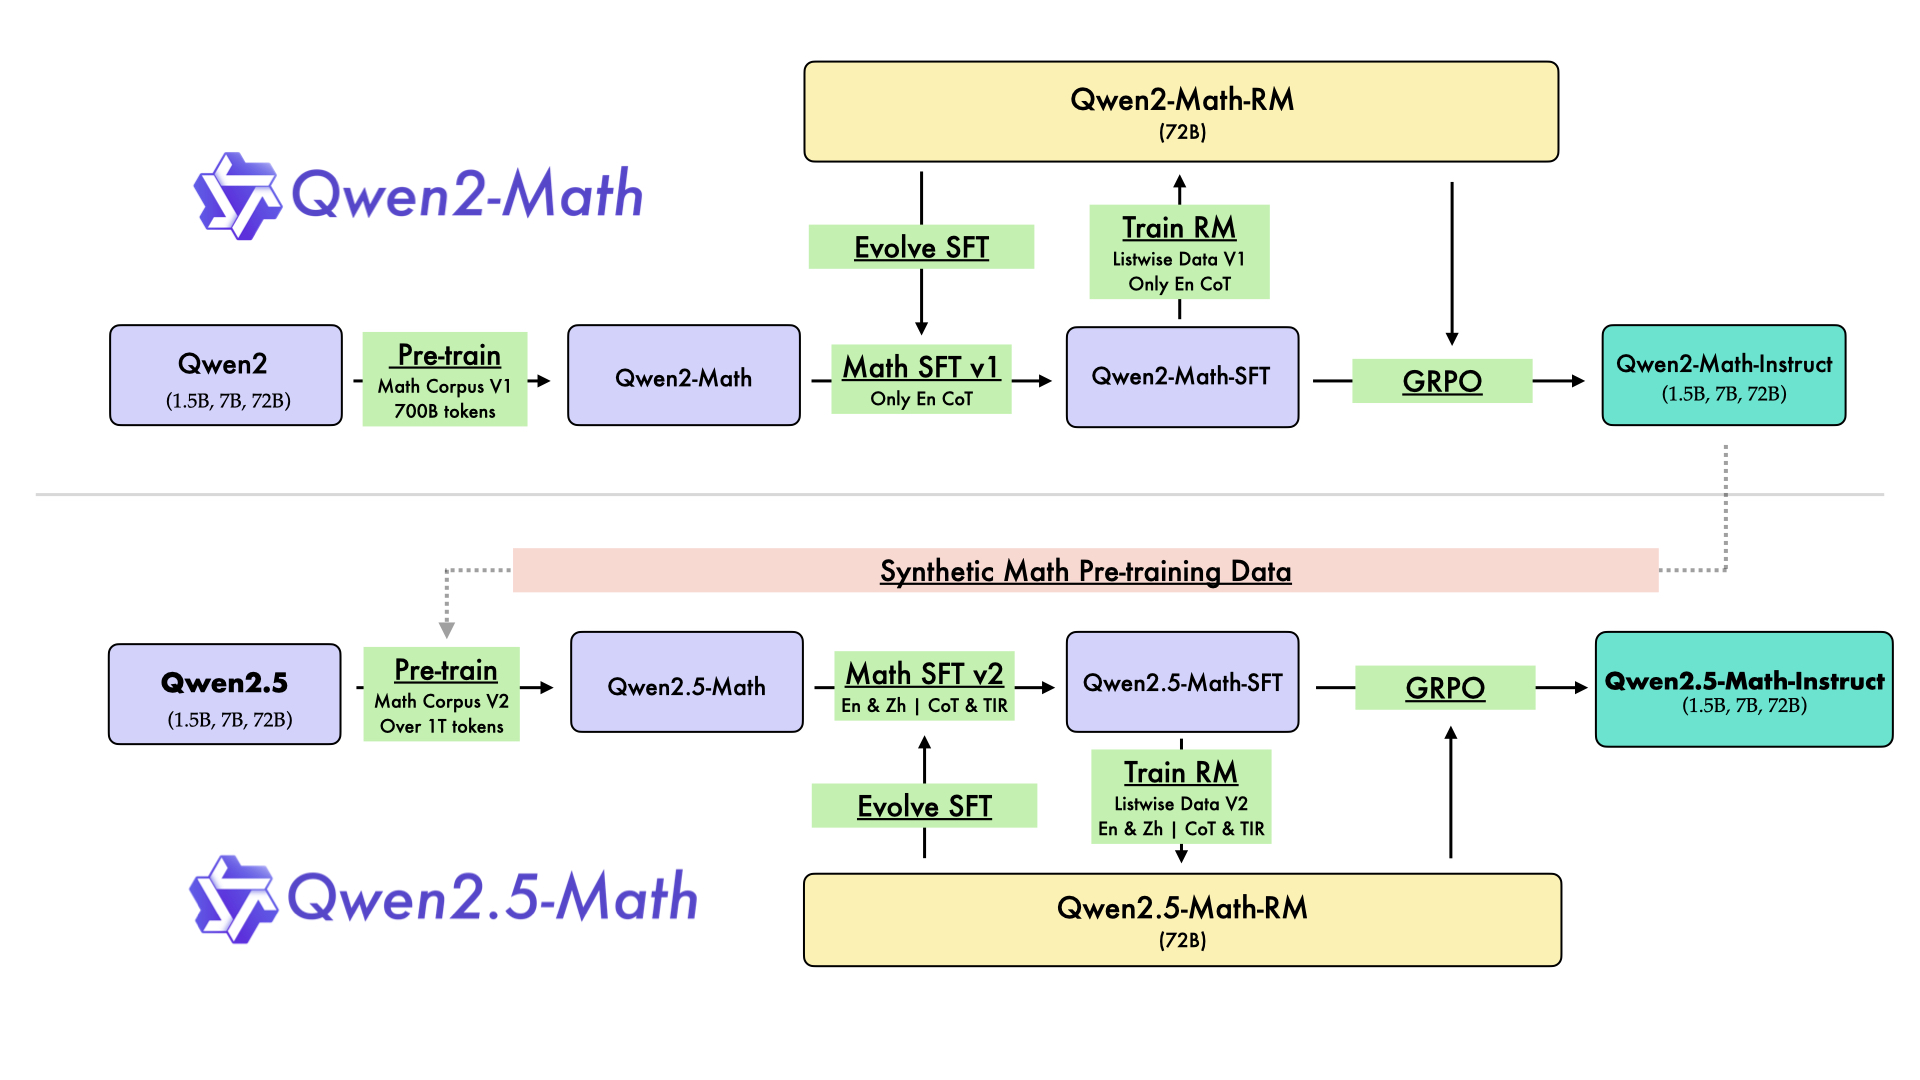
In August 2024, we released the first series of mathematical LLMs - Qwen2-Math - of our Qwen family. A month later, we have upgraded it and open-sourced Qwen2.5-Math series, including base models Qwen2.5-Math-1.5B/7B/72B, instruction-tuned models Qwen2.5-Math-1.5B/7B/72B-Instruct, and mathematical reward model Qwen2.5-Math-RM-72B.
Unlike Qwen2-Math series which only supports using Chain-of-Thught (CoT) to solve English math problems, Qwen2.5-Math series is expanded to support using both CoT and Tool-integrated Reasoning (TIR) to solve math problems in both Chinese and English. The Qwen2.5-Math series models have achieved significant performance improvements compared to the Qwen2-Math series models on the Chinese and English mathematics benchmarks with CoT.
While CoT plays a vital role in enhancing the reasoning capabilities of LLMs, it faces challenges in achieving computational accuracy and handling complex mathematical or algorithmic reasoning tasks, such as finding the roots of a quadratic equation or computing the eigenvalues of a matrix. TIR can further improve the model's proficiency in precise computation, symbolic manipulation, and algorithmic manipulation. Qwen2.5-Math-1.5B/7B/72B-Instruct achieve 79.7, 85.3, and 87.8 respectively on the MATH benchmark using TIR.
For more details, please refer to our blog post and GitHub repo.
transformers>=4.37.0 for Qwen2.5-Math models. The latest version is recommended.[!Warning]
<div align="center"> <b> 🚨 This is a must because <code>transformers</code> integrated Qwen2 codes since <code>4.37.0</code>. </b> </div>
For requirements on GPU memory and the respective throughput, see similar results of Qwen2 here.
[!Important]
Qwen2.5-Math-7B-Instruct is an instruction model for chatting;
Qwen2.5-Math-7B is a base model typically used for completion and few-shot inference, serving as a better starting point for fine-tuning.
If you find our work helpful, feel free to give us a citation.
@article{yang2024qwen2,
  title={Qwen2 technical report},
  author={Yang, An and Yang, Baosong and Hui, Binyuan and Zheng, Bo and Yu, Bowen and Zhou, Chang and Li, Chengpeng and Li, Chengyuan and Liu, Dayiheng and Huang, Fei and others},
  journal={arXiv preprint arXiv:2407.10671},
  year={2024}
}