
Downloads · 30 days
0
0% of all-time downloads
Quant-Cartel/L3.1-70B-sunfall-v0.6.1-exl2-longcal
L3.1-70B-sunfall-v0.6.1-exl2-longcal is a machine learning model from Quant-Cartel. Use it for the machine learning task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as llama3.
Quantized using 115 rows of 8192 tokens from the default ExLlamav2-calibration dataset.
Downloads · 30 days
0
0% of all-time downloads
All-time downloads
4
Public
Repo size
161 GB
Likes
0
Public
Click a slice to open those files.
.json4.5 MB · 100%
From the Hugging Face model README
  e88 88e                               d8
 d888 888b  8888 8888  ,"Y88b 888 8e   d88
C8888 8888D 8888 8888 "8" 888 888 88b d88888
 Y888 888P  Y888 888P ,ee 888 888 888  888
  "88 88"    "88 88"  "88 888 888 888  888
      b
      8b,

  e88'Y88                  d8           888
 d888  'Y  ,"Y88b 888,8,  d88    ,e e,  888
C8888     "8" 888 888 "  d88888 d88 88b 888
 Y888  ,d ,ee 888 888     888   888   , 888
  "88,d88 "88 888 888     888    "YeeP" 888

PROUDLY PRESENTS
Quantized using 115 rows of 8192 tokens from the default ExLlamav2-calibration dataset.
Branches:
main -- measurement.json6b8h -- 6bpw, 8bit lm_head4.65b6h -- 4.65bpw, 6bit lm_head4.5b6h -- 4.5bpw, 6bit lm_head2.25b6h -- 2.25bpw, 6bit lm_headOriginal model link: crestf411/L3.1-70B-sunfall-v0.6.1
Original model README below.
Sunfall (2024-07-31) v0.6.1 on top of Meta's Llama-3 70B Instruct.
NOTE: This model requires a slightly lower temperature than usual. Recommended starting point in Silly Tavern are:
General heuristic:
Mergers/fine-tuners: there is a LoRA of this model. Consider merging that instead of merging this model.
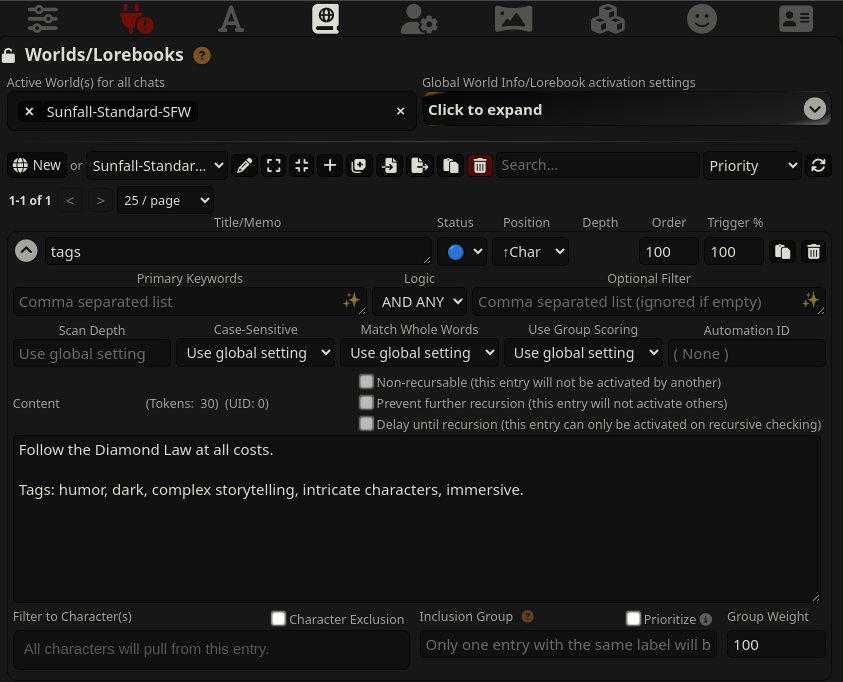
To use lore book tags (example), make sure you use Status: Blue (constant) and write e.g.
Follow the Diamond Law at all costs.

Tags: humor, dark, complex storytelling, intricate characters, immersive.
This model has been trained on context that mimics that of Silly Tavern's Llama3-instruct preset, with the following settings:
System Prompt:
You are an expert actor that can fully immerse yourself into any role given. You do not break character for any reason. Currently your role is {{char}}, which is described in detail below. As {{char}}, continue the exchange with {{user}}.
The card has also been trained on content which includes a narrator card, which was used when the content did not mainly revolve around two characters. Future versions will expand on this idea, so forgive the vagueness at this time.
(The Diamond Law is this, although new rules were added: https://files.catbox.moe/d15m3g.txt -- So far results are unclear, but the training was done with this phrase included, and the training data adheres to the law.)
The model has also been trained to do storywriting. The system message ends up looking something like this:
You are an expert storyteller, who can roleplay or write compelling stories. Follow the Diamond Law at all costs. Below is a scenario with character descriptions and content tags. Write a story based on this scenario.

Scenario: The story is about James, blabla.

James is an overweight 63 year old blabla.

Lucy: James's 62 year old wife.

Tags: tag1, tag2, tag3, ...
MMLU-Pro Benchmark: model overall is higher than the instruct base, but it loses in specific categories.
Llama3.1 70B Instruct base:

| overall | biology | business | chemistry | computer science | economics | engineering | health | history |  law  | math  | philosophy | physics | psychology | other |
| ------- | ------- | -------- | --------- | ---------------- | --------- | ----------- | ------ | ------- | ----- | ----- | ---------- | ------- | ---------- | ----- |
|   58.64 |   73.91 |    60.00 |     61.11 |            69.23 |     70.37 |       51.61 |  57.69 |   66.67 | 51.43 | 55.81 |      68.75 |   51.22 |      48.00 | 58.62 |
|     224 |      17 |       15 |        22 |                9 |        19 |          16 |     15 |       8 |    18 |    24 |         11 |      21 |         12 |    17 |
|     382 |      23 |       25 |        36 |               13 |        27 |          31 |     26 |      12 |    35 |    43 |         16 |      41 |         25 |    29 |

Sunfall v0.6.1:

| overall | biology | business | chemistry | computer science | economics | engineering | health | history |  law  | math  | philosophy | physics | psychology | other |
| ------- | ------- | -------- | --------- | ---------------- | --------- | ----------- | ------ | ------- | ----- | ----- | ---------- | ------- | ---------- | ----- |
|   60.73 |   78.26 |    60.00 |     55.56 |            69.23 |     70.37 |       64.52 |  65.38 |   75.00 | 42.86 | 62.79 |      68.75 |   56.10 |      56.00 | 51.72 |
|     232 |      18 |       15 |        20 |                9 |        19 |          20 |     17 |       9 |    15 |    27 |         11 |      23 |         14 |    15 |
|     382 |      23 |       25 |        36 |               13 |        27 |          31 |     26 |      12 |    35 |    43 |         16 |      41 |         25 |    29 |
The above benchmark output is with temp 0 and no other helping samplers. The model on its own is strong, but it gets more easily confused than the base instruct model.
Probably because I traumatized it with my vile dataset. Who knows.