Downloads · 30 days
372
4% of all-time downloads
NousResearch/Yarn-Llama-2-70b-32k
Yarn-Llama-2-70b-32k is a text generation model from NousResearch. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
Downloads · 30 days
372
4% of all-time downloads
All-time downloads
8.9K
Public
Repo size
138 GB
Likes
37
Public
Click a slice to open those files.
.bin138 GB · 100%
From the Hugging Face model README
The authors would like to thank LAION AI for their support of compute for this model. It was trained on the JUWELS supercomputer.
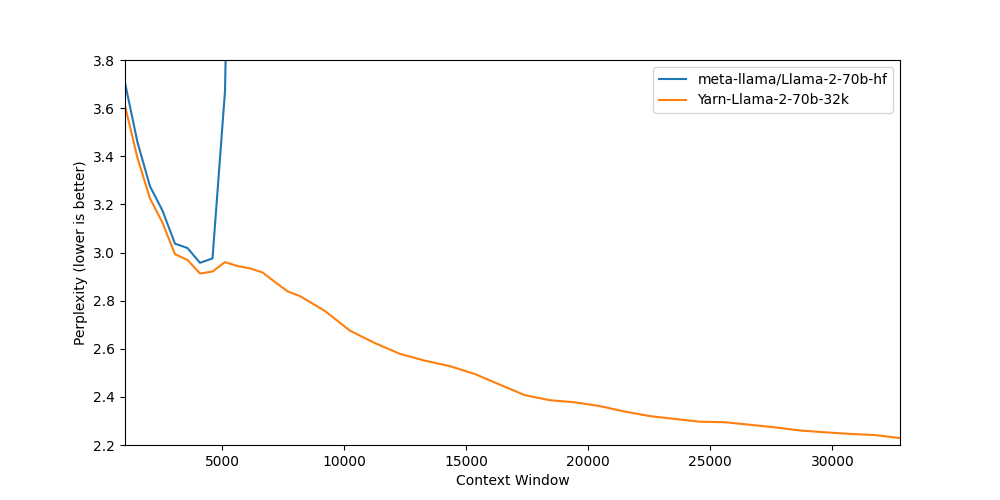
Nous-Yarn-Llama-2-70b-32k is a state-of-the-art language model for long context, further pretrained on long context data for 400 steps using the YaRN extension method. It is an extension of Llama-2-70b-hf and supports a 32k token context window.
To use, pass trust_remote_code=True when loading the model, for example
model = AutoModelForCausalLM.from_pretrained("NousResearch/Yarn-Llama-2-70b-32k",
  use_flash_attention_2=True,
  torch_dtype=torch.bfloat16,
  device_map="auto",
  trust_remote_code=True)
In addition you will need to use the latest version of transformers (until 4.35 comes out)
pip install git+https://github.com/huggingface/transformers
Long context benchmarks:
| Model | Context Window | 1k PPL | 2k PPL | 4k PPL | 8k PPL | 16k PPL | 32k PPL |
|---|---|---|---|---|---|---|---|
| Llama-2-70b-hf | 4k | 3.71 | 3.27 | 2.96 | - | - | - |
| Yarn-Llama-2-70b-32k | 32k | 3.61 | 3.22 | 2.91 | 2.82 | 2.45 | 2.23 |
Short context benchmarks showing that quality degradation is minimal:
| Model | Context Window | ARC-c | MMLU | Truthful QA |
|---|---|---|---|---|
| Llama-2-70b-hf | 4k | 67.32 | 69.83 | 44.92 |
| Yarn-Llama-2-70b-32k | 32k | 67.41 | 68.84 | 46.14 |