
Downloads · 30 days
34
0% of all-time downloads
NVFP4/Qwen3-235B-A22B-Instruct-2507-FP4
Qwen3-235B-A22B-Instruct-2507-FP4 is a text generation model from NVFP4. Use it when you need the model to write or continue text. It is set up for Model Optimizer. The card lists the license as apache-2.0.
<a href="https://chat.qwen.ai/" target="blank" style="margin: 2px;" <img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle…
Downloads · 30 days
34
0% of all-time downloads
All-time downloads
19.9K
Public
Parameters
118B
134 GB on disk
Likes
4
Public
Click a slice to open those files.
.safetensors134 GB · 100%
How the weights are stored.
U8117B · 88%
From the Hugging Face model README
We introduce the updated version of the Qwen3-235B-A22B non-thinking mode, named Qwen3-235B-A22B-Instruct-2507, featuring the following key enhancements:
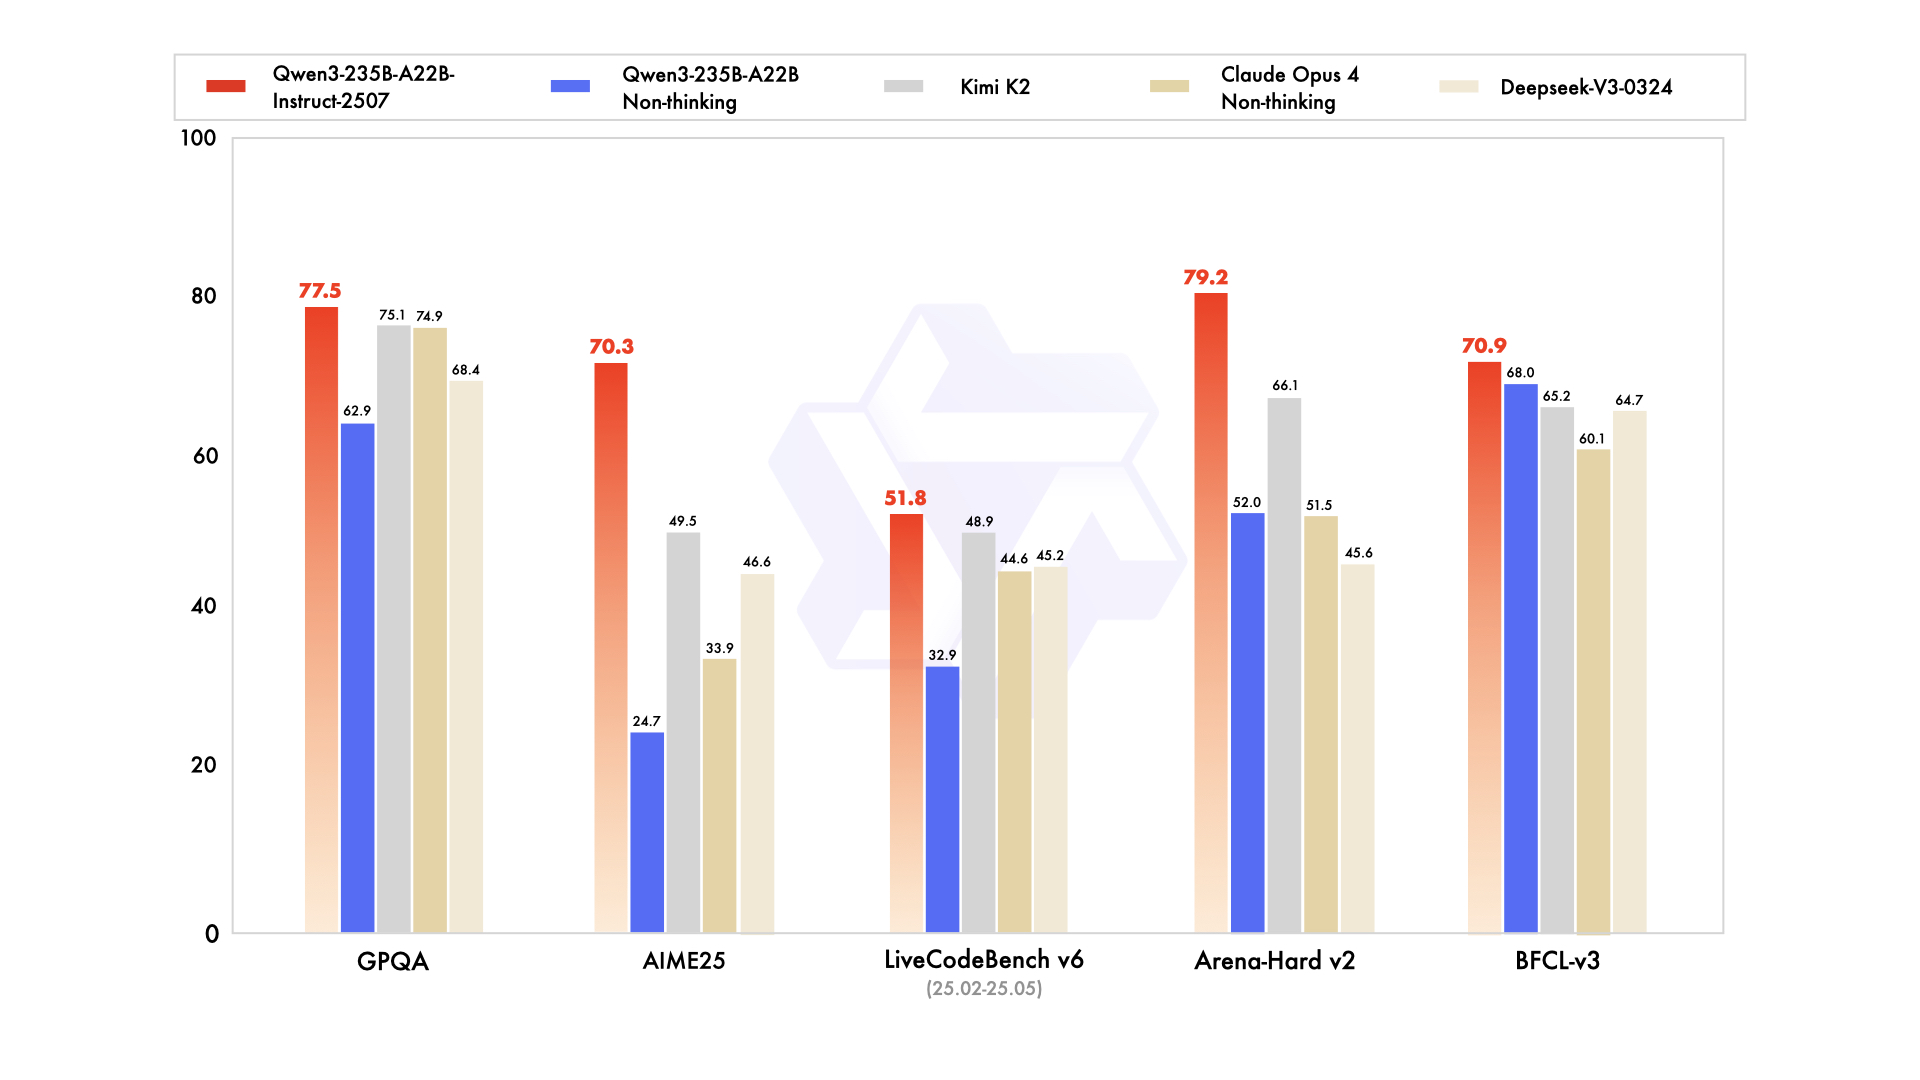
Qwen3-235B-A22B-Instruct-2507 has the following features:
NOTE: This model supports only non-thinking mode and does not generate <think></think> blocks in its output. Meanwhile, specifying enable_thinking=False is no longer required.
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our blog, GitHub, and Documentation.
| Deepseek-V3-0324 | GPT-4o-0327 | Claude Opus 4 Non-thinking | Kimi K2 | Qwen3-235B-A22B Non-thinking | Qwen3-235B-A22B-Instruct-2507 | |
|---|---|---|---|---|---|---|
| Knowledge | ||||||
| MMLU-Pro | 81.2 | 79.8 | 86.6 | 81.1 | 75.2 | 83.0 |
| MMLU-Redux | 90.4 | 91.3 | 94.2 | 92.7 | 89.2 | 93.1 |
| GPQA | 68.4 | 66.9 | 74.9 | 75.1 | 62.9 | 77.5 |
| SuperGPQA | 57.3 | 51.0 | 56.5 | 57.2 | 48.2 | 62.6 |
| SimpleQA | 27.2 | 40.3 | 22.8 | 31.0 | 12.2 | 54.3 |
| CSimpleQA | 71.1 | 60.2 | 68.0 | 74.5 | 60.8 | 84.3 |
| Reasoning | ||||||
| AIME25 | 46.6 | 26.7 | 33.9 | 49.5 | 24.7 | 70.3 |
| HMMT25 | 27.5 | 7.9 | 15.9 | 38.8 | 10.0 | 55.4 |
| ARC-AGI | 9.0 | 8.8 | 30.3 | 13.3 | 4.3 | 41.8 |
| ZebraLogic | 83.4 | 52.6 | - | 89.0 | 37.7 | 95.0 |
| LiveBench 20241125 | 66.9 | 63.7 | 74.6 | 76.4 | 62.5 | 75.4 |
| Coding | ||||||
| LiveCodeBench v6 (25.02-25.05) | 45.2 | 35.8 | 44.6 | 48.9 | 32.9 | 51.8 |
| MultiPL-E | 82.2 | 82.7 | 88.5 | 85.7 | 79.3 | 87.9 |
| Aider-Polyglot | 55.1 | 45.3 | 70.7 | 59.0 | 59.6 | 57.3 |
| Alignment | ||||||
| IFEval | 82.3 | 83.9 | 87.4 | 89.8 | 83.2 | 88.7 |
| Arena-Hard v2* | 45.6 | 61.9 | 51.5 | 66.1 | 52.0 | 79.2 |
| Creative Writing v3 | 81.6 | 84.9 | 83.8 | 88.1 | 80.4 | 87.5 |
| WritingBench | 74.5 | 75.5 | 79.2 | 86.2 | 77.0 | 85.2 |
| Agent | ||||||
| BFCL-v3 | 64.7 | 66.5 | 60.1 | 65.2 | 68.0 | 70.9 |
| TAU-Retail | 49.6 | 60.3# | 81.4 | 70.7 | 65.2 | 71.3 |
| TAU-Airline | 32.0 | 42.8# | 59.6 | 53.5 | 32.0 | 44.0 |
| Multilingualism | ||||||
| MultiIF | 66.5 | 70.4 | - | 76.2 | 70.2 | 77.5 |
| MMLU-ProX | 75.8 | 76.2 | - | 74.5 | 73.2 | 79.4 |
| INCLUDE | 80.1 | 82.1 | - | 76.9 | 75.6 | 79.5 |
| PolyMATH | 32.2 | 25.5 | 30.0 | 44.8 | 27.0 | 50.2 |
*: For reproducibility, we report the win rates evaluated by GPT-4.1.
#: Results were generated using GPT-4o-20241120, as access to the native function calling API of GPT-4o-0327 was unavailable.
The code of Qwen3-MoE has been in the latest Hugging Face transformers and we advise you to use the latest version of transformers.
With transformers<4.51.0, you will encounter the following error:
KeyError: 'qwen3_moe'
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Qwen/Qwen3-235B-A22B-Instruct-2507"

# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)

# prepare the model input
prompt = "Give me a short introduction to large language model."
messages = [
    {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

# conduct text completion
generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=16384
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()

content = tokenizer.decode(output_ids, skip_special_tokens=True)

print("content:", content)
For deployment, you can use sglang>=0.4.6.post1 or vllm>=0.8.5 or to create an OpenAI-compatible API endpoint:
python -m sglang.launch_server --model-path Qwen/Qwen3-235B-A22B-Instruct-2507 --tp 8 --context-length 262144
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507 --tensor-parallel-size 8 --max-model-len 262144
Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as 32,768.
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
Qwen3 excels in tool calling capabilities. We recommend using Qwen-Agent to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
from qwen_agent.agents import Assistant

# Define LLM
llm_cfg = {
    'model': 'Qwen3-235B-A22B-Instruct-2507',

    # Use a custom endpoint compatible with OpenAI API:
    'model_server': 'http://localhost:8000/v1',  # api_base
    'api_key': 'EMPTY',
}

# Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            'time': {
                'command': 'uvx',
                'args': ['mcp-server-time', '--local-timezone=Asia/Shanghai']
            },
            "fetch": {
                "command": "uvx",
                "args": ["mcp-server-fetch"]
            }
        }
    },
  'code_interpreter',  # Built-in tools
]

# Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

# Streaming generation
messages = [{'role': 'user', 'content': 'https://qwenlm.github.io/blog/ Introduce the latest developments of Qwen'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
Temperature=0.7, TopP=0.8, TopK=20, and MinP=0.presence_penalty parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.Adequate Output Length: We recommend using an output length of 16,384 tokens for most queries, which is adequate for instruct models.
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
answer field with only the choice letter, e.g., "answer": "C"."If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}