
Downloads · 30 days
437
8% of all-time downloads
Mungert/typhoon-ocr-7b-GGUF
typhoon-ocr-7b-GGUF is a machine learning model from Mungert. Use it for the machine learning task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
This model was generated using llama.cpp at commit 92ecdcc0.
Downloads · 30 days
437
8% of all-time downloads
All-time downloads
5.4K
Public
Repo size
138 GB
Likes
0
Public
Click a slice to open those files.
.gguf138 GB · 100%
From the Hugging Face model README
This model was generated using llama.cpp at commit 92ecdcc0.
Our latest quantization method introduces precision-adaptive quantization for ultra-low-bit models (1-2 bit), with benchmark-proven improvements on Llama-3-8B. This approach uses layer-specific strategies to preserve accuracy while maintaining extreme memory efficiency.
All tests conducted on Llama-3-8B-Instruct using:
| Quantization | Standard PPL | DynamicGate PPL | Δ PPL | Std Size | DG Size | Δ Size | Std Speed | DG Speed |
|---|---|---|---|---|---|---|---|---|
| IQ2_XXS | 11.30 | 9.84 | -12.9% | 2.5G | 2.6G | +0.1G | 234s | 246s |
| IQ2_XS | 11.72 | 11.63 | -0.8% | 2.7G | 2.8G | +0.1G | 242s | 246s |
| IQ2_S | 14.31 | 9.02 | -36.9% | 2.7G | 2.9G | +0.2G | 238s | 244s |
| IQ1_M | 27.46 | 15.41 | -43.9% | 2.2G | 2.5G | +0.3G | 206s | 212s |
| IQ1_S | 53.07 | 32.00 | -39.7% | 2.1G | 2.4G | +0.3G | 184s | 209s |
Key:
Key Improvements:
Tradeoffs:
📌 Fitting models into GPU VRAM
✔ Memory-constrained deployments
✔ Cpu and Edge Devices where 1-2bit errors can be tolerated
✔ Research into ultra-low-bit quantization
Selecting the correct model format depends on your hardware capabilities and memory constraints.
📌 Use BF16 if:
✔ Your hardware has native BF16 support (e.g., newer GPUs, TPUs).
✔ You want higher precision while saving memory.
✔ You plan to requantize the model into another format.
📌 Avoid BF16 if:
❌ Your hardware does not support BF16 (it may fall back to FP32 and run slower).
❌ You need compatibility with older devices that lack BF16 optimization.
📌 Use F16 if:
✔ Your hardware supports FP16 but not BF16.
✔ You need a balance between speed, memory usage, and accuracy.
✔ You are running on a GPU or another device optimized for FP16 computations.
📌 Avoid F16 if:
❌ Your device lacks native FP16 support (it may run slower than expected).
❌ You have memory limitations.
Quantization reduces model size and memory usage while maintaining as much accuracy as possible.
📌 Use Quantized Models if:
✔ You are running inference on a CPU and need an optimized model.
✔ Your device has low VRAM and cannot load full-precision models.
✔ You want to reduce memory footprint while keeping reasonable accuracy.
📌 Avoid Quantized Models if:
❌ You need maximum accuracy (full-precision models are better for this).
❌ Your hardware has enough VRAM for higher-precision formats (BF16/F16).
These models are optimized for extreme memory efficiency, making them ideal for low-power devices or large-scale deployments where memory is a critical constraint.
IQ3_XS: Ultra-low-bit quantization (3-bit) with extreme memory efficiency.
IQ3_S: Small block size for maximum memory efficiency.
IQ3_M: Medium block size for better accuracy than IQ3_S.
Q4_K: 4-bit quantization with block-wise optimization for better accuracy.
Q4_0: Pure 4-bit quantization, optimized for ARM devices.
| Model Format | Precision | Memory Usage | Device Requirements | Best Use Case |
|---|---|---|---|---|
| BF16 | Highest | High | BF16-supported GPU/CPUs | High-speed inference with reduced memory |
| F16 | High | High | FP16-supported devices | GPU inference when BF16 isn't available |
| Q4_K | Medium Low | Low | CPU or Low-VRAM devices | Best for memory-constrained environments |
| Q6_K | Medium | Moderate | CPU with more memory | Better accuracy while still being quantized |
| Q8_0 | High | Moderate | CPU or GPU with enough VRAM | Best accuracy among quantized models |
| IQ3_XS | Very Low | Very Low | Ultra-low-memory devices | Extreme memory efficiency and low accuracy |
| Q4_0 | Low | Low | ARM or low-memory devices | llama.cpp can optimize for ARM devices |
typhoon-ocr-7b-bf16.gguftyphoon-ocr-7b-f16.gguftyphoon-ocr-7b-bf16-q8_0.gguftyphoon-ocr-7b-f16-q8_0.gguftyphoon-ocr-7b-q4_k.gguftyphoon-ocr-7b-q4_k_s.gguftyphoon-ocr-7b-q6_k.gguftyphoon-ocr-7b-q8_0.gguftyphoon-ocr-7b-iq3_xs.gguftyphoon-ocr-7b-iq3_m.gguftyphoon-ocr-7b-q4_0.gguf❤ Please click "Like" if you find this useful!
Help me test my AI-Powered Network Monitor Assistant with quantum-ready security checks:
👉 Quantum Network Monitor
💬 How to test:
Choose an AI assistant type:
TurboLLM (GPT-4o-mini)HugLLM (Hugginface Open-source)TestLLM (Experimental CPU-only)I’m pushing the limits of small open-source models for AI network monitoring, specifically:
🟡 TestLLM – Current experimental model (llama.cpp on 2 CPU threads):
🟢 TurboLLM – Uses gpt-4o-mini for:
🔵 HugLLM – Latest Open-source models:
"Give me info on my websites SSL certificate""Check if my server is using quantum safe encyption for communication""Run a comprehensive security audit on my server"I fund the servers used to create these model files, run the Quantum Network Monitor service, and pay for inference from Novita and OpenAI—all out of my own pocket. All the code behind the model creation and the Quantum Network Monitor project is open source. Feel free to use whatever you find helpful.
If you appreciate the work, please consider buying me a coffee ☕. Your support helps cover service costs and allows me to raise token limits for everyone.
I'm also open to job opportunities or sponsorship.
Thank you! 😊
Typhoon-OCR-7B: A bilingual document parsing model built specifically for real-world documents in Thai and English inspired by models like olmOCR based on Qwen2.5-VL-Instruction.
Try our demo available on Demo
Code / Examples available on Github
Release Blog available on OpenTyphoon Blog
*Remark: This model is intended to be used with a specific prompt only; it will not work with any other prompts.
1. Structured Documents: Financial reports, Academic papers, Books, Government forms
Output format:
Each figure undergoes multi-layered interpretation:
2. Layout-Heavy & Informal Documents: Receipts, Menus papers, Tickets, Infographics
Output format:
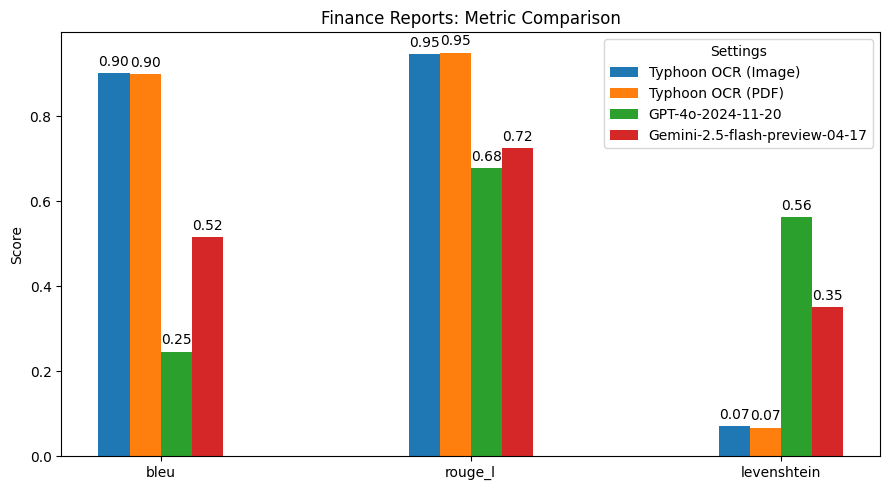
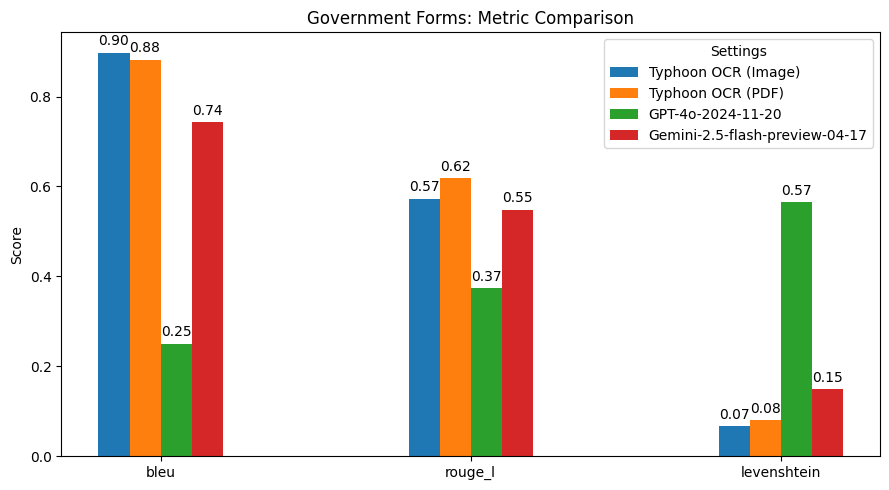
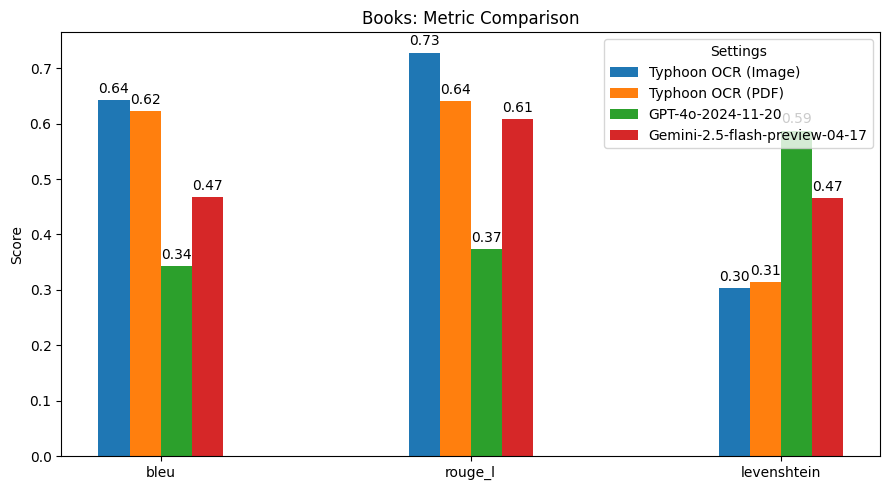
Typhoon OCR outperforms both GPT-4o and Gemini 2.5 Flash in Thai document understanding, particularly on documents with complex layouts and mixed-language content. However, in the Thai books benchmark, performance slightly declined due to the high frequency and diversity of embedded figures. These images vary significantly in type and structure, which poses challenges for our current figure tag parsing. This highlights a potential area for future improvement—specifically, in enhancing the model's image understanding capabilities. For this version, our primary focus has been on achieving high-quality OCR for both English and Thai text. Future releases may extend support to more advanced image analysis and figure interpretation.
(Recommended): Full inference code available on Colab
(Recommended): Using Typhoon-OCR Package
pip install typhoon-ocr
from typhoon_ocr import ocr_document

# please set env TYPHOON_OCR_API_KEY or OPENAI_API_KEY to use this function
markdown = ocr_document("test.png")
print(markdown)
Run Manually
Below is a partial snippet. You can run inference using either the API or a local model.
API:
from typing import Callable
from openai import OpenAI
from PIL import Image
from typhoon_ocr.ocr_utils import render_pdf_to_base64png, get_anchor_text

PROMPTS_SYS = {
    "default": lambda base_text: (f"Below is an image of a document page along with its dimensions. "
        f"Simply return the markdown representation of this document, presenting tables in markdown format as they naturally appear.\n"
        f"If the document contains images, use a placeholder like dummy.png for each image.\n"
        f"Your final output must be in JSON format with a single key `natural_text` containing the response.\n"
        f"RAW_TEXT_START\n{base_text}\nRAW_TEXT_END"),
    "structure": lambda base_text: (
        f"Below is an image of a document page, along with its dimensions and possibly some raw textual content previously extracted from it. "
        f"Note that the text extraction may be incomplete or partially missing. Carefully consider both the layout and any available text to reconstruct the document accurately.\n"
        f"Your task is to return the markdown representation of this document, presenting tables in HTML format as they naturally appear.\n"
        f"If the document contains images or figures, analyze them and include the tag <figure>IMAGE_ANALYSIS</figure> in the appropriate location.\n"
        f"Your final output must be in JSON format with a single key `natural_text` containing the response.\n"
        f"RAW_TEXT_START\n{base_text}\nRAW_TEXT_END"
    ),
}

def get_prompt(prompt_name: str) -> Callable[[str], str]:
    """
    Fetches the system prompt based on the provided PROMPT_NAME.

    :param prompt_name: The identifier for the desired prompt.
    :return: The system prompt as a string.
    """
    return PROMPTS_SYS.get(prompt_name, lambda x: "Invalid PROMPT_NAME provided.")


# Render the first page to base64 PNG and then load it into a PIL image.
image_base64 = render_pdf_to_base64png(filename, page_num, target_longest_image_dim=1800)
image_pil = Image.open(BytesIO(base64.b64decode(image_base64)))

# Extract anchor text from the PDF (first page)
anchor_text = get_anchor_text(filename, page_num, pdf_engine="pdfreport", target_length=8000)

# Retrieve and fill in the prompt template with the anchor_text
prompt_template_fn = get_prompt(task_type)
PROMPT = prompt_template_fn(anchor_text)

messages = [{
        "role": "user",
        "content": [
            {"type": "text", "text": PROMPT},
            {"type": "image_url", "image_url": {"url": f"data:image/png;base64,{image_base64}"}},
        ],
    }]
# send messages to openai compatible api
openai = OpenAI(base_url="https://api.opentyphoon.ai/v1", api_key="TYPHOON_API_KEY")
response = openai.chat.completions.create(
          model="typhoon-ocr-preview",
          messages=messages,
          max_tokens=16384,
          temperature=0.1,
          top_p=0.6,
          extra_body={
              "repetition_penalty": 1.2,
          },
      )
text_output = response.choices[0].message.content
print(text_output)
Local Model (GPU Required):
# Initialize the model
model = Qwen2_5_VLForConditionalGeneration.from_pretrained("scb10x/typhoon-ocr-7b", torch_dtype=torch.bfloat16 ).eval()
processor = AutoProcessor.from_pretrained("scb10x/typhoon-ocr-7b")

device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model.to(device)
# Apply the chat template and processor
text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
main_image = Image.open(BytesIO(base64.b64decode(image_base64)))

inputs = processor(
          text=[text],
          images=[main_image],
          padding=True,
          return_tensors="pt",
      )
inputs = {key: value.to(device) for (key, value) in inputs.items()}

# Generate the output
output = model.generate(
                  **inputs,
                  temperature=0.1,
                  max_new_tokens=12000,
                  num_return_sequences=1,
                  repetition_penalty=1.2,
                  do_sample=True,
              )
# Decode the output
prompt_length = inputs["input_ids"].shape[1]
new_tokens = output[:, prompt_length:]
text_output = processor.tokenizer.batch_decode(
          new_tokens, skip_special_tokens=True
      )
print(text_output[0])
This model only works with the specific prompts defined below, where {base_text} refers to information extracted from the PDF metadata using the get_anchor_text function from the typhoon-ocr package. It will not function correctly with any other prompts.
PROMPTS_SYS = {
    "default": lambda base_text: (f"Below is an image of a document page along with its dimensions. "
        f"Simply return the markdown representation of this document, presenting tables in markdown format as they naturally appear.\n"
        f"If the document contains images, use a placeholder like dummy.png for each image.\n"
        f"Your final output must be in JSON format with a single key `natural_text` containing the response.\n"
        f"RAW_TEXT_START\n{base_text}\nRAW_TEXT_END"),
    "structure": lambda base_text: (
        f"Below is an image of a document page, along with its dimensions and possibly some raw textual content previously extracted from it. "
        f"Note that the text extraction may be incomplete or partially missing. Carefully consider both the layout and any available text to reconstruct the document accurately.\n"
        f"Your task is to return the markdown representation of this document, presenting tables in HTML format as they naturally appear.\n"
        f"If the document contains images or figures, analyze them and include the tag <figure>IMAGE_ANALYSIS</figure> in the appropriate location.\n"
        f"Your final output must be in JSON format with a single key `natural_text` containing the response.\n"
        f"RAW_TEXT_START\n{base_text}\nRAW_TEXT_END"
    ),
}
We suggest using the following generation parameters. Since this is an OCR model, we do not recommend using a high temperature. Make sure the temperature is set to 0 or 0.1, not higher.
temperature=0.1,
top_p=0.6,
repetition_penalty: 1.2
This is a task-specific model intended to be used only with the provided prompts. It does not include any guardrails or VQA capability. Due to the nature of large language models (LLMs), a certain level of hallucination may occur. We recommend that developers carefully assess these risks in the context of their specific use case.
https://twitter.com/opentyphoon
@misc{typhoon2,
      title={Typhoon 2: A Family of Open Text and Multimodal Thai Large Language Models},
      author={Kunat Pipatanakul and Potsawee Manakul and Natapong Nitarach and Warit Sirichotedumrong and Surapon Nonesung and Teetouch Jaknamon and Parinthapat Pengpun and Pittawat Taveekitworachai and Adisai Na-Thalang and Sittipong Sripaisarnmongkol and Krisanapong Jirayoot and Kasima Tharnpipitchai},
      year={2024},
      eprint={2412.13702},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2412.13702},
}