
Downloads · 30 days
123
0% of all-time downloads
MILVLG/imp-v1-3b
imp-v1-3b is a text generation model from MILVLG. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
A very small man can cast a very large shadow. ——George R.R. Martin, A Clash of Kings
Downloads · 30 days
123
0% of all-time downloads
All-time downloads
39K
Public
Parameters
3.2B
31.9 GB on disk
Likes
200
Public
Click a slice to open those files.
.safetensors6.4 GB · 100%
From the Hugging Face model README
A very small man can cast a very large shadow.
——George R.R. Martin, A Clash of Kings
[Technical report (coming soon)] [Demo] [Github]
The Imp project aims to provide a family of a strong multimodal small language models (MSLMs). Our imp-v1-3b is a strong MSLM with only 3B parameters, which is build upon a small yet powerful SLM Phi-2 (2.7B) and a powerful visual encoder SigLIP (0.4B), and trained on the LLaVA-v1.5 training set.
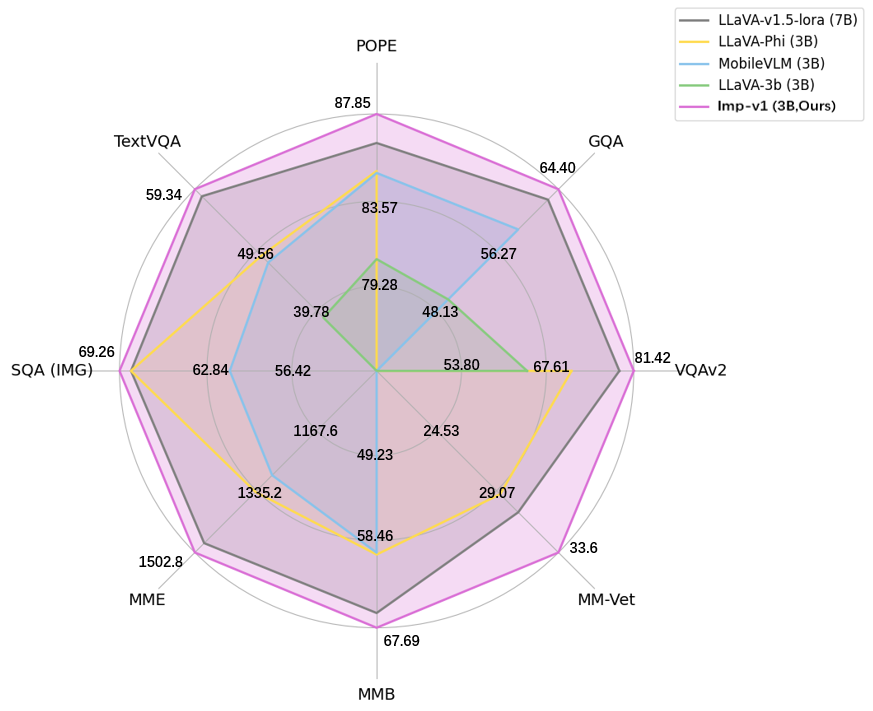
As shown in the image below, imp-v1-3b significantly outperforms the counterparts of similar model sizes, and even achieves slightly better performance than the strong LLaVA-7B model on various multimodal benchmarks.
We release our model weights and provide an example below to run our model . Detailed technical report and corresponding training/evaluation code will be released soon on our GitHub repo. We will persistently improve our model and release the next versions to further improve model performance :)
Install dependencies
pip install transformers # latest version is ok, but we recommend v4.39.2
pip install -q pillow accelerate einops
You can use the following code for model inference. The format of text instruction is similar to LLaVA. A Colab page to run this example is provided here. Note that the example can only be run on GPUs currently.
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer
from PIL import Image

torch.set_default_device("cuda")

#Create model
model = AutoModelForCausalLM.from_pretrained(
    "MILVLG/imp-v1-3b",
    torch_dtype=torch.float16,
    device_map="auto",
    trust_remote_code=True)
tokenizer = AutoTokenizer.from_pretrained("MILVLG/imp-v1-3b", trust_remote_code=True)

#Set inputs
text = "A chat between a curious user and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the user's questions. USER: <image>\nWhat are the colors of the bus in the image? ASSISTANT:"
image = Image.open("images/bus.jpg")

input_ids = tokenizer(text, return_tensors='pt').input_ids
image_tensor = model.image_preprocess(image)

#Generate the answer
output_ids = model.generate(
    input_ids,
    max_new_tokens=100,
    images=image_tensor,
    use_cache=True)[0]
print(tokenizer.decode(output_ids[input_ids.shape[1]:], skip_special_tokens=True).strip())
We conduct evaluation on 9 commonly-used benchmarks, including 5 academic VQA benchmarks and 4 popular MLLM benchmarks, to compare our Imp model with LLaVA (7B) and existing MSLMs of similar model sizes.
| Models | Size | VQAv2 | GQA | SQA(IMG) | TextVQA | POPE | MME(P) | MMB | MM-Vet |
|---|---|---|---|---|---|---|---|---|---|
| LLaVA-v1.5-lora | 7B | 79.10 | 63.00 | 68.40 | 58.20 | 86.40 | 1476.9 | 66.10 | 30.2 |
| TinyGPT-V | 3B | - | 33.60 | - | - | - | - | - | - |
| LLaVA-Phi | 3B | 71.40 | - | 68.40 | 48.60 | 85.00 | 1335.1 | 59.80 | 28.9 |
| MobileVLM | 3B | - | 59.00 | 61.00 | 47.50 | 84.90 | 1288.9 | 59.60 | - |
| MC-LLaVA-3b | 3B | 64.24 | 49.60 | - | 38.59 | 80.59 | - | - | - |
| Imp-v1 (ours) | 3B | 81.42 | 64.40 | 69.26 | 59.34 | 87.85 | 1502.8 | 67.69 | 33.6 |
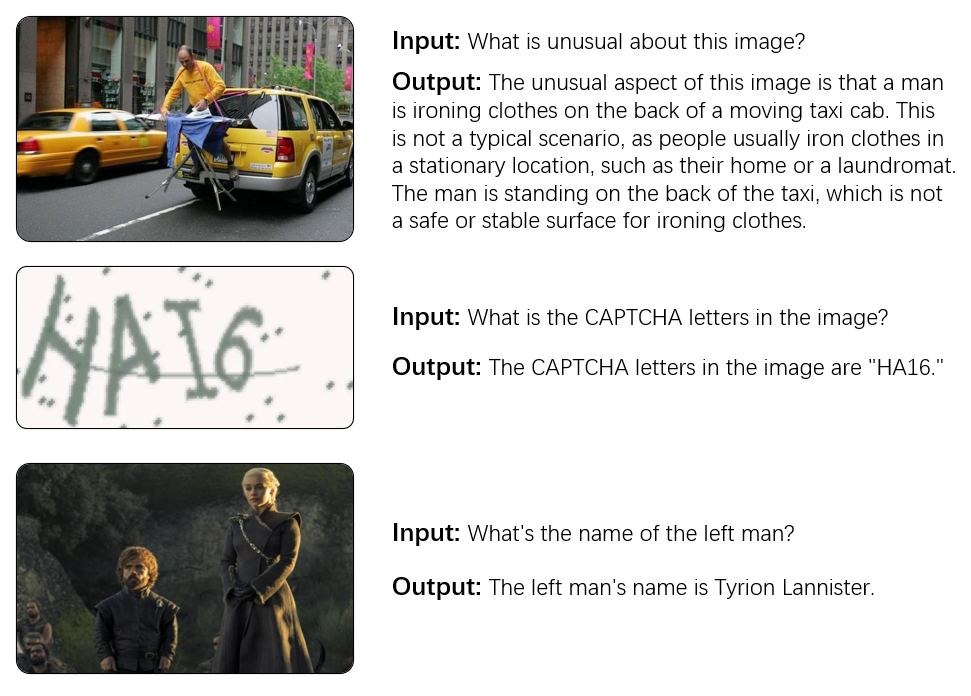
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.
This project is maintained by the MILVLG@Hangzhou Dianzi University (HDU) led by Prof. Zhou Yu and Jun Yu, and is mainly developed by Zhenwei Shao and Xuecheng Ouyang. We hope our model may serve as a strong baseline to inspire future research on MSLM, as well as its derivative applications on mobile devices and robots.
If you use our model or refer our work in your studies, please cite:
@article{imp2024,
  title={Imp: Highly Capable Large Multimodal Models for Mobile Devices},
  author={Shao, Zhenwei and Yu, Zhou and Yu, Jun and Ouyang, Xuecheng and Zheng, Lihao and Gai, Zhenbiao and Wang, Mingyang and Ding, Jiajun},
  journal={arXiv preprint arXiv:2405.12107},
  year={2024}
}