Downloads · 30 days
606
1% of all-time downloads
LeoLM/leo-mistral-hessianai-7b
leo-mistral-hessianai-7b is a text generation model from LeoLM. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
Meet LeoLM-Mistral, the first open and commercially available German Foundation Language Model built on Mistral 7b. Our models extend Llama-2's capabilities into German through continued pretraining on a large corpus…
Downloads · 30 days
606
1% of all-time downloads
All-time downloads
88.1K
Public
Repo size
29 GB
Likes
30
Public
Click a slice to open those files.
.bin14.5 GB · 100%
From the Hugging Face model README
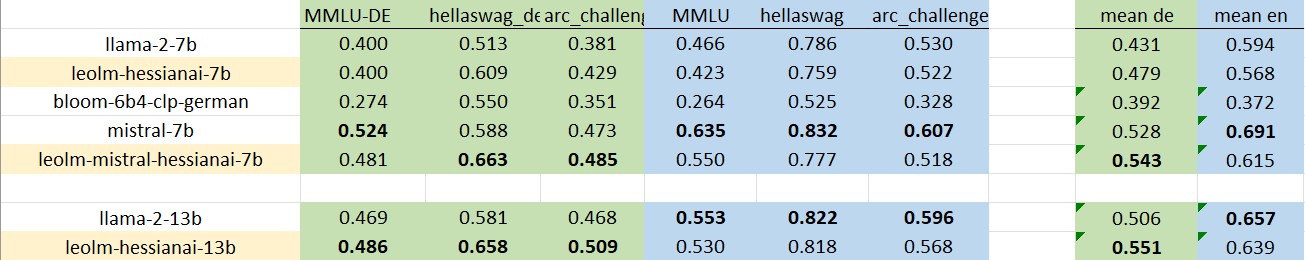
Meet LeoLM-Mistral, the first open and commercially available German Foundation Language Model built on Mistral 7b.
Our models extend Llama-2's capabilities into German through continued pretraining on a large corpus of German-language and mostly locality specific text.
Thanks to a compute grant at HessianAI's new supercomputer 42, we release three foundation models trained with 8k context length.
LeoLM/leo-mistral-hessianai-7b under Apache 2.0 and
LeoLM/leo-hessianai-7b and LeoLM/leo-hessianai-13b under the Llama-2 community license (70b also coming soon! 👀).
With this release, we hope to bring a new wave of opportunities to German open-source and commercial LLM research and accelerate adoption.
Read our blog post or our paper (preprint coming soon) for more details!
A project by Björn Plüster and Christoph Schuhmann in collaboration with LAION and HessianAI.
First install direct dependencies:
pip install transformers torch accelerate
If you want faster inference using flash-attention2, you need to install these dependencies:
pip install packaging ninja
pip install flash-attn
Then load the model in transformers:
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

model = AutoModelForCausalLM.from_pretrained(
    model="LeoLM/leo-mistral-hessianai-7b",
    device_map="auto",
    torch_dtype=torch.bfloat16,
    use_flash_attn_2=True # optional
)
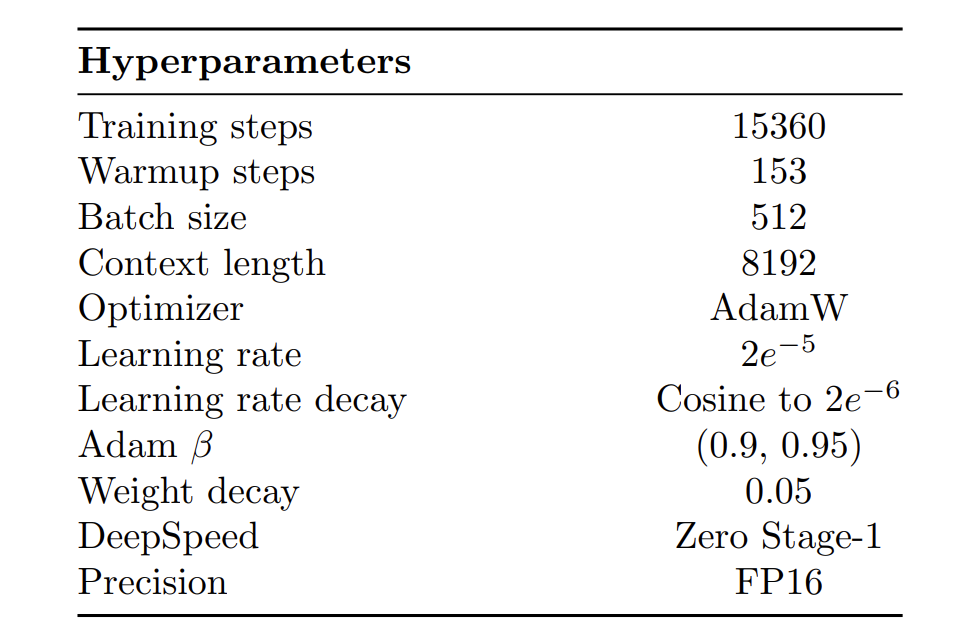
Note that for Mistral training, we changed learning rate to 1e-5 going down to 1e-6. We also used Zero stage 3 and bfloat16 dtype.