
Downloads · 30 days
267
41% of all-time downloads
KoalaAI/Bamboo-Nano
Bamboo-Nano is a text generation model from KoalaAI. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as openrail.
This is a WIP foundational (aka base) model trained only on public domain (CC0) datasets, primarily in the English language. The primary goal of this model is to see how a limited tokenizer influences model training s…
Downloads · 30 days
267
41% of all-time downloads
All-time downloads
644
Public
Parameters
145M
579 MB on disk
Likes
2
Public
Click a slice to open those files.
.safetensors579 MB · 100%
From the Hugging Face model README
This is a WIP foundational (aka base) model trained only on public domain (CC0) datasets, primarily in the English language. The primary goal of this model is to see how a limited tokenizer influences model training speed & coherency.
Further training is planned & ongoing, but currently no multi-language datasets are in use or planned; though this may change in the future and the current datasets can contain languages other than English.
Though the training data of this model is CC0, the model itself is not. The model is released under the OpenRAIL license, as tagged.
As mentioned, a few updates are planned:
This table tracks the performance of our model on various tasks over time. The metric used is 'acc'.
| Date (YYYY-MM-DD) | arc_easy | hellaswag | sglue_rte | truthfulqa | preplexity (wikitext) | Avg |
|---|
Our tokenizer was trained from scratch on 500,000 samples from the Openwebtext dataset. For variation, we also included 250,000 samples from our GitHub-CC0 dataset, in the hopes that code would be tokenized properly despite our small vocab_size. Like Mistral, we use the LlamaTokenizerFast as our tokenizer class; in legacy mode.
Our vocabulary size is 5100 tokens. A far cry from larger model's sizes of typically 32000 or greater.
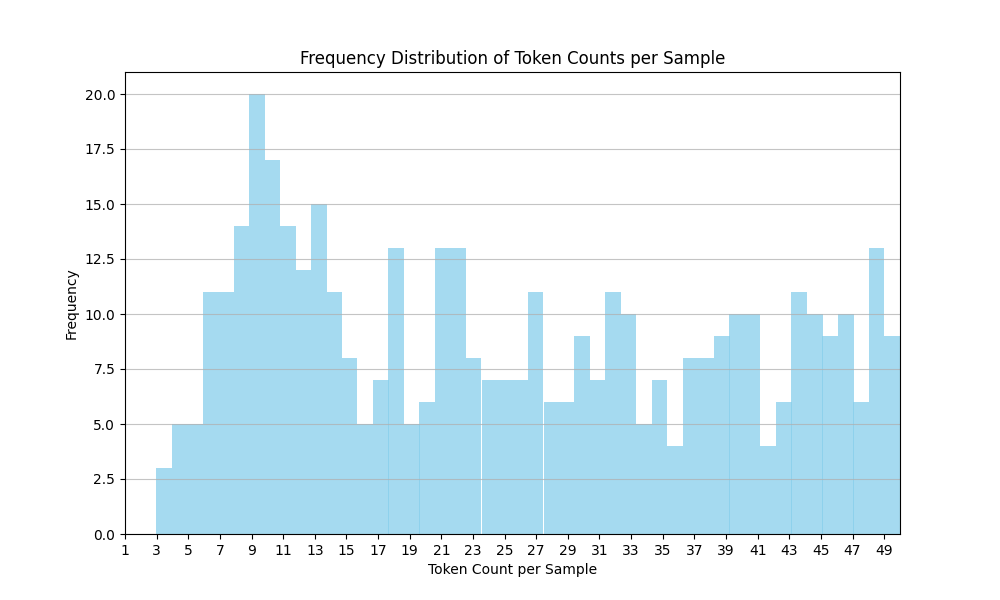
A histogram of the token counts per sample in the dataset reveals some interesting insights:
When comparing the token count statistics to another dataset, OpenWebText (OWT), some key differences emerge:
The significantly higher average token length and token-to-character ratio for the GitHub dataset compared to OWT indicates the GitHub samples contain much longer and more verbose text. This aligns with the bimodal distribution and long tail observed in the histogram, which suggests the dataset contains a mix of both concise and more complex, lengthier text samples.
This analysis highlights the challenges of using a limited vocabulary tokenizer on a diverse dataset with varying text complexity. The bimodal distribution and long tail in the token count histogram suggest the tokenizer may not be optimally suited for the full range of text samples, leading to increased token counts for some inputs. Further investigation into the dataset composition and tokenizer performance may be warranted to understand how the vocabulary size impacts the model's ability to efficiently represent the text.