
Downloads · 30 days
301
33% of all-time downloads
KoalaAI/Bamboo-400M
Bamboo-400M is a text generation model from KoalaAI. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as openrail.
This is a WIP foundational (aka base) model trained only on public domain (CC0) datasets, primarily in the English language. Further training is planned & ongoing, but currently no multi-language datasets are in use o…
Downloads · 30 days
301
33% of all-time downloads
All-time downloads
917
Public
Parameters
416M
8.3 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors1.7 GB · 100%
From the Hugging Face model README
This is a WIP foundational (aka base) model trained only on public domain (CC0) datasets, primarily in the English language.
Further training is planned & ongoing, but currently no multi-language datasets are in use or planned; though this may change in the future and the current datasets can contain languages other than English.
Though the training data of this model is CC0, the model itself is not. The model is released under the OpenRAIL license, as tagged.
As mentioned, a few updates are planned:
This table tracks the performance of our model on various tasks over time. The metric used is 'acc'.
| Date (YYYY-MM-DD) | arc_easy | hellaswag | sglue_rte | truthfulqa | Avg |
|---|---|---|---|---|---|
| 2024-07-30-2 | 28.91% ± 0.94% | 25.32% ± 0.43% | 50.54% ± 3.01% | 41.31% ± 1.16% | 36.52% |
| 2024-07-30 | 29.50% ± 0.94% | 25.36% ± 0.43% | 50.54% ± 3.01% | 41.07% ± 1.16% | 36.60% |
| 2024-07-29 | 32.24% ± 0.96% | 25.74% ± 0.44% | 47.29% ± 3.01% | 39.91% ± 1.11% | 36.30% |
| 2024-07-27 | 27.40% ± 0.92% | 25.52% ± 0.44% | 52.71% ± 3.01% | 39.52% ± 1.11% | 36.29% |
Our tokenizer was trained from scratch on 500,000 samples from the Openwebtext dataset. Like Mistral, we use the LlamaTokenizerFast as our tokenizer class; in legacy mode.
The histogram below illustrates the distribution of token counts per sample in our Mistral tokenizer, trained on 500,000 samples. This analysis provides insights into the tokenizer's behavior and its ability to handle various sentence lengths. The histogram was created using 10,000 samples of tokenization.
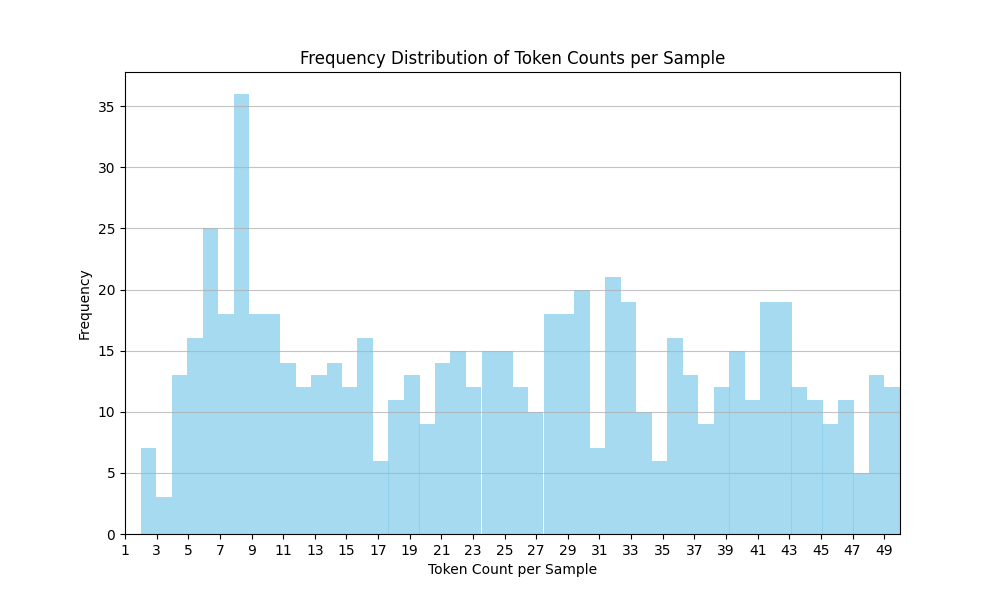
Key Observations:
Overall: The tokenizer demonstrates a balanced approach, predominantly producing shorter sequences while still accommodating longer and more complex sentences. This balance promotes both computational efficiency and the ability to capture meaningful context.
Further Analysis: While the tokenizer performs well overall, further analysis of the peak at 7 tokens and the lower frequency of very short sequences (1-3 tokens) could provide additional insights into its behavior and potential areas for refinement.
Theory On 7-token peak: Since English sentences have an average of 15-20 words, our tokenizer may be splitting them into 7-9 tokens, which would possibly explain this peak.