
Downloads · 30 days
8
31% of all-time downloads
Jingya/Ghibli-Diffusion-Neuronx
Ghibli-Diffusion-Neuronx is a text-to-image model from Jingya. Use it when you need an image from a text prompt. It is set up for diffusers. The card lists the license as creativeml-openrail-m.
This is the fine-tuned Stable Diffusion model trained on images from modern anime feature films from Studio Ghibli. Use the tokens ghibli style in your prompts for the effect.
Downloads · 30 days
8
31% of all-time downloads
All-time downloads
26
Public
Repo size
5.2 GB
Likes
0
Public
Click a slice to open those files.
.neuron5.2 GB · 100%
From the Hugging Face model README
nitrosocke/Ghibli-Diffusion] and compiled on Inf2 neuronx devices with 🤗 optimum-neuron.This is the fine-tuned Stable Diffusion model trained on images from modern anime feature films from Studio Ghibli. Use the tokens ghibli style in your prompts for the effect.
If you enjoy my work and want to test new models before release, please consider supporting me
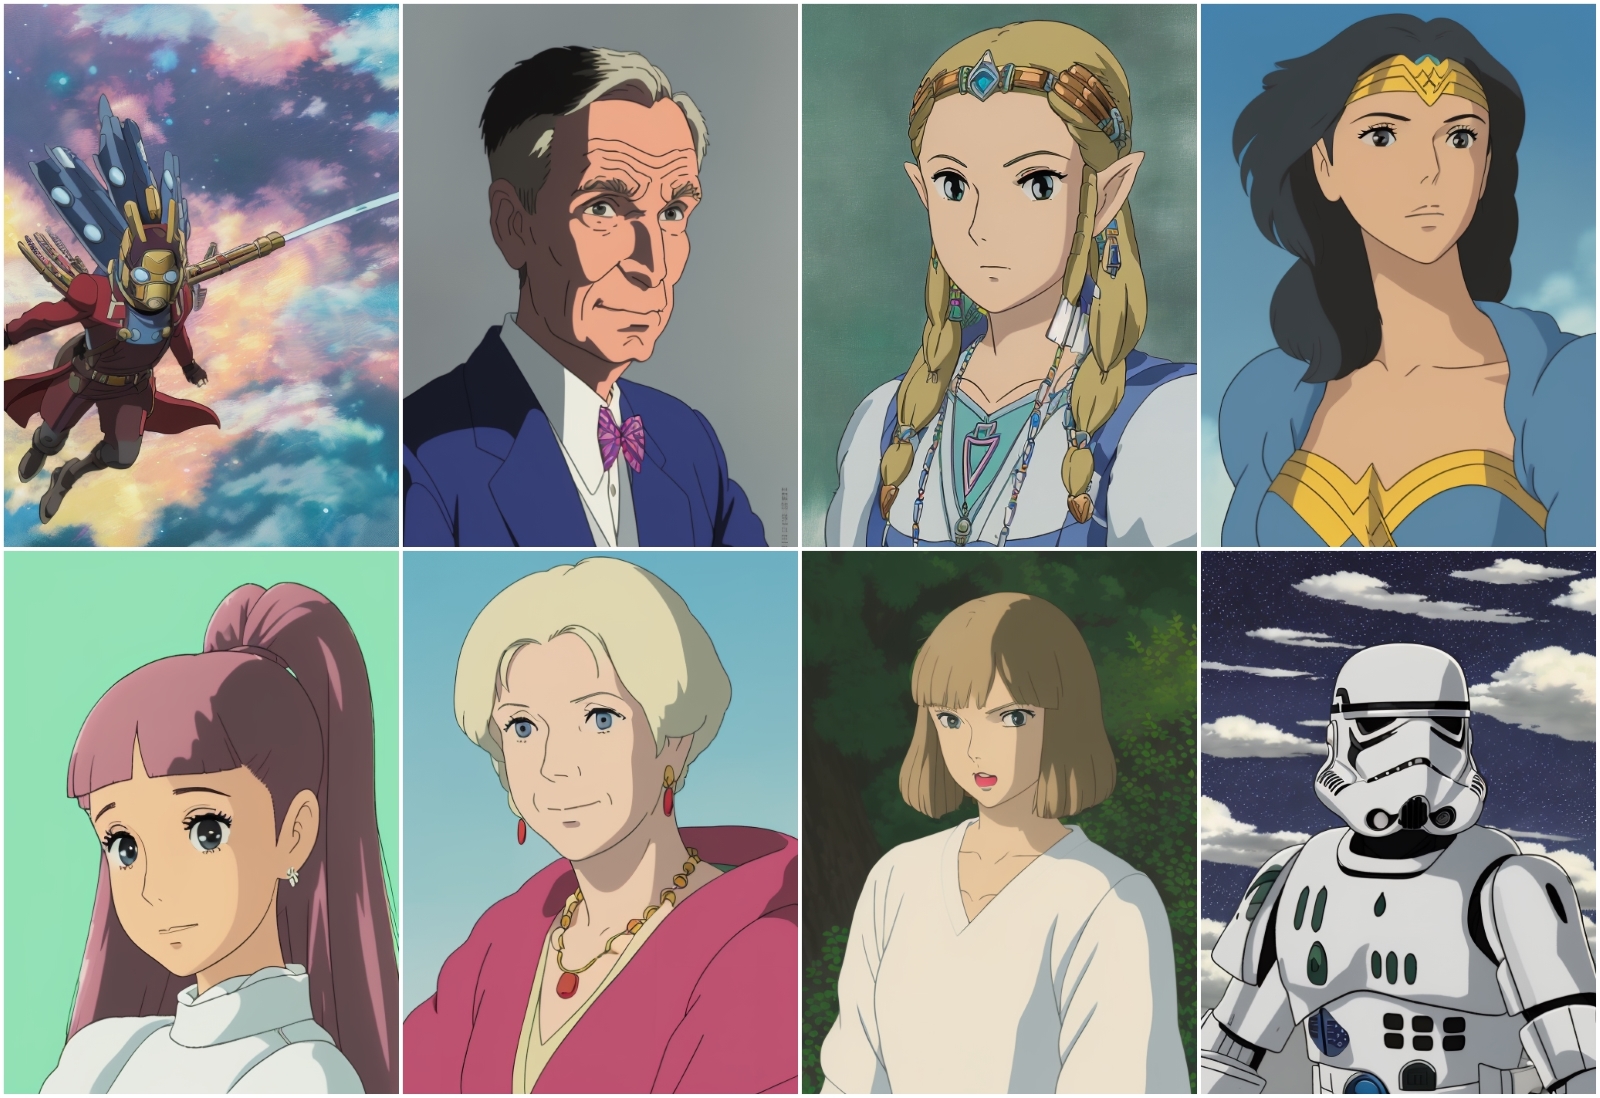
Characters rendered with the model:
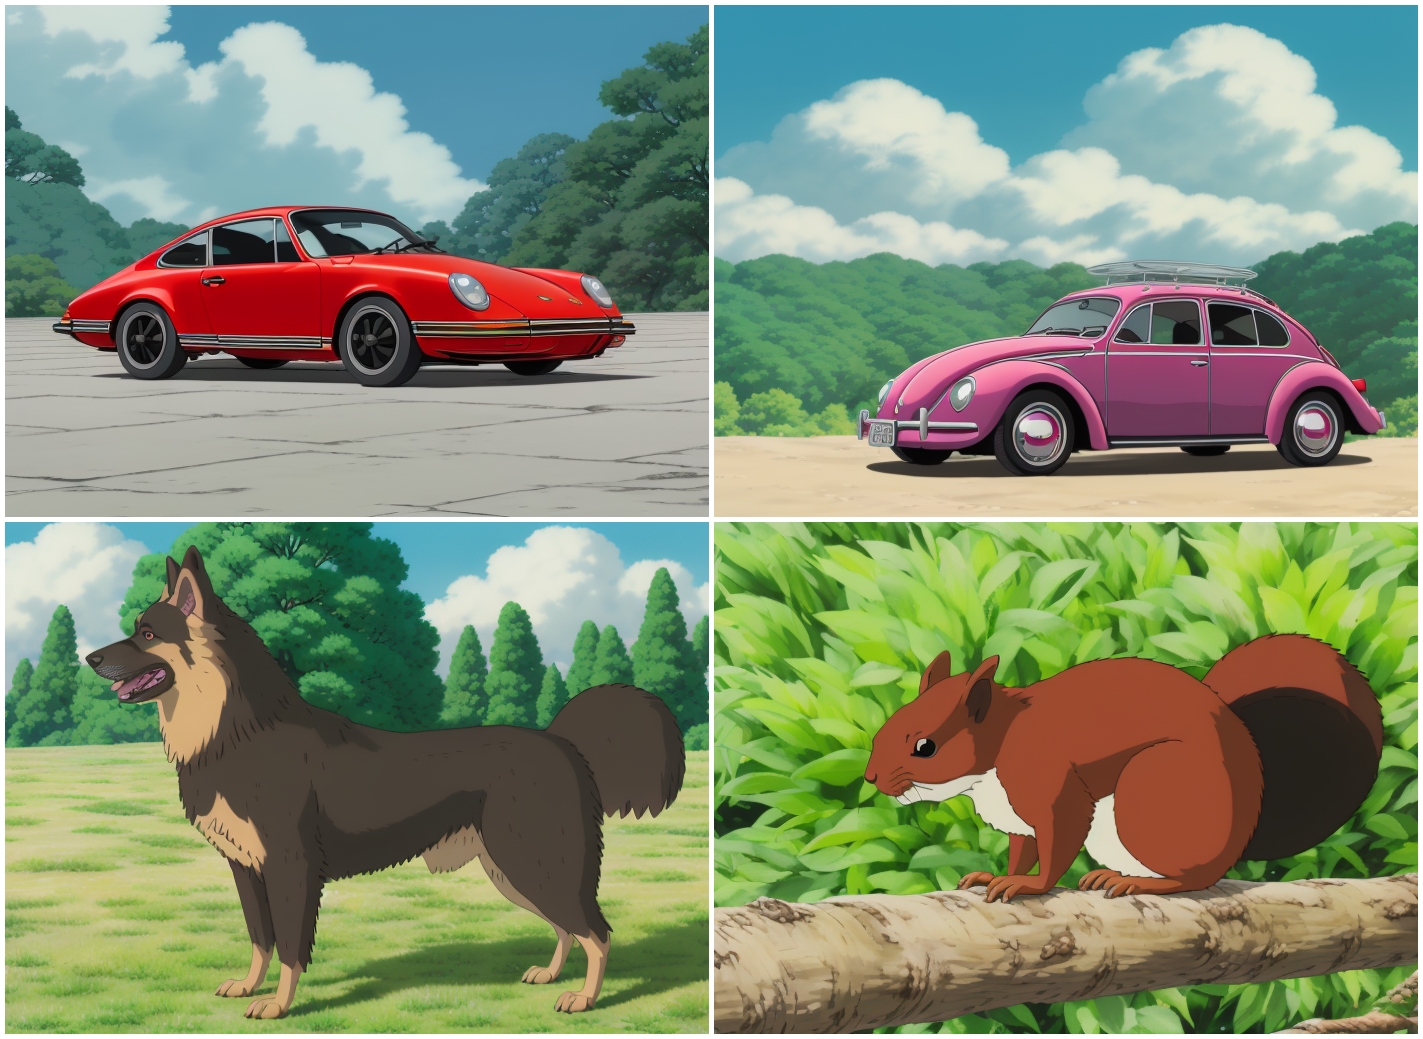
 Cars and Animals rendered with the model:
 Landscapes rendered with the model:
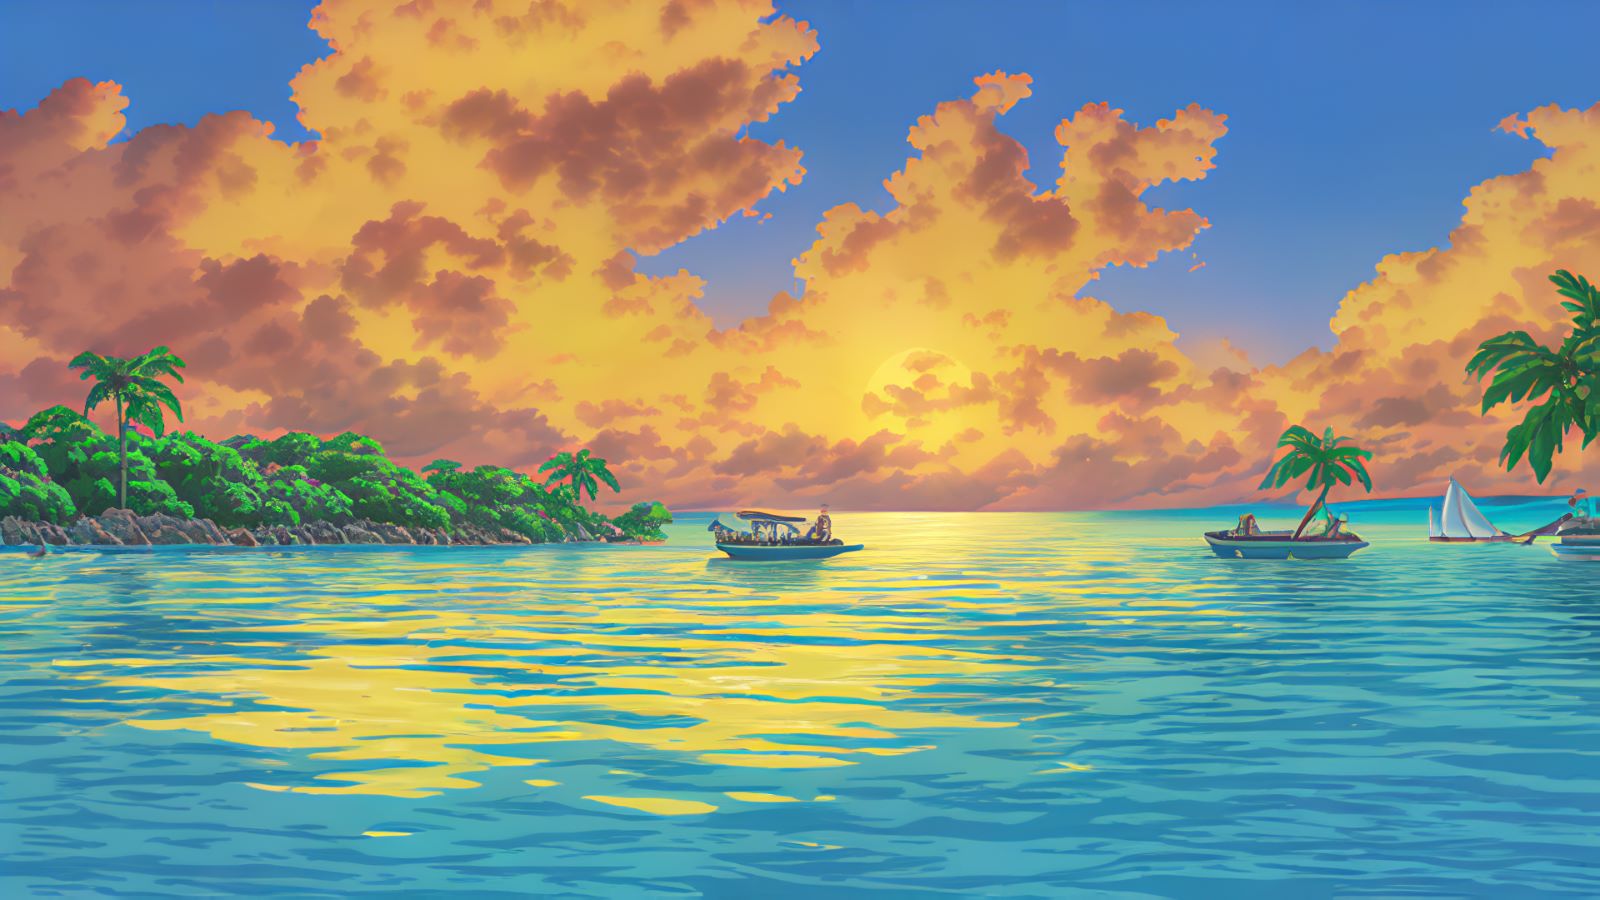 ghibli style beautiful Caribbean beach tropical (sunset) - Negative prompt: soft blurry
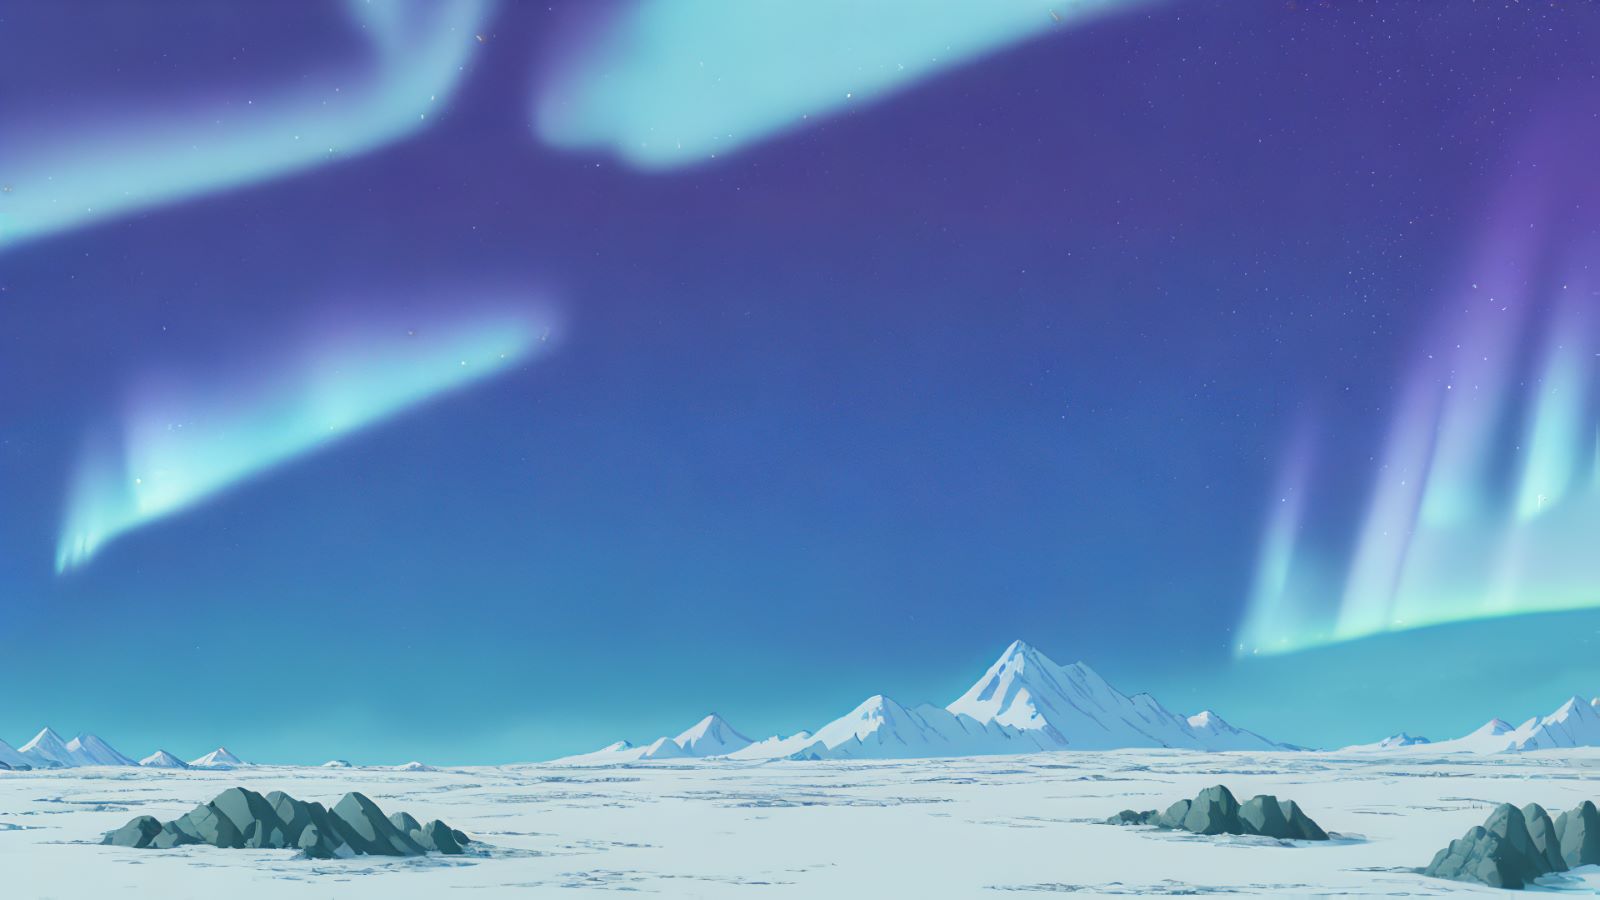 ghibli style ice field white mountains ((northern lights)) starry sky low horizon - Negative prompt: soft blurry
ghibli style (storm trooper) Negative prompt: (bad anatomy) Steps: 20, Sampler: DPM++ 2M Karras, CFG scale: 7, Seed: 3450349066, Size: 512x704
ghibli style VW beetle Negative prompt: soft blurry Steps: 30, Sampler: Euler a, CFG scale: 7, Seed: 1529856912, Size: 704x512
This model was trained using the diffusers based dreambooth training by ShivamShrirao using prior-preservation loss and the train-text-encoder flag in 15.000 steps.
<!-- ### Gradio We support a [Gradio](https://github.com/gradio-app/gradio) Web UI run redshift-diffusion: [](https://huggingface.co/spaces/nitrosocke/Ghibli-Diffusion-Demo)-->This model can be used just like any other Stable Diffusion model with Optimum on AWS neuron devices. For more information, please have a look at the Stable Diffusion.
from optimum.neuron import NeuronStableDiffusionPipeline

model_id = "nitrosocke/Ghibli-Diffusion"
input_shapes = {"batch_size": 1, "height": 512, "width": 512}
compiler_args = {"auto_cast": "matmul", "auto_cast_type": "bf16"}

pipe = NeuronStableDiffusionPipeline.from_pretrained(
    model_id, export=True, dynamic_batch_size=False, **input_shapes, **compiler_args, device_ids=[0, 1]
)
pipe = pipe.to("cuda")

prompt = "ghibli style magical princess with golden hair"
image = pipe(prompt).images[0]

image.save("./magical_princess.png")
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies: