
Downloads · 30 days
23
1% of all-time downloads
HaileyStorm/llama3-5.4b-instruct
llama3-5.4b-instruct is a text generation model from HaileyStorm. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
Quantized versions of this model are available: - https://huggingface.co/HaileyStorm/llama3-5.4b-instruct-Q80-GGUF - https://huggingface.co/HaileyStorm/llama3-5.4b-instruct-Q6K-GGUF - https://huggingface.co/HaileyStor…
Downloads · 30 days
23
1% of all-time downloads
All-time downloads
1.8K
Public
Parameters
5.4B
10.8 GB on disk
Likes
1
Public
Click a slice to open those files.
.safetensors10.8 GB · 100%
From the Hugging Face model README
Quantized versions of this model are available:
This is a "merge" of pre-trained language models created using mergekit. It is a prune of Meta-Llama-3-8B-Instruct from 32 layers down to 20, or about 5.4B parameter -- it's about 67% the size of the original. Mostly, this is a test of (significant) pruning & healing an instruct-tuned model.
I healed the model by doing a full weight DPO finetune for 139k samples (3.15 epochs), and then a LoRA with r=128 a=256 for 73k samples (1.67 epochs). Both had 8k sequence length.
Prior to healing, the model returned absolute gibberish to any prompt, rarely two real words together. For example, give "2+2=" it might return "Mahmisan Pannpyout Na RMITa CMI TTi GP BP GP RSi TBi DD PS..."
The results are pretty good! The model has issues, but could have legitimate uses. It can carry on a conversation. It's certainly usable, if not useful.
Truthfulness and commonsense reasoning suffered the least from the prune / were healed the best. Knowledge and complex reasoning suffered the most. This model has 67% the parameters of the original, and has:
An average of 69% the benchmark scores for 67% the parameters, not bad! (Note, I had issues running the GSM8K and BBH benchmarks.) I do believe it could be much better, by doing the pruning in stages (say, 4 layers at a time) with some healing in between, and longer healing at the end with a more diverse dataset.
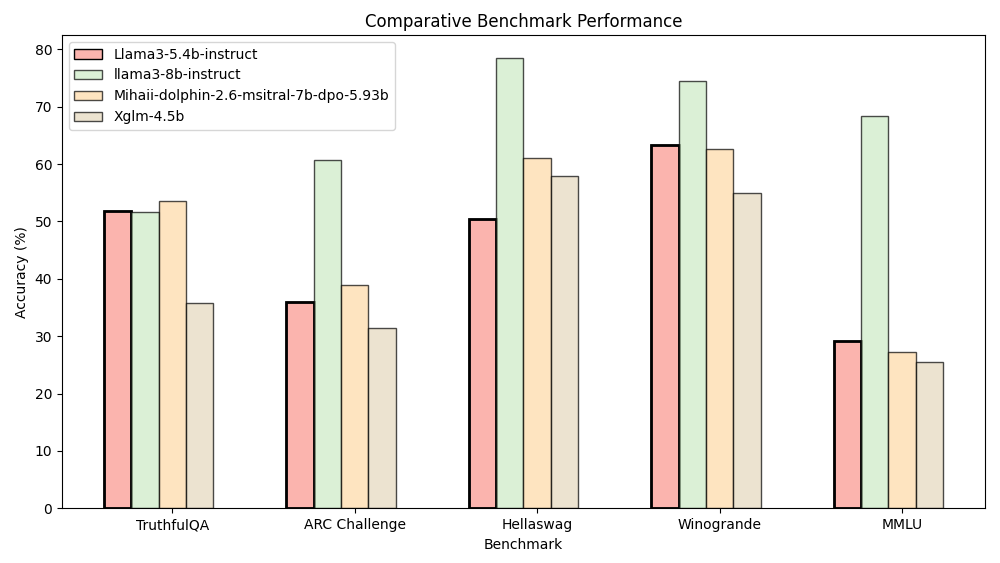 Figure 1: Benchmark results for the pruned model, the original 8B model, and other models of similar size. Truthfulness and commonsense reasoning suffered the least from the prune / were healed the best. Knowledge and complex reasoning suffered the most.
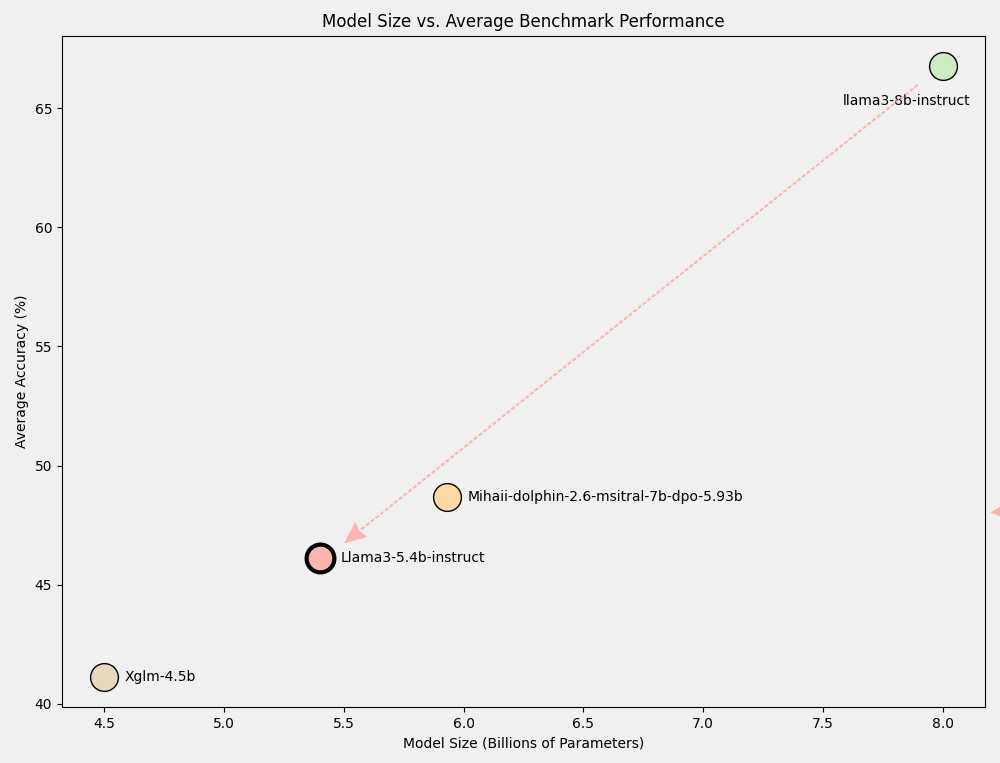 Figure 2: Model size vs average benchmark performance. Llama3-5.4b-instruct may not be fully healed, but its performance scales linearly with its size.
This size should allow for:
And of course, as stated, it was a test of significant pruning, and of pruning&healing an instruct-tuned model. As a test, I think it's definitely successful.
This model was merged using the passthrough merge method.
The following models were included in the merge:
The following YAML configuration was used to produce this model:
dtype: bfloat16
merge_method: passthrough
slices:
- sources:
  - layer_range: [0, 16]
    model: meta-llama/Meta-Llama-3-8B-Instruct
- sources:
  - layer_range: [20, 21]
    model: meta-llama/Meta-Llama-3-8B-Instruct
- sources:
  - layer_range: [29, 32]
    model: meta-llama/Meta-Llama-3-8B-Instruct
Here are the logs for the full weight fine tune:
And the LoRA logs: